
The Call That Might Have Worked
An agent builds your checkout. It calls the payment provider, waits up to ten seconds, and if no answer comes back it shows the customer "Payment failed, please try again." The customer clicks the button again. Two days later they email support: their card was charged twice.
Nothing crashed. The first charge went through. The provider's response was slow, or it was lost on the way back, and your code treated "I did not hear back" as "it did not happen." Those are two different facts, and many distributed-systems bugs come from confusing them.
The third outcome
Inside one process, a function call ends with a return or a throw, and if the process dies the caller dies with it, so nobody is left wondering. A call to another machine adds a third outcome, where the caller survives but loses contact: you do not know.
The request may never have arrived. It may have arrived and failed. It may have arrived, succeeded, and the response was lost or delayed past your timeout. From the caller's side, those cases look identical: silence.
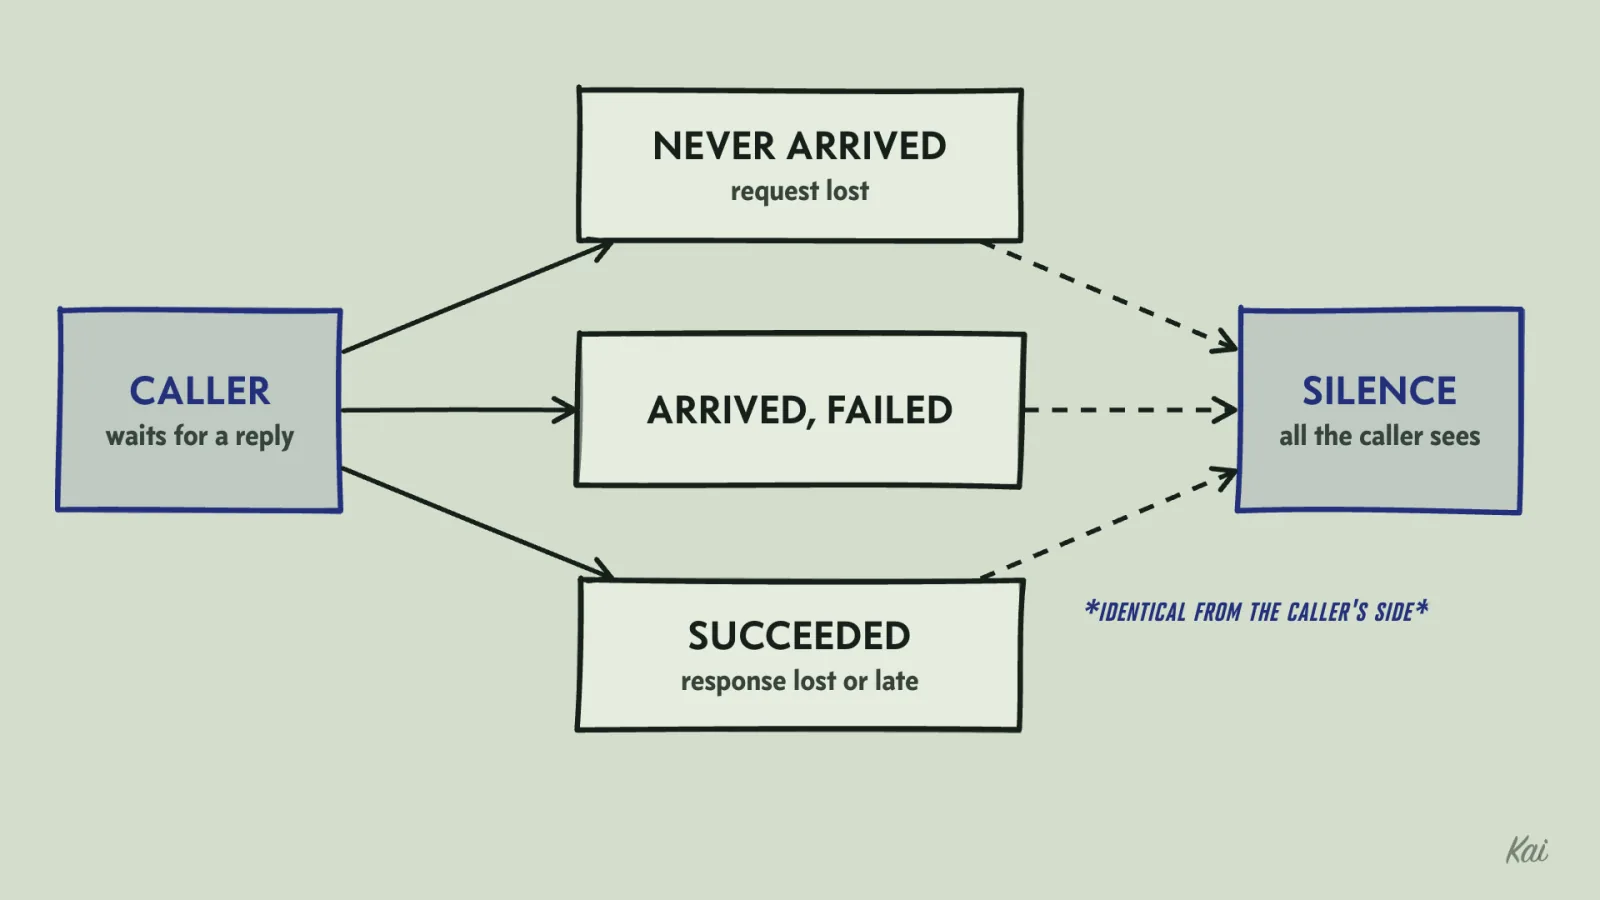
When the provider's acknowledgment of completion does reach you, the call is settled. The trouble is the call where none arrives: without one, you cannot tell a lost request from a lost response. Making the acknowledgment itself reliable takes another acknowledgment, which can be lost too, and so on without end. This is the two generals problem, and it is why a sender over an unreliable network cannot be certain in every case that the other side acted on its message.
So every remote call forces a choice. You can send once and never retry, which means some messages are lost (at-most-once). Or you can retry until you get an answer, which means some messages are delivered more than once (at-least-once).
Exactly-once delivery would require the sender to know something it cannot know. What real systems do is deliver at-least-once and make the receiver handle duplicates so that processing a message twice has the same effect as processing it once. That property is called idempotency, and the combination is often called effectively-once processing.
Idempotency keys
Here is how to build a payment endpoint that is safe to retry. The client creates a random ID for each logical purchase, before the first attempt, and sends the same ID on every retry of that purchase. The server stores the result for each ID and returns the stored result when it sees the ID again.
CREATE TABLE idempotency_keys (
  key          text PRIMARY KEY,
  request_hash text NOT NULL,
  status       text NOT NULL CHECK (status IN ('pending', 'done')),
  response     jsonb
);async function charge(key: string, req: ChargeRequest): Promise<ChargeResponse> {
const hash = sha256(JSON.stringify(req));
const inserted = await db.query(
`INSERT INTO idempotency_keys (key, request_hash, status)
VALUES ($1, $2, 'pending') ON CONFLICT (key) DO NOTHING`,
[key, hash],
);
if (inserted.rowCount === 0) {
const { rows } = await db.query(
"SELECT request_hash, status, response FROM idempotency_keys WHERE key = $1", [key]);
if (rows[0].request_hash !== hash) throw new ConflictError("key reused with different request");
if (rows[0].status === "pending") throw new ConflictError("original request still in progress");
return rows[0].response;
}
const result = await paymentProvider.charge(req, { idempotencyKey: key });
await db.query(
"UPDATE idempotency_keys SET status = 'done', response = $2 WHERE key = $1",
[key, result],
);
return result;
}Walk through the retry. The client sends key k1. The server inserts k1 as pending, charges the card, stores the response, and replies. The reply is lost.
The client times out and retries with k1. The insert hits the primary key and changes nothing, so the server reads the stored row, sees done, and returns the original response. The card was charged once, and the client got its answer.
Each line guards a specific case. The primary key makes the claim on k1 atomic, so two retries arriving at the same moment cannot both charge. The pending state tells the second one that the first is still running. The hash catches a client bug that reuses one key for two different purchases.
And the key is passed on to the provider, because the same problem exists one hop further down: if the server crashes after charging but before recording done, the key stays pending, and whatever process cleans up pending keys needs to be able to ask the provider what happened to k1 rather than charging again. Payment APIs such as Stripe accept an idempotency key for exactly this reason: because the provider deduplicates on the key, retrying the provider call with k1 returns the first charge instead of making a second one.
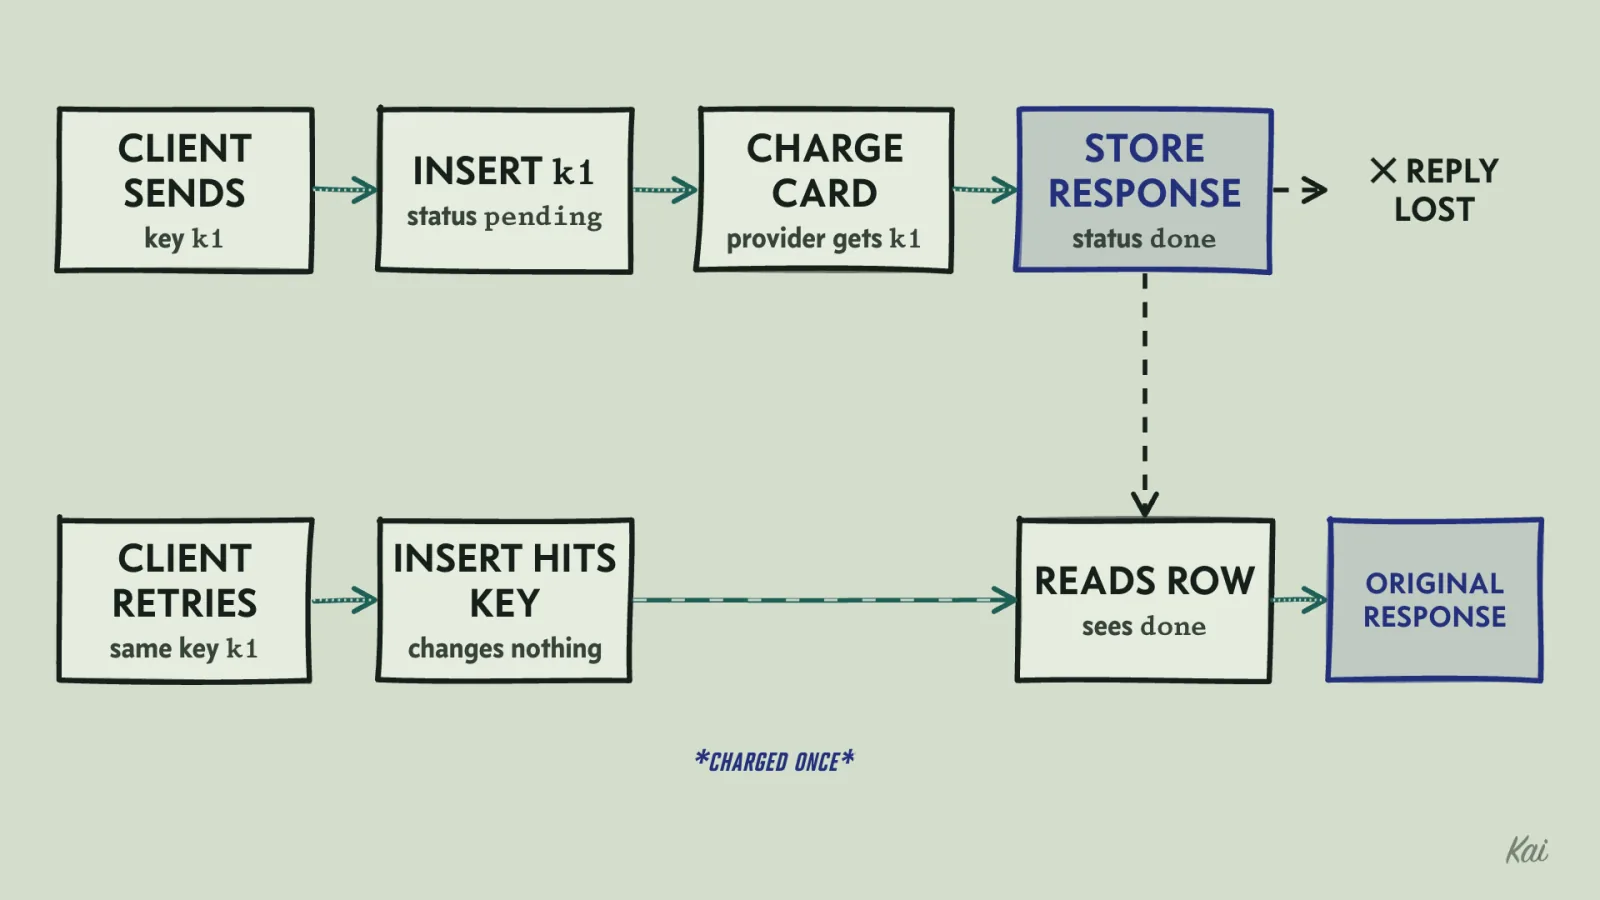
done, but its reply is lost; the retry with the same k1 hits the primary key, reads done, and gets the original response.Keys do not last forever. Stripe, for example, may remove a key once it is at least 24 hours old, and your own table should expire old rows too. Retry within that window. After it, a retry with the same key can become a second charge, so look up the original payment at the provider and reconcile before charging again.
A real version of this endpoint also records definite failures, such as a declined card, so the key does not stay pending forever. Only an unknown outcome should leave it pending for the cleanup process to resolve.
The client side matters as much. The key must be generated once per purchase and reused across retries. A key generated inside the retry loop gives each attempt a fresh key, and the server correctly treats each one as a new purchase.
This block runs both clients against a server that stores one response per key and loses the reply to the first attempt.
// A stand-in for the server above: it stores one response per key,
// and the reply to the first attempt is lost on the way back.
let charges = 0;
let replyLost = true;
const stored = new Map<string, string>();

async function chargeEndpoint(key: string, cents: number): Promise<string> {
  const earlier = stored.get(key);
  if (earlier) return earlier;
  charges += 1;
  const response = `charge #${charges} for ${cents} cents`;
  stored.set(key, response);
  if (replyLost) {
    replyLost = false;
    throw new Error("timeout");
  }
  return response;
}

let keysMade = 0;
const newKey = () => `key-${++keysMade}`;

async function payWithRetries(cents: number, keyFor: () => string) {
  for (let attempt = 1; attempt <= 3; attempt++) {
    try {
      return await chargeEndpoint(keyFor(), cents);
    } catch {
      // timed out: try again
    }
  }
  throw new Error("gave up");
}

const fresh = await payWithRetries(2500, newKey); // new key on every attempt
console.log("key made inside the loop:", fresh, "| charges:", charges);

charges = 0;
replyLost = true;
const purchaseKey = newKey(); // made once, before the first attempt
const reused = await payWithRetries(2500, () => purchaseKey);
console.log("key made once per purchase:", reused, "| charges:", charges);
Output
The same reasoning applies when a service changes its database and also publishes a message to a queue. If it commits and then crashes before publishing, the message is lost. If it publishes first and the commit fails, the message describes something that never happened.
The outbox pattern writes the message into an outbox table in the same transaction as the change, and a separate process publishes rows from that table, retrying until the queue accepts them. Delivery is then at-least-once, so consumers deduplicate, usually by a message ID.
Every wait needs a limit
Now the other half of the checkout problem. Suppose the payment provider does not fail. It just gets slow, taking 30 seconds to answer instead of 300 milliseconds, and your code has no timeout at all.
Little's law says the number of requests in progress equals the arrival rate times the time each one takes. At 50 checkouts per second and 0.3 seconds each, about 15 are in progress at once. At 30 seconds each, 1,500 are.
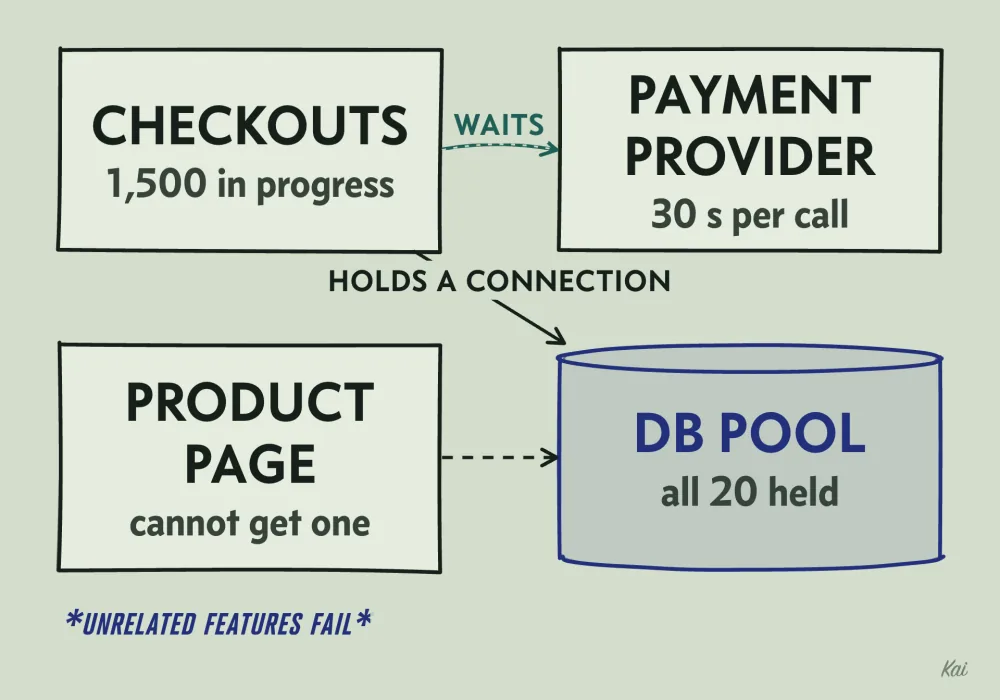
Each of those holds a connection, some memory, and often a slot in a database connection pool that other pages also need. If the pool has 20 connections, the product page, which never talks to the payment provider, starts failing too, because it cannot get a connection. One slow dependency has taken down unrelated features.
A timeout turns "slow" into "failed" at a point you choose. Set it from what the dependency normally does, and choose the rate of false timeouts you can live with, since any timeout also cuts off some slow calls that would have succeeded. If 99.9% of payment calls finish within two seconds, a three-second timeout cuts off the stuck ones and a small fraction of the slow successes, and each of those needs the idempotent retry above. Every network call, every database query and every lock acquisition needs one. Library defaults are often infinite or measured in minutes, so read what yours are.
Retrying without making it worse
Once calls can time out, you will want to retry the ones that fail, and a careless retry policy makes outages worse.
Take a service that retries every failed call to its inventory backend three times, immediately. When the backend is healthy, that is harmless. When the backend is struggling, every failing request becomes four requests in quick succession.
If you normally send 1,000 requests per second and they all start failing, you are now sending up to 4,000 per second to a service that was already failing at 1,000. Every other client of that backend with the same policy does the same. The backend cannot recover while the load is four times higher than the load that broke it. This is a retry storm.
The fix has three parts. Wait between attempts, and double the wait each time (exponential backoff): 100 ms, 200 ms, 400 ms, capped at a few seconds. Add randomness to each wait (jitter), because if a thousand clients failed at the same moment and all wait exactly 200 ms, they all retry at the same moment again. And stop after a small number of attempts.
async function withRetry<T>(fn: () => Promise<T>, attempts = 3): Promise<T> {
  if (!Number.isInteger(attempts) || attempts < 1) throw new RangeError("attempts must be a positive integer");
  for (let i = 0; ; i++) {
    try {
      return await fn();
    } catch (err) {
      if (i === attempts - 1 || !isRetryable(err)) throw err;
      const ceiling = Math.min(5_000, 100 * 2 ** i);
      await sleep(Math.random() * ceiling); // full jitter
    }
  }
}
isRetryable matters. Retry timeouts, connection errors and responses that mean "try later" (503, 429). Do not retry a 400 that says the card number is invalid; it will be invalid every time. And only retry operations that are idempotent, or that carry an idempotency key.
This block counts where 1,000 simultaneous retries land with each kind of wait:
// 1,000 clients fail at the same moment and each waits before retrying.
// Count how many retries land in the busiest 10 ms slice of time.
function busiestWindow(retryTimes: number[], windowMs = 10): number {
  const counts = new Map<number, number>();
  for (const t of retryTimes) {
    const w = Math.floor(t / windowMs);
    counts.set(w, (counts.get(w) ?? 0) + 1);
  }
  return Math.max(...counts.values());
}

const clients = 1000;
const fixedWait = Array.from({ length: clients }, () => 200);
const fullJitter = Array.from({ length: clients }, () => Math.random() * 200);

console.log("fixed 200 ms wait:", busiestWindow(fixedWait), "retries in the busiest 10 ms");
console.log("random wait up to 200 ms:", busiestWindow(fullJitter), "retries in the busiest 10 ms");
Output
With a fixed wait, all 1,000 retries arrive in the same window. With full jitter, the busiest window holds around 60, and the numbers change a little on each run.
Timeouts in a chain
Retries and timeouts interact when calls are nested. Say service A calls B, and B calls C. B gives each call to C a one-second timeout and makes up to three attempts, with backoff waits of up to 100 ms and 200 ms between them. B's worst case is 3 × 1 s + 0.3 s = 3.3 seconds before it gives up.
If A calls B with a two-second timeout, A abandons the request while B is still retrying. B keeps working on a response A will never read, and A, if it also retries, starts a new request that makes B try C three more times. With three attempts at each of two layers, one user action can hit C nine times. Add a third retrying layer and it is 27.
Two rules keep this under control. If B may use its full retry budget, A's timeout on B has to exceed B's worst case of 3.3 seconds plus B's own processing, so say four. If A cannot wait that long, pass A's deadline down with the request so B stops retrying when A stops waiting. And retry at one layer, usually the one closest to the failing dependency, while the layers above treat a failure as final.
Clocks disagree
Distributed systems also go wrong over time itself. An agent builds an audit log where each service writes events with Date.now(), and a report sorts them by timestamp to show what happened in what order.
Every machine has its own clock, and no two agree exactly. Clocks drift, and NTP, the protocol that corrects them, adjusts them in small steps and sometimes large jumps, including backward. Two servers can easily disagree by several milliseconds, and far more when one has lost contact with its time source.
If server 1 records "order placed" at 12:00:00.005 and server 2 records "payment captured" for that order at 12:00:00.003, the log says the payment came first. Sorting by wall-clock time from different machines gives an order that did not happen.
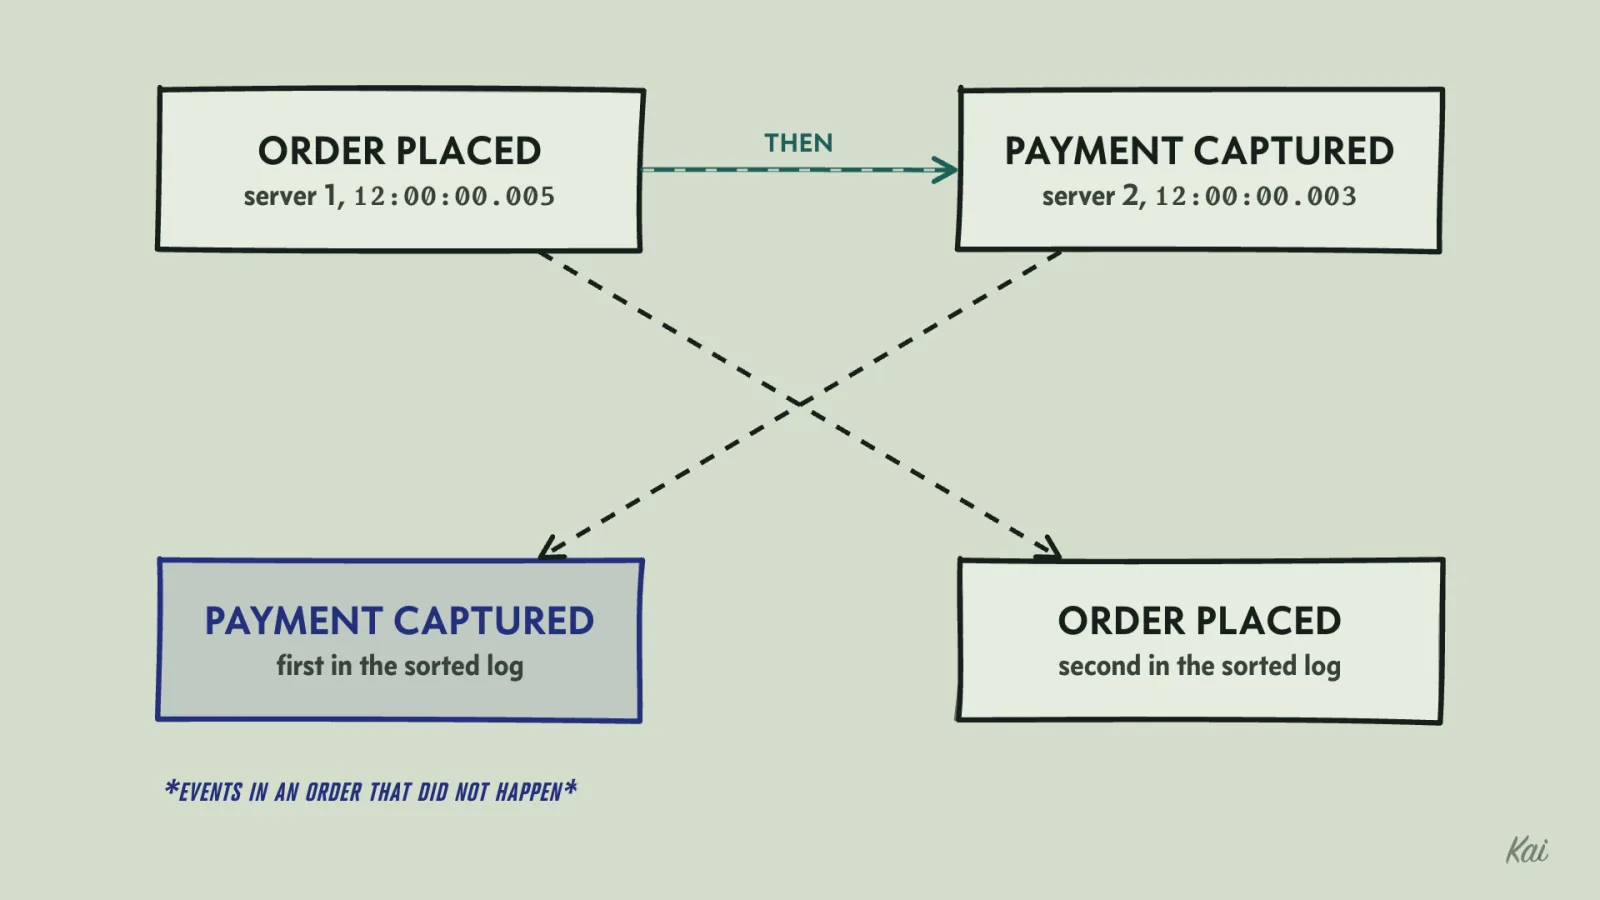
Some rules follow. To measure how long something took on one machine, use a monotonic clock (performance.now() in JavaScript, time.monotonic() in Python), which only moves forward and is unaffected by clock corrections. To order events, use something that captures causality, which means a logical clock carried in the messages. A database sequence does not do this: it orders the handing out of IDs, and a service that writes its log entry late gets a later number than an event it caused.
A Lamport clock is a counter each process increments on every event and attaches to every message; a receiver sets its counter above the highest value it has seen. If event X caused event Y, X gets the smaller number. The reverse does not hold, because two unrelated events also get numbers, so a smaller number alone does not show cause.
Here is the audit log case with a 4 ms skew between the two servers:
// Server 2's clock runs 4 ms behind server 1's. Only this simulation knows the true time.
let trueTime = 1_000;
const skew = { s1: 0, s2: -4 };
const wallClock = (server: "s1" | "s2") => trueTime + skew[server];

const lamport = { s1: 0, s2: 0 };
const log: Array<{ what: string; wall: number; lamport: number }> = [];

// Server 1 places the order and sends a message carrying its counter.
trueTime += 1;
lamport.s1 += 1;
log.push({ what: "order placed", wall: wallClock("s1"), lamport: lamport.s1 });
const message = { orderId: 7, lamport: lamport.s1 };

// Two milliseconds later, server 2 receives it and captures the payment.
trueTime += 2;
lamport.s2 = Math.max(lamport.s2, message.lamport) + 1;
log.push({ what: "payment captured", wall: wallClock("s2"), lamport: lamport.s2 });

const order = (key: "wall" | "lamport") =>
  [...log].sort((a, b) => a[key] - b[key]).map((e) => `${e.what} (${e[key]})`);
console.log("by wall clock:", order("wall"));
console.log("by Lamport clock:", order("lamport"));
Output
The payment really happened 2 ms after the order, but server 2 stamped it 2 ms before. The Lamport counter puts them in the order the message forced.
Agreeing on anything
The hardest version of these problems is getting several machines to agree, for example on which one is the leader allowed to accept writes. The standard approach is a quorum: a decision counts once a majority has accepted it. With five nodes, three must agree, so the system survives two failures, and two different majorities always share at least one node. That shared node stops two nodes from both being elected leader for the same term, provided each node durably records its vote and grants at most one vote per term; a node that forgot its vote after a restart could vote twice.
When the network splits, the side without a majority has to stop accepting writes or risk accepting ones the other side contradicts. That forced choice between staying available and staying consistent during a partition is the CAP tradeoff.
Getting these protocols right is hard enough that you should use a proven implementation: your database's own replication, or a coordination service such as etcd or ZooKeeper, instead of an agent's homemade lock built on a cache and a timestamp.