
The promise an API makes
A customer reports that invoice totals sometimes show a rounding error, and you give the bug to an agent. It finds that the API returns totals as strings like "19.99" and decides, reasonably, that money should be an integer number of cents. It changes the response of GET /v1/invoices/{id} so total is now 1999, updates the web app to divide by 100, and the tests pass.
The API also has clients you didn't write. A customer's billing script does this:
const invoice = await res.json();
row.amount = `$${parseFloat(invoice.total).toFixed(2)}`;
parseFloat(1999) returns 1999, so the script now reports an invoice of $1999.00. The script keeps running and reports a total a hundred times too large. Your mobile app, whose decoder expects total to be a string, fails to decode the whole invoice and shows an error screen to every user who hasn't updated. The agent fixed a real bug and broke two clients, one loudly and one silently, and nothing in your test suite could see either.
An API is a promise to code you don't control.
What the contract includes
The contract is everything a client can observe and might rely on. Field names and types are the obvious part. So are the status codes, the shape of error bodies, whether a field can be null, the order items come back in, the default page size, and how long a request takes. Hyrum Wright's observation, known as Hyrum's Law, is that with enough users, every observable behavior of a system ends up depended on by somebody, whatever the documentation said.
This matters because a client is often out of your reach. A mobile app version stays installed on phones for months after you ship a new one. A customer's script runs from a cron job that nobody at that company has looked at in a year. You can't update those clients, so the only safe changes are the ones they can survive unchanged.
Compatible and breaking changes
The test for any change is one question: would a client built against yesterday's API, and never updated, still behave correctly? Walking through common changes with that question gives a fairly stable table.
| Change | Effect on existing clients |
|---|---|
| Add an optional field to a response | Usually safe; breaks clients that reject unknown fields |
| Add an optional request parameter | Safe |
| Remove or rename a response field | Breaks every client that reads it |
| Change a field's type or unit | Breaks, often silently |
| Make a request field required | Breaks every client that doesn't send it |
Return null where a value was always present |
Breaks clients that never checked |
| Add a new value to an enum | Breaks clients that treat unknown values as errors |
| Change the default sort order or page size | Breaks clients that relied on the old default |
The type change in the invoice example is the worst row, because a string that parses as a number and a number are both accepted by lenient code. The client keeps running and writes wrong data.
The way to ship a change like that is to add first and remove later, sometimes called expand and contract. Add a new field, total_cents: 1999, next to the old total: "19.99", and serve both. Update your own clients to read the new field.
Here are the two old clients, unchanged, reading the original response, the agent's change and the expanded response:
// The customer's billing script. res.json() returns `any`, so nothing checks the type.
const scriptAmount = (invoice: any) => `$${parseFloat(invoice.total).toFixed(2)}`;

// The mobile app's decoder, which expects `total` to be a string.
function appScreen(invoice: any): string {
  if (typeof invoice.total !== "string") return `error screen (total is a ${typeof invoice.total})`;
  return `shows ${invoice.total}`;
}

const responses: [string, string][] = [
  ["original", '{"id":"inv_1","total":"19.99"}'],
  ["agent's change", '{"id":"inv_1","total":1999}'],
  ["both fields", '{"id":"inv_1","total":"19.99","total_cents":1999}'],
];

for (const [label, body] of responses) {
  const invoice = JSON.parse(body);
  console.log(`${label.padEnd(15)} script: ${scriptAmount(invoice).padEnd(9)} app: ${appScreen(invoice)}`);
}
Output
The agent's change sends one client wrong numbers and the other to an error screen. The expanded response gives both of them exactly what they had before, while new code reads total_cents.
Mark the old one deprecated in the documentation and tell API customers the date it will be removed. For clients whose versions you control, such as your own mobile app, track how many users are still on each version, and remove the field only when the versions that need it are gone. Your logs can't tell you which fields an outside integration reads, so for those you ask: get confirmation that each integration has moved, or keep the old shape alive under the old API version. Then remove the field, or keep it forever if the cost of keeping it is small.
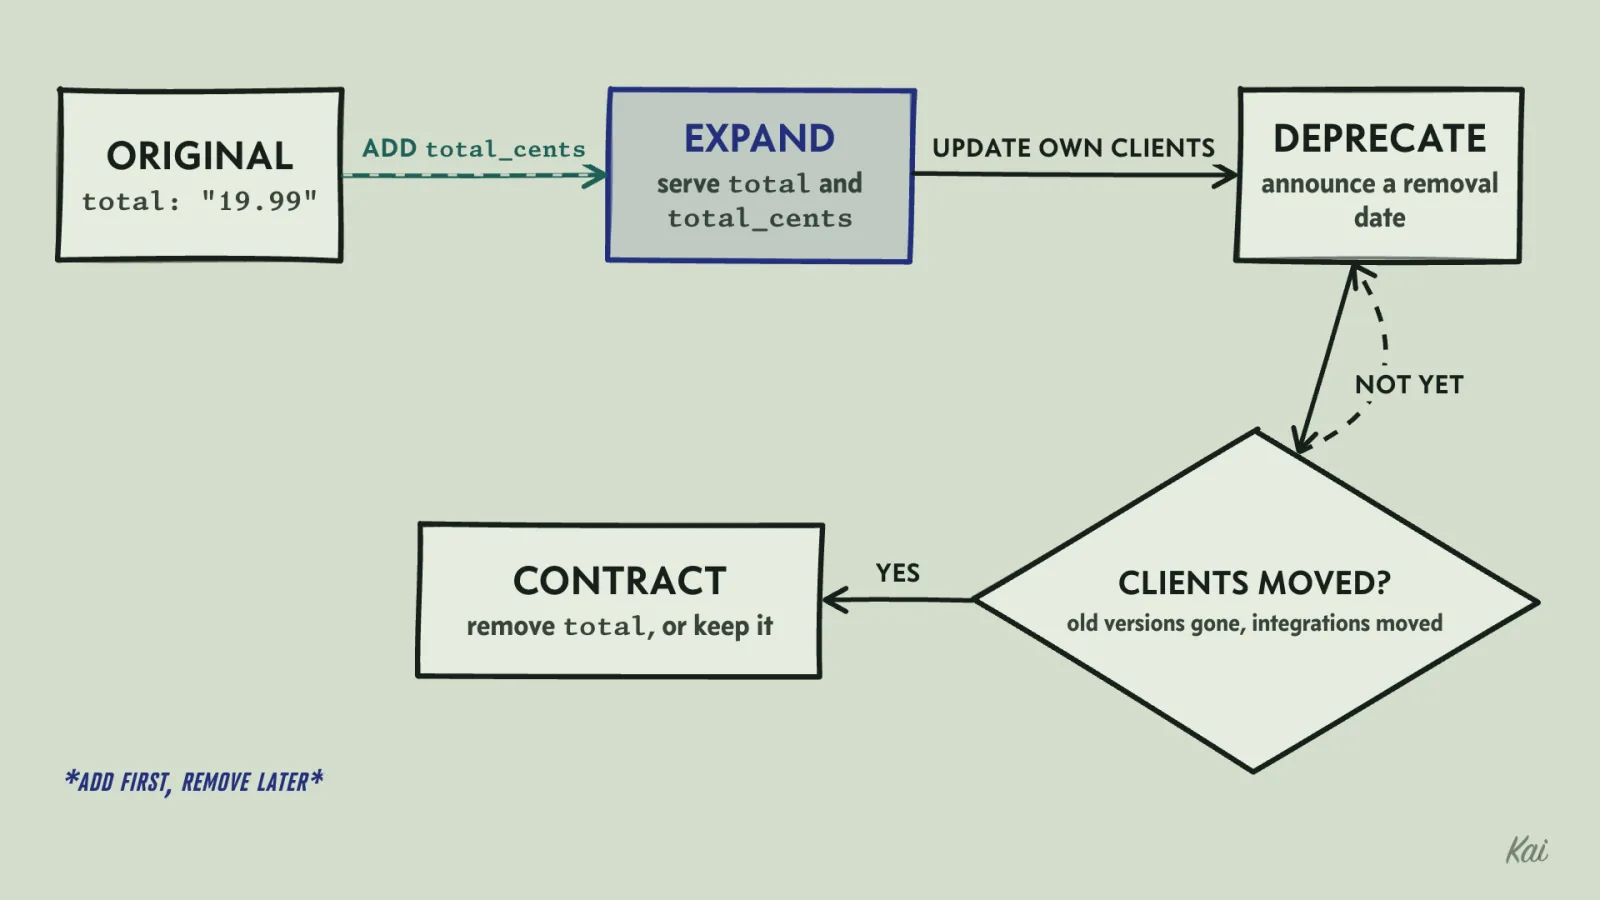
When a change can't be made additive, give the new shape a new version, such as /v2/invoices, and keep /v1 running with the old shape. Stripe takes this further: its API essay describes pinning each account to the version it first used and translating responses back to that version's shape, so old integrations keep working while the API changes underneath them. Whatever scheme you use, a breaking change always ships with a version number that tells clients they have to opt in.
Bounding every response
The same agent is asked for an activity feed and adds GET /v1/projects/{id}/events, which returns every event for the project. On the development database, a project has 200 events and the response comes back in a few milliseconds.
Your largest customer's project has 4 million events. At around 400 bytes of JSON each, the full response is 1.6 GB. The database reads every row, the server holds all of them in memory while it builds the JSON, and the request runs past whatever timeout sits in front of the server, so the client receives nothing.
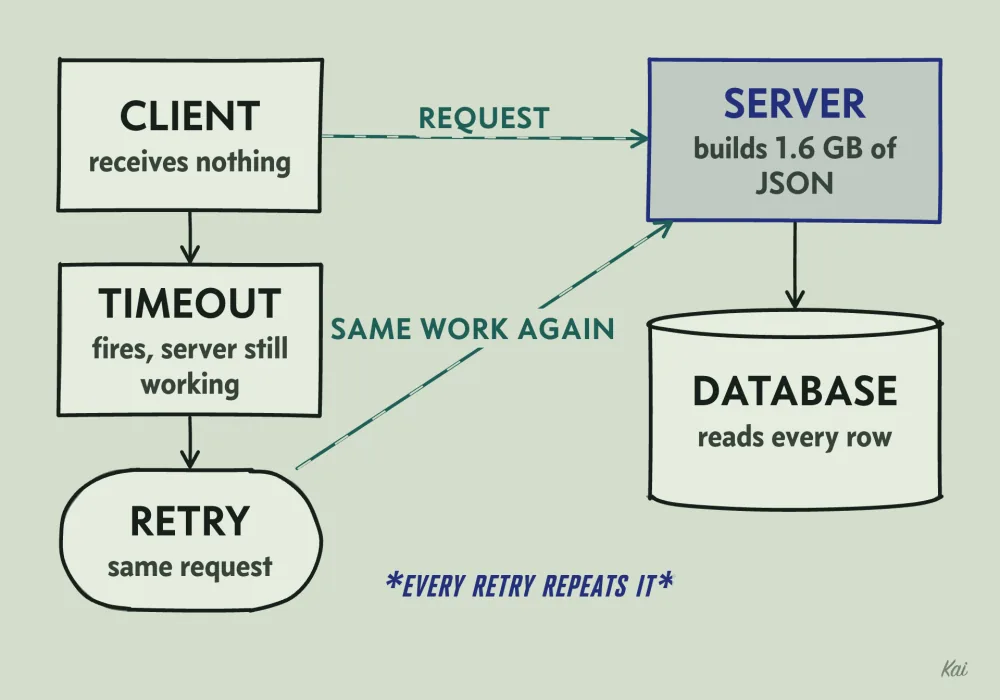
The client then retries, and the server does all that work again. An endpoint with no limit works for every account until the day one account grows, and then it becomes a way for a single request to exhaust your server's memory.
Every list endpoint needs a limit the server enforces, with a default and a maximum, and a way to fetch the next page. A common first attempt is an offset: ?limit=50&offset=200000.
It has two problems. The database still has to walk past 200,000 rows to throw them away, so late pages get slower. And if new events arrive while a client is paging, every row shifts down, so the client sees some events twice; deletions make it skip some.
Keyset pagination, often exposed as a cursor, avoids both. Each page remembers the last row it returned, and the next page asks for rows after that one.
SELECT id, kind, created_at
FROM events
WHERE project_id = $1 AND id < $2
ORDER BY id DESC
LIMIT $3;
The first page, which has no cursor, drops the id < $2 condition. With an index on (project_id, id), the database jumps straight to the right place, so page 10,000 costs about the same as page 1. New rows land at the top and don't shift anything below the cursor. If you sort by a timestamp instead of an ID, add the ID as a tiebreaker, because two rows can share a timestamp.
You can run both kinds of page against the same table. A new event arrives while the client is reading page 1:
CREATE TABLE events (id INTEGER PRIMARY KEY, project_id TEXT, kind TEXT);
INSERT INTO events (id, project_id, kind) VALUES
  (1, 'p_42', 'task.created'), (2, 'p_42', 'comment.created'), (3, 'p_42', 'task.assigned'),
  (4, 'p_42', 'task.closed'), (5, 'p_42', 'comment.created'), (6, 'p_42', 'task.reopened');

-- Page 1, newest first. The last row it returns is id 4.
SELECT 'page 1' AS page, id, kind FROM events
WHERE project_id = 'p_42' ORDER BY id DESC LIMIT 3;

-- A new event lands between the two requests.
INSERT INTO events (id, project_id, kind) VALUES (7, 'p_42', 'task.created');

-- Page 2 by offset: skip the 3 rows already shown.
SELECT 'page 2, offset' AS page, id, kind FROM events
WHERE project_id = 'p_42' ORDER BY id DESC LIMIT 3 OFFSET 3;

-- Page 2 by cursor: rows older than the last one shown.
SELECT 'page 2, cursor' AS page, id, kind FROM events
WHERE project_id = 'p_42' AND id < 4 ORDER BY id DESC LIMIT 3;
Output
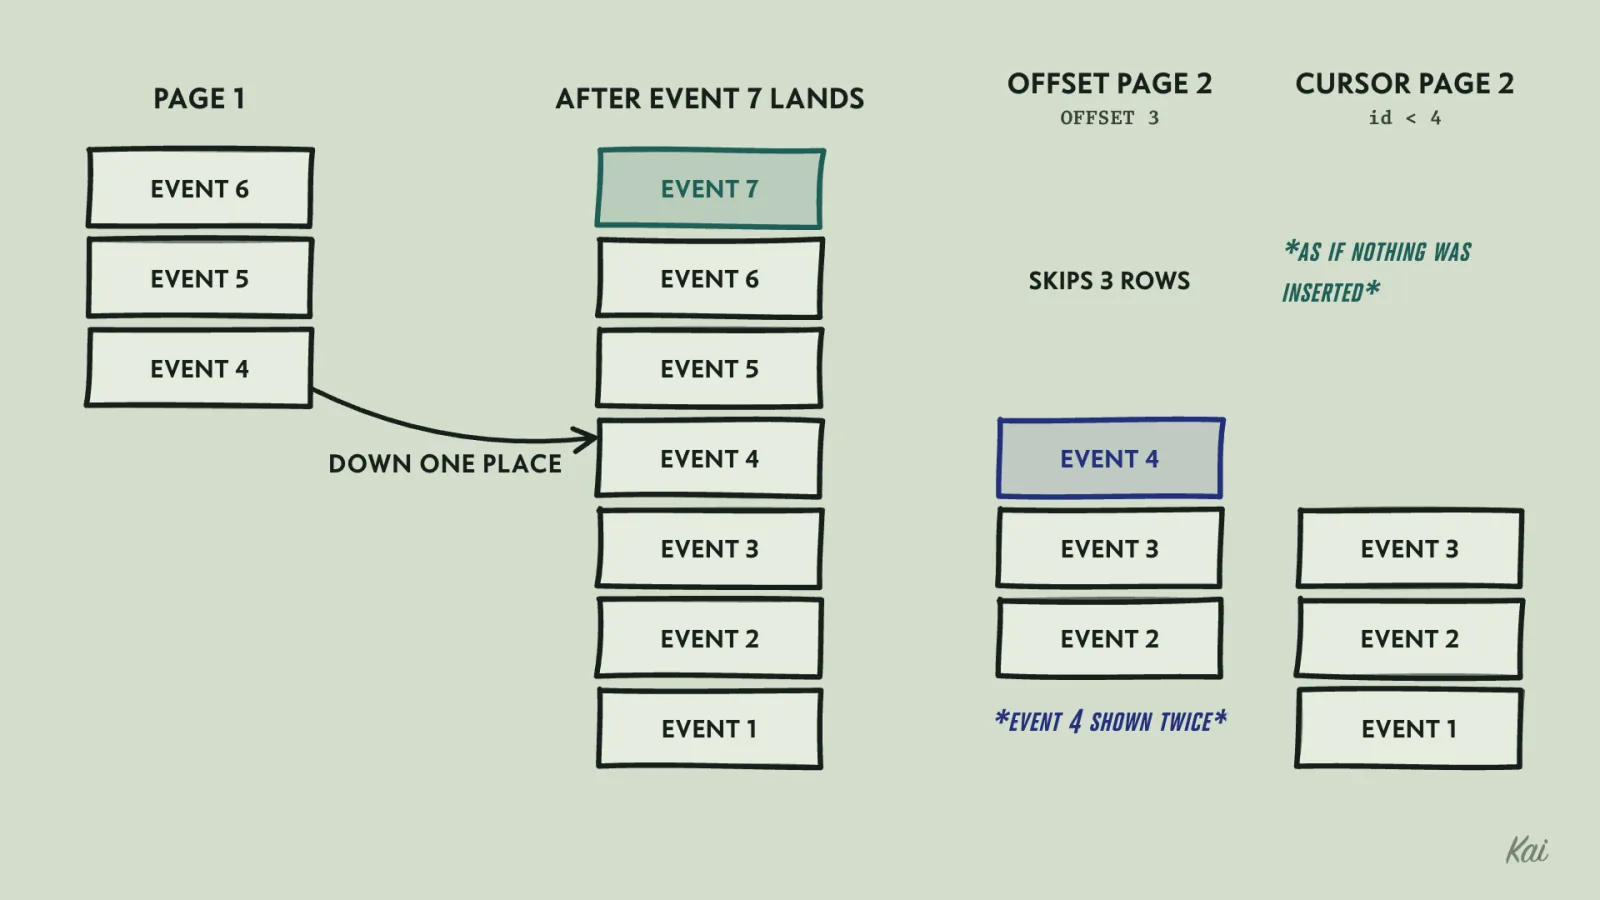
The offset page shows event 4 a second time, because event 7 pushed every row down one place. The cursor page starts at event 3, as if nothing had been inserted. The client still has to fetch event 7 by starting again from the top, which is what a feed does when it refreshes.
The server hands the cursor to the client as an opaque string, so you can change what's inside it later without breaking anyone.
const DEFAULT_LIMIT = 50;
const MAX_LIMIT = 100;

function parseLimit(raw: unknown): number | null {
  if (raw === undefined) return DEFAULT_LIMIT;
  const n = Number(raw);
  return Number.isInteger(n) && n >= 1 && n <= MAX_LIMIT ? n : null;
}

function encodeCursor(lastId: number): string {
  return Buffer.from(JSON.stringify({ id: lastId })).toString("base64url");
}

function decodeCursor(raw: string): number | null {
  try {
    const parsed = JSON.parse(Buffer.from(raw, "base64url").toString("utf8"));
    return Number.isSafeInteger(parsed?.id) ? parsed.id : null;
  } catch {
    return null;
  }
}
The handler fetches limit + 1 rows. If it gets the extra row, there is another page, and the response carries a cursor built from the last row it returns:
{
  "data": [{ "id": 88123, "kind": "comment.created", "created_at": "2026-09-14T08:12:44Z" }],
  "next_cursor": "eyJpZCI6ODgxMjN9"
}
When next_cursor is absent, the client has reached the end. A cursor that fails to decode is the client's mistake and gets a 400 response.
The same thinking applies to requests. Cap the size of request bodies, the number of IDs a batch endpoint accepts, and the rate at which one API key can call you. Each of these is part of the contract, so publish them.
Errors callers can act on
An error response has two readers. A program needs to decide what to do next, and a person debugging needs to know what went wrong. If every endpoint invents its own shape, one returning { "error": "bad" }, another { "message": ..., "code": 12 }, and a third a plain-text string, then every client has to special-case every endpoint.
RFC 9457, Problem Details for HTTP APIs, defines one shape, served with the content type application/problem+json:
{
  "type": "https://api.example.com/problems/invalid-parameter",
  "title": "Invalid query parameter",
  "status": 400,
  "detail": "limit must be an integer from 1 to 100",
  "instance": "/v1/projects/p_42/events"
}
type is a stable identifier a program can switch on. title is a short human summary of that type, and detail explains this particular occurrence. You can add your own fields, such as a request ID.
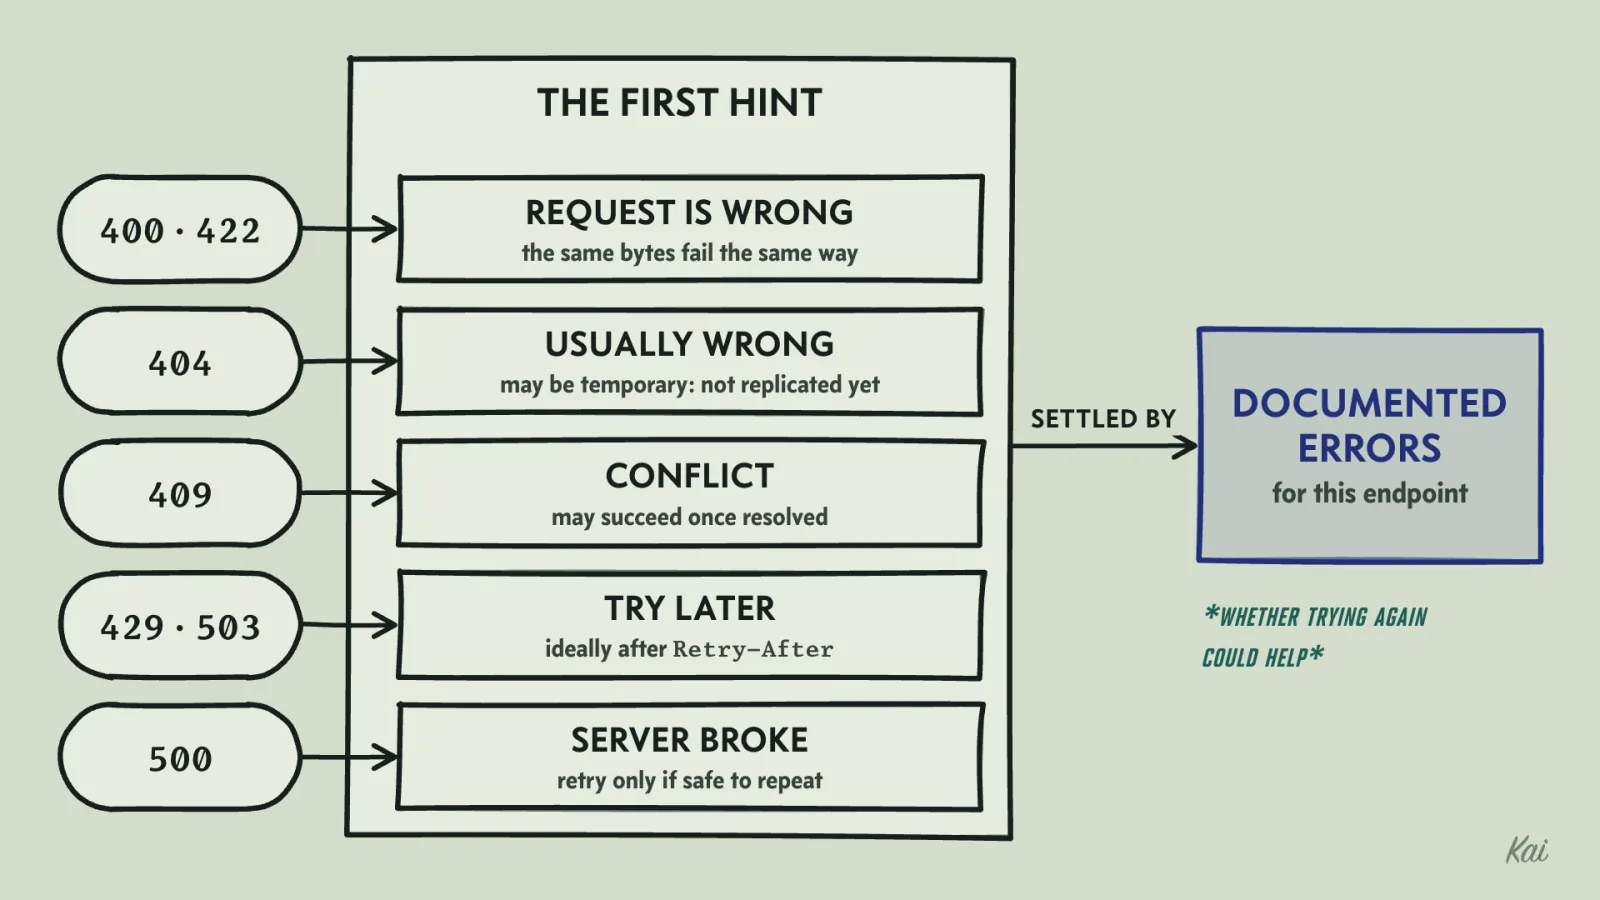
The status code is the first hint about whether trying again could help, and the endpoint's documented errors settle it. A 400 or 422 means the request itself is wrong, and sending the same bytes again will fail the same way. A 404 usually means the same, but it can be temporary, for example when a record hasn't replicated yet. A 409 says the request conflicts with the current state, so it may succeed once the client has resolved the conflict. A 429 or 503 means try later, ideally after the wait given in a Retry-After header, which holds either a number of seconds or an HTTP date (RFC 9110). A 500 means something broke on the server, and the client should retry only if the operation is safe to repeat.
The error body is also where agents leak internals. A handler like this is common in generated code:
res.status(500).json({ error: err.message, stack: err.stack });A stack trace tells an outsider your file layout, library versions and sometimes fragments of SQL. Log the details on the server under a request ID and return only the ID.
app.use((err: unknown, req: Request, res: Response, _next: NextFunction) => {
  const requestId = crypto.randomUUID();
  logger.error({ requestId, path: req.path, err }, "unhandled error");
  res.status(500).type("application/problem+json").json({
    type: "about:blank",
    title: "Internal Server Error",
    status: 500,
    request_id: requestId,
  });
});
Putting this in one error handler, and having every endpoint throw typed errors that the handler maps to problem details, is how the shape stays the same across endpoints written by different people and different agents.
Writing the contract down
Everything above works better when the contract exists as a file a machine can read. OpenAPI describes HTTP endpoints, their parameters and their response bodies, using JSON Schema for the shapes. Here is the invoice as the API originally promised it. This fragment sits inside a full OpenAPI document, which also has the top-level openapi, info and paths fields that the generator needs:
components:
  schemas:
    Invoice:
      type: object
      required: [id, total]
      properties:
        id:
          type: string
        total:
          type: string
          pattern: "^[0-9]+\\.[0-9]{2}$"
          description: Amount in dollars, as a decimal string.
From a file like this you can generate client types, for example with bunx openapi-typescript openapi.yaml -o api.d.ts, and validators for tests. A contract test calls the real endpoint and checks the response against the published schema. Here ./schemas exports invoiceSchema, the Invoice schema above loaded as a plain JSON Schema object:
import { test, expect } from "bun:test";
import Ajv from "ajv";
import { invoiceSchema } from "./schemas";

const validateInvoice = new Ajv().compile(invoiceSchema);

test("GET /v1/invoices/:id matches the published schema", async () => {
  const res = await fetch(`${process.env.API_URL}/v1/invoices/inv_test_1`);
  const body = await res.json();
  validateInvoice(body);
  expect(validateInvoice.errors ?? []).toEqual([]);
});
Run against the agent's change, this test fails with "must be string" on /total. That failure forces the right conversation: either the schema changes, which is a public decision that can be reviewed as such, or the code changes back. A schema diff tool such as oasdiff can compare the old and new OpenAPI files in CI and fail the build on any change that breaks existing clients in a way the document can express, before a person even reads the diff. Promises the schema doesn't describe, such as the order items come back in or the unit of an amount, need tests of their own: a test that creates three events and asserts they come back newest first will catch a changed sort that no schema diff would.