
Where the Time and Money Go
Your order history page takes about half a second to load. You ask an agent to make it faster. It comes back with a rewrite of formatPrice, the function that turns an integer number of cents into a string like $1,234.50.
The new version caches its Intl.NumberFormat object instead of building one per call, and a microbenchmark shows it running ten times faster. The agent reports success.
You deploy it and the page still takes half a second. The agent optimized something that was slow in isolation, without checking whether it was slow in the page. This is a common way for performance work to fail: code gets faster in a place where the request was never spending its time.
Measure the request before touching the code
When a request's stages run one after another, its total time is the sum of the time spent in each, plus any time spent waiting. (When work overlaps, the total follows the critical path, the longest chain of steps that each wait on the one before, and that chain is what you measure.) So the first job is to find out how the total splits up. You can do that with a few lines of timing code around each stage:
type Timings = Record<string, number>;

async function timed<T>(label: string, timings: Timings, fn: () => T | Promise<T>): Promise<T> {
  const start = performance.now();
  try {
    return await fn();
  } finally {
    timings[label] = (timings[label] ?? 0) + (performance.now() - start);
  }
}

async function orderHistory(userId: string, db: Db) {
  const timings: Timings = {};
  const orders = await timed("orders query", timings, () =>
    db.query("SELECT id, placed_at FROM orders WHERE user_id = $1", [userId]));
  for (const order of orders) {
    order.items = await timed("items queries", timings, () =>
      db.query("SELECT * FROM order_items WHERE order_id = $1", [order.id]));
  }
  const html = await timed("render", timings, () => renderOrders(orders));
  console.log(timings);
  return html;
}
For a customer with 50 orders, one run prints something like this:
{ "orders query": 9.1, "items queries": 412.6, "render": 23.8 }Total: about 445 milliseconds. formatPrice runs inside render, and all of rendering is 24 ms. Suppose price formatting was 2 ms of that and the agent made it ten times faster. The function now takes 0.2 ms, so it saved 1.8 ms out of 445, less than half a percent.
Removing the function entirely would save 2 ms, about 0.45 percent, and that is the most any change to it could save, because a speedup to one part of a program can only remove the time that part was taking. This limit is called Amdahl's law, and it is why you measure the split before you choose what to optimize.
The real cost is the loop. It sends one query per order, 50 round trips to the database, each around 8 ms including the network. This shape is called an N+1 query: one query for the list, then one more for each item in it. One query for all the items replaces all 50:
const ids = orders.map((o) => o.id);
const items = await db.query("SELECT * FROM order_items WHERE order_id = ANY($1)", [ids]);
The code then groups the items by order_id in memory. That query takes around 10 ms, and the page drops from about 445 ms to about 45.
You can run both shapes against a stand-in database where every query waits 8 ms. Both return the same items. The first also scans the item list once per order, but those 50 scans take well under a millisecond, so the timing shows the round trips.
// A stand-in database: every query is one round trip of about 8 ms.
let roundTrips = 0;
const ITEMS = Array.from({ length: 150 }, (_, i) => ({ orderId: 1 + (i % 50), sku: `sku-${i}` }));
const orderIds = Array.from({ length: 50 }, (_, i) => i + 1);

async function query<T>(rows: () => T[]): Promise<T[]> {
  roundTrips++;
  await new Promise((r) => setTimeout(r, 8));
  return rows();
}

async function itemsOneQueryPerOrder() {
  const byOrder = new Map<number, unknown[]>();
  for (const id of orderIds) {
    byOrder.set(id, await query(() => ITEMS.filter((it) => it.orderId === id)));
  }
  return byOrder;
}

async function itemsInOneQuery() {
  const wanted = new Set(orderIds);
  const rows = await query(() => ITEMS.filter((it) => wanted.has(it.orderId)));
  const byOrder = new Map<number, unknown[]>();
  for (const row of rows) byOrder.set(row.orderId, [...(byOrder.get(row.orderId) ?? []), row]);
  return byOrder;
}

for (const [label, load] of [["one query per order", itemsOneQueryPerOrder], ["one query for all", itemsInOneQuery]] as const) {
  roundTrips = 0;
  const start = performance.now();
  const byOrder = await load();
  const ms = Math.round(performance.now() - start);
  console.log(`${label}: ${byOrder.size} orders, ${roundTrips} ${roundTrips === 1 ? "query" : "queries"}, ${ms} ms`);
}
Output
A CPU profiler would have been a poor tool for finding this. A sampling profiler records what the processor is executing, and while the code waits on the database, the process is mostly idle. The 400 ms of waiting barely appears in a CPU profile, while the 24 ms of rendering looks like the whole story.
For a request handler, start with wall-clock timing of each stage, or a tracing system that records spans for each query and outgoing call. Reach for a CPU profiler once you know the time is spent computing.
To catch a misplaced optimization, ask of any performance change what fraction of the request's time the changed code took before the change. If the agent cannot answer with a measurement, it has not found the bottleneck yet.
Averages hide the users who wait
One request tells you where the time goes. To know what users experience, you need the distribution over many requests. Latency is usually reported as percentiles. The p50 is the median; the p99 is the time that 99 percent of requests beat and 1 percent do not.
The average is a poor summary because latency distributions have long tails. A page where most requests take 40 ms and 2 percent take 3 seconds has an average near 100 ms, a number that describes no real user.
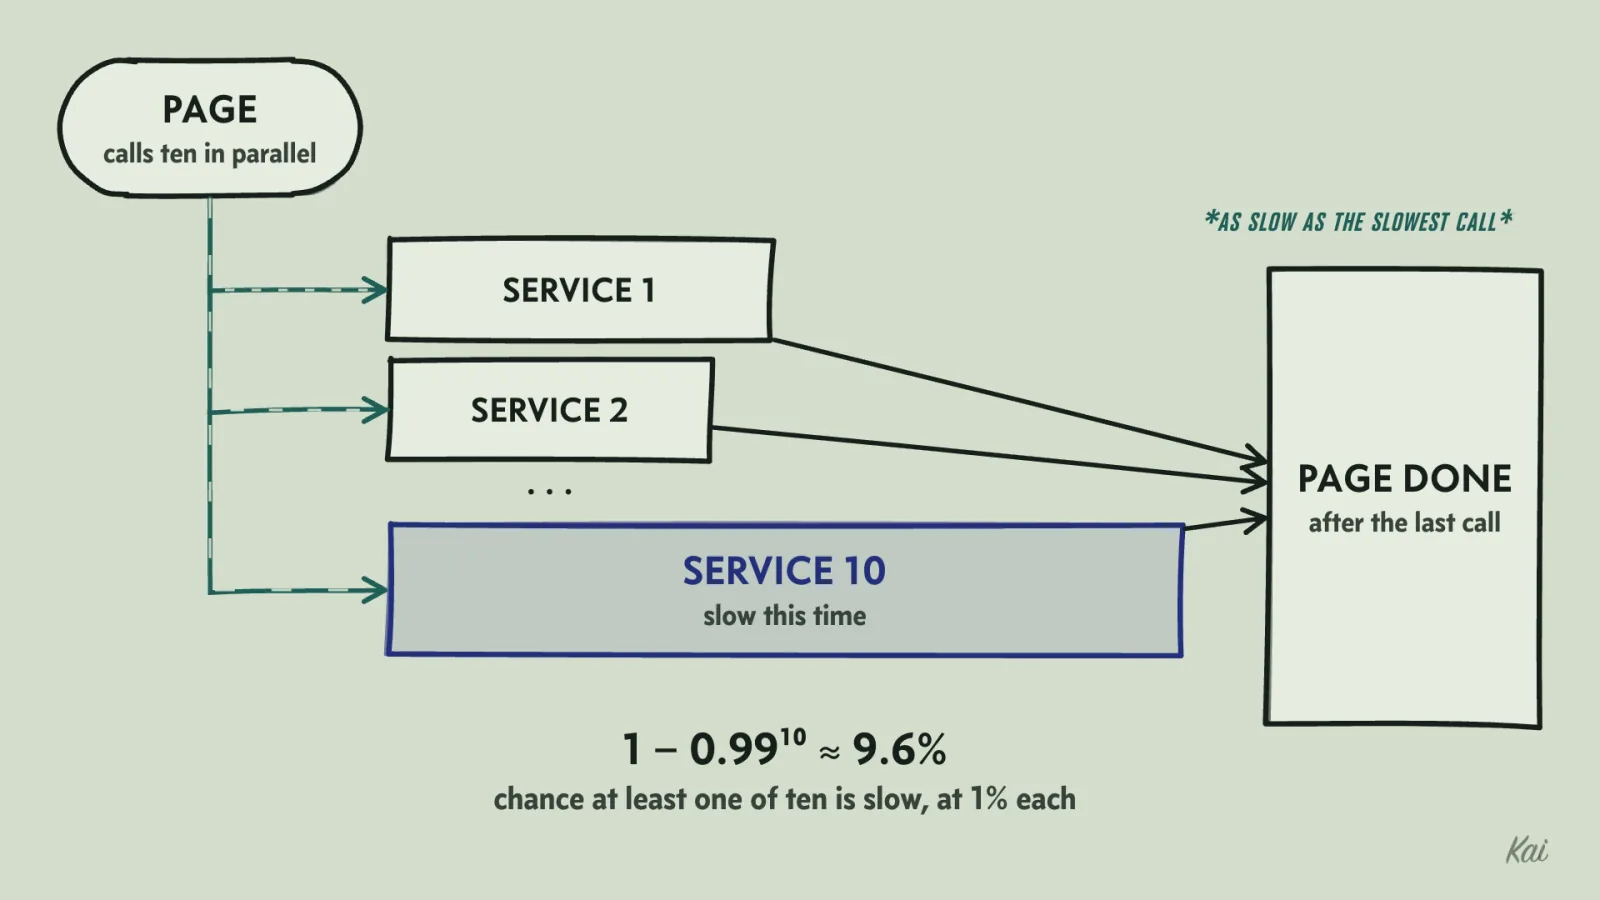
Tails also compound. If rendering a page calls ten backend services in parallel and waits for all of them, the page is as slow as the slowest call. If each service is slow on 1 percent of calls, and the slow calls are independent, the chance that at least one of the ten is slow is 1 − 0.99¹⁰, about 9.6 percent. A 1-in-100 problem in each service becomes a nearly 1-in-10 problem for the page.
Why it works for ten users and falls over at a thousand
The second measure is throughput: how many requests per second the system completes. Latency and throughput are tied together by a relation called Little's law. The average number of requests in progress equals the arrival rate times the average time each one spends in the system.
Apply it to a resource with a fixed number of slots, like a database connection pool. Say a checkout service runs with a pool of 10 connections per instance, and each checkout request holds a connection for 50 ms. Each connection can serve 20 requests per second, so the pool can serve at most 200 requests per second.
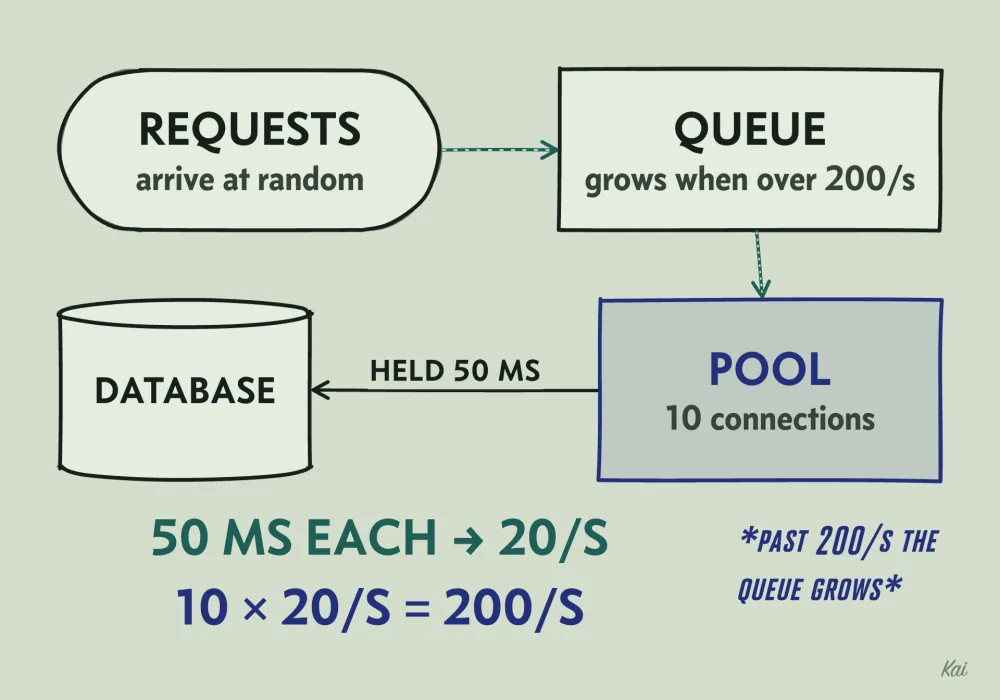
Below that average rate, most requests find a free connection, but bursts still queue: if 15 requests arrive within the same 50 ms, 5 of them wait for a connection. Above the average rate, the queue grows without limit, and nothing about the code has changed except the load.
Queues get worse faster than intuition suggests. In the simplest queueing model, one server with random arrivals and randomly varying (exponentially distributed) service times, the average time a request spends in the system is its service time divided by one minus the utilization. A pool of ten connections is a different model, so read the numbers below as the shape of the curve, not as a prediction for that pool.
At 50 percent utilization, a 50 ms operation takes 100 ms on average. At 90 percent, 500 ms. At 95 percent, a full second. The curve is nearly flat and then nearly vertical, which is why a system can look fine at 70 percent load and collapse at 95.
The checkout pool shows the same shape. This simulation sends randomly timed requests at 10 connections, each held for 50 ms, and reports each request's wait plus its 50 ms of work. The clock is simulated, so it finishes at once.
const POOL = 10;
const HOLD_MS = 50;
const REQUESTS = 20_000;

let seed = 42;
function random(): number {
  // A small seeded generator, so every run prints the same numbers.
  seed = (seed * 1664525 + 1013904223) % 4294967296;
  return seed / 4294967296;
}

function simulate(perSecond: number) {
  const freeAt = new Array<number>(POOL).fill(0);
  const waits: number[] = [];
  let now = 0;
  for (let i = 0; i < REQUESTS; i++) {
    now += (-Math.log(1 - random()) / perSecond) * 1000; // random gap until the next arrival
    const slot = freeAt.indexOf(Math.min(...freeAt)); // the connection that frees up first
    const start = Math.max(now, freeAt[slot]);
    freeAt[slot] = start + HOLD_MS;
    waits.push(start - now);
  }
  const sorted = [...waits].sort((a, b) => a - b);
  const pct = (p: number) => Math.round(sorted[Math.floor(p * (sorted.length - 1))] + HOLD_MS);
  return { p50: pct(0.5), p99: pct(0.99), lastWait: Math.round(waits[waits.length - 1]) };
}

for (const rate of [50, 100, 150, 180, 190, 195, 210]) {
  const r = simulate(rate);
  console.log(`${rate}/s  p50 ${r.p50} ms  p99 ${r.p99} ms  last request waited ${r.lastWait} ms`);
}
Output
Up to 150 per second the median request does not wait at all. At 195, which is 97.5 percent of capacity, the p99 is more than ten times the work itself. At 210 the arrivals outpace the pool, and the wait keeps growing for as long as the traffic lasts.
With ten users, none of this is visible. The pool is idle most of the time. That is why these limits are found in production unless you look for them on purpose.
The same arithmetic applies to every fixed limit on the path. Postgres ships with max_connections set to 100. If autoscaling runs 15 instances, each with a pool of 10, they will try to open 150 connections and some will be refused.
A third-party API with a limit of 600 requests per minute supports 10 per second across your whole fleet, however many instances you run. When you review an agent's design, list every pool, limit and quota on the request path, and divide.
Load testing: finding the knee
A load test sends traffic at a controlled rate and records latency and errors. Raise the rate in steps and hold each step long enough for the numbers to settle. Here is what that looks like for one instance of the checkout service:
| Requests/sec | p50 | p99 | Errors |
|---|---|---|---|
| 50 | 58 ms | 110 ms | 0% |
| 100 | 60 ms | 130 ms | 0% |
| 150 | 68 ms | 240 ms | 0% |
| 190 | 140 ms | 900 ms | 0% |
| 220 | 2.1 s | timeout | 12% |
The degradation point, often called the knee, is between 150 and 190. Past it, latency climbs quickly while throughput stops growing.
The table shows where the service degrades. To find the cause, check each resource the request uses for three things: how busy it is (utilization), how much work is waiting for it (saturation), and whether it is returning errors. Brendan Gregg calls this the USE method.
Here the database CPU sits at 35 percent, which rules out CPU saturation and nothing else: lock waits, slow storage or a single saturated core could still limit it. So check those as well. In this test, lock waits stay near zero and each query still takes about 12 ms at the knee, so the database is not what slows down. The application's CPU is at 40 percent. The pool's wait time, the time requests spend waiting for a free connection, rises from zero to hundreds of milliseconds right at the knee. The bottleneck is the connection pool, and its ceiling matches the 200 per second from the arithmetic.
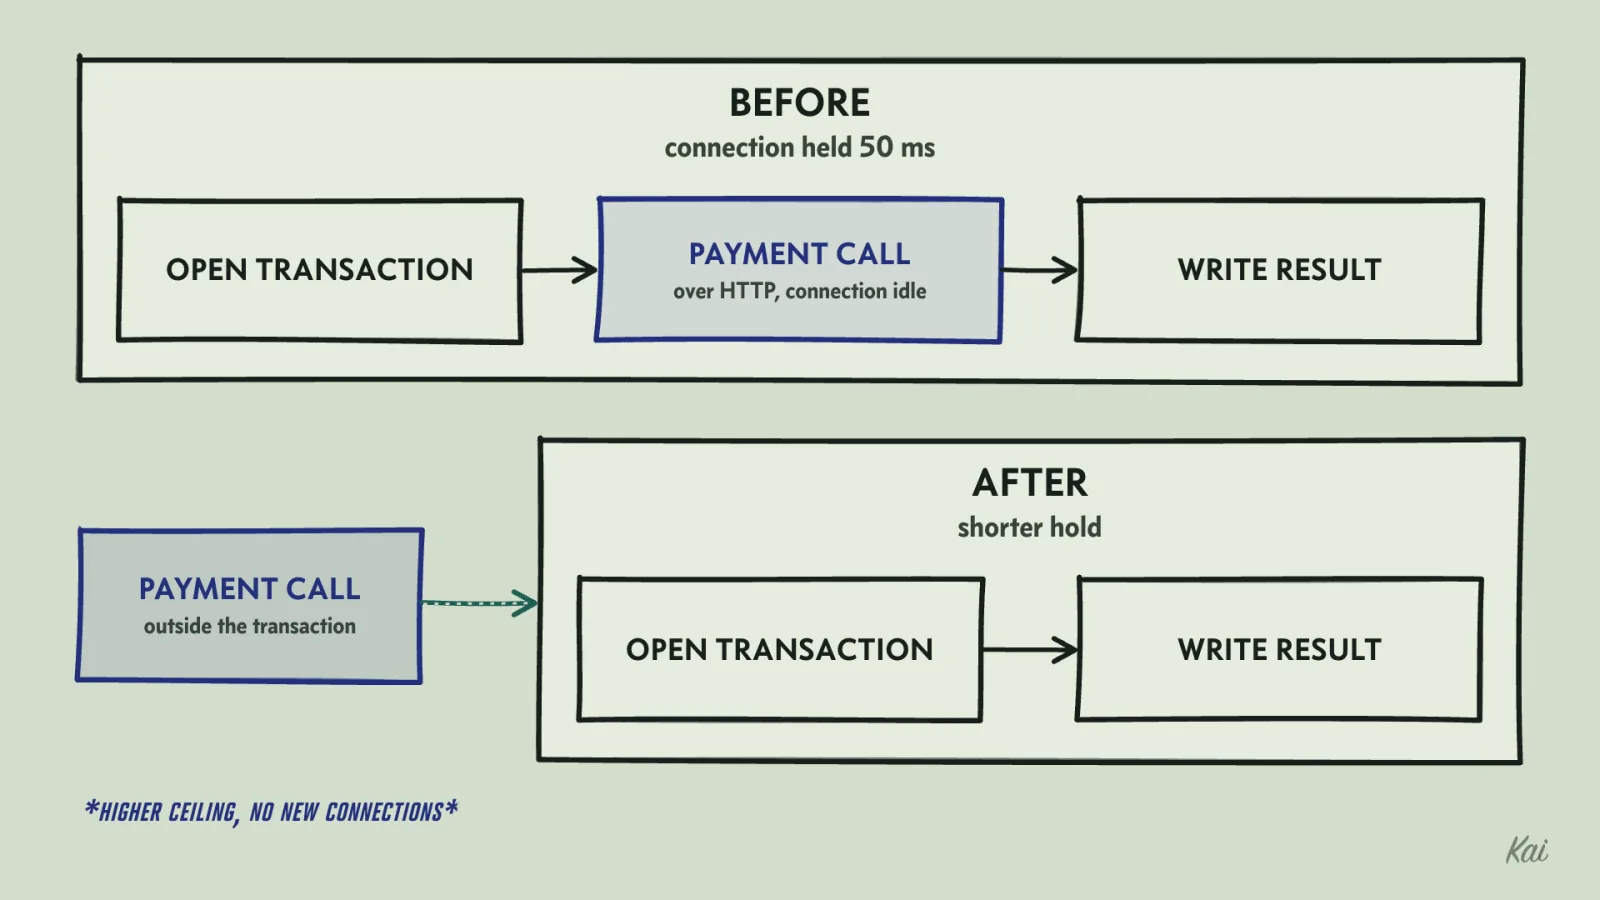
Reading the handler shows why each request holds a connection for 50 ms when its queries take 12: it opens a transaction, calls a payment provider over HTTP, then writes the result. The connection sits idle during the HTTP call. Moving the call outside the transaction shortens the hold time and raises the ceiling without adding a single connection.
Many load generators send a request, wait for the response, then send the next. When the server slows down, such a generator slows its own sending rate, so it never produces the queue a real crowd would, and it under-reports latency at the tail.
Gil Tene named this effect coordinated omission. Configure the tool to send at a fixed arrival rate whatever the server does. In k6 that is the constant-arrival-rate executor.
Caches: every input belongs in the key
Once you know where the time goes, a cache is often the fix. A cache stores the result of a computation under a key, so the next request with the same key skips the work. It is correct only when two requests with the same key would have produced the same result. So the key must include every input the result depends on.
Keys go wrong because many inputs are implicit. Take an endpoint that quotes shipping for a product:
async function shippingQuote(productId: string, viewer: { country: string; tier: "member" | "free" }) {
  const key = `shipping:${productId}`;
  const hit = await cache.get(key);
  if (hit) return hit;
  const quote = await computeShipping(productId, viewer.country, viewer.tier);
  await cache.set(key, quote, { ttlSeconds: 300 });
  return quote;
}
The key has one input and the computation has three. The first visitor after the cache expires decides the quote everyone sees for the next five minutes. If that visitor was a paid member in Germany, customers in the United States see free shipping priced in euros.
Here is the same mistake with a plain map as the cache, next to a key that holds every input.
type User = { country: "DE" | "US"; tier: "member" | "free" };
type Quote = { cents: number; currency: "EUR" | "USD" };

const cache = new Map<string, Quote>();

function computeShipping(productId: string, country: User["country"], tier: User["tier"]): Quote {
  const cents = tier === "member" ? 0 : country === "DE" ? 690 : 850;
  return { cents, currency: country === "DE" ? "EUR" : "USD" };
}

function cached(key: string, compute: () => Quote): Quote {
  const hit = cache.get(key);
  if (hit) return hit;
  const quote = compute();
  cache.set(key, quote);
  return quote;
}

const keyOnProduct = (productId: string, user: User) =>
  cached(`shipping:${productId}`, () => computeShipping(productId, user.country, user.tier));

const keyOnEveryInput = (productId: string, user: User) =>
  cached(`shipping:${productId}:${user.country}:${user.tier}`, () => computeShipping(productId, user.country, user.tier));

const memberInGermany: User = { country: "DE", tier: "member" };
const visitorInUS: User = { country: "US", tier: "free" };

for (const [label, quote] of [["key on product only", keyOnProduct], ["key on every input", keyOnEveryInput]] as const) {
  cache.clear();
  const first = quote("lamp-42", memberInGermany);
  const second = quote("lamp-42", visitorInUS);
  console.log(`${label}: member in Germany pays ${(first.cents / 100).toFixed(2)} ${first.currency}, visitor in the US pays ${(second.cents / 100).toFixed(2)} ${second.currency}`);
}
Output
To audit a cache, read the function it wraps and list everything it reads: its arguments, plus the current user, their session, locale, country, permissions, feature flags and the clock. Every item on that list must be in the key, or must provably not change the output. When the output belongs to one user, either the user's ID goes in the key or the response stays out of any shared cache.
HTTP caches follow the same rule. A response marked Cache-Control: private may be stored by the user's browser but not by a CDN or proxy. Vary tells a cache which request headers to add to its key. A page carrying a user's account details that is served without either can be stored once and handed to the next visitor.
The other half of correctness is staleness. A cached value is a copy, and the original can change. Deleting the cache entry when the data is written helps, but it has a race.
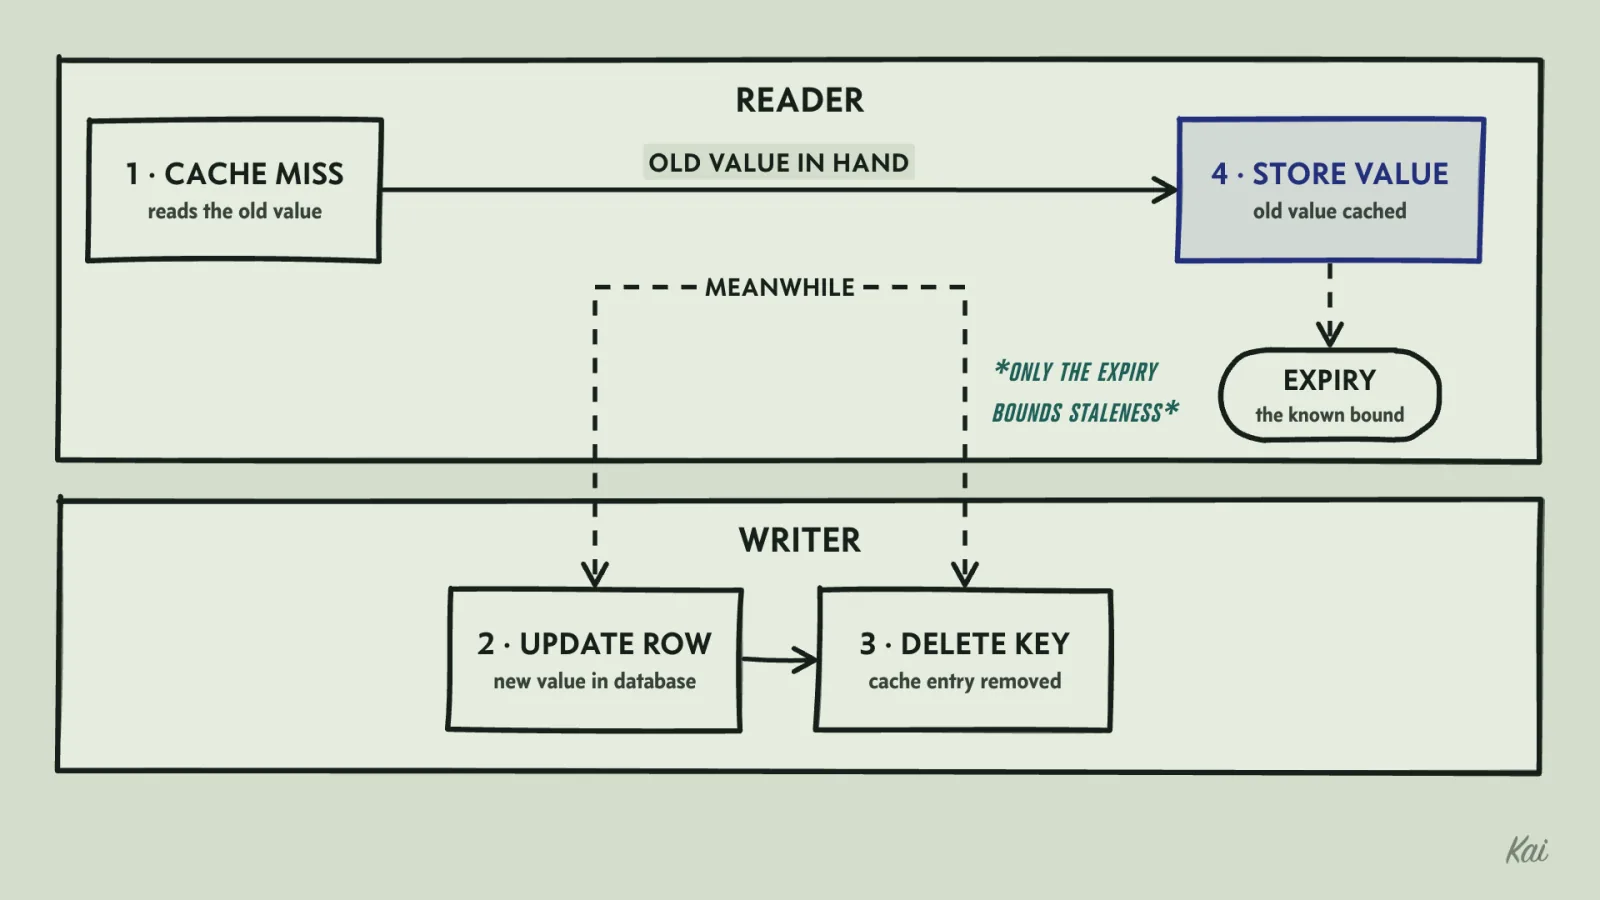
A reader misses the cache and reads the old value from the database. A writer updates the row and deletes the key. The reader then stores its old value in the cache, where it stays. For that reason, every cache entry should carry an expiry even when you also invalidate on write, so that the worst-case staleness has a known bound.
Put a ceiling on cost
Capacity costs money, and some capacity scales itself. An autoscaler with no maximum answers a traffic spike, or a bot, by adding instances until the bill stops it. A feature that calls a language model does the same thing per request.
Suppose each call costs one cent. A scraper hitting that endpoint 50 times a second makes 4.32 million calls a day, which is $43,200 a day.
Treat spend like latency: measure it per feature, set a budget, and alert when it moves. Then put a hard ceiling in front of every resource that scales with traffic, such as a maximum instance count, a per-user rate limit on model calls, and a spending cap with the provider where one exists.
For any design an agent hands you, compute two numbers before it ships: the request rate at which the first fixed limit on its path is exhausted, and the most it can cost in one hour if traffic goes to a hundred times normal.