
What the Machine Does Under Your Script
An agent hands you a nightly export job. It pulls every order from the database, writes them to a CSV file, and a second script uploads that file to a partner. You run it on your laptop against a test database with 2,000 orders. It finishes in a second, the file looks right, and the agent reports success.
Every line of that job asks the hardware and the operating system to do something, and each of those requests has a cost and a failure mode. Most of them are invisible at 2,000 rows. They show up at 20 million rows, during a power cut, or when the job runs on a platform with rules your laptop does not have. To catch them in review you need a working picture of what the machine is doing underneath.
The CPU and the gap between speeds
A CPU core does one simple thing very fast. It fetches an instruction, such as "add these two registers" or "load 8 bytes from this address", carries it out, and moves to the next one. Registers are a few dozen small slots inside the core. A modern core runs at 3 to 5 billion cycles per second and can finish several instructions per cycle, so arithmetic on values already in registers costs almost nothing.
The trouble is getting data into those registers. The data your program uses lives in main memory (RAM), and RAM is far away in CPU terms. So the chip keeps small, fast copies of recently used memory in caches, and when those miss it goes to RAM, and when the data is not in RAM it goes to storage or across a network. Each step down is far slower.
These are rough figures for current hardware. They vary by machine, but the ratios hold.
| Operation | Rough time |
|---|---|
| L1 cache hit | about 1 ns |
| Main memory read | about 100 ns |
| SSD random read | 20 to 100 µs |
| Round trip inside a data center | around 0.5 ms, often less |
| Round trip across a continent (US coast to coast) | about 70 ms |
Stretch the scale until one memory read takes a minute. A cache hit then takes under a second. An SSD read takes between three and seventeen hours, a round trip inside the data center takes about three and a half days, and a request across the United States takes more than a year.
Two things follow. A program that touches memory in order, row after row, runs far faster than one that jumps around, because the cache loads memory in lines of 64 bytes on most chips, and the next value is usually already there. And any design that crosses the network in a loop is paying the most expensive price on the table.
The block below adds up the same four million numbers in two orders. The grid is stored row after row, so reading by rows walks memory in order, and reading by columns jumps 16 KB between reads. Each order runs twice, because a function's first run includes the engine's warm-up.
// A 2048 x 2048 grid of numbers, stored row after row in one block of memory.
const n = 2048;
const grid = new Float64Array(n * n).fill(1);

function byRows() {
  let sum = 0;
  for (let r = 0; r < n; r++) for (let c = 0; c < n; c++) sum += grid[r * n + c]; // the next 8 bytes
  return sum;
}
function byColumns() {
  let sum = 0;
  for (let c = 0; c < n; c++) for (let r = 0; r < n; r++) sum += grid[r * n + c]; // 16 KB further on
  return sum;
}

for (const add of [byRows, byColumns, byRows, byColumns]) {
  const start = performance.now();
  const sum = add();
  console.log(`${add.name.padEnd(9)} sum ${sum}  ${(performance.now() - start).toFixed(1)} ms`);
}
Output
On the laptop this lesson was checked on, the column order took three to five times as long.
Processes and the memory they are given
When you type bun export.ts into a shell, a sequence of steps runs before any of your code does. The shell reads the line, splits it into words and searches the directories in PATH for a program called bun. It then asks the kernel to create a new process (on Unix, with fork) and to replace that process's program with Bun (with exec). The kernel sets up a fresh address space, loads the Bun runtime, and starts it running on some core.
From there the program runs until it calls exit with a number, or until the kernel kills it. The shell has been waiting with wait, and when the process ends the kernel hands the shell that number. The shell stores it in $?. Zero means success, and anything else means failure.
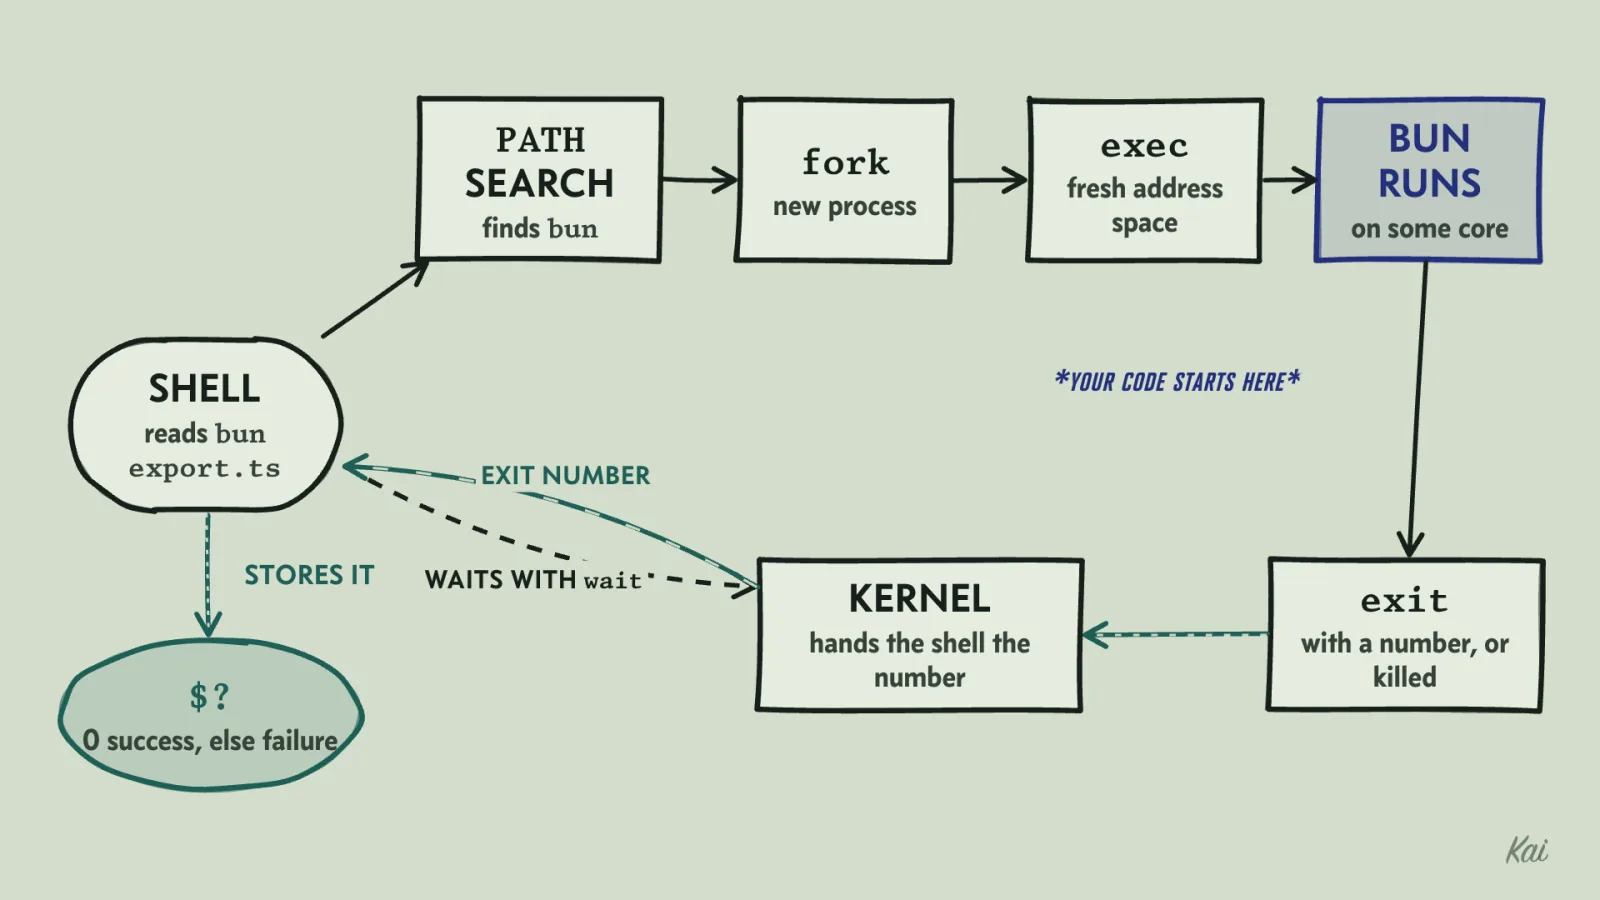
$?.The address space is virtual. Your process sees one large, private range of addresses, and the kernel maps the pages you actually use onto physical RAM. This is how the operating system isolates programs from each other: one process cannot read another's memory because the other process's pages are absent from its map. It also means memory can run out in a way that has nothing to do with your code being wrong.
Here is the agent's export job.
import { writeFileSync } from "node:fs";
import postgres from "postgres";

type Order = { id: string; customer_id: string; total_cents: number; created_at: Date };
const toLine = (o: Order) => `${o.id},${o.customer_id},${o.total_cents},${o.created_at.toISOString()}\n`;

async function exportOrders(sql: postgres.Sql, path: string) {
  const rows = await sql<Order[]>`SELECT id, customer_id, total_cents, created_at FROM orders`; // every row, in memory, at once
  writeFileSync(path, rows.map(toLine).join(""));
}

const sql = postgres(process.env.DATABASE_URL!);
try {
  await exportOrders(sql, process.argv[2]);
  console.log("export complete");
} catch (e) {
  console.log(`export failed: ${e}`);
} finally {
  await sql.end();
}
The query builds a JavaScript object for every row, then map and join build the whole file as one string before anything is written. Measured in Bun, each row costs roughly two hundred bytes once you count its object, its Date and its line of text. At 2,000 rows that is under a megabyte. At 20 million rows it is about four gigabytes, and the process's memory grows until it hits a limit.
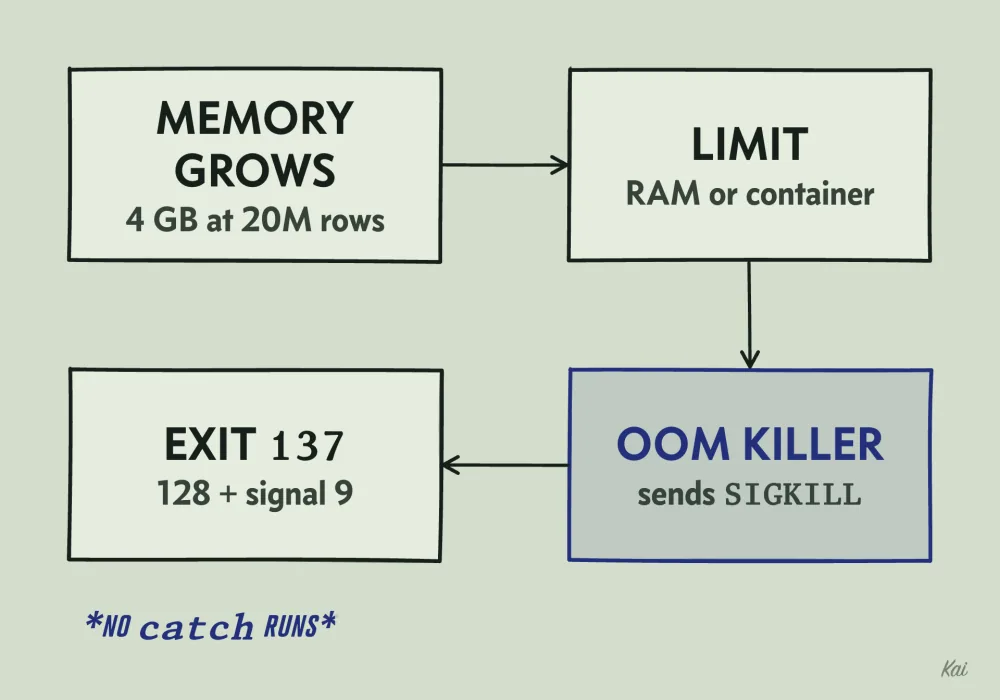
catch block runs, and the job log only shows 137.That limit might be the machine's physical RAM, or it might be a container limit set far lower. When it is reached on Linux, the kernel's out-of-memory killer sends the process SIGKILL. The process gets no chance to run a catch block or print a message.
The shell reports the exit status as 128 plus the signal number, so a process killed by signal 9 shows up as 137. If you see 137 in a job log, look for memory growth first. Node also has its own heap limit: hitting it prints "JavaScript heap out of memory" and aborts with 134, again skipping every catch.
The fix is to stream. Ask the database for rows in batches, write each batch, and let it go.
import { open } from "node:fs/promises";

async function exportOrders(sql: postgres.Sql, path: string) {
  const file = await open(path, "w");
  try {
    const query = sql<Order[]>`SELECT id, customer_id, total_cents, created_at FROM orders`;
    for await (const rows of query.cursor(10_000)) { // fetches 10,000 rows per round trip
      await file.writeFile(rows.map(toLine).join("")); // writes the whole chunk before resolving
    }
  } finally {
    await file.close();
  }
}
Memory use is now set by the batch size, and it stays flat whether the table has two thousand rows or two billion. The same question applies to any code that reads input: does its memory grow with the size of the data? If readFileSync, await file.text(), JSON.parse of a whole file, or a query with no cursor or LIMIT appears, the answer is yes.
When a write is actually written
The streaming version still has a problem. When file.writeFile resolves, the data has usually not reached the disk.
There can be two layers of buffering between your code and the SSD. First, many write APIs buffer inside your process: a Node stream from createWriteStream queues chunks in memory and flushes them to the kernel later, while FileHandle.writeFile repeats the write system call until the kernel has the whole chunk, since one write may take only part of it. Second, the kernel's write system call copies the data into the page cache, which is kernel memory, and returns immediately.
The kernel writes dirty pages to the device later, typically within tens of seconds. If the machine loses power in between, the data is gone, even though every call your program made returned success.
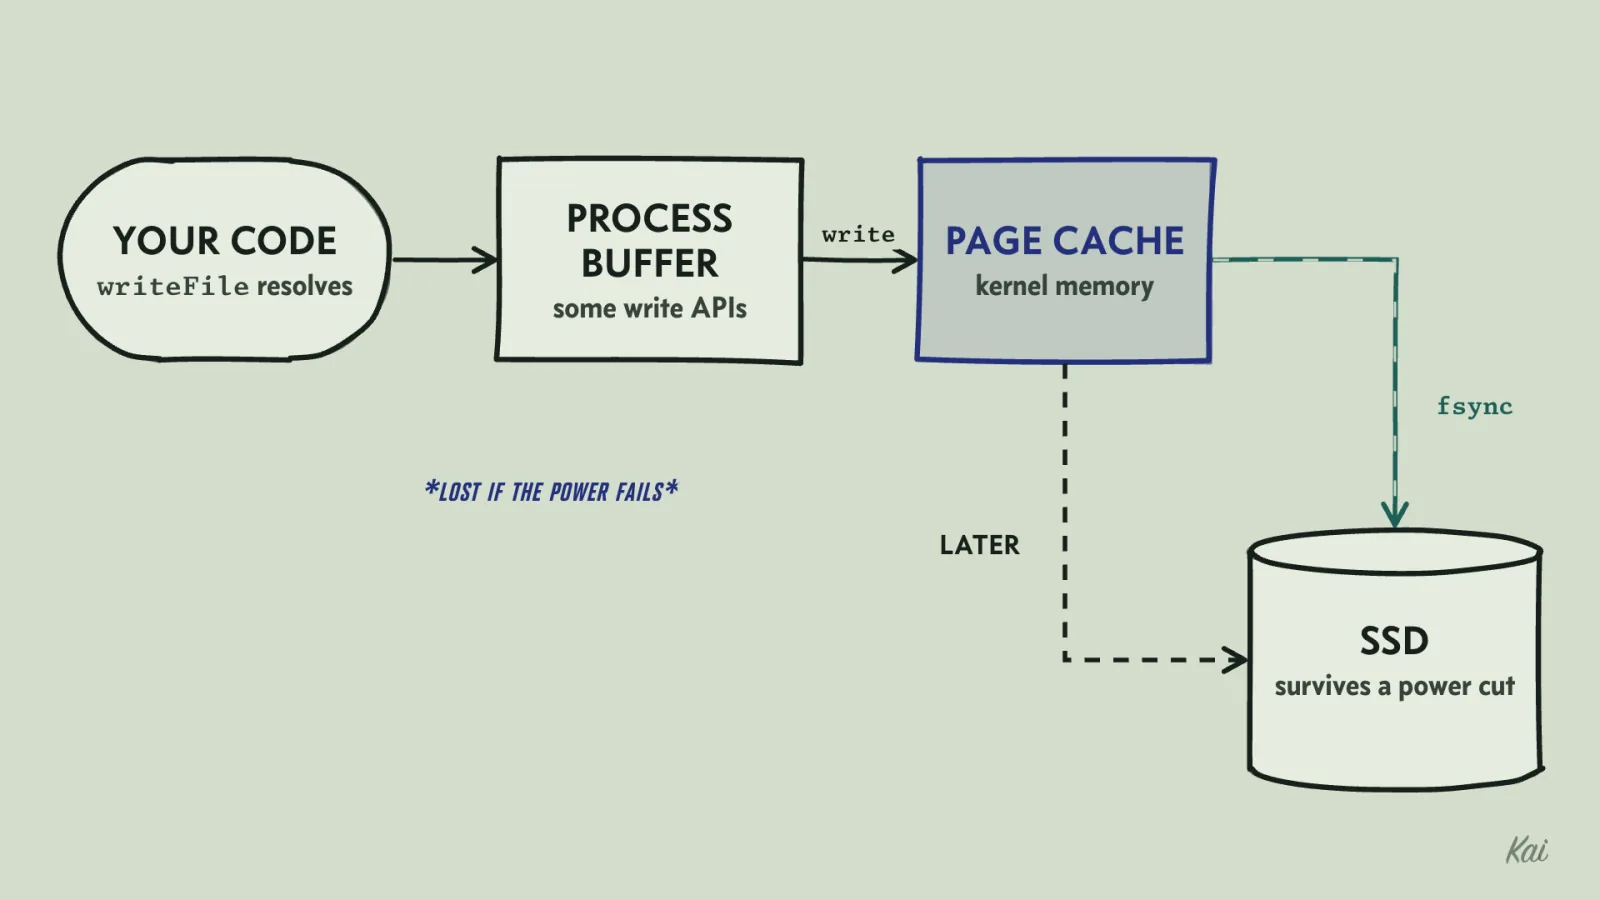
fsync, puts it on the device that survives a power cut.The call that forces data down to the device is fsync, which Node exposes as FileHandle.sync(). It returns only when the kernel has sent the file's data and metadata to storage and the device reports it done. For a newly created file there is one more step: the directory entry that names the file is also data, and it needs its own fsync on the directory.
A file that another program will read should appear all at once or not at all. The standard pattern is to write to a temporary name, sync it, and rename it into place, because a rename within one filesystem is atomic. Each call gets its own temporary name, or two exports running at once would write into the same file.
import { randomUUID } from "node:crypto";
import { open, rename, type FileHandle } from "node:fs/promises";
import { dirname } from "node:path";

async function writeDurably(path: string, writeRows: (file: FileHandle) => Promise<void>) {
  const tmp = `${path}.${randomUUID()}.tmp`; // one temp file per call
  const file = await open(tmp, "wx");          // fails if that name already exists
  try {
    await writeRows(file); // each write hands its chunk to the kernel
    await file.sync();     // kernel page cache -> device (fsync)
  } finally {
    await file.close();
  }
  await rename(tmp, path); // atomic swap on the same filesystem
  const dir = await open(dirname(path), "r");
  try {
    await dir.sync();      // make the rename itself durable
  } finally {
    await dir.close();
  }
}
This toy file system has a page cache that programs see and a disk that survives a power cut. It cuts the power after every step of two strategies and shows what orders.csv holds afterward.
// A toy file system with a page cache. `cache` is what programs see; `disk` is what survives a power cut.
let cache = new Map<string, string>();
let disk = new Map<string, string>();
let pendingRenames: [string, string][] = [];

const write = (name: string, data: string) => cache.set(name, (cache.get(name) ?? "") + data);
const fsync = (name: string) => disk.set(name, cache.get(name) ?? "");
const rename = (from: string, to: string) => {
  cache.set(to, cache.get(from) ?? "");
  cache.delete(from);
  pendingRenames.push([from, to]); // the directory change is cached too
};
const fsyncDir = () => {
  for (const [from, to] of pendingRenames) { disk.set(to, disk.get(from) ?? ""); disk.delete(from); }
  pendingRenames = [];
};

type Step = [label: string, run: () => void];
const inPlace: Step[] = [
  ["open orders.csv, truncating it", () => cache.set("orders.csv", "")],
  ["write rows 1-2", () => write("orders.csv", "B1 B2")],
  ["kernel writes dirty pages back", () => fsync("orders.csv")], // it may do this at any moment
  ["write rows 3-4", () => write("orders.csv", " B3 B4")],
  ["report saved", () => {}],
];
const tempThenRename: Step[] = [
  ["write rows 1-2 to orders.csv.tmp", () => write("orders.csv.tmp", "B1 B2")],
  ["kernel writes dirty pages back", () => fsync("orders.csv.tmp")],
  ["write rows 3-4", () => write("orders.csv.tmp", " B3 B4")],
  ["fsync orders.csv.tmp", () => fsync("orders.csv.tmp")],
  ["rename to orders.csv", () => rename("orders.csv.tmp", "orders.csv")],
  ["fsync the directory", fsyncDir],
  ["report saved", () => {}],
];

// Replay each strategy, cutting the power after every step, and read orders.csv from disk.
for (const [name, steps] of [["write in place", inPlace], ["temp file, fsync, rename", tempThenRename]] as const) {
  console.log(name);
  for (let cut = 0; cut < steps.length; cut++) {
    cache = new Map([["orders.csv", "A1 A2 A3 A4"]]);
    disk = new Map(cache);
    pendingRenames = [];
    for (const [, run] of steps.slice(0, cut + 1)) run();
    console.log(`  power cut after ${steps[cut][0].padEnd(33)} disk has [${disk.get("orders.csv")}]`);
  }
}
Output
Written in place, the disk can hold half a new file after the job reported "saved". With the temporary file, a power cut leaves the whole old export or the whole new one.
When code reports "saved" or "committed" to a user or another system, find the line that makes it true. If the answer is a write call with no fsync after it, the claim holds only as long as the power stays on. Databases do this work for you on commit, which is one reason to put important state in a database rather than a hand-written file.
Exit codes are the job's only report
Look again at the first version's catch block. It catches every error, prints a message and lets the script run to its end. A Bun or Node script that reaches its end exits with status 0. Without the catch, the error would have ended the script with status 1, so the catch-all is what turned a failure into a success.
The scheduler that runs it sees 0 and records a success. The upload step that runs next gets whatever the failure left behind: a partial file, the previous night's export, or no file at all.
Nothing downstream reads your log messages. The scheduler, the CI system, the shell script that chains steps together and the orchestrator that restarts failed containers all make their decision from the exit status. A failure has to reach that number.
try {
  await exportOrders(sql, process.argv[2]);
  console.log("export complete");
} catch (e) {
  console.error(`export failed: ${e}`);
  process.exitCode = 1; // the script exits 1 after the finally block closes the connection
} finally {
  await sql.end();
}
Shell scripts have the same problem in a different form. By default, bash keeps going after a command fails, and a pipeline's status is the status of its last command only.
#!/usr/bin/env bash
set -euo pipefail   # exit on most failures, error on unset variables, fail if any pipe stage fails

bun export.ts /data/orders.csv
gzip -c /data/orders.csv > /data/orders.csv.gz
upload /data/orders.csv.gz
Without set -e, a failed bun line is ignored and upload runs anyway. Without pipefail, bun export.ts | gzip > out.gz reports gzip's success even when the export crashed.
set -e has exceptions. It does not fire for a command that is an if or while condition, or one followed by && or ||, so bun export.ts || echo "failed" carries on after a failure. When you review a script, check what happens to each command's status and whether the script's own exit code reflects the worst thing that happened.
The platform has rules your laptop does not
Your laptop lets a process use most of the machine's memory and run for as long as it likes. Production platforms set limits, and they enforce them by stopping the process.
A container has a memory limit, and crossing it gets the process killed as described above. A router in front of a web app may give up on a slow request; Heroku's router, for example, answers the client with an error after 30 seconds. That ends the client's wait, but the app keeps working on the request, and it may finish long after the client has left.
A serverless function has a hard execution limit, which on AWS Lambda is 15 minutes, and the platform stops the function when it is reached. Some platforms give the process a termination signal and a short grace period before the kill, and some just kill it.
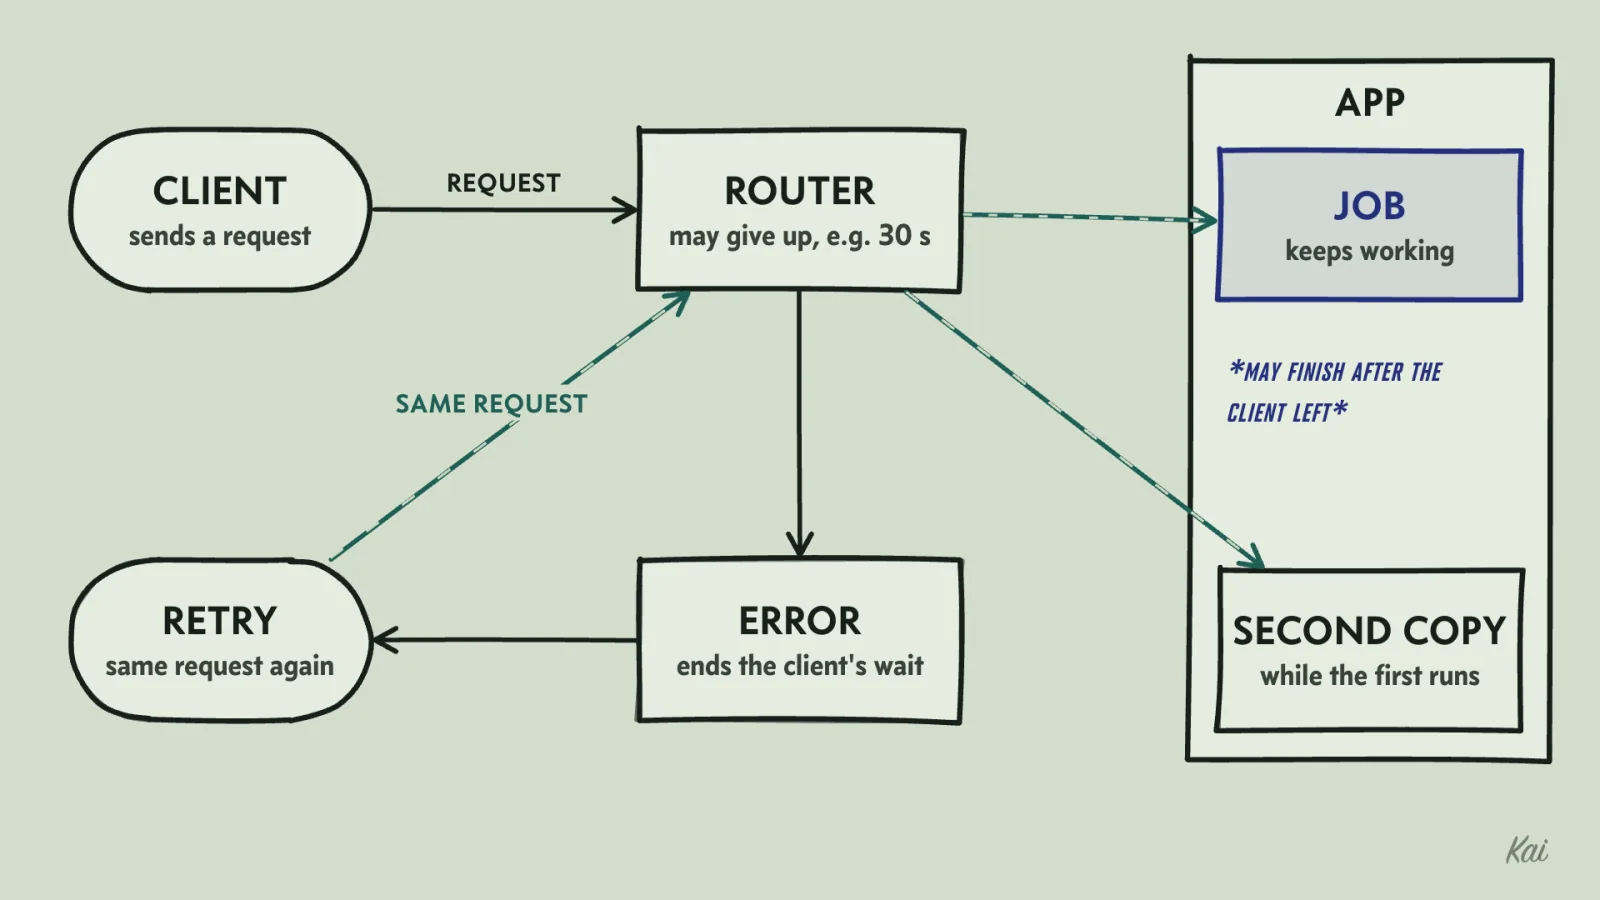
So a job that takes three minutes on your laptop and runs inside a web request shows the client an error at 30 seconds while the work carries on, and a retry can start a second copy. Under a hard limit the same job is stopped midway, every time. When an agent writes background work, ask where it will run and what that environment's limits are for memory, CPU time, disk and duration. Then compare those limits with the size of the real input, estimated from production data rather than the test fixture.
Seeing what a process is actually doing
When a program fails in a way its logs do not explain, you can watch its conversation with the kernel. Opening a file, connecting a socket and asking for data all go through system calls, and two standard tools show them. A trace shows those requests and not every byte, because buffered readers fetch data in large chunks and memory-mapped files are read without a call per read.
lsof lists the open files of a process, and on Unix sockets count as files. lsof -p 41822 shows everything process 41822 has open. lsof -i :8080 shows which process is listening on port 8080, which explains why a server fails to start with "address already in use".
COMMAND   PID USER   FD   TYPE  DEVICE SIZE/OFF NODE NAME
node    41822 app    23u  IPv4  812345      0t0  TCP *:8080 (LISTEN)
The FD column is the file descriptor number the process uses for that file, and the NAME column is the file path or the address and port.
strace on Linux prints each system call as it happens, with its arguments and return value. strace -f -e trace=openat,connect bun export.ts limits the output to file opens and network connections.
openat(AT_FDCWD, "/etc/export/config.yaml", O_RDONLY) = -1 ENOENT (No such file or directory)
connect(3, {sa_family=AF_INET, sin_port=htons(5432), sin_addr=inet_addr("10.0.4.12")}, 16) = -1 ECONNREFUSED (Connection refused)
The first line says the program looked for its config at a path that does not exist. The second says it tried to reach a database on port 5432 at 10.0.4.12 and nothing was listening. The return value after = is the kernel's answer, and a negative number with an error name is the real reason the program failed, whatever the program chose to print. On macOS, lsof works the same way, and fs_usage or dtruss fill the role of strace.
For a summary in place of a stream, strace -c bun export.ts prints a table of how many times each system call ran and how long each took, which shows whether the job spends its time reading, writing or waiting.