
Two Requests, One Row
An agent writes you an endpoint that adds loyalty points to an account. It is four lines long and obviously correct:
const { rows } = await db.query("SELECT points FROM accounts WHERE id = $1", [id]);
const next = rows[0].points + earned;
await db.query("UPDATE accounts SET points = $1 WHERE id = $2", [next, id]);
return next;It passes every test, because every test sends one request at a time. In production the same customer checks out on their phone while a referral bonus is credited in the background, and the two requests arrive a few milliseconds apart.
Both requests report success and nothing is logged, yet the account ends up holding only one of the two changes.
The database did exactly what it was told, one statement at a time. The bug lives in the gap between the SELECT and the UPDATE, and to see it you have to think about two requests at once.
The lost update, step by step
Call the two requests A and B. The account starts with 100 points. A adds 10, B adds 50. Here is one order the database is allowed to run their statements in:
| Step | Request A | Request B | Stored value |
|---|---|---|---|
| 1 | reads 100 | 100 | |
| 2 | reads 100 | 100 | |
| 3 | writes 110 | 110 | |
| 4 | writes 150 | 150 |
The right answer is 160. B computed its new value from a number that was already stale by the time it wrote, so A's change was overwritten. This is called a lost update, and it appears anywhere code reads a value, computes a new one in the application, and writes it back: balances, counters, inventory, the number of seats left.
You can reproduce it by hand with two terminal sessions connected to the same database. In session 1, run BEGIN; and the SELECT. In session 2, run the whole read and write and commit. Then go back to session 1, write the value it computed, and commit. At PostgreSQL's default isolation level, Read Committed, both transactions commit without an error and session 1's write overwrites session 2's change.
For an automated test, you need the two reads to both happen before either write. The simplest way is to fire many requests in parallel and check the total:
test("concurrent point grants are not lost", async () => {
  await resetAccount(id, 0);
  await Promise.all(Array.from({ length: 50 }, () => addPoints(id, 1)));
  expect(await getPoints(id)).toBe(50);
});
With the four-line version, this test usually ends with a total below 50, as long as addPoints goes through a connection pool with more than one connection. A test like this can pass by luck, so a stronger version forces the interleaving: pause request A after its read (with a hook, or a barrier both requests wait on) until request B has also read.
Closing the gap
The first fix is to stop doing arithmetic in the application. Let the database compute the new value inside a single statement:
UPDATE accounts SET points = points + $1 WHERE id = $2 RETURNING points;An UPDATE takes a lock on the row it changes. At Read Committed, if two of these arrive together, the second waits for the first to commit, then re-reads the committed row and adds to it. Nothing is lost, because there is no longer a moment where one request holds a stale copy. At Repeatable Read or Serializable the second one instead fails with a serialization error and has to be retried.
You can watch both versions run against an in-memory table where every query takes 5 ms. The stand-in for the single UPDATE reads and writes in one step that nothing can come between, which is what the row lock gives the real statement.
const accounts = new Map<number, number>();
const roundTrip = () => new Promise((resolve) => setTimeout(resolve, 5));

// The agent's version: read, add in the application, write back.
async function addPoints(id: number, earned: number) {
  await roundTrip();
  const points = accounts.get(id)!;          // SELECT points ...
  await roundTrip();
  accounts.set(id, points + earned);         // UPDATE accounts SET points = $1 ...
}

// The fix: UPDATE accounts SET points = points + $1, one statement.
async function addPointsAtomic(id: number, earned: number) {
  await roundTrip();
  accounts.set(id, accounts.get(id)! + earned);
}

for (const add of [addPoints, addPointsAtomic]) {
  accounts.set(1, 100);
  await Promise.all([add(1, 10), add(1, 50)]);
  const pair = accounts.get(1);

  accounts.set(1, 0);
  await Promise.all(Array.from({ length: 50 }, () => add(1, 1)));
  console.log(`${add.name}: 100 + 10 + 50 = ${pair}; fifty grants of 1 = ${accounts.get(1)}`);
}
Output
The read-then-write version loses A's 10 points, exactly as in the table. With fifty requests, all fifty read 0 before any of them writes, so the total is 1.
That works when the new value is a simple function of the old one. When there is a rule to check first, such as "stock may not go below zero", you can often fold the rule into the same statement:
UPDATE products SET stock = stock - $1
WHERE sku = $2 AND stock >= $1;
Then check how many rows it changed. Zero rows means either the rule failed or no product has that sku, so a caller that needs to tell "sold out" from "no such product" has to look further. At Read Committed no other request can slip in between the check and the write, because they are the same statement.
The second fix is to keep the read and the write separate but hold a lock between them. SELECT ... FOR UPDATE reads the row and locks it until the transaction ends:
BEGIN;
SELECT points FROM accounts WHERE id = $1 FOR UPDATE;
-- application computes the new value
UPDATE accounts SET points = $2 WHERE id = $1;
COMMIT;
A second transaction that tries SELECT ... FOR UPDATE on the same row waits at that line until the first commits, then reads the new value (at Repeatable Read or Serializable it fails with a serialization error instead). This is pessimistic locking: you assume a conflict and block it up front.
There is also an optimistic version. Give the row a version column, read it along with the data, and make the write conditional on it:
UPDATE accounts SET points = $1, version = version + 1
WHERE id = $2 AND version = $3;
If another write got there first, the version no longer matches, zero rows change, and your code reads again and retries. No lock is held while the user thinks, which suits cases where conflicts are rare and the gap between read and write is long, such as a user editing a form for a minute. The conditional UPDATE can still wait briefly if another transaction holds the row at that moment. The check only works if every writer of that row bumps version, including background jobs; one that skips it can overwrite a change without failing anyone's version check.
All or nothing
Transactions do a second job, separate from concurrency. Consider an order endpoint that inserts an order, then for each line item decrements stock and inserts the item. If the process crashes halfway through, after the order row is written, it leaves partial data behind: an order with no items. A transaction makes the whole group atomic: either every statement's effect becomes visible, or none of them does.
Here is the pattern in Node with the pg library:
const client = await pool.connect();
try {
  await client.query("BEGIN");
  const { rows } = await client.query(
    "INSERT INTO orders (customer_id) VALUES ($1) RETURNING id", [customerId]);
  for (const item of items) {
    const reserved = await client.query(
      "UPDATE products SET stock = stock - $2 WHERE sku = $1 AND stock >= $2",
      [item.sku, item.qty]);
    if (reserved.rowCount === 0) throw new Error(`cannot reserve ${item.sku}`);
    await client.query(
      "INSERT INTO line_items (order_id, sku, qty) VALUES ($1, $2, $3)",
      [rows[0].id, item.sku, item.qty]);
  }
  await client.query("COMMIT");
} catch (err) {
  await client.query("ROLLBACK");
  throw err;
} finally {
  client.release();
}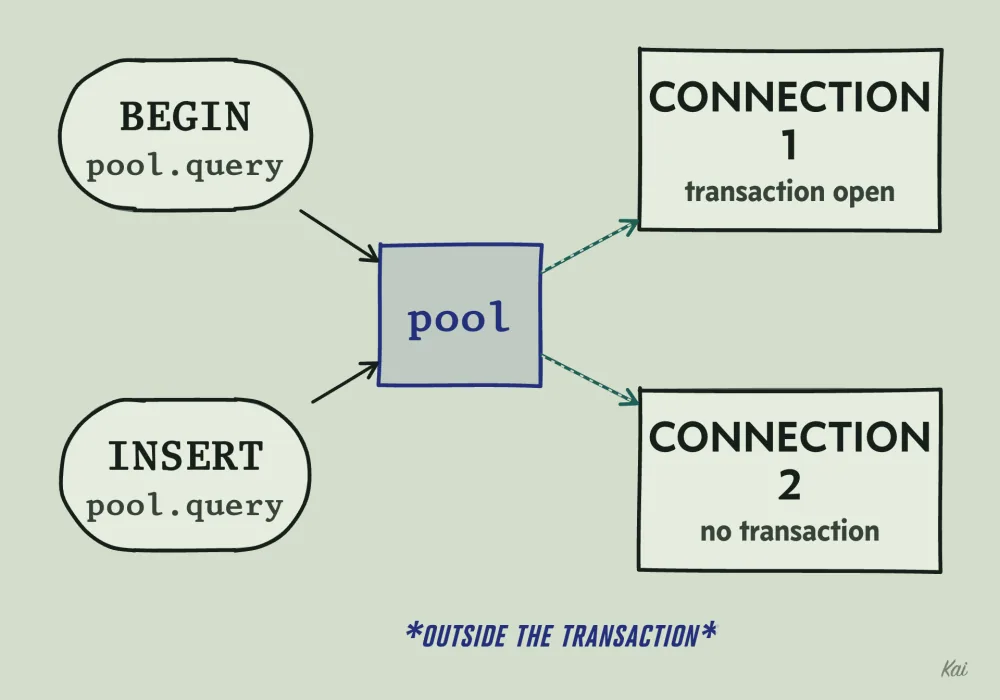
pool.query call can get its own connection, so BEGIN opens a transaction on one while the INSERT runs on another.The detail agents get wrong is pool.connect(). A transaction belongs to one connection. If the code calls pool.query("BEGIN") and then pool.query("INSERT ..."), the pool may hand each call a different connection, and the inserts run outside the transaction entirely. The code looks transactional and has no protection. With the real transaction, running out of stock on the third item throws, and the rollback undoes the order row and the first two decrements.
A transaction also covers only what happens inside the database. If the endpoint sends a confirmation email or calls a payment API in the middle, a rollback does not unsend the email. Put those side effects after the commit. A crash between the commit and the send then loses the email, so when delivery must be reliable, record the pending work in a table inside the transaction (an outbox) and have a separate worker send it, retrying until it succeeds.
Isolation: what concurrent transactions can see
Wrapping the four-line endpoint in BEGIN and COMMIT does not by itself fix the lost update. Whether it helps depends on the isolation level, which is the database's rule for how much one transaction can see of others running at the same time.
Isolation levels are defined by which anomalies they allow. An anomaly is a result that could not happen if the transactions had run one after another. PostgreSQL's behavior at each level looks like this:
| Anomaly | Read Committed | Repeatable Read | Serializable |
|---|---|---|---|
| Dirty read (seeing uncommitted data) | prevented | prevented | prevented |
| Non-repeatable read (same row, two reads, two answers) | allowed | prevented | prevented |
| Lost update (read, compute, write back) | allowed | prevented | prevented |
| Phantom (same query, new rows appear) | allowed | prevented | prevented |
| Write skew (two checks pass, combined writes break a rule) | allowed | allowed | prevented |
PostgreSQL defaults to Read Committed. MySQL's InnoDB defaults to Repeatable Read, and its Repeatable Read does not behave like PostgreSQL's, so the table above is only for PostgreSQL. Always check the documentation for the database you are actually using.
Under PostgreSQL's Repeatable Read, the lost update is prevented by an error: when B tries to update a row that A changed and committed after B's snapshot was taken, B fails with a serialization error. The snapshot is taken at a transaction's first query, not at BEGIN, so a transaction that has only said BEGIN has not yet fixed what it can see. The error is the database protecting you, and it puts a duty on you. Code running at Repeatable Read or Serializable has to catch that error and retry the whole transaction. An agent that raises the isolation level without adding a retry loop has turned silent data loss into user-facing errors under load.
Double-booking and write skew
Write skew is how a check inside a transaction can still be wrong by the time the transaction commits. A meeting room booking endpoint does this inside a transaction:
BEGIN;
SELECT count(*) FROM bookings
WHERE room_id = 5 AND starts_at < '11:00' AND ends_at > '10:00';
-- if count is 0:
INSERT INTO bookings (room_id, starts_at, ends_at) VALUES (5, '10:00', '11:00');
COMMIT;
(Times are shortened for reading; real columns would be full timestamps.)
Two people book room 5 for 10:00 at the same moment. At Read Committed or Repeatable Read, both transactions run the count and see zero, because neither has inserted yet. Both insert and both commit, so the room is double-booked.
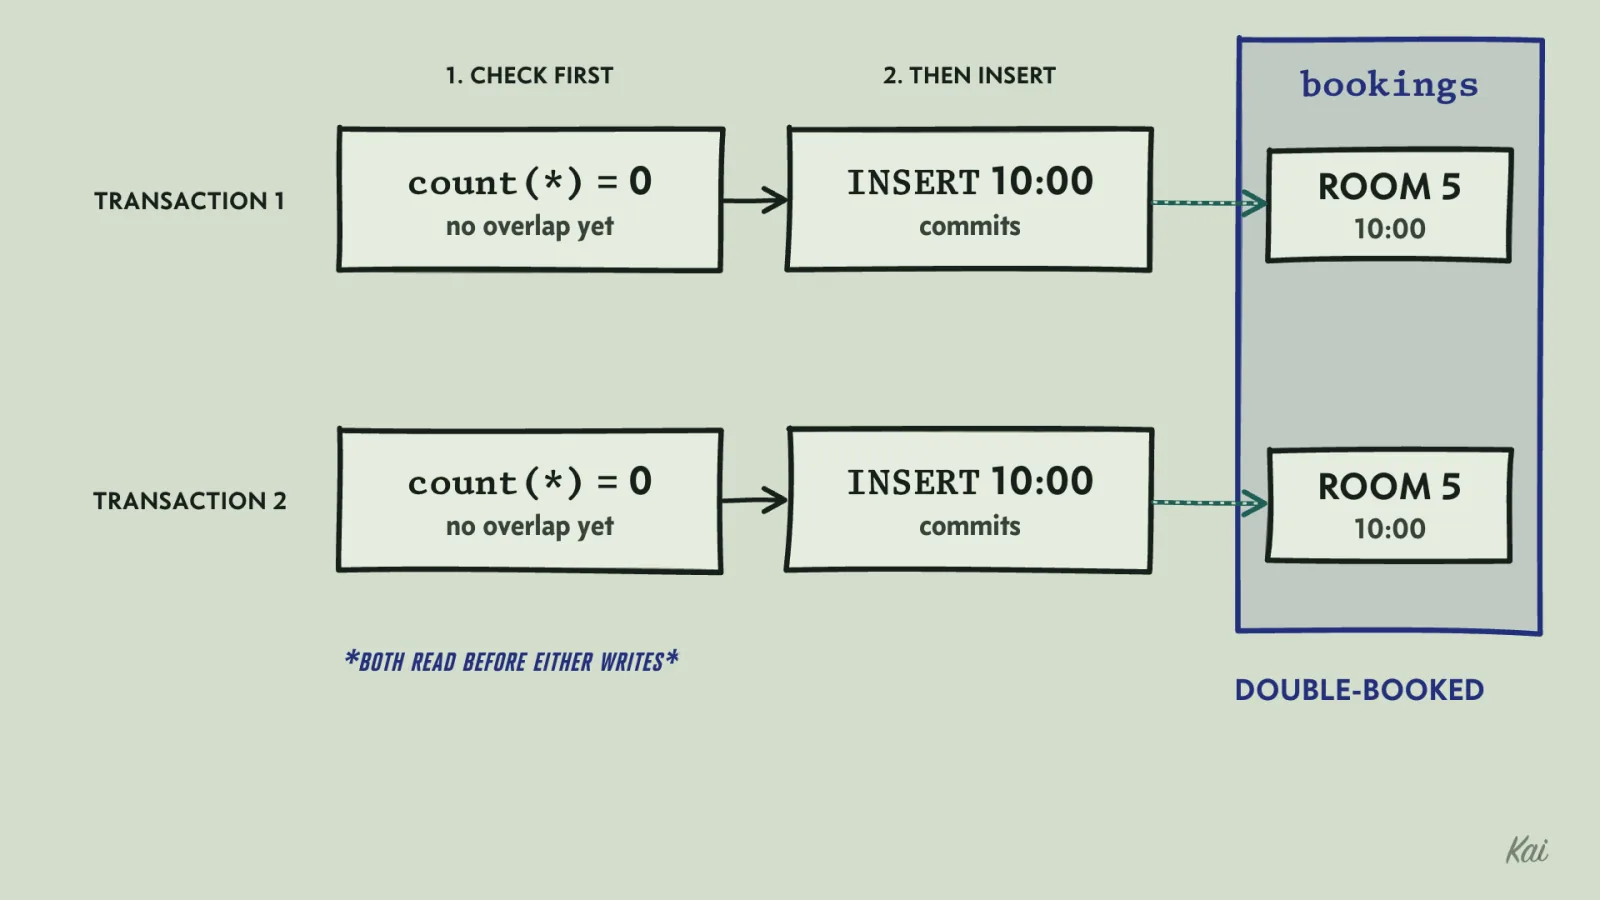
No row was written twice, so there is no lost update for Repeatable Read to catch. Each transaction made a decision based on a check, and the other transaction's write made that check false.
Serializable isolation catches this in PostgreSQL by aborting one of the two with a serialization failure.
Two other fixes work at the default level. One is a constraint, so the rule lives in the database: a unique constraint on (room_id, slot) if bookings use fixed slots, or a PostgreSQL exclusion constraint (with the btree_gist extension) that forbids overlapping time ranges for the same room. The other is to lock something both transactions must touch, such as SELECT ... FROM rooms WHERE id = 5 FOR UPDATE before the check, so the second booking waits for the first.
When an agent says "this is safe because it is in a transaction", find the check and the write, and ask what a second copy of the same transaction would see if it ran its check before the first one committed.
Replicas and reading your own writes
Many production databases have one primary that takes writes and one or more replicas that copy the primary's changes and serve reads. The copy is not instant. The primary streams its log of changes and each replica applies them a little later.
That delay is replica lag. It varies: often milliseconds, but seconds or more when a replica is under heavy load or a large write is being applied.
Now picture a user who edits their display name. The write goes to the primary. The page redirects, and the next request reads the profile from a replica that has not applied the change yet. The user sees their old name and edits it again.
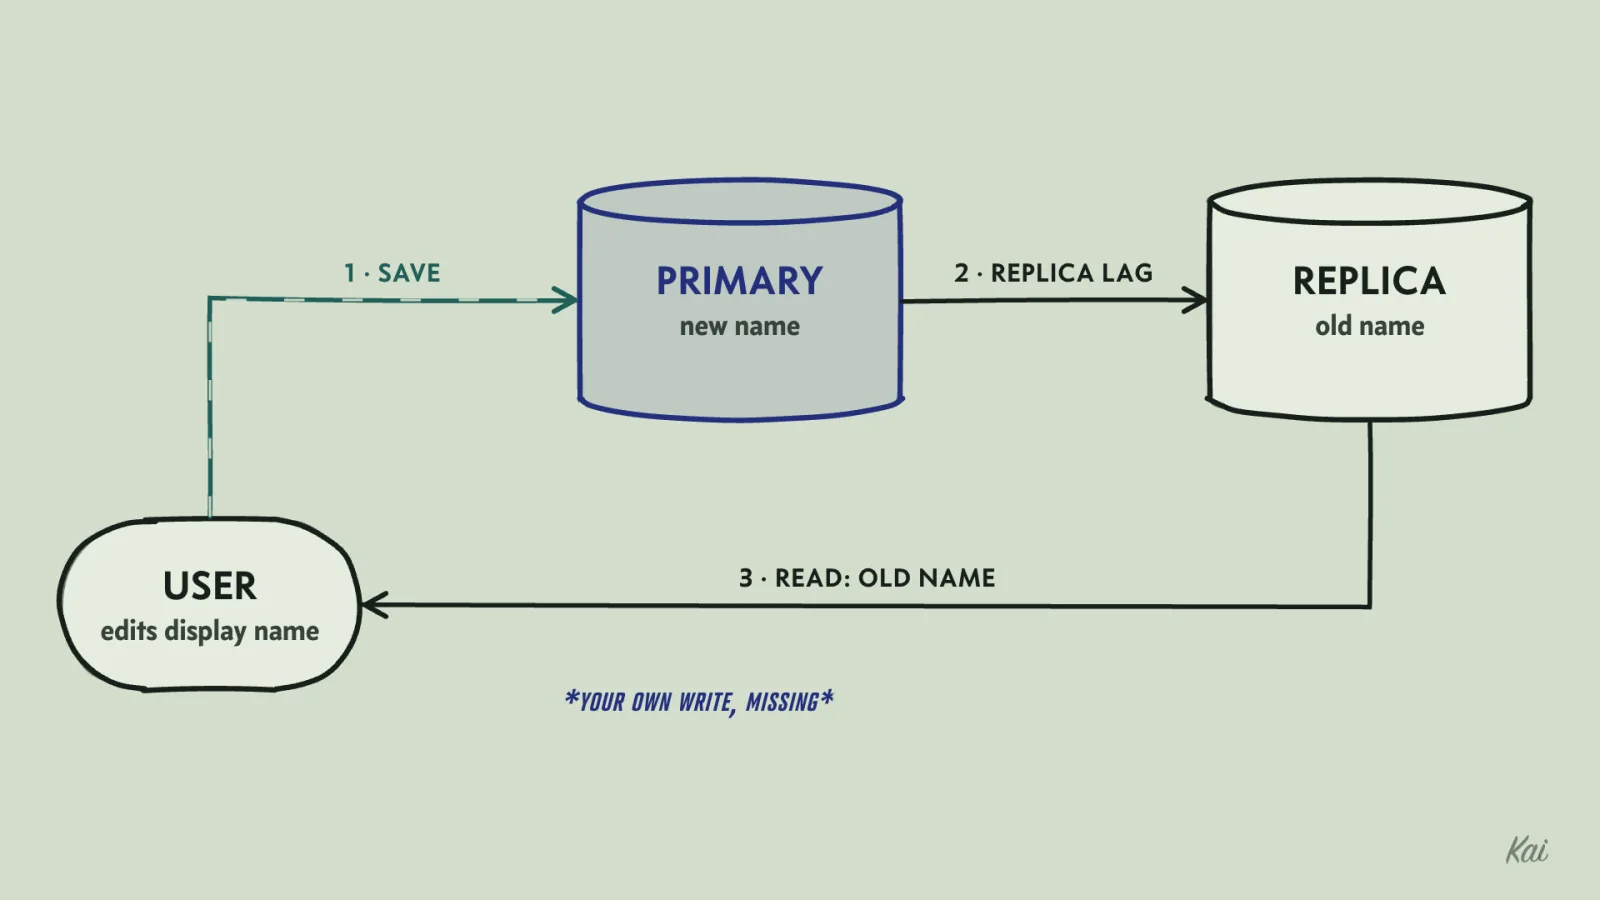
The guarantee they wanted is called read-your-writes consistency: after you write something, your own later reads reflect it. Other users may see it a moment later without harm. A system that only promises the replicas will catch up eventually, if writes stop, is called eventually consistent, and it does not give you this.
A much stronger model, linearizability, says every operation appears to take effect at one instant between its start and its finish, in real-time order, as though there were one copy of the data. Sending every read to the primary removes replica lag, which is one obstacle, but the guarantee also depends on ordering across the whole system, including what happens at failover. Replicas trade some of that away in exchange for spreading the read load.
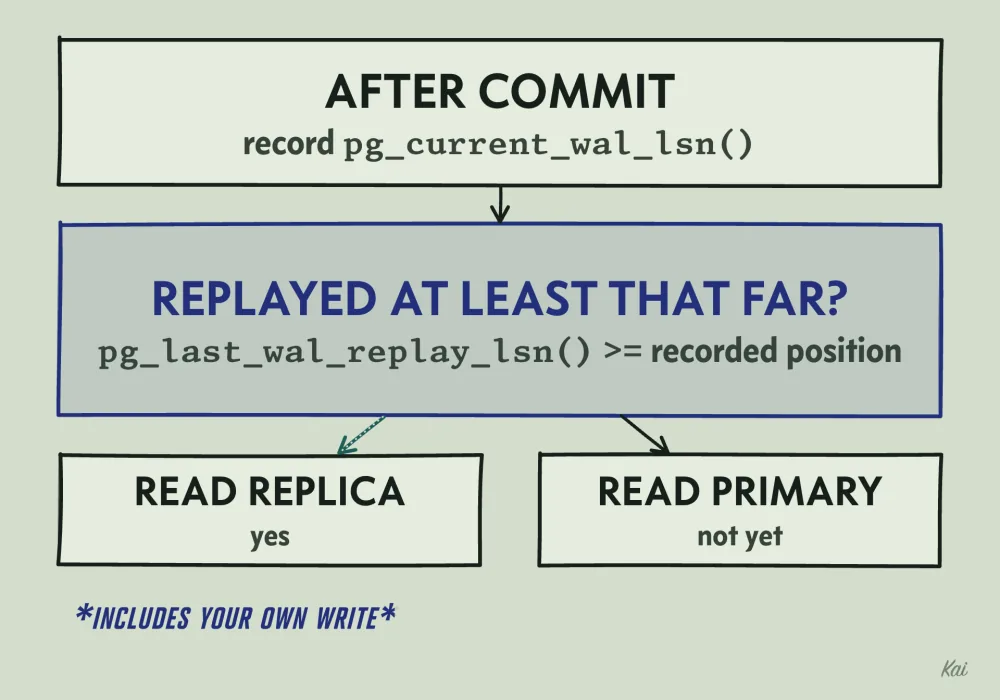
There are two common ways to provide read-your-writes on top of replicas. The simple one is to route a user's reads to the primary for a short window after they write, for example by storing the time of their last write in their session and sending their reads to the primary for the next few seconds. That cuts stale reads but guarantees nothing, because lag can outlast any window you pick. The precise one is to record the primary's log position after the write commits (in PostgreSQL, pg_current_wal_lsn()), and before reading from a replica, check that the replica has replayed at least that far (pg_last_wal_replay_lsn()), falling back to the primary if it has not.
Here are the three routes on a fake clock, with a replica that applies each change 50 ms after the primary and a 30 ms window for the session rule. The user saves a new name and reads it back 40 ms later:
let now = 0;                       // fake clock, in milliseconds
const LAG = 50;                    // this replica is 50 ms behind
const primary = new Map([["name", "Ana"]]);
const replica = new Map(primary);
const log: { key: string; value: string; at: number }[] = [];
let replayed = 0;                  // how many log entries the replica has applied

function advance(ms: number) {
  now += ms;
  while (replayed < log.length && log[replayed].at + LAG <= now) {
    const change = log[replayed++];
    replica.set(change.key, change.value);
  }
}

function write(key: string, value: string) {
  primary.set(key, value);
  log.push({ key, value, at: now });
  return { position: log.length, at: now };  // what the session remembers
}

const fromReplica = (key: string) => replica.get(key);
const withWindow = (key: string, w: { at: number }) =>
  now - w.at < 30 ? primary.get(key) : replica.get(key);
const withPosition = (key: string, w: { position: number }) =>
  replayed >= w.position ? replica.get(key) : primary.get(key);

const saved = write("name", "Ana Lima");
advance(40);
console.log("replica only:  ", fromReplica("name"));
console.log("30 ms window:  ", withWindow("name", saved));
console.log("log position:  ", withPosition("name", saved));
Output
The window closed at 30 ms and the replica caught up at 50 ms, so for those 20 ms the session rule served the old name. The position check compared the replica's progress with the write itself and read the primary instead.
For any code that reads a value and then writes based on it, find the moment it learned the fact and the moment it acted on it. If another request can change that fact in between, you need an atomic statement, a lock, a version check, a constraint or a serializable transaction that closes the gap.