
Questions You Can Answer From Outside
A customer writes in: "Checkout failed at about two o'clock, and then I saw the charge on my card." You open the checkout service's logs and find this, written by code an agent added last month:
2026-09-30T14:02:08Z INFO checkout {"email":"dana@example.com","cardNumber":"4111111111111111","cvc":"123","items":[...]}
2026-09-30T14:02:11Z ERROR payment failedThe first line contains a full card number, which now sits in every system that stores or forwards these logs. The second line says something failed and nothing else: which order, which request, how long it waited, what the payment service said. You cannot tell whether the error line belongs to this customer's request, and you cannot tell whether they were really charged.
A running service is a closed box. Once it is deployed, everything you will ever know about what it did comes from what it wrote down while doing it. Observability is the practice of making it write down the right things, so that when a question comes up that you did not plan for, the answer is already in the data.
Three kinds of record
There are three shapes of data a service can emit, and each answers a different kind of question.
An event is a record of one thing that happened: one request, one job run, one failed login. It can carry as many details as you like, because you write it once and read it rarely. Logs are events.
A metric is a number summarised over time: requests per second, errors per minute, the 99th percentile of latency. A metric throws away the details of individual events and keeps a running count, which makes it cheap to store for months and fast to graph and alert on.
A trace is a set of linked events describing one request as it passes through several services. Each step is a span with a start time, a duration and a pointer to the span that called it. Put together, the spans show where the time went and which hop failed.
The mistakes in this subsection come from putting the wrong data in the wrong shape: details that belong in events stuffed into metrics, or events written with too little detail to be useful.
Logs as records
A log line written as a sentence, like payment failed for order 99107 after 3004ms, can be read by a person and searched only with fragile text matching. A log line written as a record with named fields can be filtered, grouped and counted: all errors for order_id=ord_99107, all requests where duration_ms > 2000, the error rate per route. That is what structured logging means. The format is usually JSON, one object per line.
The most useful pattern is one wide event per unit of work. Instead of scattering ten small lines through a request handler, collect fields as the request proceeds and write one line at the end with everything: who, what, how long, what happened, and the error if there was one.
import { randomUUID } from "node:crypto";

type Fields = Record<string, string | number | boolean | null>;

function log(level: "info" | "error", event: string, fields: Fields): void {
  console.log(JSON.stringify({ ts: new Date().toISOString(), level, event, ...fields }));
}

export async function handleCheckout(req: Request): Promise<Response> {
  const requestId = req.headers.get("x-request-id") ?? randomUUID();
  const started = performance.now();
  const fields: Fields = { request_id: requestId, route: "POST /checkout" };

  try {
    let body: any;
    try {
      body = await req.json();
    } catch {
      fields.status = 400;
      fields.error = "malformed JSON";
      return new Response("bad request", { status: 400 });
    }
    if (
      typeof body?.orderId !== "string" ||
      typeof body.userId !== "string" ||
      !Number.isInteger(body.amountCents) ||
      !Array.isArray(body.items)
    ) {
      fields.status = 400;
      fields.error = "invalid request body";
      return new Response("bad request", { status: 400 });
    }

    // Allowlist: name each field that goes in the log. The card token and email never do.
    Object.assign(fields, {
      user_id: body.userId,
      order_id: body.orderId,
      amount_cents: body.amountCents,
      item_count: body.items.length,
    });

    const pay = await fetch(process.env.PAYMENTS_URL + "/charge", {
      method: "POST",
      headers: { "content-type": "application/json", "x-request-id": requestId },
      body: JSON.stringify({ orderId: body.orderId, amountCents: body.amountCents, cardToken: body.cardToken }),
      signal: AbortSignal.timeout(3000),
    });
    fields.payments_status = pay.status;
    await pay.body?.cancel(); // only the status is needed; release the connection
    if (!pay.ok) throw new Error(`payments returned ${pay.status}`);
    fields.status = 200;
    return new Response("ok");
  } catch (err) {
    fields.status = 502;
    fields.error = err instanceof Error ? `${err.name}: ${err.message}` : String(err);
    return new Response("payment failed", { status: 502 });
  } finally {
    fields.duration_ms = Math.round(performance.now() - started);
    log(Number(fields.status) >= 500 ? "error" : "info", "checkout", fields);
  }
}
The request ID and the base fields are set before anything is parsed, the parsing happens inside the try, and the log call sits in finally. Every way out of the function, including a malformed body that is rejected with a 400, writes exactly one event. A handler that parsed the body first would log nothing for a request that failed to parse, and those are the requests you most need to see.
The allowlist comes next. The code names each field that goes into the log, so a new field added to the request body next month stays out until someone decides it belongs. The opposite approach, logging the body and redacting known secret fields, fails the first time someone adds a field the redaction list does not know about. Run both approaches on today's request body and on next month's, after a saved-card feature adds a token to it:
type Body = Record<string, unknown>;

// Redaction: log everything except the fields someone remembered to list.
const SECRET_FIELDS = ["password", "cardNumber", "cvc"];
function redactingLogLine(body: Body): string {
  const copy: Body = { ...body };
  for (const key of SECRET_FIELDS) if (key in copy) copy[key] = "[redacted]";
  return JSON.stringify(copy);
}

// Allowlist: log only the fields someone decided belong in the log.
function allowlistLogLine(body: Body): string {
  return JSON.stringify({ order_id: body.orderId, amount_cents: body.amountCents });
}

const today: Body = { orderId: "ord_99107", amountCents: 4599, cardNumber: "4111111111111111", cvc: "123" };
const nextMonth: Body = { ...today, savedCardToken: "tok_8f2a91c4" };

console.log("today, redaction:     ", redactingLogLine(today));
console.log("today, allowlist:     ", allowlistLogLine(today));
console.log("next month, redaction:", redactingLogLine(nextMonth));
console.log("next month, allowlist:", allowlistLogLine(nextMonth));
Output
Both lines are safe today. Next month the redacting logger writes the saved-card token in full, although nobody touched the logging code. The allowlist line has not changed.
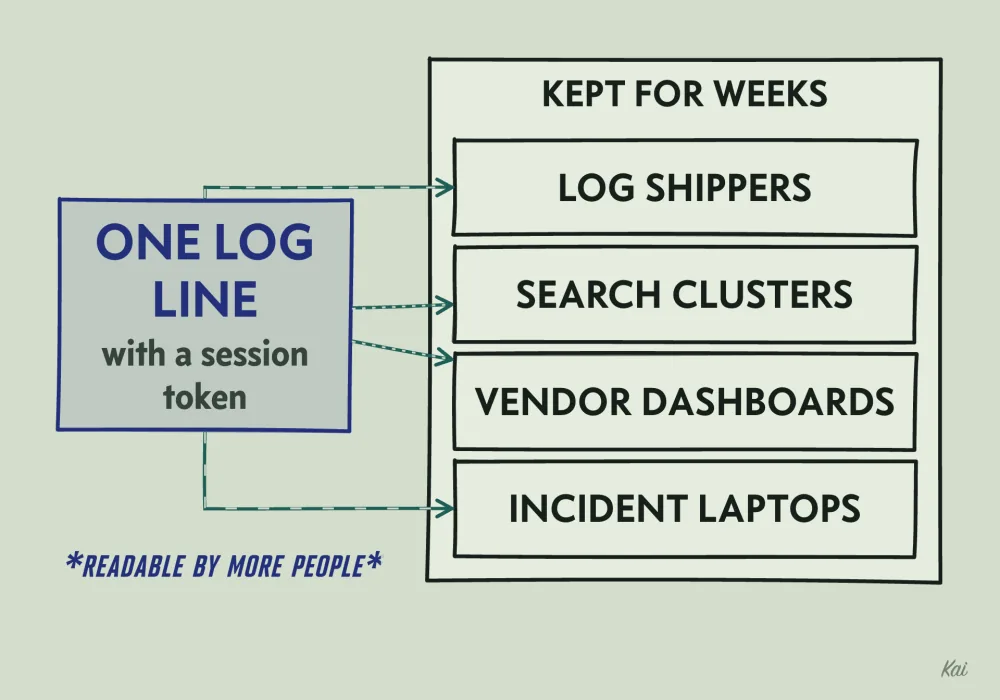
Logs are copied to more places than your database: log shippers, search clusters, vendor dashboards, laptops during an incident. They are kept for weeks and readable by more people. A password or session token in a log is a credential anyone with log access can use. When you review logging code, look for any line that passes a whole request, response, headers object or user record to the logger.
The error line needs context as well. The failure line carries the request ID, the order, the amount, the payment service's status if it answered, the error's type and message, and how long the request took. The test for an error log is whether the line identifies the request and the failing operation, and points to the data needed to reproduce the failure safely: the request ID finds the request in other systems, and the order ID finds the stored order you can replay against a test environment. The line should not be a recipe for re-sending the request, because that could charge the card a second time. ERROR payment failed fails that test. So does a line that includes the message but not the inputs, because "timeout" alone does not tell you which order or which dependency.
Following one request across two services
Look at the x-request-id header in the code above. Checkout takes the ID from the incoming request if a caller already set one, makes one otherwise, logs it, and sends it on to the payment service, which logs it too. That shared value is a correlation ID, and it is what turns two separate piles of logs into one story.
Back to the customer. You search checkout's logs for their user_id around 14:02 and find one line:
{"ts":"2026-09-30T14:02:11.482Z","level":"error","event":"checkout","request_id":"7f3c9a1e-5d2b-4c1a-9e7f-2b8d6a4c0f13","route":"POST /checkout","user_id":"u_18422","order_id":"ord_99107","amount_cents":4599,"item_count":2,"status":502,"error":"TimeoutError: The operation was aborted due to timeout","duration_ms":3004}Then you search the payment service's logs for that request_id:
{"ts":"2026-09-30T14:02:11.611Z","level":"info","event":"charge","request_id":"7f3c9a1e-5d2b-4c1a-9e7f-2b8d6a4c0f13","order_id":"ord_99107","status":200,"processor_ms":2987,"duration_ms":3120}The two lines together explain the complaint. The payment service charged the card successfully, but it took 3.12 seconds, mostly waiting on the card processor. Checkout gave up at 3 seconds and told the customer it failed. Neither log alone shows that. The fix is a design question (a longer timeout, or checking the charge status before reporting failure), and you know which question to ask because the IDs lined up.
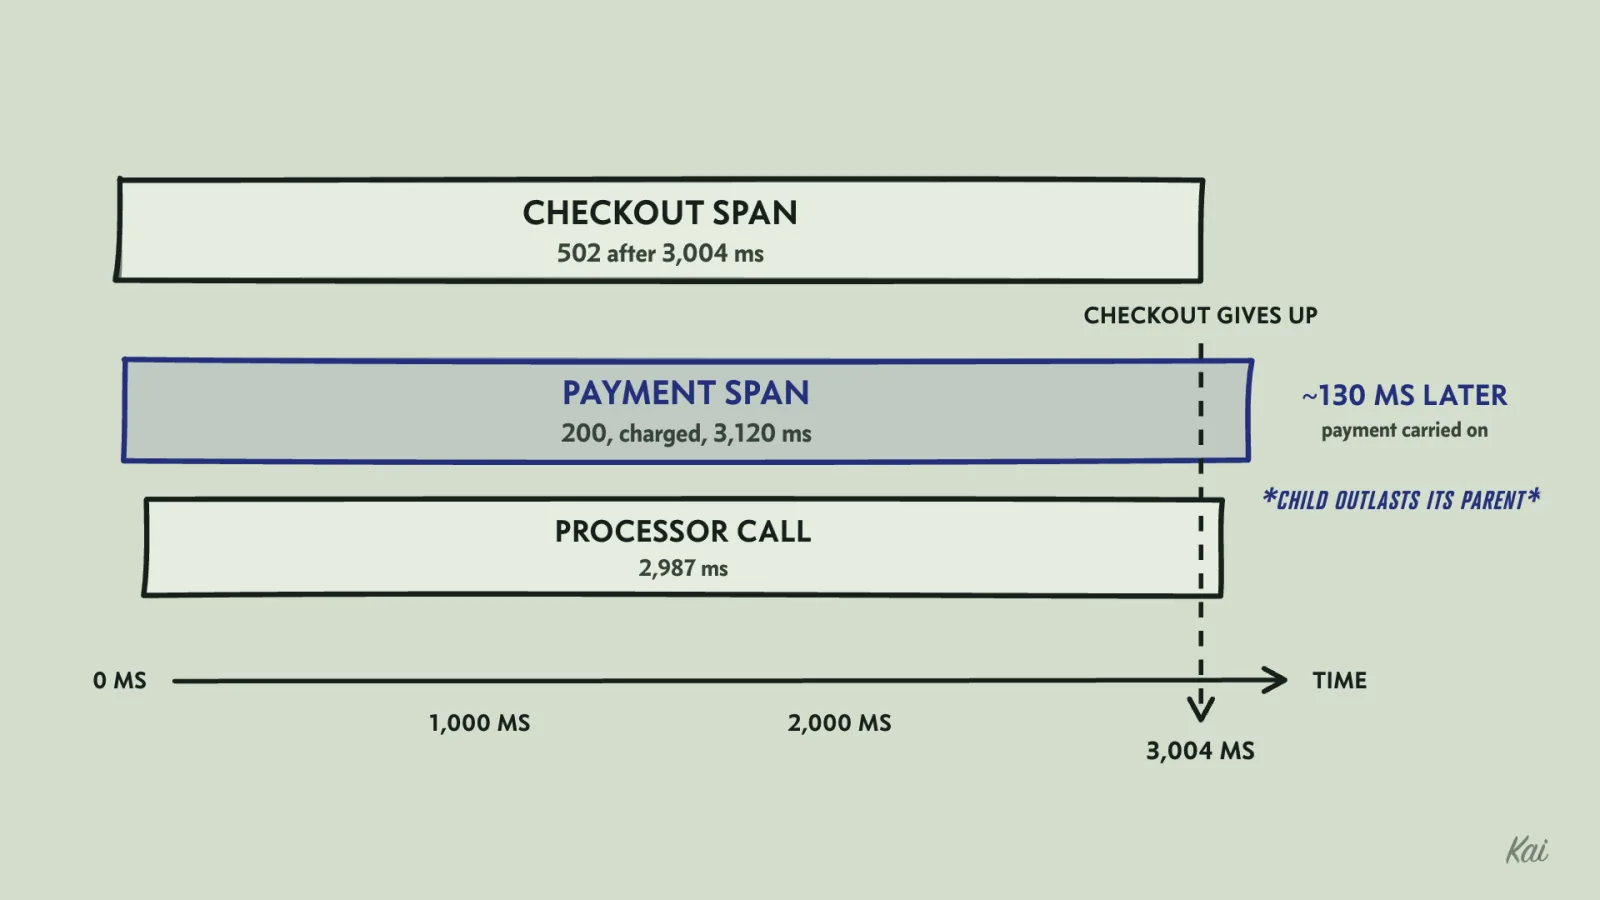
Distributed tracing does the same job with more structure. Each request gets a trace ID, each unit of work inside it gets a span ID, and each span records its parent. The IDs travel between services in a header; the W3C Trace Context standard names it traceparent and packs a version, the 32-hex-digit trace ID, the 16-hex-digit parent span ID and some flags into one value. A tracing backend then draws the request as a timeline, and the payment service's span would show as a bar about 3.1 seconds long, most of it the 2,987 ms processor call. That bar starts inside the checkout span but ends about 130 ms after the checkout span does, since checkout stopped waiting at 3 seconds and payment carried on. A child span can outlast its parent, and here that is the evidence that checkout timed out while the charge went through. OpenTelemetry is the common open-source way to produce these spans and to put the trace ID into your log lines, so logs and traces can be joined.
Metrics and the cost of a label
A metric is stored as a set of time series. A series is one metric name plus one exact combination of label values, like http_requests_total{route="POST /checkout", status="502"}. Every distinct combination is its own series, stored and indexed separately, and hosted metrics services commonly price by how many series you have.
So the number of series is the product of the number of values each label can take. With 20 routes, 8 status codes and 3 regions, a request counter has at most 480 series. Add a user_id label and the ceiling becomes 480 times the number of users. With 2 million active users that is up to 960 million series for one counter, and every new user adds more. Monitoring systems slow down or run out of memory long before that, and the bill grows with every sign-up.
This simulation sends 200,000 requests from up to 50,000 users and counts the series a counter creates with and without a user_id label:
const routes = ["GET /cart", "POST /checkout", "GET /orders/:id"];
const statuses = ["200", "400", "502"];

// A small seeded random generator, so every run prints the same numbers.
let seed = 42;
function random(n: number): number {
  seed ^= seed << 13; seed ^= seed >>> 17; seed ^= seed << 5;
  return (seed >>> 0) % n;
}

const withoutUser = new Set<string>();
const withUser = new Set<string>();

for (let i = 1; i <= 200_000; i++) {
  const route = routes[random(routes.length)];
  const status = statuses[random(statuses.length)];
  const user = "u_" + random(50_000);
  withoutUser.add(`route=${route},status=${status}`);
  withUser.add(`route=${route},status=${status},user_id=${user}`);
  if (i === 1_000 || i === 20_000 || i === 200_000) {
    console.log(`after ${i} requests: ${withoutUser.size} series without user_id, ${withUser.size} with it`);
  }
}
Output
Without the label the count stops at 9, one per route and status pair. With it, most requests create a new series, and the count keeps climbing toward 9 × 50,000 = 450,000. In production the user count itself keeps growing, so there is no ceiling at all.
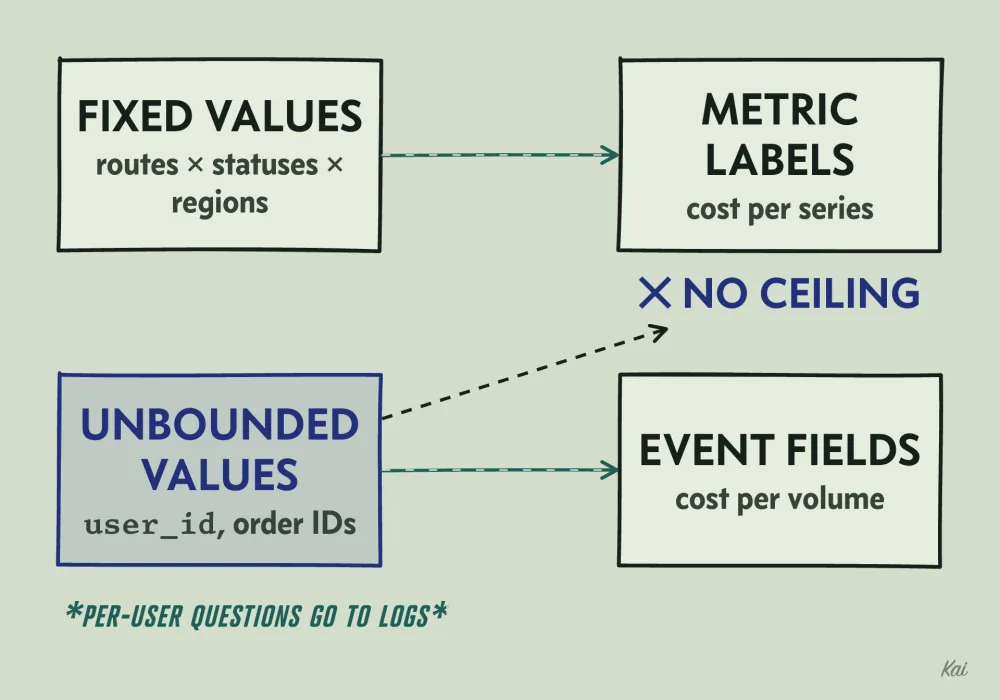
Labels must have a small, fixed set of possible values. User IDs, email addresses, order IDs, request IDs and raw URLs with IDs in the path all have unbounded values, and they belong in events, where each record carries its own details without creating a new series. Storing and indexing events still costs money, so what you pay for is volume, which grows with traffic and not with the number of distinct users. If you need per-user questions answered, query the logs.
For choosing which metrics a service should have, two short lists cover most cases. For anything that handles requests, measure rate, errors and duration (the RED method). For resources like CPUs, disks and connection pools, measure utilization, saturation and errors (the USE method). Rate comes from a counter, a number that only goes up, read as its increase per second. The number of open connections in a pool is a gauge, a value that goes up and down. Duration is a histogram, which counts requests into latency buckets so you can compute percentiles later.
Defining "working" from the user's side
A service level indicator (SLI) is a measurement of what users experience, written as a ratio: good events divided by valid events. For checkout, a reasonable SLI is the fraction of checkout requests that did not return a 5xx status. A second one could be the fraction that completed within one second.
A service level objective (SLO) is the target for that ratio over a window, for example 99.9% of checkout requests succeed over 30 days. The remaining 0.1% is the error budget. At 10 checkouts per second, 30 days is 25,920,000 requests, so the budget is 25,920 failed checkouts. In time, 0.1% of 30 days is 43.2 minutes of total outage.
Alerting then becomes a question about the budget. The burn rate is how fast you are spending it relative to the pace that would use it up exactly at the end of the window. A burn rate of 1 spends the budget in 30 days. A burn rate of 14.4 sustained for one hour spends 14.4 / 720 = 2% of the whole month's budget, since 30 days is 720 hours and, at a steady 10 checkouts per second, each hour holds 1/720 of the month's requests. That is a reasonable threshold for waking someone: an hour-long error rate above 14.4 × 0.1% = 1.44%.
sum(rate(http_requests_total{route="POST /checkout", status=~"5.."}[1h]))
  /
sum(rate(http_requests_total{route="POST /checkout"}[1h]))
  > 0.0144
Practical setups pair this with a shorter window, such as five minutes, that must also be over the threshold, so the page stops soon after the problem does. The SRE Workbook chapter on alerting on SLOs works through that design.
Compare this with an alert on CPU above 80%. Suppose the payment service's credentials expire and every charge is rejected immediately. Checkout now returns 502 in a few milliseconds instead of doing real work, so its CPU goes down. The CPU alert stays quiet while every customer fails. The burn-rate alert fires within minutes, because it measures the thing users feel. High CPU with happy users is something to look at during working hours, and a failing checkout at low CPU is an outage. Page on symptoms users experience, and keep resource metrics on dashboards and in tickets.
Review observability code against a customer complaint you invent. The logs should take you from their words to the one failing request without guessing, and an alert on a user-facing SLI should have fired before they wrote in.