
The Change Is Yours Once You Approve It
On Friday afternoon your agent opens a pull request that reworks the invoice page of your billing app. It is 600 lines across eleven files. The tests pass, the description is tidy, and you want to leave. You skim the file list for a minute, click approve, and it ships.
On Saturday morning support escalates to you, because you are on call. Customers in the United States are seeing a red "Overdue" banner on invoices that are due today, along with a warning about late fees. Some have paid twice to be safe. Customers in Europe see nothing wrong.
The agent wrote the code. You are the one being paged, and by Monday someone will ask you why this was approved.
Approval makes you accountable
The service needs a named person or team for incident decisions and follow-up, and a record of who responds and what evidence supported the approval. Approving makes you accountable for that review decision. The team that owns the service remains responsible for operating the result, whoever or whatever produced the diff.
So an approval is a claim: I believe this change is correct, and here is the evidence I relied on. Try saying that about the Friday approval.
The minute it took is beside the point. A one-minute approval can be sound when every criterion the change was built against has an eval, the evals ran on the final diff, and the risky part was small enough to read. The Friday approval rested on the green checkmark and on the description the agent wrote about its own work. The checkmark covered what the tests covered, and no criterion or test said what an invoice due today should show a customer in another time zone. Nobody read the date logic either. That is approval without evidence.
A meaningful approval can name its evidence, in this order:
- The criteria the change was built against, and the evals or tests that check each one, run on the final diff.
- The parts you read line by line because no criterion reaches them or a miss would be costly, such as date handling, money, or anything touching permissions.
- Whether you ran the change yourself.
- The dependencies, configuration and database changes it added.
Criteria and evals come first because they check every later change against the same target. Reading goes where they cannot reach. If you cannot name evidence for the behavior that worries you, ask for the missing criterion and an eval that exercises it, or read that part yourself. If the evidence is still insufficient, hold approval. That costs less than this approval cost your customers.
On call for code you did not write
In 1985 Peter Naur argued that a program is really the theory in its programmers' heads: why it is shaped the way it is, what each part is for, how it would change to meet a new need. The source code is a partial record of that theory. When an agent writes the code, the theory lives nowhere unless someone builds it.
Writing the criteria and reading the risky parts are two of the ways you build it. An approval with neither leaves you on call for a program nobody understands.
So the skill that matters on Saturday morning is diagnosing a bug yourself, without asking an agent to guess.
Start from the symptom and the pattern. Only customers in the United States are reporting it, and only around the due date. A bug that depends on where the user is suggests time zones. The banner comes from a function the agent added:
export function daysUntilDue(dueDate: string, now: Date = new Date()): number {
  const due = new Date(dueDate);            // dueDate looks like "2026-02-09"
  const today = new Date(now.getFullYear(), now.getMonth(), now.getDate());
  return Math.floor((due.getTime() - today.getTime()) / 86_400_000);
}
The page shows "Overdue" when this returns a negative number. Read each line and ask what value it produces. JavaScript parses a date-only string like "2026-02-09" as midnight UTC. The today line builds midnight in the browser's local time zone.
In New York in February, midnight UTC on 9 February is 19:00 on 8 February local time. So due is five hours before today, the difference is negative, and Math.floor rounds it down to −1. The invoice is due today and the page calls it overdue. In Berlin, midnight UTC falls after local midnight, the difference is positive, and the bug hides.
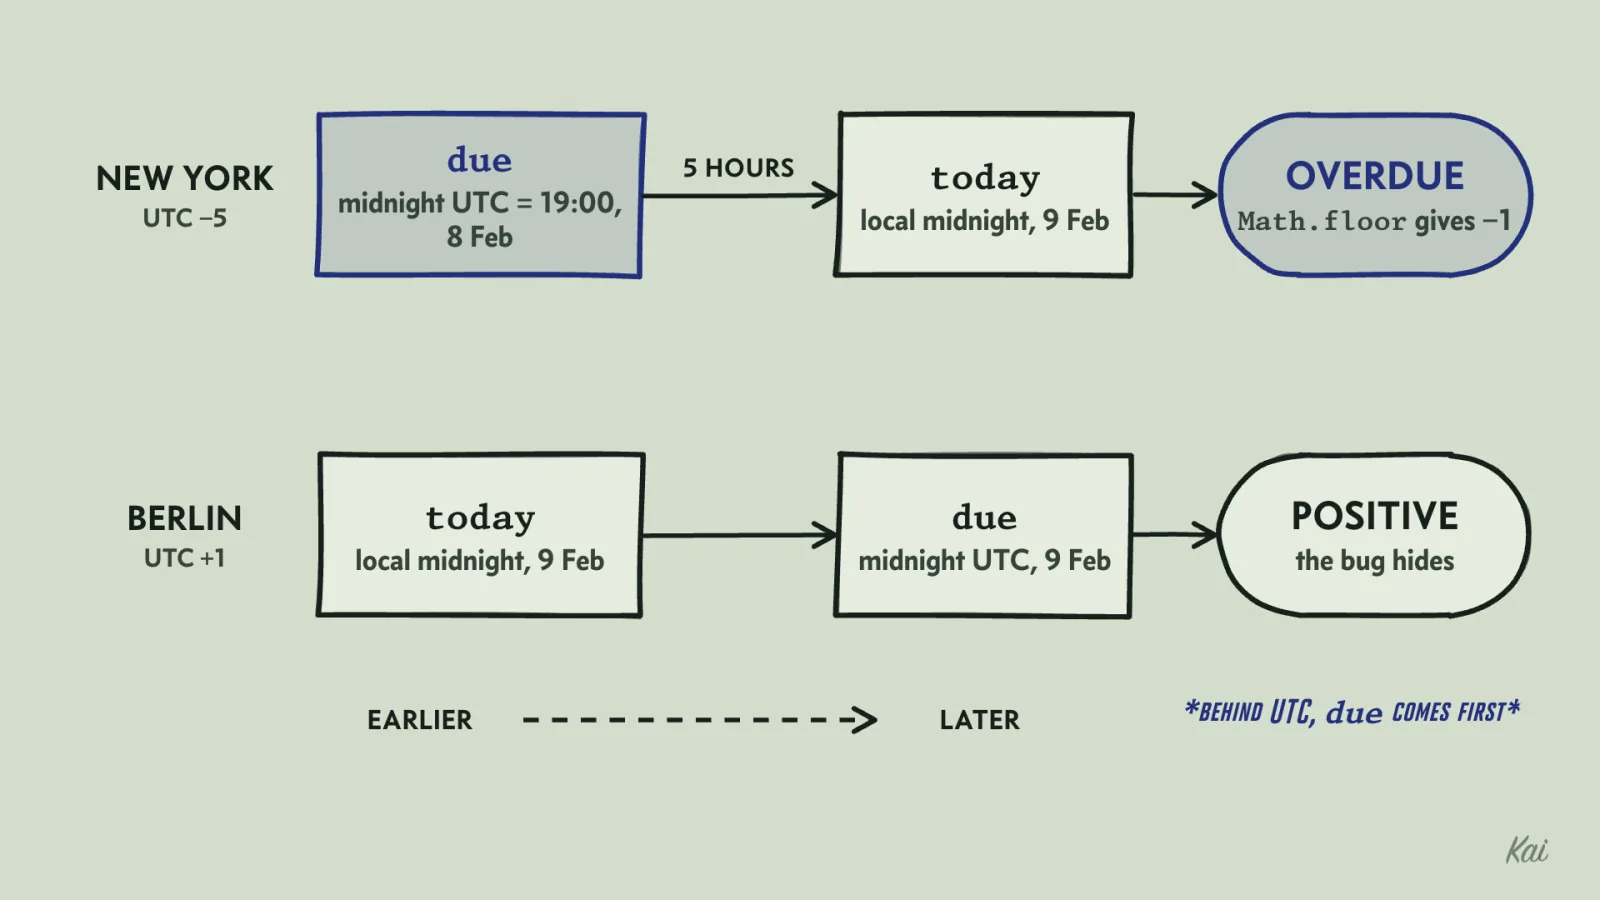
due comes before today and Math.floor turns the gap into −1. In Berlin the order flips and the bug hides.Next, reproduce it in a test before you fix anything. The test suite passed because CI runs in UTC, where the two midnights are the same. Setting the time zone for the test run exposes it:
// due.test.ts, run with: TZ=America/New_York bun test ./due.test.ts
import { expect, test } from "bun:test";
import { daysUntilDue } from "./due.ts";

test("an invoice due today is due in 0 days", () => {
  const now = new Date(2026, 1, 9, 10, 0); // 9 Feb 2026, 10:00 local time
  expect(daysUntilDue("2026-02-09", now)).toBe(0);
});
Under TZ=UTC this passes. Under TZ=America/New_York it fails with Expected: 0 and Received: -1. Now you have the bug pinned down in a form that will stay caught.
For this product an invoice is overdue by the viewer's local calendar date. The fix extracts that date from now, then represents both dates as UTC midnights so the subtraction is a whole number of days:
const DAY_MS = 86_400_000;

export function daysUntilDue(dueDate: string, now: Date = new Date()): number {
  const [y, m, d] = dueDate.split("-").map(Number);
  const due = Date.UTC(y, m - 1, d);
  const today = Date.UTC(now.getFullYear(), now.getMonth(), now.getDate());
  return (due - today) / DAY_MS;
}
Both values are now midnight UTC on a calendar date, so the difference is always a whole number of days, including across daylight-saving changes. The test passes in New York and in UTC. Add a CI job that runs the date tests under at least one time zone behind UTC and one ahead of it, so the next change to this code gets the same check.
A playground cannot change your browser's time zone, so the block below models each viewer with a fixed offset from UTC and runs both versions for an invoice due today:
const DAY_MS = 86_400_000;
const HOUR_MS = 3_600_000;

// A playground cannot change your browser's time zone, so this models one:
// a viewer whose clock is offsetHours from UTC (February, so no summer time).
// It returns the viewer's local year, month and day for an instant.
function localDate(instant: number, offsetHours: number): [number, number, number] {
  const shifted = new Date(instant + offsetHours * HOUR_MS);
  return [shifted.getUTCFullYear(), shifted.getUTCMonth(), shifted.getUTCDate()];
}

// The agent's version: the due date at midnight UTC, today at the viewer's local midnight.
function buggyDaysUntilDue(dueDate: string, now: number, offsetHours: number): number {
  const due = new Date(dueDate).getTime();
  const [y, m, d] = localDate(now, offsetHours);
  const today = Date.UTC(y, m, d) - offsetHours * HOUR_MS; // local midnight as an instant
  return Math.floor((due - today) / DAY_MS);
}

// The fix: both calendar dates as UTC midnights.
function fixedDaysUntilDue(dueDate: string, now: number, offsetHours: number): number {
  const [dy, dm, dd] = dueDate.split("-").map(Number);
  const [y, m, d] = localDate(now, offsetHours);
  return (Date.UTC(dy, dm - 1, dd) - Date.UTC(y, m, d)) / DAY_MS;
}

const viewers: [string, number][] = [["Los Angeles", -8], ["New York", -5], ["London", 0], ["Berlin", 1], ["Tokyo", 9]];
for (const [city, offset] of viewers) {
  const now = Date.UTC(2026, 1, 9, 10) - offset * HOUR_MS; // 10:00 on 9 Feb, local time
  console.log(`${city.padEnd(11)} buggy: ${buggyDaysUntilDue("2026-02-09", now, offset)}  fixed: ${fixedDaysUntilDue("2026-02-09", now, offset)}`);
}
Output
Every viewer behind UTC sees the invoice as a day overdue under the agent's version, and every viewer at or ahead of UTC sees it correctly. That split is why European customers saw nothing wrong.
A postmortem that changes something
On Monday a draft postmortem appears. Its root cause reads "incorrect date logic in code generated by the agent", and its only action item is "hotfix deployed".
That line names the function and whoever typed it. A person could have written the same function, and the next one will pass through the same gaps. The useful question is which defences were in place and why each one let the bug through. Richard Cook's "How Complex Systems Fail" makes the point that failures in complex systems have several contributing causes, and that picking one of them as the root cause is a story told after the fact.
Tests ran only in UTC, so a whole class of time-zone bugs could not fail in CI. The approval had no evidence for the date logic: no criterion covered an invoice due today in another time zone, and nobody read the code. The change went to every customer at once. A staged rollout would have limited the exposure, but nothing throws in this bug and the error rate stays flat, so noticing it also needed a check of invoice status for users in an affected time zone.
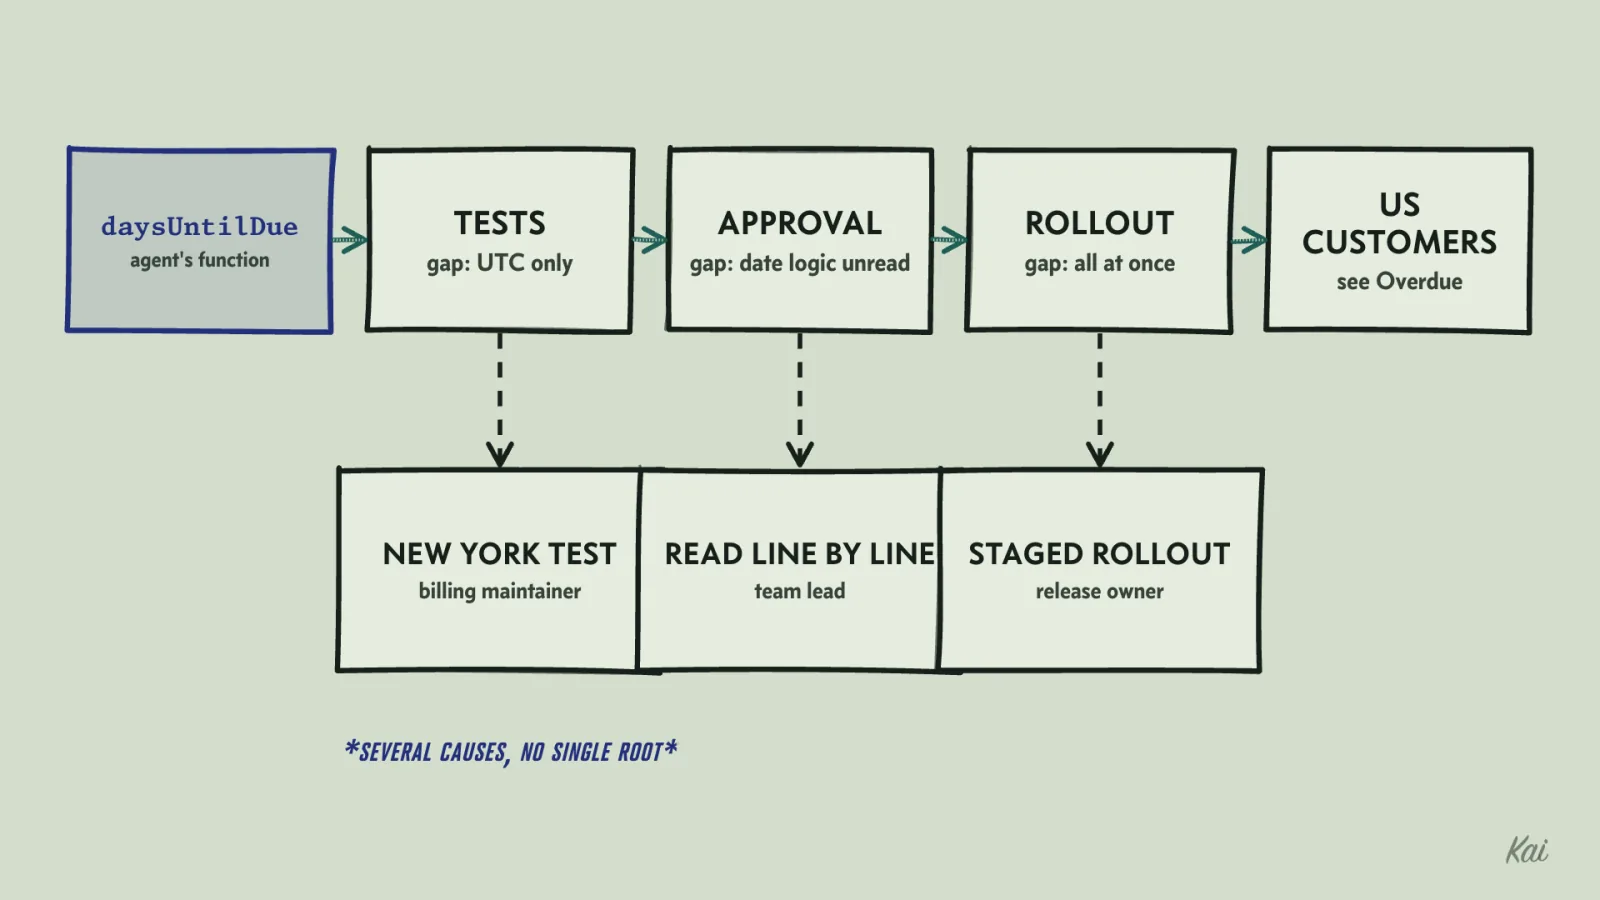
Each of those becomes a corrective action with an owner and a date. The billing maintainer adds the criterion "an invoice due today shows as due today in every time zone", checked by a New York regression test, by Friday. The team lead adopts a review rule that date and money code is read line by line. The release owner puts billing changes behind a staged rollout with that status check.
Writing "AI-generated code" as a root cause leaves the failed review and test controls unexplained, so assign an owner and a date to each corrective action instead.
Agent output as supply chain
Review an outside contribution for its source, license obligations and added dependencies. Agent output deserves the same review, for a concrete reason: models can reproduce code they were trained on, sometimes nearly word for word, and most often when that code is common in public repositories.
If a function in the agent's diff matches code from a GPL-licensed project, pause the merge and have the licensing reviewer establish its source, its license and whether permission is needed. If you distribute a combined program that incorporates GPL-covered code, GPL obligations generally apply to the combined program, including making its source available to the people who receive it. Private use and separate, independent programs need a different analysis.
AGPLv3 also requires a modified covered program that supports remote interaction to offer its corresponding source to those network users. For a proprietary product, a real match is a conflict someone has to resolve, by removing and rewriting the code, by getting permission, or by complying with the license. How the code is used and distributed in your product is a question for whoever handles licensing at your company, and you are the one who has to raise it.
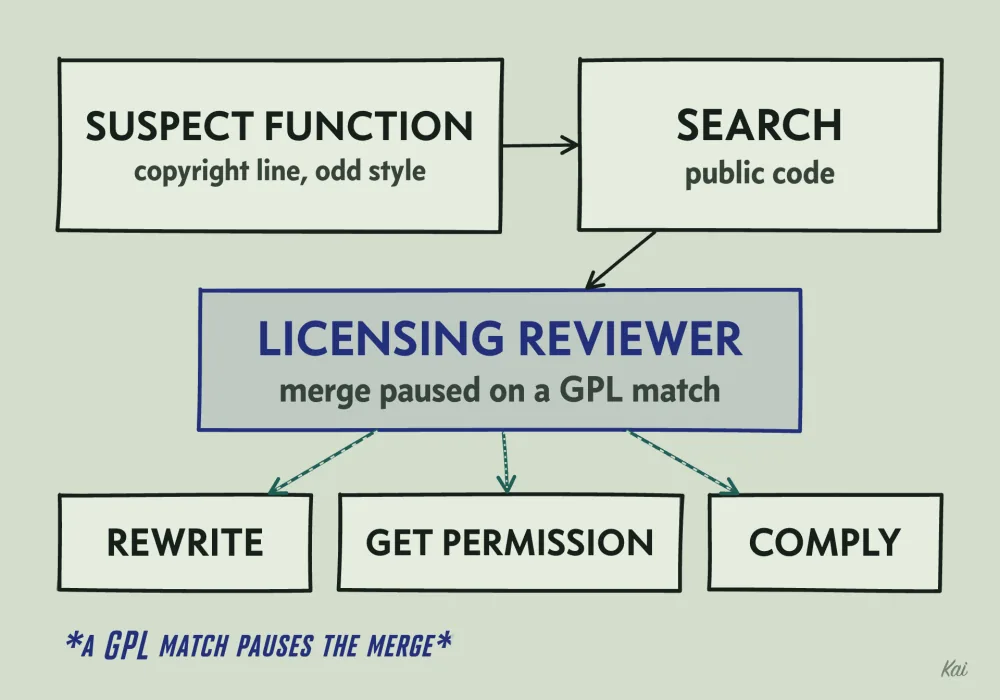
You can catch this in review. A function with unusually specific comments, a copyright line, or a coding style that does not match the rest of your project deserves a search against public code. Snippet-matching scanners exist that compare code against open-source projects, and some coding assistants can block suggestions that match public code. None of them sees everything, so the reviewer's eye still counts.
Dependencies are the other half. An agent that adds a package to fix a small problem has brought in a new maintainer, a new license, and every package that one depends on. Read the dependency diff as carefully as the code diff.
Keep a record of where each change came from. Record the agent and model in a commit trailer, and list the verified licenses of new dependencies in the pull request. When a license question or a bad model version turns up months later, that record tells you which commits to look at.
Knowing when to take the controls
In 1983 Lisanne Bainbridge described what she called the ironies of automation. Designers automate the tasks that are easy to automate and leave the operator the rest, which are the rare, hard cases. At the same time, the operator no longer practices the everyday work that would keep their skills ready for those hard cases. In aviation it shows up as pilots losing hand-flying skill, and in 2013 the US Federal Aviation Administration urged airlines to give pilots more chances to fly manually.
The same thing happens when agents write most of your code. You spend your days reviewing and prompting, and then an incident arrives that the agent cannot solve, and you are out of practice. Regularly fix bugs and write features without assistance. Read the code those changes depend on.
There are also clear signals that it is time to stop directing and do the work yourself:
- The agent has tried to fix the same failure three times and it still fails.
- You cannot explain why its last attempt did not work.
- The problem is new to this codebase, with no similar code for the agent to follow.
- The code controls security or money.
If repeated patches fail and the agent cannot say what each result establishes, stop the loop. Keep the useful tests and observations, remove the speculative changes, and reproduce the failure yourself the way you did with the invoice bug.
Recovery before approval
Recovery is part of what you approve. Before approving, record which deployment you would restore, and check whether reverting or disabling the feature is safe with the data as it is now. If the change ran a migration that a revert cannot undo, name the forward fix instead. A forward fix restores service without rolling anything back.
Put the recovery steps and the team on call for the service in the pull request description, next to the new dependencies and their licenses.