
Every Value Is Stored in Some Encoding
An agent writes the code that turns a price typed into a form into cents for your payment provider.
const cents = Math.floor(parseFloat(input) * 100);It looks obviously right. For "4.35" it produces 434. A customer is charged a cent less than the price on the page, the order total no longer matches the invoice, and the reconciliation job flags it a month later.
Inside the machine everything is bits, and every number, string and timestamp is an encoding: a rule for turning a value into bits and back. Each rule has cases where the value that comes back differs from the one that went in. Code written without knowing the rule works on the examples someone thought to test and fails quietly on the rest. To catch these bugs you need to know each encoding well enough to predict where it bends.
Integers have edges
A bit is 0 or 1, and a byte is 8 bits. With n bits you can represent 2^n different values. An unsigned 8-bit integer covers 0 to 255. Signed integers use two's complement, which gives half the patterns to negative numbers, so a signed 32-bit integer runs from −2,147,483,648 to 2,147,483,647.
Go past the top and the value wraps. In Java, adding 1 to an int holding 2,147,483,647 gives −2,147,483,648, with no error. In C, signed overflow is undefined behavior, which is worse, because the compiler may assume it never happens. Any counter, ID or byte total that could someday exceed about 2.1 billion needs a 64-bit type, whose limit is around 9.2 × 10^18.
Floating point is binary scientific notation
Most languages represent numbers with a fractional part as IEEE 754 double-precision floats. A double spends 64 bits on a sign, an exponent and 52 bits of fraction, which gives 53 significant binary digits. It is scientific notation in base 2: a binary number like 1.0110... times a power of two.
In base 10, you can write 1/4 exactly as 0.25, but 1/3 becomes 0.3333... and you have to stop somewhere. Base 2 has the same problem with a different set of numbers. A fraction is exact in binary only if its denominator is a power of two. One tenth has a factor of 5 in its denominator, so in binary it is 0.000110011001100... repeating forever, and the double stores the nearest value it can.
You can print the stored values with more digits than the language normally shows.
console.log((0.1).toPrecision(25));        // 0.1000000000000000055511151
console.log((0.2).toPrecision(25));        // 0.2000000000000000111022302
console.log((0.3).toPrecision(25));        // 0.2999999999999999888977698
console.log((0.1 + 0.2).toPrecision(25));  // 0.3000000000000000444089210
console.log(0.1 + 0.2 === 0.3);            // false
Output
Both 0.1 and 0.2 are stored slightly high. Their exact sum falls between two doubles, and rounding picks the one just above 0.3. The literal 0.3 is stored as the neighbor just below. They are two different doubles, so 0.1 + 0.2 === 0.3 is false.
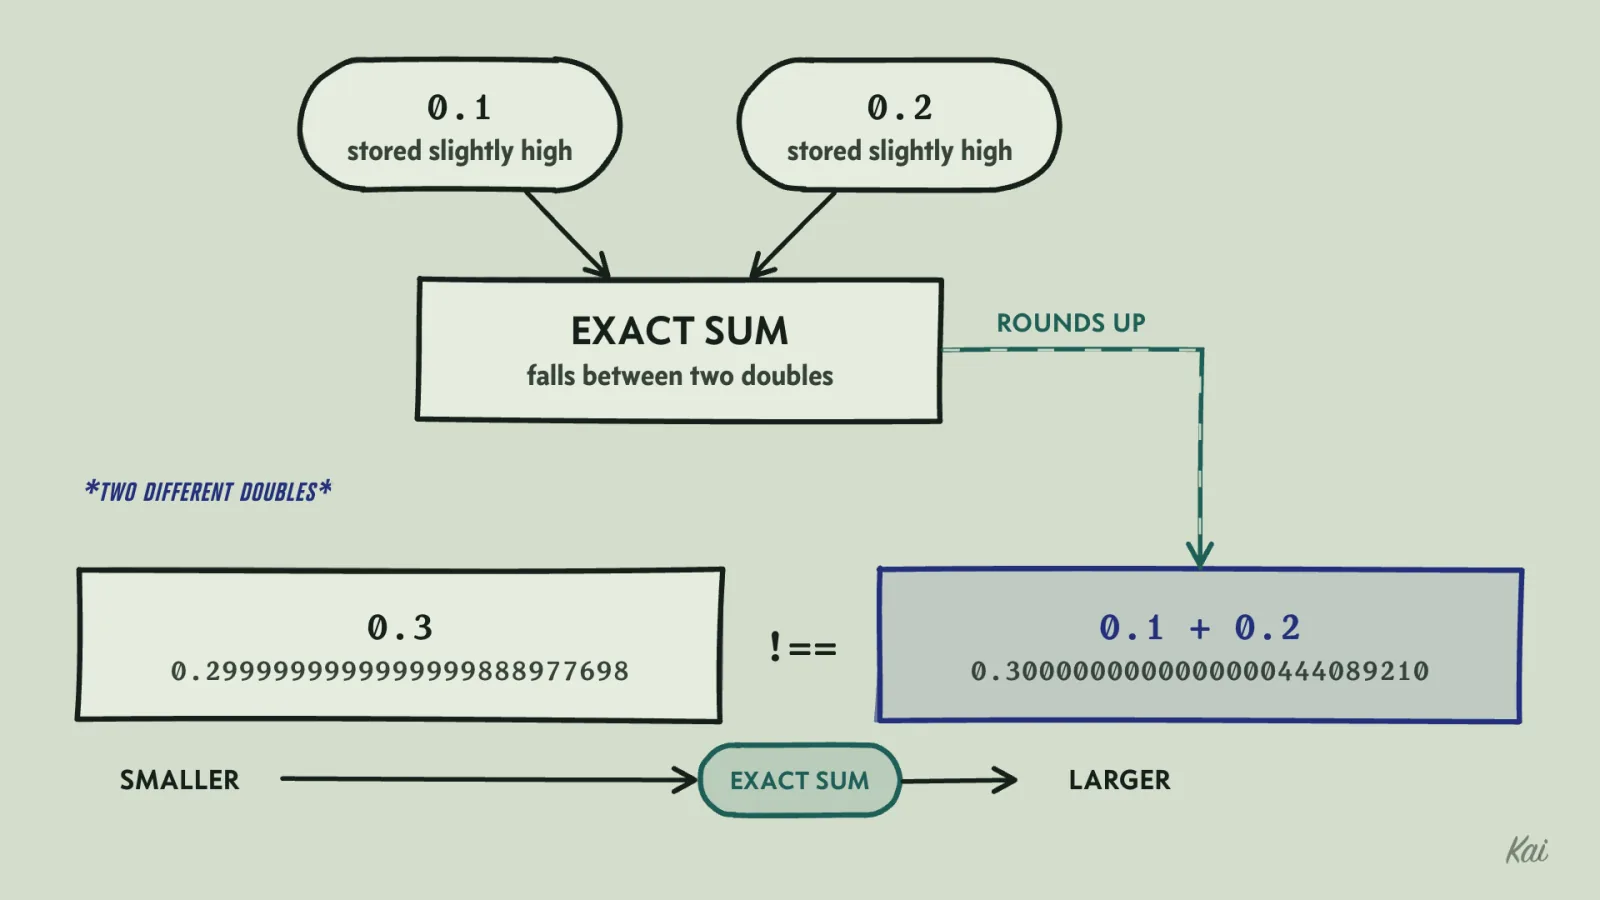
0.1 and 0.2 falls between two doubles and rounds up, while the literal 0.3 is stored as the neighbor below, so 0.1 + 0.2 === 0.3 is false.This happens in any language that uses IEEE 754 doubles, which is nearly all of them.
The opening bug is the same effect. The double nearest 4.35 is 4.3499999999999996447..., and multiplying by 100 gives 434.99999999999994. Math.floor throws away everything after the point and returns 434. Rounding instead of flooring gives 435 here, but the deeper fault is that money passed through a type that cannot hold 4.35 at all.
Money wants exact units
Money has a smallest unit, and an integer count of it suits amounts that are already settled: prices, invoice lines, ledger entries. The usual choice is cents, or the minor unit of the currency, since some currencies have zero or three decimal places. Integers add and compare exactly. Calculations that need fractions, such as tax rates, interest and currency conversion, use exact decimals with an explicit rounding step, described below.
// The agent's version, through a float.
const viaFloat = (s: string) => Math.floor(parseFloat(s) * 100);

// Works on the digits of the text and never builds a float.
function parseCents(s: string): bigint {
  const m = /^(\d+)(?:\.(\d{1,2}))?$/.exec(s.trim());
  if (!m) throw new Error(`not a price: ${s}`);
  return BigInt(m[1]) * 100n + BigInt((m[2] ?? "").padEnd(2, "0"));
}

for (const s of ["4.35", "4.3", "12", "1.15", "0.29", "123456789012345.67"]) {
  console.log(`${s}: float ${viaFloat(s)}, digits ${parseCents(s)}`);
}
Output
The float version loses a cent on 4.35, 1.15 and 0.29, and gets the last digits of the long price wrong. parseCents works on the digits of the text and never builds a float. The result is a BigInt, which has no upper limit, so a long input keeps every digit. The same sum done with Number would quietly round once the value passed 2^53, a limit covered below. Convert to a Number or a database column only after checking the range.
The other approach is a decimal type, such as Python's Decimal or Java's BigDecimal, which stores base-10 digits so 4.35 is exactly 4.35. Build it from a string, because Decimal(4.35) receives the float that already lost the value.
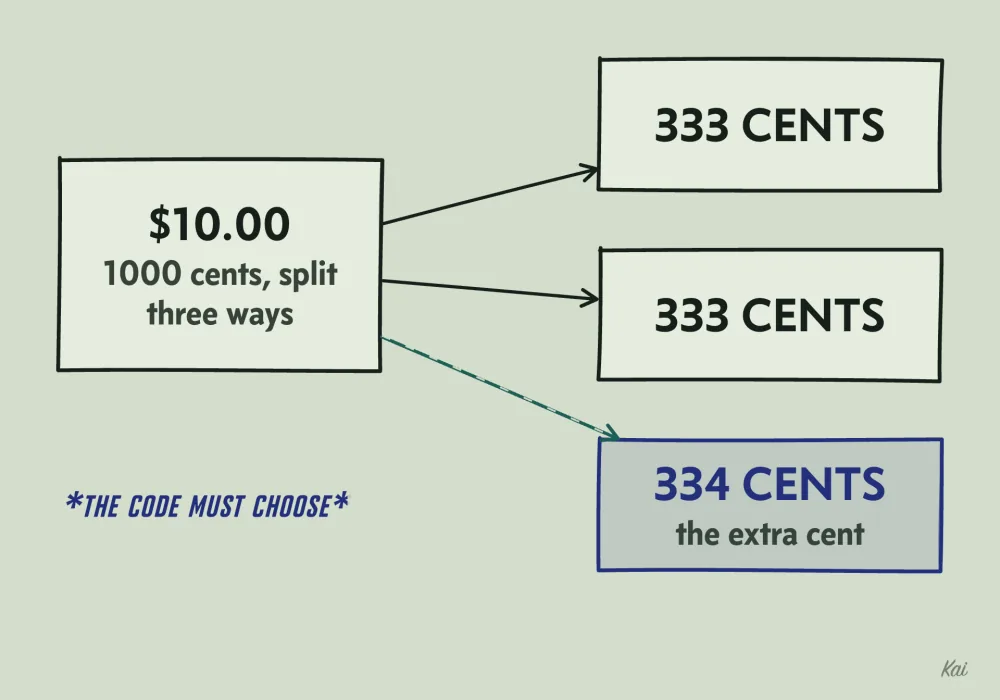
Integer cents move the problem to one place: division. Tax, discounts, currency conversion and splitting a bill all produce fractions of a cent, and something has to decide where they go. Split $10.00 three ways and you get 333, 333 and 334 cents, and the code must choose who pays the extra one.
Rounding needs a named rule too. Python's round(2.675, 2) returns 2.67 because the stored value is 2.67499999..., and JavaScript's (1.005).toFixed(2) returns "1.00" for the same reason. Finance code states its rounding mode (half-up, half-even) explicitly and applies it once, at a defined step.
When you review money code, find every place a value is parsed, multiplied, divided or compared. Any float, double or plain JavaScript number with a fractional part on that path is a bug waiting for the right input. An equality check on amounts that went through floating point can reject two totals that are mathematically equal but were computed along different routes.
Large integers in JSON
JSON text can hold any number of digits, but most parsers turn numbers into doubles. A double holds integers exactly only up to 2^53, which is 9,007,199,254,740,992. Past that, consecutive integers can no longer all be represented, and the parser returns the nearest one it can.
JSON.parse('{"id": 9007199254740993}').id    // 9007199254740992
JSON.parse('{"id": 1234567890123456789}').id // 1234567890123456800
No error is raised. The ID now names a different record, or none.
Databases hand out 64-bit IDs routinely, and distributed ID schemes produce values far above 2^53. This is why some public APIs send each ID twice, once as a number and once as a string. RFC 8259, the JSON standard, warns about exactly this range. If an ID can exceed 2^53, send it as a string and keep it a string on the client.
Text has three different lengths
Unicode assigns a number, called a code point, to every character it knows: U+0041 for "A", U+00E9 for "é", U+1F44D for the thumbs-up emoji. An encoding turns code points into bytes. UTF-8, the one you will meet almost everywhere, uses 1 byte for ASCII, 2 for most accented Latin letters, 3 for most Chinese and Japanese characters and 4 for emoji.
What a person sees as one character can be several code points. "é" can be the single code point U+00E9, or a plain "e" followed by U+0301, a combining accent.
A skin-tone emoji is the base emoji plus a modifier. A family emoji is several people joined by invisible zero-width joiners. Unicode calls the visible unit a grapheme cluster.
So a string has at least three lengths, and JavaScript adds a fourth, because its .length counts UTF-16 code units, where anything above U+FFFF takes two.
| Text | UTF-8 bytes | Code points | JS .length |
Visible characters |
|---|---|---|---|---|
| é (one code point) | 2 | 1 | 1 | 1 |
| é (e + combining accent) | 3 | 2 | 2 | 1 |
| 👍🏽 | 8 | 2 | 4 | 1 |
| 👨👩👧 | 18 | 5 | 8 | 1 |
The program below measures each row of the table in all four units, then truncates a message two ways.
const seg = new Intl.Segmenter("en", { granularity: "grapheme" });
const bytes = (s: string) => new TextEncoder().encode(s).length;
const visible = (s: string) => [...seg.segment(s)].length;

const samples = {
  "precomposed e-acute": "\u00E9",
  "e + combining accent": "e\u0301",
  "thumbs up, skin tone": "\u{1F44D}\u{1F3FD}",
  "family": "\u{1F468}\u200D\u{1F469}\u200D\u{1F467}",
};
for (const [name, s] of Object.entries(samples)) {
  console.log(`${name}: bytes ${bytes(s)}, code points ${[...s].length}, .length ${s.length}, visible ${visible(s)}`);
}

const msg = "Nice \u{1F44D}\u{1F3FD} work";
console.log(JSON.stringify(msg.slice(0, 6)));  // "Nice \ud83d"

function truncate(s: string, n: number) {
  return [...seg.segment(s)].slice(0, n).map((x) => x.segment).join("");
}
console.log(truncate(msg, 6));                 // Nice 👍🏽

console.log("\u00E9" === "e\u0301");                                    // false
console.log("\u00E9".normalize("NFC") === "e\u0301".normalize("NFC"));  // true
Output
.slice(0, 6) counts UTF-16 code units and stops after the first half of the emoji, which JSON.stringify prints as the escape \ud83d. That lone surrogate renders as a replacement box and is rejected by some encoders. Cutting UTF-8 bytes in the middle of a sequence produces invalid UTF-8. The two forms of "é" also compare as unequal until you normalize them, so a username check can treat them as different names. Normalize to one form (usually NFC) before comparing or storing keys.
When you see a length check or a truncation, ask which unit it counts and which unit the limit was meant in. A database column, an SMS segment, an API field limit and a UI counter may all count differently.
Time is an instant plus a place
An instant is a single point on the global timeline. It is usually stored as a count of seconds or milliseconds since 1970-01-01 00:00 UTC, or as a string with an explicit offset such as 2026-03-10T14:00:00Z. Local time is what a wall clock shows in some place, and turning one into the other needs a time zone: a named region such as America/New_York with rules for its offset from UTC, including daylight saving.
A timestamp written without a zone names no instant at all. JavaScript shows how quickly that goes wrong. A date-time string with no offset is parsed in the local zone of the machine running the code.
new Date("2026-03-10T09:00:00").toISOString()
// on a server set to America/Los_Angeles: "2026-03-10T16:00:00.000Z"
// on a server set to Europe/Berlin:       "2026-03-10T08:00:00.000Z"
The same stored string becomes two instants eight hours apart depending on where the server runs. Move the service to another region and every stored event shifts.
Store the instant in UTC and convert to local time only for display, using the viewer's zone name. The zone database knows when each place changes its clocks. Here is one webinar series at 14:00 UTC each week, shown to viewers in New York and London.
const show = (iso, zone) => new Intl.DateTimeFormat("en-GB", {
  timeZone: zone, day: "numeric", month: "short",
  hour: "2-digit", minute: "2-digit", timeZoneName: "short",
}).format(new Date(iso));

for (const t of ["2026-03-03T14:00:00Z", "2026-03-10T14:00:00Z", "2026-03-31T14:00:00Z"]) {
  console.log(show(t, "America/New_York"), "|", show(t, "Europe/London"));
}
// 3 Mar, 09:00 GMT-5 | 3 Mar, 14:00 GMT
// 10 Mar, 10:00 GMT-4 | 10 Mar, 14:00 GMT
// 31 Mar, 10:00 GMT-4 | 31 Mar, 15:00 BST
That is what Node prints. The punctuation and the zone abbreviations come from the runtime's locale data, so another runtime may write "3 Mar at 09:00" instead.
The United States moved its clocks forward on 8 March 2026 and the UK on 29 March, so for three weeks the gap between New York and London was four hours instead of five. Code that stored "UTC−5" for New York, or added a fixed five hours, would be wrong for those weeks and for the whole summer. A zone name follows the rules, and a fixed offset stays wrong from the next clock change on.
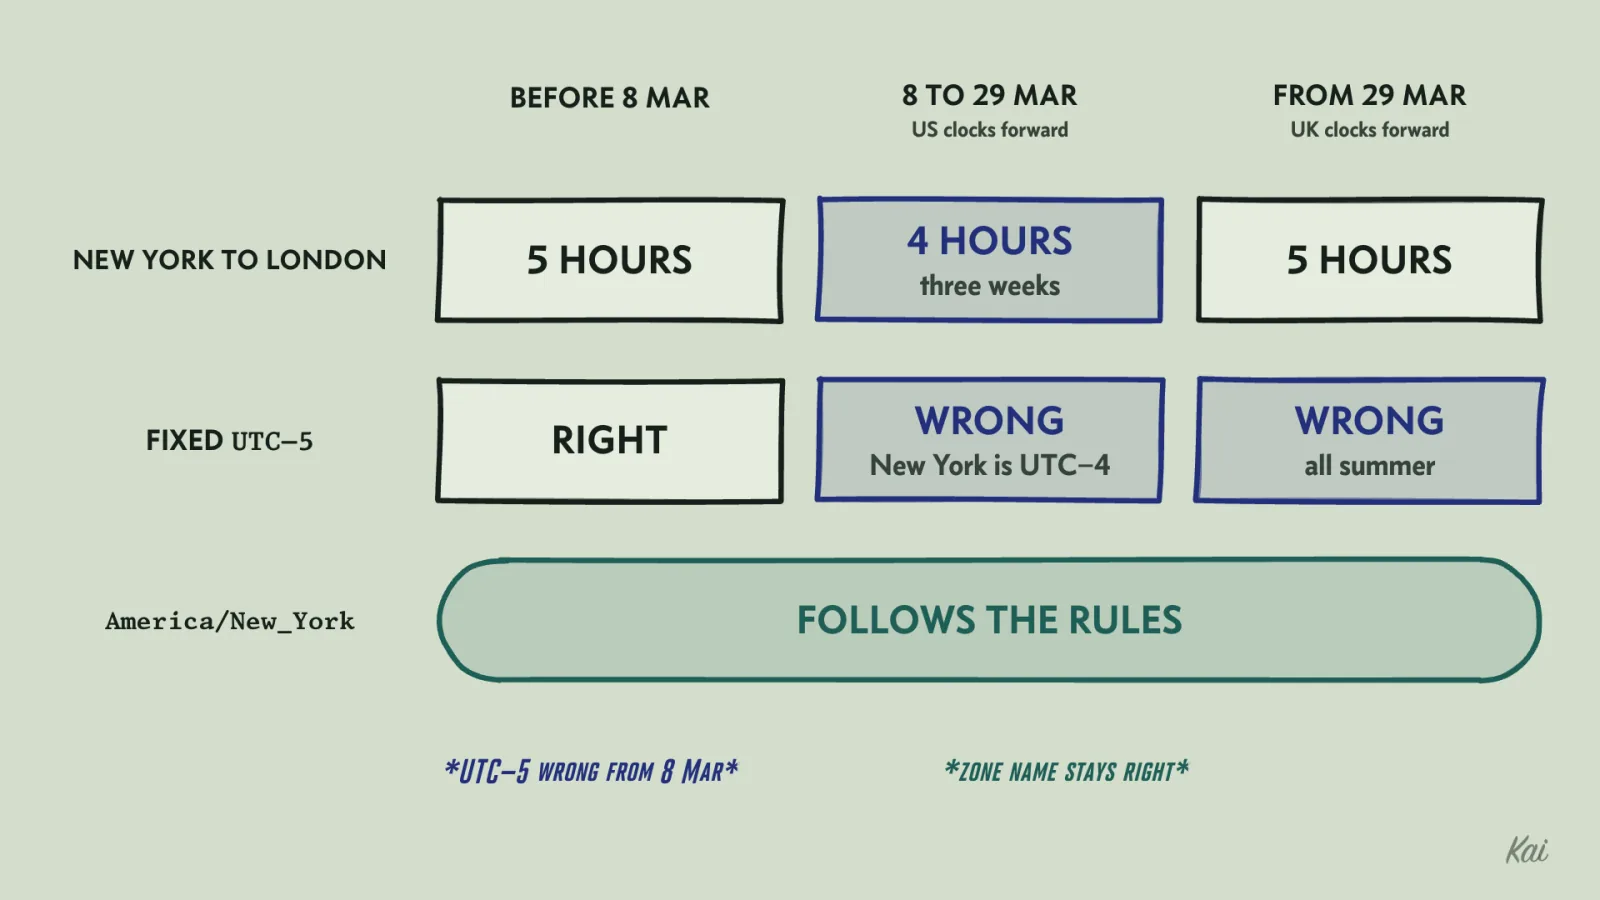
UTC−5 is wrong from 8 March on; the zone name America/New_York follows every change.One case reverses the rule. A future event defined in local time, such as a dentist appointment at 09:00 in Berlin next year, should be stored as that local time plus the zone name. Governments change daylight-saving rules with little notice, and a UTC value computed today would then point at the wrong hour.
For any timestamp in a review, find where its zone or offset is written down. If the answer is the server's configured zone, the value will move when the server does.