
Doing the Arithmetic Before the Build
An agent writes a script to tag your support history. It reads each of the 1,000,000 tickets in the database, sends the ticket text to a language model with instructions to pick a category, and writes the category back. The code is clean, it handles errors, and it worked on the ten tickets you tried. What it lacks is an estimate of what a full run costs.
A support ticket plus the instructions is around 1,500 tokens of input, and the answer is under 100 tokens of output. Assume a price of $3 per million input tokens and $15 per million output tokens. A million tickets at 1,500 tokens each is 1.5 billion input tokens, which costs $4,500. A million answers at 100 tokens each is 100 million output tokens, which costs $1,500. One run costs $6,000. If the agent then schedules the script nightly over every ticket, instead of only the new ones, that is about $180,000 a month. If each call takes about two seconds and the script runs ten at a time, one pass takes 1,000,000 × 2 s / 10 = 200,000 seconds, which is more than two days, so a nightly run would never finish before the next one starts.
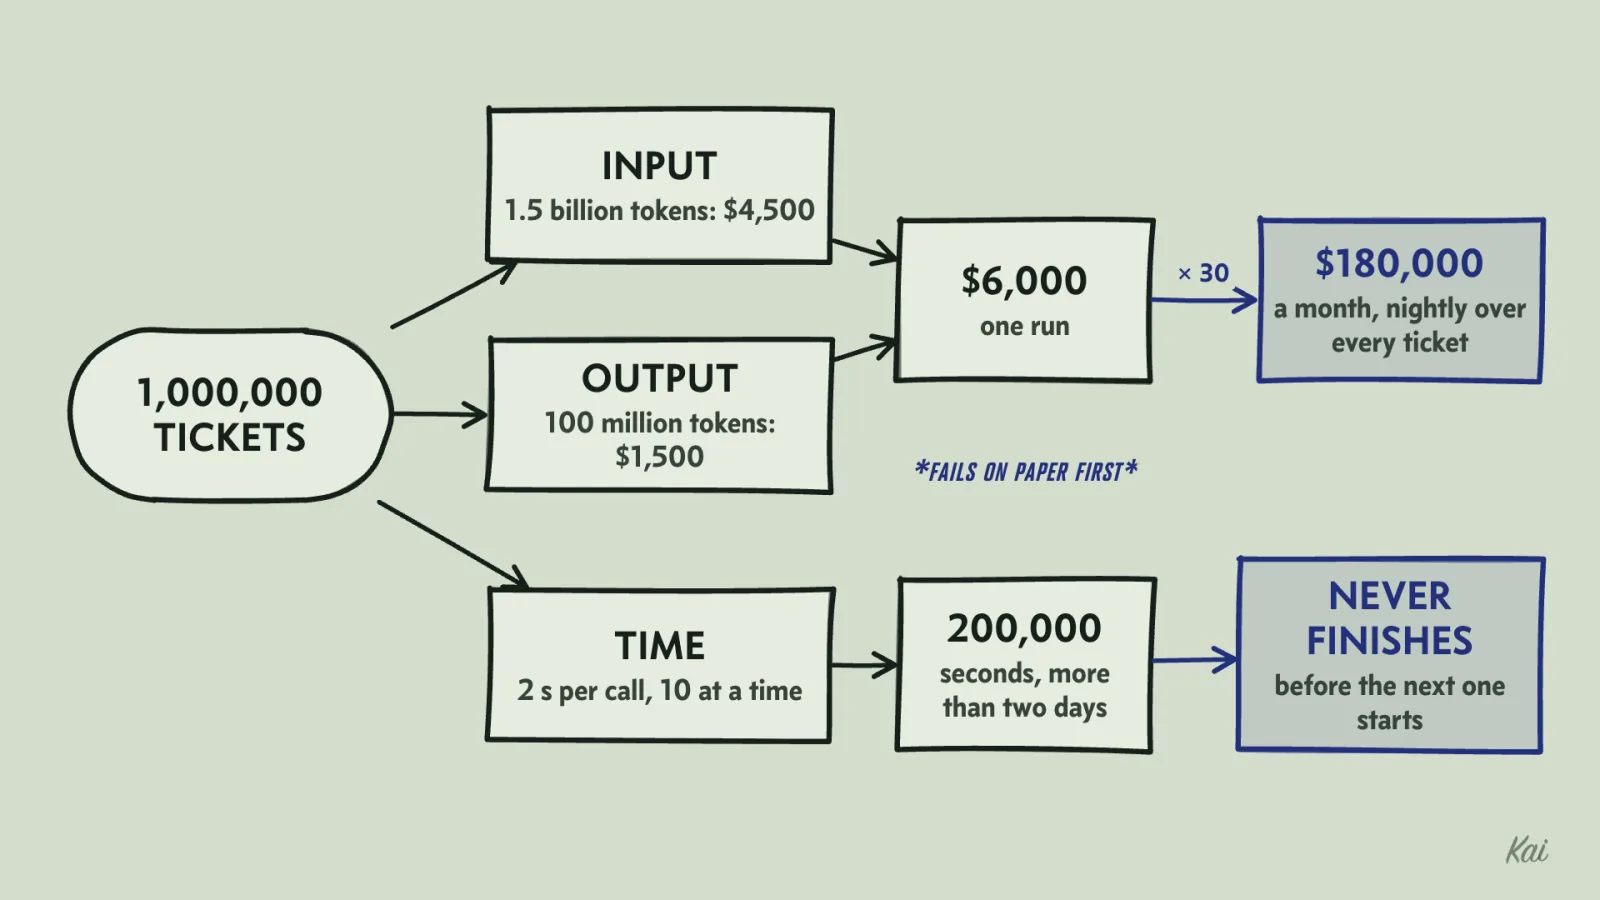
Back-of-the-envelope estimation is the habit of doing this arithmetic before building, so that designs that cannot work fail on paper where they are cheap to fix.
Round hard and keep the exponent
An estimate aims to get the power of ten right. Whether the answer is 3,000 or 5,000 rarely changes a decision. Whether it is 3,000 or 3,000,000 always does. So start by rounding every input to one significant figure, do the arithmetic in powers of ten, and keep track of the exponent above everything else. When the result lands within a factor of two or three of a limit, redo it with more precision, because rounding can move it to the wrong side.
A few conversions do most of the work:
- A day has 86,400 seconds. Round it to 10^5. A year has about 3 × 10^7 seconds.
- 2^10 is 1,024, close to 10^3. So 2^20 is about a million, 2^30 about a billion, 2^40 about a trillion. A KiB, MiB, GiB and TiB are within 10% of a KB, MB, GB and TB, which is noise at this precision.
- Network speeds are quoted in bits and storage in bytes, and a byte is 8 bits. A 1 Gbps link moves at most 125 MB per second.
- English text runs roughly four characters per model token, so a page of text is several hundred tokens.
Latency needs a few reference points too, each rounded to its order of magnitude. A read from main memory takes around 100 nanoseconds. A random read from a solid-state disk takes tens of microseconds to around a hundred. A round trip between two machines in the same data center takes a few hundred microseconds. A round trip between continents takes around 100 milliseconds or more, set by distance and the speed of light in fiber. Tables of measured figures like these exist, and Simon Eskildsen's napkin-math repository is one. Look up the numbers for the hardware you actually run on when the answer is close.
Turn daily volume into load per second
Designs describe volume per day. Components fail at a rate per second. So the first conversion in almost every estimate is from one to the other, and then from the average to the peak.
Suppose an agent designs click tracking for an app that sees a billion clicks a day, with every click inserted as its own row in one relational database. The average rate is 10^9 / 86,400 ≈ 11,600 writes per second. Traffic with a daily cycle is far from flat, so assume the busiest hour runs at about three times the average and check that against your own traffic graphs. That gives around 35,000 writes per second at peak.
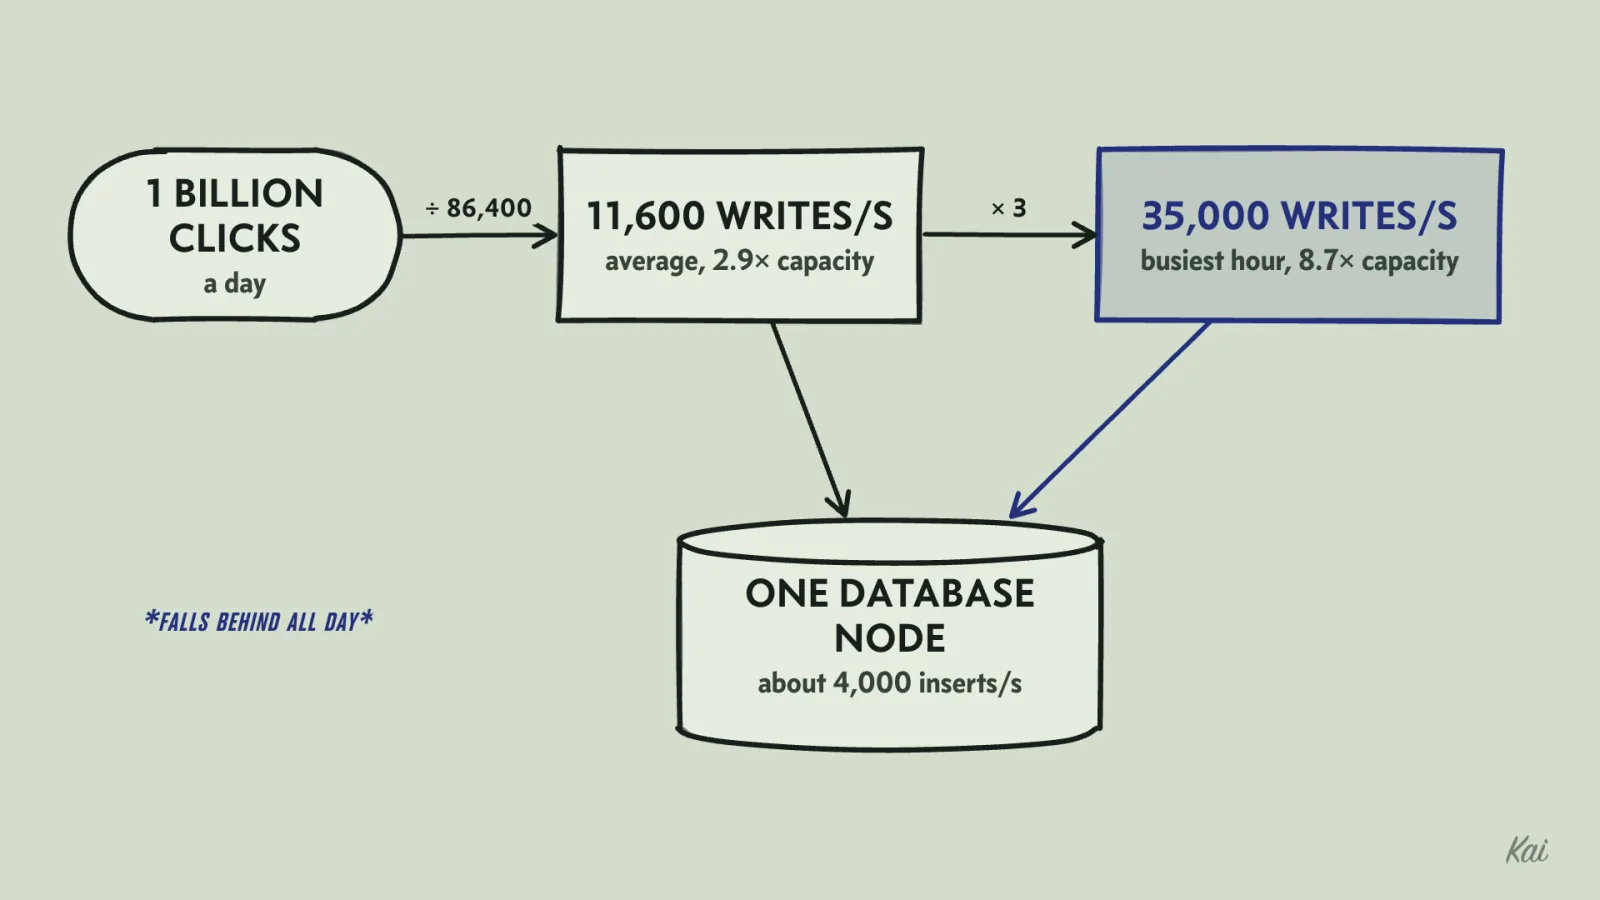
Now compare that load with the capacity of the component that has to absorb it. Say the team load-tested this database node last quarter and it sustained about 4,000 single-row inserts per second. The average alone is about 2.9 times that, and the peak is about 8.7 times, so the node falls behind all day and the backlog only grows. A gap that size is too large to expect configuration tuning to close, so the fixes change the shape of the design: batch many clicks into one insert, buffer them in a queue and write them in bulk, aggregate counts before storing them, or spread the writes across several nodes.
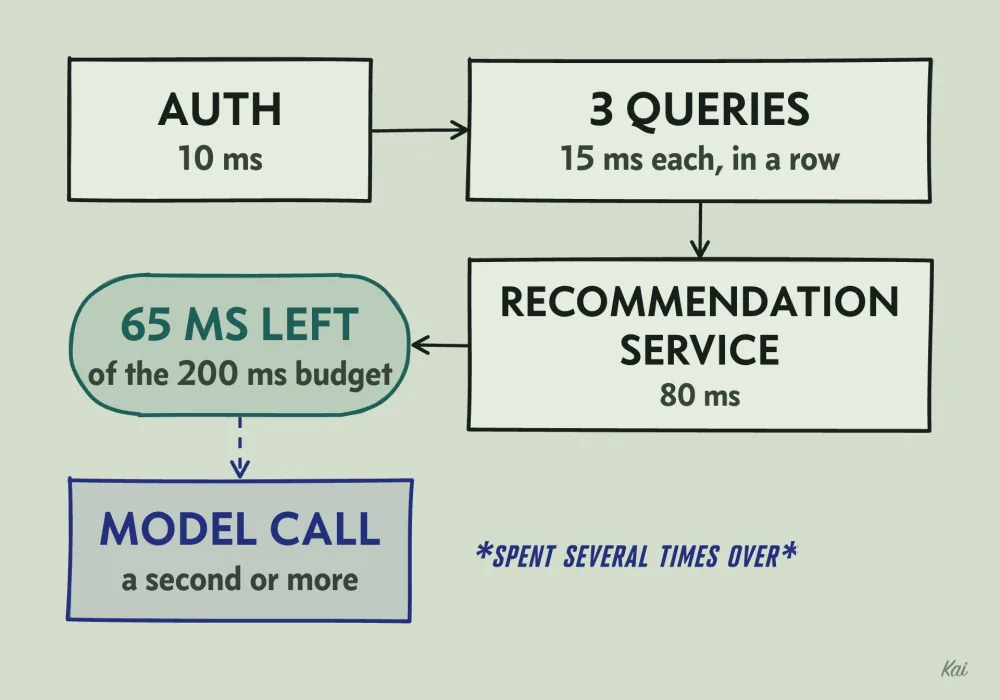
The same method works for latency. If a page must respond within 200 ms, write down every step it waits on. Say authentication takes 10 ms, three database queries run one after another at 15 ms each, and a recommendation service takes 80 ms. That adds up to 135 ms and leaves 65 ms for rendering and the network. If the agent then adds a model call that generates a paragraph, which typically takes a second or more, the budget is spent several times over before anything else happens. Adding up a budget like this shows which step to make parallel, cache, or move off the request path.
Storage grows every second, forever
Storage estimates multiply three things: records per second, bytes per record, and seconds of retention. Take a service handling 5,000 requests per second, where an agent has added a log line of about 1 KB for every request.
const requestsPerSecond = 5_000;
const bytesPerRequest = 1_000;
const secondsPerDay = 86_400;

const bytesPerSecond = requestsPerSecond * bytesPerRequest;
const bytesPerDay = bytesPerSecond * secondsPerDay;
const bytesPerYear = bytesPerDay * 365;
console.log(`${bytesPerSecond / 1e6} MB/s, ${bytesPerDay / 1e9} GB/day, ${Math.round(bytesPerYear / 1e12)} TB/year`);

// Second route: 5 MB every second, and a year is about 3 × 10^7 seconds.
const roughYear = 5e6 * 3e7;
console.log(`rounded route: ${roughYear / 1e12} TB/year`);
Output
Check the result a second way, as the last two lines do. The service writes 5 MB every second of every day. A year is about 3 × 10^7 seconds, and 5 × 10^6 × 3 × 10^7 = 1.5 × 10^14 bytes, or 150 TB. The two methods agree within rounding, so the arithmetic is probably right.
Next put a price on it. Hosted log services charge per gigabyte ingested, and prices vary a lot between vendors, so use your own contract rate. At an assumed $0.50 per GB, 432 GB a day costs about $216 a day, or roughly $6,500 a month, before storage and search. If the service itself runs on $3,000 a month of servers, its logs cost twice as much as it does. To bring that down, log a sample of successful requests, keep full records only for errors, drop fields you never query, and set a retention period.
Cost is volume times unit price
Every cost estimate is the same product: how many units the feature consumes per day, times the price per unit. The unit may be a request, a gigabyte stored for a month, a gigabyte transferred out of a cloud region, a CPU-hour, or a model token. The skill is in finding the volume, because the prices are published and the volume is buried in the design.
For a model feature, the volume is requests per day times tokens per request, split into input and output because they are priced differently. Look closely at the input side. An agent that sends a 20,000-token document as context on every request pays for those 20,000 tokens every time, even if the question is ten words long. Tokens per request is often where a factor of ten hides.
Then ask how the volume scales. A cost that is fine at today's traffic may grow with users, with rows, or with the product of the two. The opening example cost $6,000 as a one-time backfill and $180,000 a month as a nightly job over every row. Processing only the new tickets each night would cost a small fraction of that, and the code for the two versions differs by one filter. Here are the three runs side by side, assuming 3,000 new tickets a day:
const inputTokens = 1_500;   // ticket text plus instructions
const outputTokens = 100;    // the category
const inputPrice = 3 / 1e6;  // dollars per input token
const outputPrice = 15 / 1e6;
const secondsPerCall = 2;
const concurrency = 10;

function run(tickets: number) {
  const dollars = Math.round(tickets * (inputTokens * inputPrice + outputTokens * outputPrice));
  const seconds = (tickets * secondsPerCall) / concurrency;
  return { dollars, seconds };
}

const all = run(1_000_000);
const fresh = run(3_000);
console.log(`one backfill: $${all.dollars}, ${all.seconds} s`);
console.log(`nightly over every ticket: $${all.dollars * 30} a month`);
console.log(`nightly over new tickets: $${fresh.dollars} a night, ${fresh.seconds} s`);
Output
The full pass takes 200,000 seconds, about 56 hours, so it cannot run nightly at any price. The new-ticket pass costs $18 and ten minutes.
Write the units and let them cancel
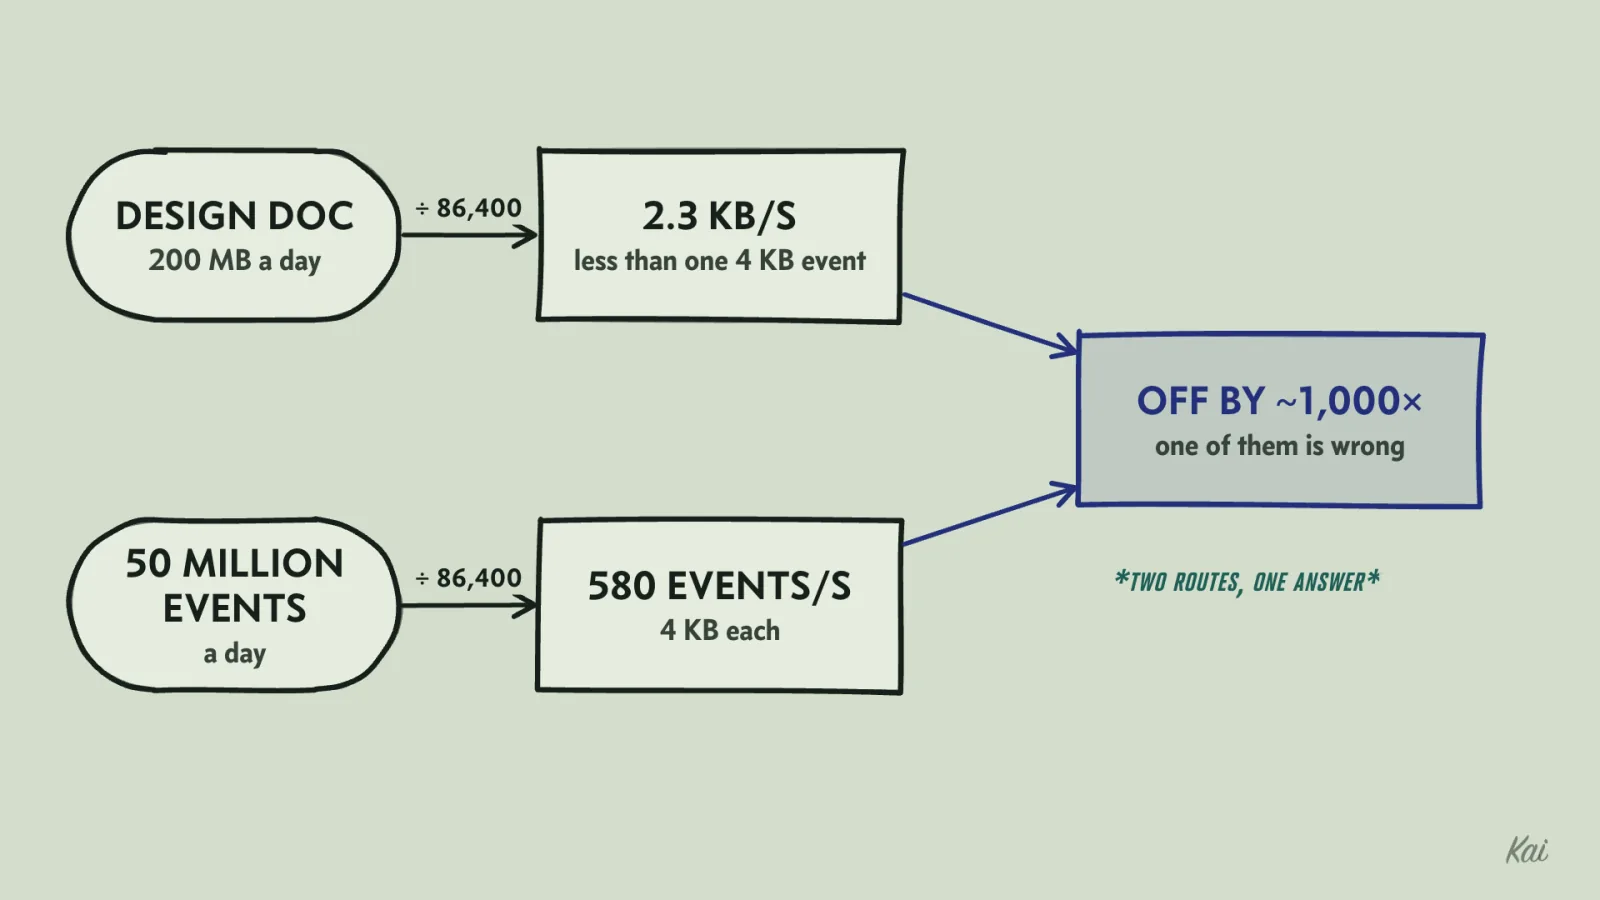
The mistakes that estimation catches best are factor-of-a-thousand errors, and they almost always come from a dropped unit. A design doc says: "Each event is about 4 KB and we expect 50 million events a day, so storage grows by about 200 MB a day." Redo it with the units attached:
50 × 10^6 events/day × 4 × 10^3 bytes/event = 2 × 10^11 bytes/day = 200 GB/day.
Here is the same multiplication done by code that carries each unit with its number, as an exponent, so the units cancel the way they do on paper:
type Units = Record<string, number>; // bytes per event is { byte: 1, event: -1 }
type Quantity = { n: number; units: Units };

function times(a: Quantity, b: Quantity): Quantity {
  const units: Units = { ...a.units };
  for (const [name, power] of Object.entries(b.units)) {
    units[name] = (units[name] ?? 0) + power;
    if (units[name] === 0) delete units[name];
  }
  return { n: a.n * b.n, units };
}

function show(x: Quantity): string {
  const top = Object.keys(x.units).filter((k) => x.units[k] > 0);
  const bottom = Object.keys(x.units).filter((k) => x.units[k] < 0);
  return `${x.n.toExponential(1)} ${top.join(" ")}/${bottom.join(" ")}`;
}

const eventsPerDay: Quantity = { n: 50e6, units: { event: 1, day: -1 } };
const bytesPerEvent: Quantity = { n: 4e3, units: { byte: 1, event: -1 } };
const growth = times(eventsPerDay, bytesPerEvent);

console.log("design doc:", 50 * 4, "MB/day");
console.log("with units:", show(growth));
console.log("the doc is low by a factor of", growth.n / (200 * 1e6));
Output
The events cancel, and what is left is bytes per day. The doc was off by a factor of 1,000, most likely because someone multiplied 50 by 4 and attached "MB" to a result that should have carried six more zeros from the event count and three from the kilobytes. Milliseconds against seconds, bits against bytes, and per-day against per-second are the other common sources. Those hide factors of 1,000, 8 and 86,400.
A second route to the same quantity catches what the first one missed. 50 million events a day is about 580 events per second. The doc's 200 MB a day is about 2.3 KB per second, which is less than one 4 KB event per second. The two figures disagree by a factor of about 1,000, so one of them is wrong.
After the units come out right, compare the answer with something you already know. Does 35,000 writes per second fit on one database node? Compare it with that node's measured number. An answer that disagrees with a reference point by more than a factor of ten means either the design is wrong or the arithmetic is, and both are worth knowing before anything is built.
Every rate in a design converts to a peak per-second load with units attached, and the component where that load most exceeds its measured capacity is the first suspect. Which one fails first also depends on the buffers in front of it and the length of the burst: a queue holding 1 million clicks absorbs a 31,000-per-second overload for about 32 seconds, and a peak that lasts an hour overflows it.