
Telling an Agent What You Want
You typed: "Invoice due dates are off by one day for some customers. Fix it and make sure the tests pass." Twenty minutes later the agent is done.
It added a new formatDueDate function inside the invoices module, changed the CI configuration to run tests in a different time zone, and deleted an assertion in a test that started failing along the way. The tests pass.
Each of those changes is a reasonable reading of what you wrote. You never said which date helper to use, which files were off limits, or what "fixed" would look like. The agent settled each of those questions without you.
The tempting repair is to take the wheel: tell it which file to open, which line to change and what to type. That prompt fails in a different way. A prompt should say what you want precisely enough that someone could check the result: the outcome, the facts the agent cannot see, the limits on what it may touch, and the evidence that proves it done. The steps belong to the agent. The criteria themselves are the subject of Requirements and Acceptance Criteria.
What the agent does with silence
As How Agents Work and How They Fail showed, the model knows only the text in its context plus the patterns from training. When the request leaves a decision open, the agent may infer, inspect the repository, or ask.
"Fix it" leaves the method open. The agent does not know that src/lib/dates.ts already has a function for exactly this, so it is as ready to write a new one as to search for the old one, and the codebase ends up with two date helpers that handle time zones slightly differently.
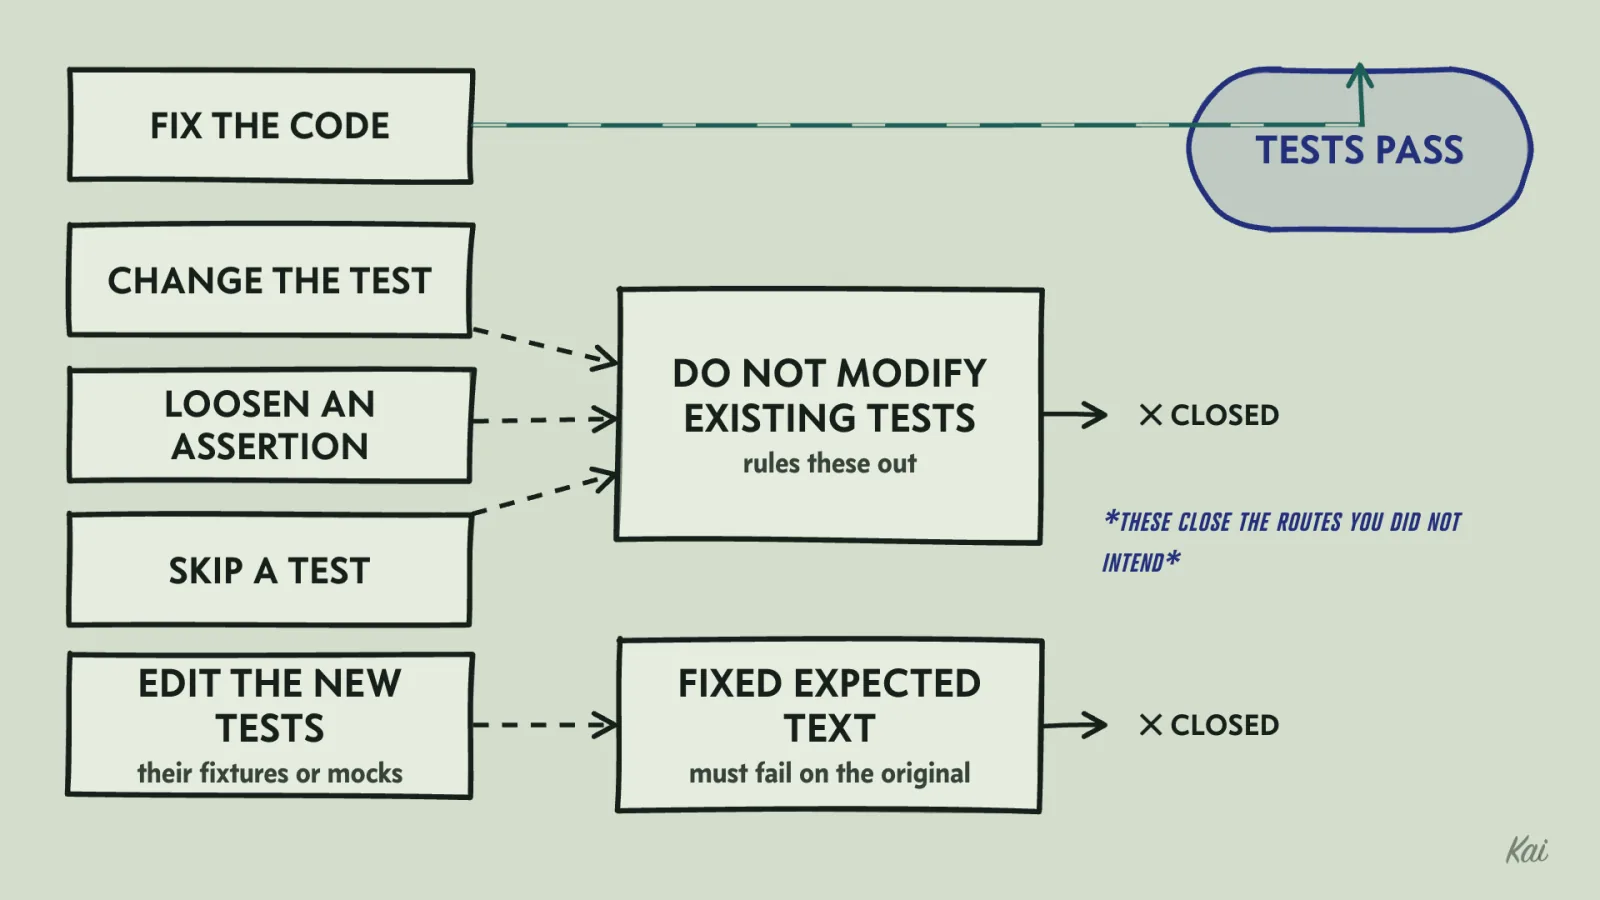
"Make sure the tests pass" states a goal with several routes. Fixing the code is one. Changing the test, loosening an assertion or skipping a test are others, and all of them satisfy the sentence you wrote. An agent in a loop that stops when the tests are green can take any of them.
The request also sets no boundary around the module. If the existing instructions and permissions allow it, the agent may edit the build scripts, the CI configuration or the shared library, and editing them can look like progress toward the goal.
The bug
Due dates are stored as date-only strings like "2026-10-15". The invoice page calls new Date(dueDate), and JavaScript parses a date-only ISO string as midnight UTC. Formatted in the browser for a customer in Los Angeles, midnight UTC on October 15 is 17:00 on October 14 local time, so the invoice shows the 14th. The test suite runs with TZ=UTC, where the two dates agree, so it never caught the bug.
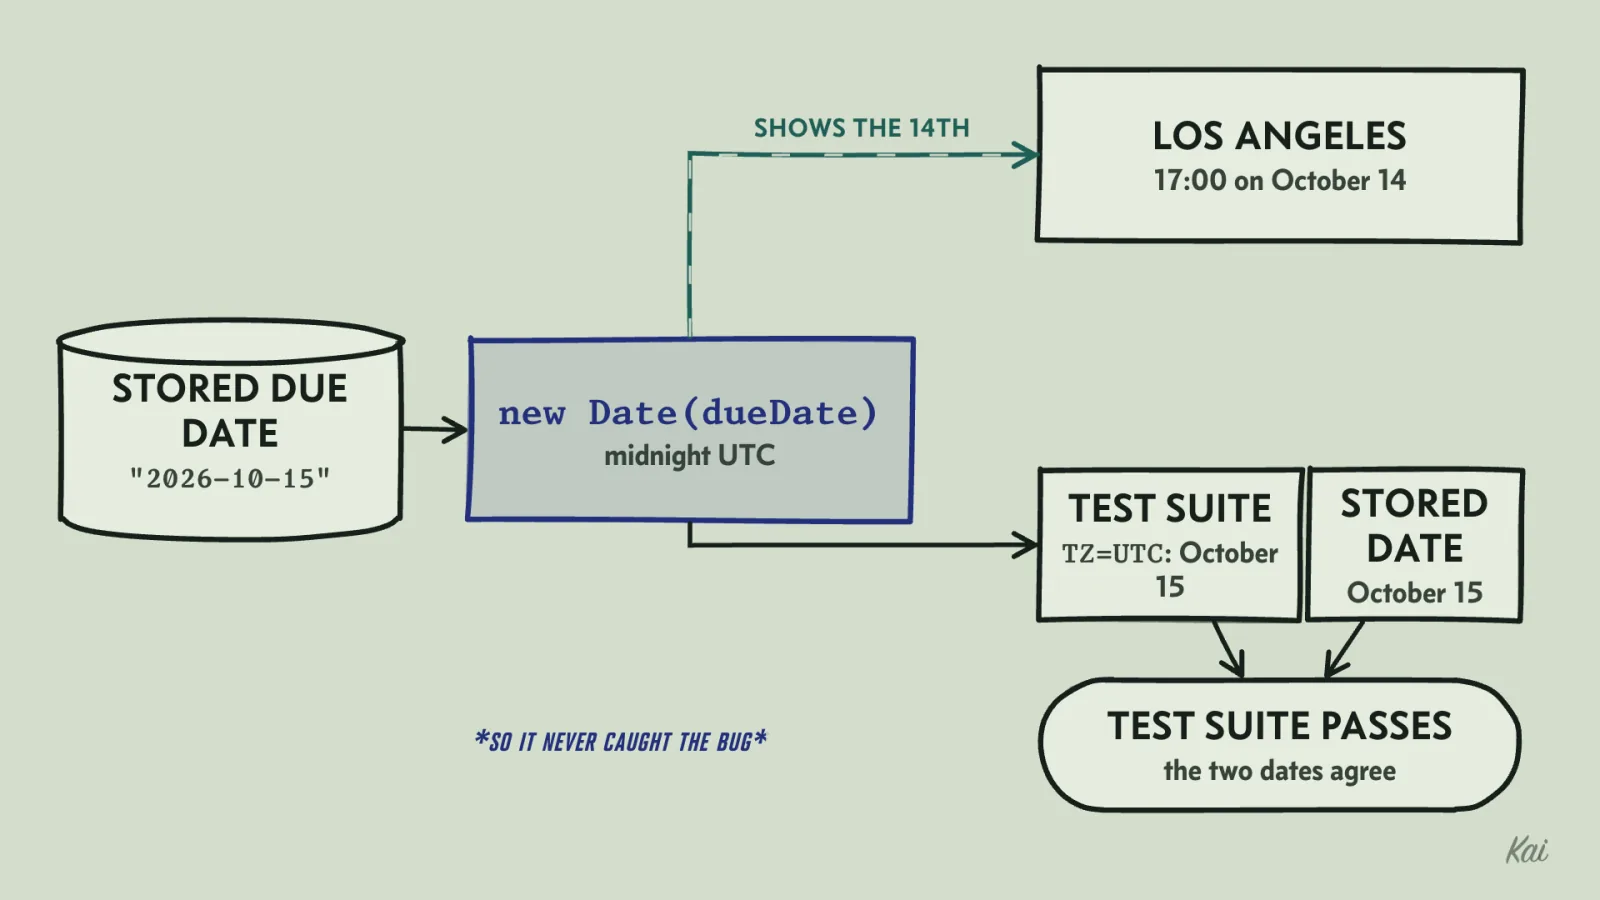
new Date(dueDate) turns the stored date into midnight UTC, which a Los Angeles browser shows as 17:00 on October 14. The test suite runs with TZ=UTC, where the two dates agree, so it never caught the bug.You can watch both halves of that. The time zone passed to each call plays the part of the customer's browser.
// The renderer's current code. timeZone stands in for the customer's browser.
function renderDueDate(dueDate: string, timeZone: string): string {
  return new Date(dueDate).toLocaleDateString("en-US", { timeZone, month: "short", day: "numeric", year: "numeric" });
}

// A stand-in for formatCalendarDate: the date-only string becomes midnight UTC,
// and formatting in UTC reads back the same calendar date wherever the customer is.
function formatCalendarDate(isoDate: string, locale: string): string {
  return new Date(`${isoDate}T00:00:00Z`).toLocaleDateString(locale, { timeZone: "UTC", month: "short", day: "numeric", year: "numeric" });
}

const expected = "Oct 15, 2026";
for (const tz of ["UTC", "America/Los_Angeles", "Asia/Tokyo"]) {
  const before = renderDueDate("2026-10-15", tz);
  console.log(`${tz}: old code shows ${before} (test ${before === expected ? "passes" : "fails"}), fixed code shows ${formatCalendarDate("2026-10-15", "en-US")}`);
}
Output
The old code fails only west of UTC, so any check of a fix has to run in a time zone like Los Angeles.
A prompt made of steps
Suppose you found that cause yourself, in src/invoices/render.ts, and wrote the fix down as instructions:
Open src/invoices/render.ts. Find the line that calls new Date(dueDate).
Replace it with formatCalendarDate(dueDate, locale), imported from
src/lib/dates.ts. Then run bun test and tell me when it passes.
The agent does exactly that. Every step is done, the suite is green, and a customer in Los Angeles who opens the invoice list still sees October 14. The list page lives in src/invoices/list.ts and has its own new Date(dueDate). Your diagnosis covered one file, so your steps covered one file, and the agent had no reason to look further.
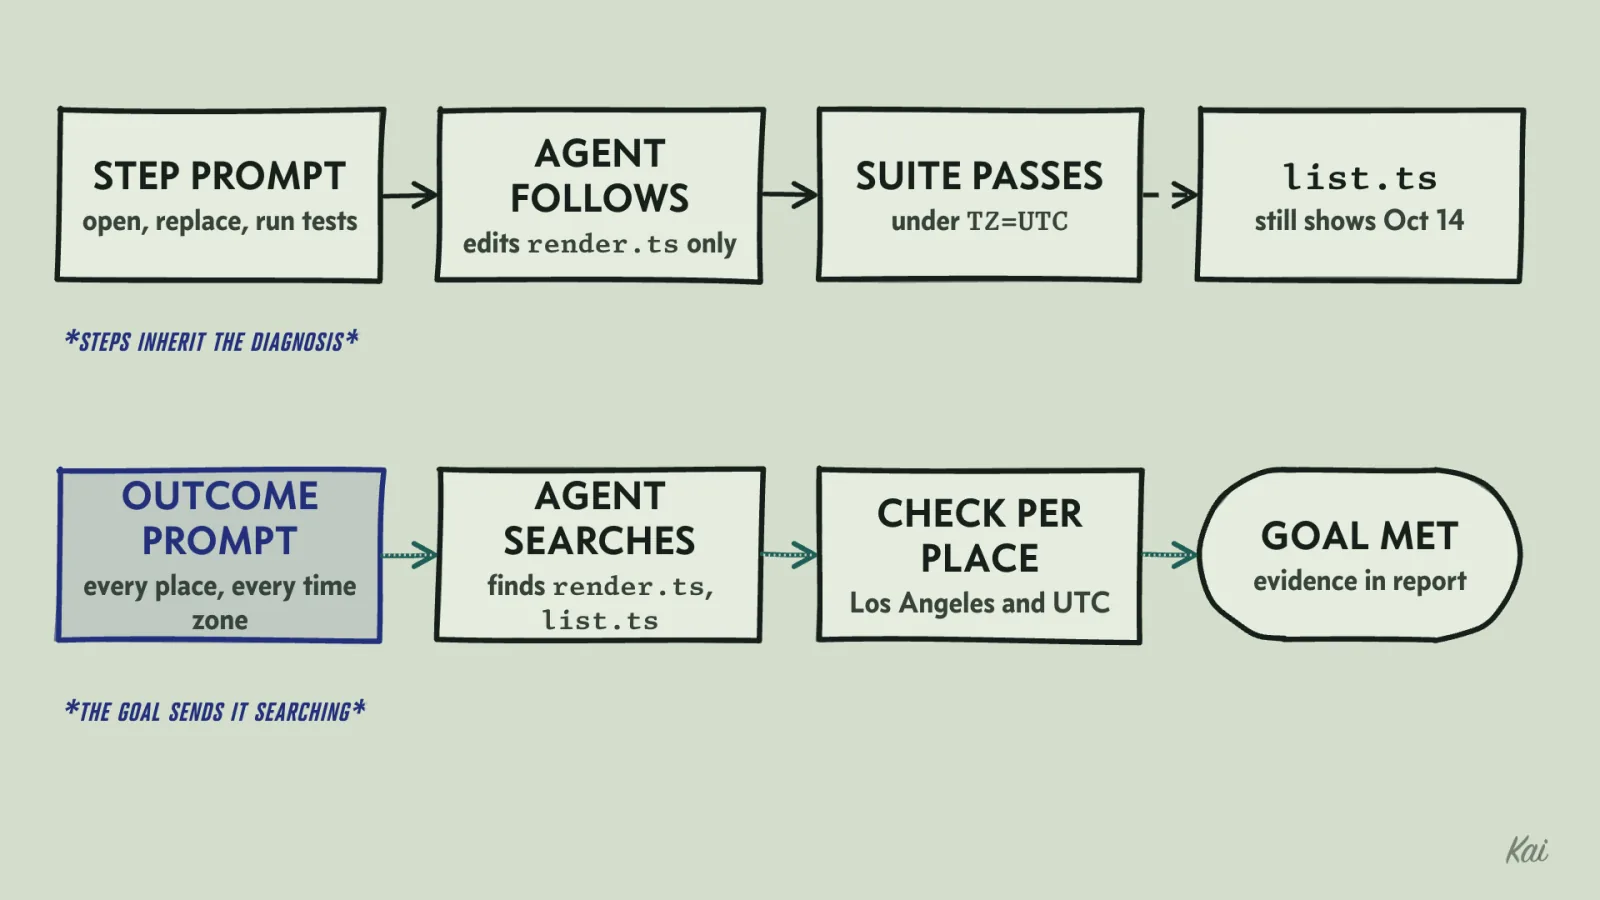
render.ts, the suite passes under TZ=UTC, and list.ts still shows Oct 14. The outcome prompt says every place and every time zone, so the agent searches, and a check per place proves the goal.Three things went wrong at once. The prompt carried your diagnosis as steps, so the agent inherited its blind spot. It named no outcome, so nobody had anything to hold the result against; "tell me when it passes" checks a suite that already passed before the change. And searching a repository for every place that formats a due date is quick work for an agent, which the steps gave it no reason to do.
That last cost grows with time. Richard Sutton's 2019 essay "The Bitter Lesson" observed that across decades of AI research, methods built on human knowledge of how to solve a problem were overtaken by general methods that scale with computation. Daniel Miessler applies it to prompts and harnesses in his essay "Bitter Lesson Engineering", with the rule "Don't confuse the 'what' with the 'how'." Steps written for last year's model hold back this year's. What you want, and the facts about your system, stay useful however capable the model becomes.
A prompt made of outcomes
Here is the same task written as what you want.
Goal
Invoice due dates display one day early for customers west of UTC.
Everywhere the app shows an invoice due date, a date stored as
"2026-10-15" must display as "Oct 15, 2026" with locale en-US, in every
time zone. Other locales keep the same calendar date in their existing
format.

Context
- Due dates are stored as date-only strings ("2026-10-15").
- src/invoices/render.ts formats them with new Date(dueDate), which parses
  a date-only string as midnight UTC. That is the likely cause; confirm it.
- src/lib/dates.ts already exports formatCalendarDate(isoDate, locale),
  which treats a date-only string as a calendar date. Use it. Do not add
  another date helper.
- Tests run with TZ=UTC, which is why they never caught this.

Scope
- You may edit files in src/invoices/ and test/invoices/.
- Do not edit src/lib/, package.json, the lockfile, or anything in .github/.
  If the fix seems to need one of those, stop and explain why.
- Do not modify or delete existing tests or assertions.
- Other problems you notice are out of scope. List them in your report.

Done when
- For each place that displays a due date, a new test renders a due date
  of "2026-10-15" with locale en-US and expects "Oct 15, 2026".
- Against the original code, with the time zone set to America/Los_Angeles,
  each new test fails because it displays "Oct 14, 2026". Against your
  change, the same tests and setup pass.
- The full suite passes with the rendering time zone set to
  America/Los_Angeles and then to UTC. If any tests run in a browser,
  set the browser context's time zone, not only TZ for the test runner.
- Your report lists every place you found that displays a due date, the
  commands you ran after your last edit with their output and time-zone
  configuration, and the files you changed.
Every line describes the result or the system, and the order of work is the agent's. Finding the list page is now its problem, because the goal says "everywhere" and the report has to show what it found.
The prompt still names render.ts and the helper. Those are facts about your system that the agent would otherwise have to discover or guess. "Use it. Do not add another date helper." is a preference and a constraint, a statement about what an acceptable result looks like, so it counts as what. A smarter model would still need to be told it, because the convention lives in your head.
The test for every line
Every line of a prompt is either a statement about the result or a step toward it. To sort them, ask of each line: would a more capable model, given the same facts, make this line unnecessary? If yes, the line is how. Cut it, or rewrite it as the outcome, fact or check it was protecting.
| Line | What it states | Kind |
|---|---|---|
Open src/invoices/render.ts. |
A step | How |
render.ts formats them with new Date(dueDate) |
A fact about the code | What |
Replace it with formatCalendarDate(...) |
A step built on one diagnosis | How |
Use it. Do not add another date helper. |
A convention the result follows | What |
Do not edit ... anything in .github/. |
A boundary | What |
Then run bun test and tell me when it passes. |
A step | How |
the commands you ran after your last edit |
The evidence you will check | What |
The same knowledge can be written either way. "Open render.ts and find new Date" and "render.ts formats them with new Date(dueDate)" carry the same information about the code. The order stops the agent's thinking at your diagnosis. The fact leaves it free to find a second call site.
Most how lines come from a worry. "Run bun test" was a worry about unverified work. The done-when line asking for the commands and their output, run after the last edit, answers the same worry as a requirement on the result, whatever route the agent takes. When you catch yourself writing a step, write down the worry underneath it as an outcome or a check.
Checks on the outcome work the same whoever chose the steps. This block turns the goal into a check and runs it on the code the step prompt left, and on code that meets the goal.
// The original code that both files started with.
const buggy = (iso: string, timeZone: string) =>
  new Date(iso).toLocaleDateString("en-US", { timeZone, month: "short", day: "numeric", year: "numeric" });
// A stand-in for formatCalendarDate from src/lib/dates.ts.
const formatCalendarDate = (iso: string, locale: string) =>
  new Date(`${iso}T00:00:00Z`).toLocaleDateString(locale, { timeZone: "UTC", month: "short", day: "numeric", year: "numeric" });

type Surfaces = Record<string, (iso: string, timeZone: string) => string>;
// After the step prompt: render.ts changed as instructed, list.ts untouched.
const afterSteps: Surfaces = { "render.ts": (iso) => formatCalendarDate(iso, "en-US"), "list.ts": buggy };
// Code that meets the goal: every place that displays a due date uses the helper.
const meetsGoal: Surfaces = { "render.ts": (iso) => formatCalendarDate(iso, "en-US"), "list.ts": (iso) => formatCalendarDate(iso, "en-US") };

// The suite runs under TZ=UTC only.
const suiteUnderUtc = (s: Surfaces) => Object.values(s).every((show) => show("2026-10-15", "UTC") === "Oct 15, 2026");
// The goal: every place, every time zone, shows the stored calendar date.
function checkGoal(name: string, s: Surfaces): void {
  const failures: string[] = [];
  for (const [file, show] of Object.entries(s))
    for (const tz of ["UTC", "America/Los_Angeles", "Asia/Tokyo"]) {
      const shown = show("2026-10-15", tz);
      if (shown !== "Oct 15, 2026") failures.push(`${file} in ${tz} shows ${shown}`);
    }
  console.log(`${name}: suite ${suiteUnderUtc(s) ? "passes" : "fails"}, goal ${failures.length ? `fails (${failures.join("; ")})` : "met"}`);
}
checkGoal("after the step prompt", afterSteps);
checkGoal("meets the goal", meetsGoal);
Output
The step prompt's result passes the suite and fails the goal, though every step was carried out as written. Only a check on the outcome exposes it.
What each section adds
The context section does the work a new teammate would do in their first hour. It names the file, the suspected cause and the helper that already exists, so the agent has an implementation to call and a reinvented one is easy to spot afterward.
Context also means leaving things out. Pasting the whole invoices module, the last three incident reports and a style guide makes the prompt long without making it clearer, and irrelevant context can bury the task's own instructions. Include what the fix needs: the files involved, the conventions that apply, and any past decision that rules out an obvious approach. Standing context that applies to every task, such as the test command and what good work looks like to you, belongs in files the agent reads at the start of every session, which the lesson on harness design covers.
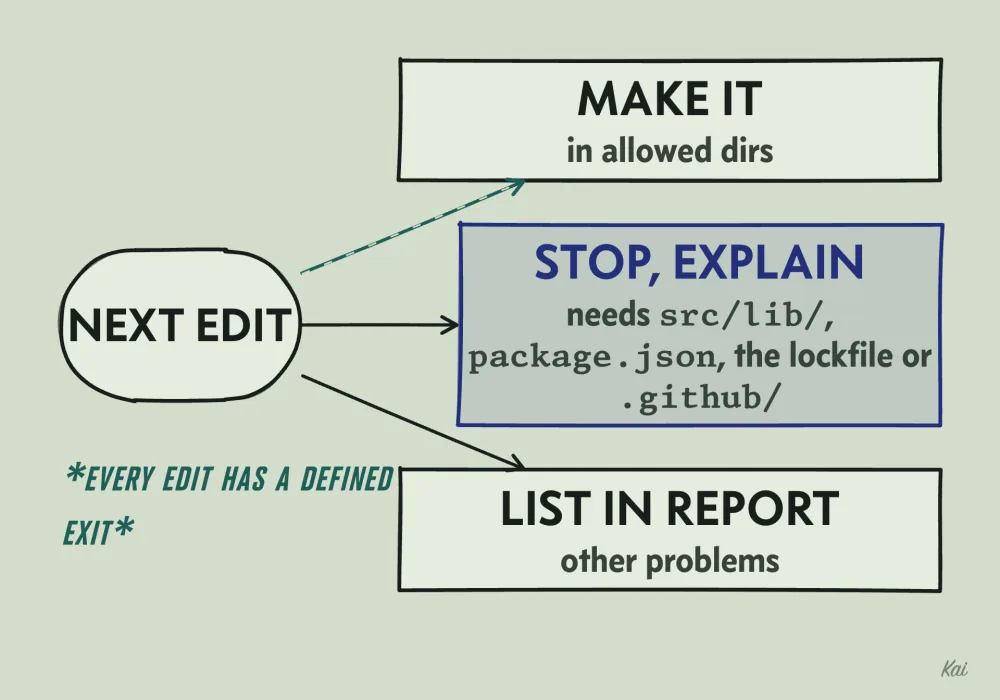
src/lib/, package.json, the lockfile or .github/, and list other problems in the report instead of fixing them in the diff.The scope section turns a vague permission into a list. Naming the directories the agent may edit, and the ones it may not, makes an edit to .github/ a visible violation. The instruction to stop and explain gives the agent something to do other than push through the boundary when the task does need to cross it. The line about other problems gives the agent a place to report cleanup it would otherwise do in the diff, which is how a ten-line fix grows into a change across twenty files.
The done-when section closes the routes you did not intend. "Do not modify existing tests" rules out weakening the assertions already there.
The agent can still edit the new tests, their fixtures or their mocks, so the prompt fixes the expected text and requires the same tests to fail against the original code for the right reason: the wrong displayed date. A test that passes against the buggy code proves nothing.
Running under both time zones matters because the original suite already passed under UTC, and a browser test needs its own time-zone setting because the runner's TZ may not reach it.
The last line asks for evidence. An agent's final message is generated text, and "all tests pass" is a likely sentence whether or not the tests ran. A pasted command with its output, run after the last edit, is something you can check.
The stranger test
Before you send a prompt, read it as a capable engineer who has never seen the repository. List what they would need to ask: which file, which helper, whether CI is off limits, how you will judge the result. Each item is a decision the agent may investigate, ask about or guess. Answer the ones that affect scope or correctness in the prompt.
Some items will be design decisions, such as whether generated files are stored or rebuilt on demand, which affects cost and how long customer data is kept. Those are yours. Decide them and write the answer into the prompt as a constraint. The stranger also flags how lines. Told to open a file and replace a line, a capable engineer would ask what the change is for, and the answer is the line the prompt should have contained.
Sizing a task by its checks
Once a prompt is written as outcomes, how much to hand over at once has a direct answer: as much as its checks can verify.
Take "let customers download invoices as PDFs and get them by email". It touches rendering, storage, permissions, a background job and email. Written as outcomes, each with its check:
- A test renders a fixture invoice to PDF, and the extracted text contains the customer name, the total and the due date.
- Tests show the owner can download the PDF, another customer's request gets a 404, and a logged-out request gets a 401.
- A test issues an invoice and finds exactly one queued email addressed to the customer, with the PDF attached.
Every outcome has a check the agent can run and you can run again, so this is one task. The agent will break it into steps and order them, building the renderer before the endpoint that serves it, because planning the steps is part of executing them. The size of the diff has no bearing on whether these checks prove the feature works.
Now add "the PDF should look professional". Nothing in the list can say pass or fail on that, so the agent decides what professional means, and its choice will pass every test you have. Before that outcome goes into a prompt, give it a check, such as a reference layout the output must match or a rubric with examples of good and bad, or keep it out of done-when and judge it yourself.
Split the work where a check is missing or different in kind: an outcome whose check needs something that does not exist yet, a decision only you can make, or a one-way change, such as a migration that drops a column, whose check is a rehearsal on a copy of production data. Inside each task, the decomposition is the agent's.
What to check when the work comes back
The prompt tells you what to check. Record the starting commit before the agent runs. Afterward compare git diff --stat <starting-commit> with the scope list, and run git status --short --untracked-files=all to see new files. Any file outside the scope is a finding.
That comparison, and a count of assertions and skipped tests, are mechanical enough to script. This block runs them on the vague prompt's result:
// The scope section of the prompt, as data.
const mayEdit = ["src/invoices/", "test/invoices/"];

// Files the vague prompt's run touched: `git diff --stat <starting-commit>` plus new untracked files.
const changed = [
  "src/invoices/render.ts",
  "src/invoices/formatDueDate.ts",
  "test/invoices/render.test.ts",
  ".github/workflows/test.yml",
];
for (const file of changed.filter((f) => !mayEdit.some((dir) => f.startsWith(dir)))) {
  console.log("outside scope:", file);
}

// The test file before and after the run. Count assertions and skipped tests.
const before = `
test("due date", () => { expect(render(inv)).toContain("Oct 15, 2026"); });
test("total", () => { expect(total(inv)).toBe(120); expect(tax(inv)).toBe(20); });`;
const after = `
test("due date", () => { expect(render(inv)).toContain("Oct 15, 2026"); });
test.skip("total", () => { expect(total(inv)).toBe(120); });`;
const count = (src: string, pattern: RegExp) => (src.match(pattern) ?? []).length;
console.log("assertions:", count(before, /expect\(/g), "->", count(after, /expect\(/g));
console.log("skipped tests:", count(before, /\.skip\(/g), "->", count(after, /\.skip\(/g));
Output
The new formatDueDate.ts sits inside an allowed directory, so the scope check passes it. Catching a duplicate helper takes a search of the diff for new functions whose names resemble existing helpers. Then check the execution log to see that the reported commands ran after the final edit; if there is no log, rerun them against the final tree.
These checks show the agent stayed inside the lines you drew. Whether it reached the goal is a check against the goal itself: render a due date on every page that shows one, in a Los Angeles browser context, and read what it displays.