
A Test Should Give the Same Answer Every Time
An agent adds a free-trial banner and a test suite to go with it. Everything passes on your laptop. In CI, one test fails every few dozen runs, and a rerun turns it green. Here is the code and the test:
const DAY = 86_400_000; // milliseconds in a day

export function trialDaysLeft(trialEnd: Date): number {
  return Math.floor((trialEnd.getTime() - Date.now()) / DAY);
}

test("shows three days left", () => {
  const trialEnd = new Date(Date.now() + 3 * DAY);
  expect(trialDaysLeft(trialEnd)).toBe(3);
});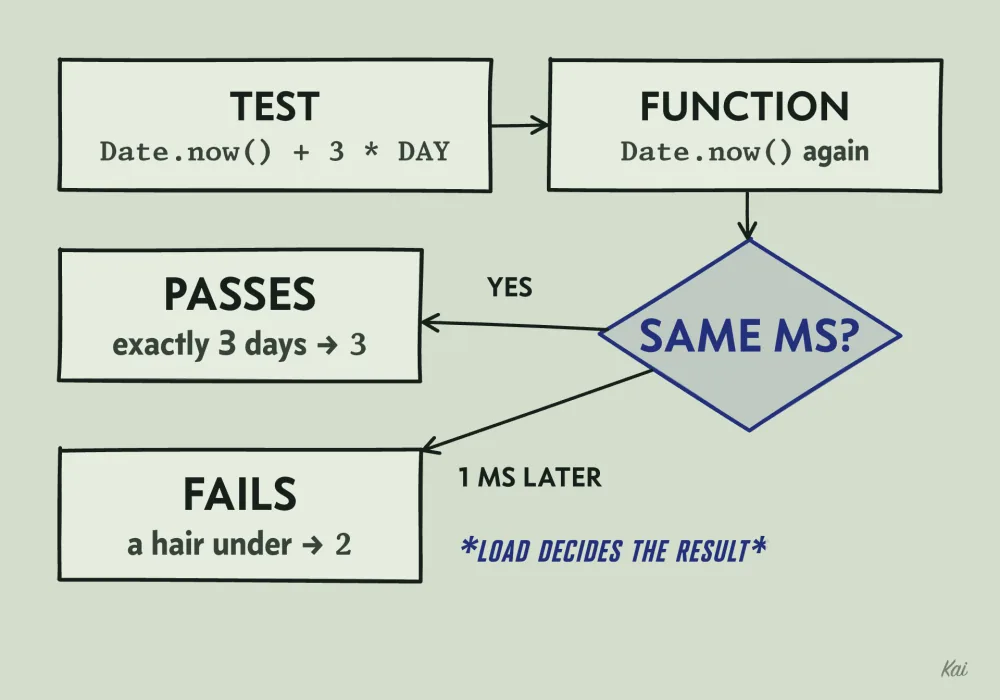
The test reads the clock, and then the function reads it again. If both reads land in the same millisecond, the difference is exactly three days and the answer is 3. If one millisecond passes between them, the difference is a hair under three days, Math.floor turns it into 2, and the test fails. On an idle laptop the two reads almost always share a millisecond, and on a busy CI machine they sometimes do not, so any run where the clock ticks between them fails, at a rate that depends on timing and load.
You can make the bad run happen on purpose. The playground replaces Date.now() with a clock that moves a set number of milliseconds each time it is read, then runs the same test with the clock standing still and with it moving 1 millisecond.
const DAY = 86_400_000;

// A stand-in for Date.now() that advances `tick` ms on every read.
function makeClock(tick: number): () => number {
  let t = Date.UTC(2026, 2, 10, 12);
  return () => {
    t += tick;
    return t;
  };
}

// The original function, reading the clock it is given instead of Date.now().
function trialDaysLeft(trialEnd: Date, readClock: () => number): number {
  return Math.floor((trialEnd.getTime() - readClock()) / DAY);
}

for (const tick of [0, 1]) {
  const readClock = makeClock(tick);
  const trialEnd = new Date(readClock() + 3 * DAY); // the test reads the clock first
  console.log(`clock moves ${tick} ms per read: ${trialDaysLeft(trialEnd, readClock)} days left`);
}
Output
A test that fails at random does damage beyond its own result. People learn to rerun red builds until they go green, and the day a real bug turns the build red, they rerun that too.
Every flaky test has a hidden input
A test is deterministic when its result depends only on what the test itself sets up. The trial test has an input it never set up: the clock. The usual hidden inputs are few:
- the current time and date;
- random numbers;
- the network, including any service you do not run yourself;
- the order tests run in, and whatever state earlier tests left behind in a global variable, a file or a shared database;
- timing between threads, processes or a browser and a server.
The fix is the same move each time. Turn the hidden input into an explicit one that the test controls. For time, the function takes now as a parameter, and the production caller passes new Date():
export function trialDaysLeft(trialEnd: Date, now: Date): number {
  return Math.floor((trialEnd.getTime() - now.getTime()) / DAY);
}

test("three full days left", () => {
  const now = new Date("2026-03-10T12:00:00Z");
  const trialEnd = new Date("2026-03-13T12:00:00Z");
  expect(trialDaysLeft(trialEnd, now)).toBe(3);
});
This test gives the same answer on every machine, every day. When you cannot change a signature, test frameworks offer fake clocks that replace the system time; Vitest has vi.useFakeTimers() with vi.setSystemTime(), and Jest has matching functions. A fake clock stays installed until something restores it, so it leaks into every later test in the file unless you undo it:
import { afterEach, test, expect, vi } from "vitest";

afterEach(() => vi.useRealTimers());

// Against the original one-argument trialDaysLeft, which reads Date.now().
test("three full days left", () => {
  vi.useFakeTimers();
  vi.setSystemTime(new Date("2026-03-10T12:00:00Z"));
  expect(trialDaysLeft(new Date("2026-03-13T12:00:00Z"))).toBe(3);
});Without the afterEach, a later test that expects real time to pass, such as one with a timeout, would wait on a clock that never advances.
Watch for a subtler version of the same problem: a test that computes its expected value from the real current date. It runs a different input every day. Most days are ordinary, so it passes for weeks. Then it runs on the 31st of a month, on February 29th, or on a day when daylight saving time makes the local day 23 or 25 hours long, and it fails. Fixed dates in the test turn those special days into deliberate test cases instead of accidents of the calendar.
Randomness gets the same treatment. The code takes a random source or a seed as a parameter, and the test supplies a fixed one. For ordering, each test builds the state it needs and cleans up after itself, and many test runners have an option to shuffle test order so that hidden dependencies between tests show up on purpose. For the network, the test talks to something you control, such as a local fake server, never a live third-party API that can be slow or down.
Fixed sleeps guess, and guess wrong
End-to-end tests drive a real browser against a real server, and the timing between them is a hidden input. Agents often handle it like this:
await page.click("#save");
await page.waitForTimeout(2000);
expect(await page.textContent("#status")).toBe("Saved");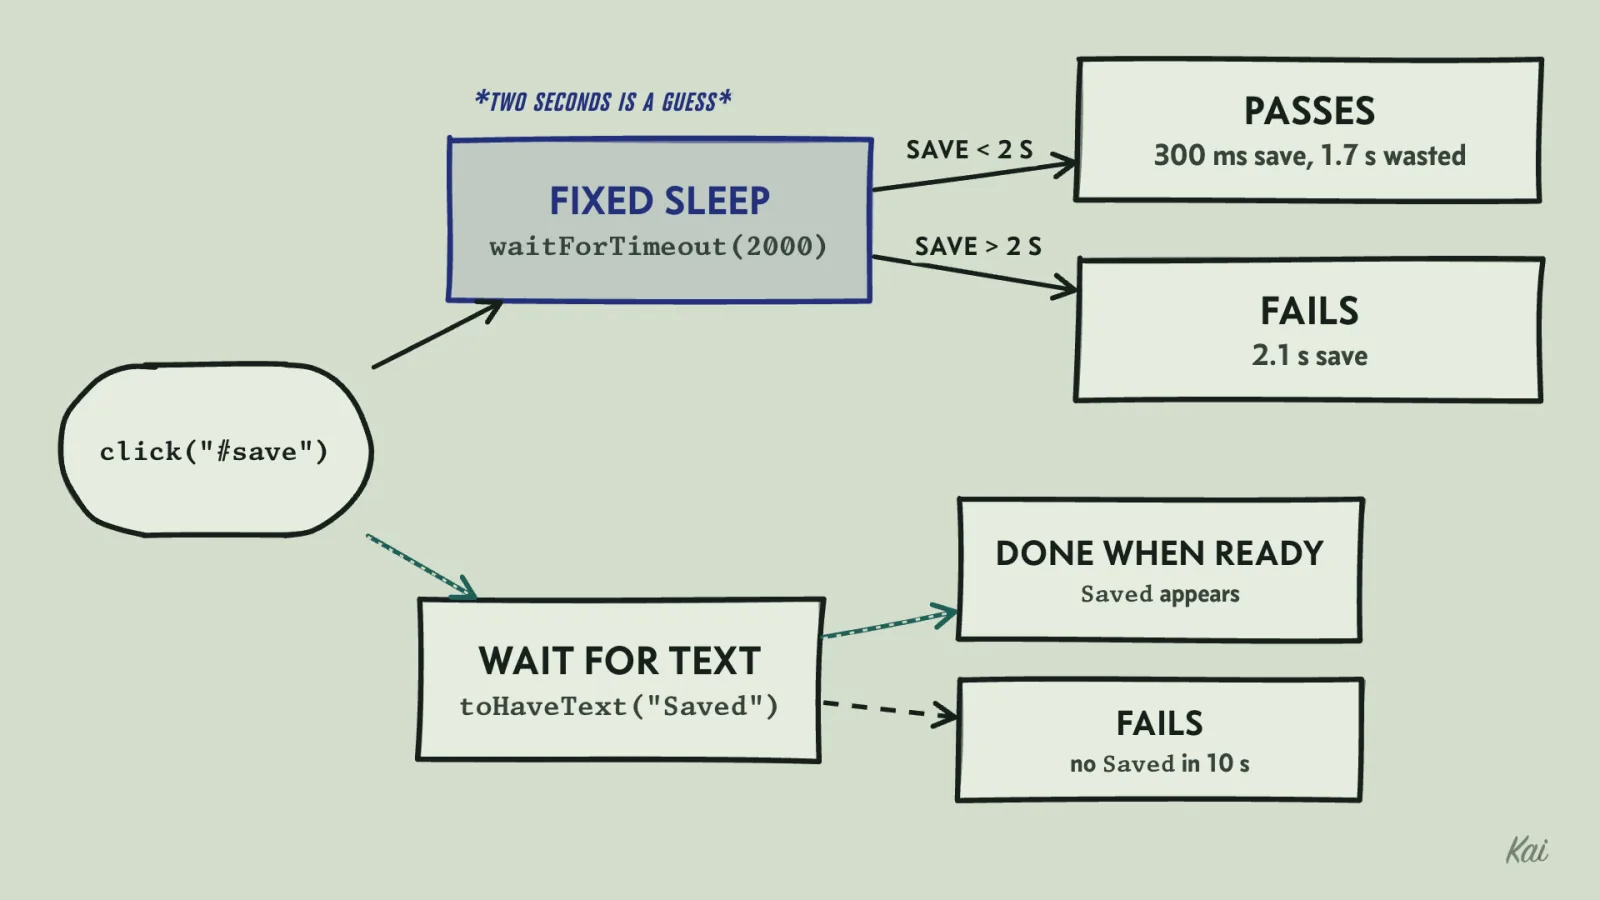
Saved appears, and fails only if it has not appeared after 10 seconds.Two seconds is a guess about how long saving takes. When saving takes 300 milliseconds, the test wastes 1.7 seconds, and across three hundred such tests that is over eight minutes of waiting. When CI is loaded and saving takes 2.1 seconds, the test fails.
The fix is to wait for the condition itself, with a deadline:
await page.click("#save");
await expect(page.locator("#status")).toHaveText("Saved", { timeout: 10_000 });
Playwright's toHaveText keeps checking until the text matches or the timeout expires. Where your tools lack that, a polling helper does the same job:
async function waitFor(check: () => Promise<boolean>, timeoutMs = 10_000, everyMs = 50) {
  const deadline = Date.now() + timeoutMs;
  for (;;) {
    const remaining = deadline - Date.now();
    if (remaining <= 0) break;
    // Race each check against the time left, so one hung check cannot outlive the deadline.
    let timer: ReturnType<typeof setTimeout> | undefined;
    const expired = new Promise<"expired">((resolve) => {
      timer = setTimeout(() => resolve("expired"), remaining);
    });
    let result: boolean | "expired";
    try {
      result = await Promise.race([check(), expired]);
    } finally {
      clearTimeout(timer);
    }
    if (result === true) return;
    if (result === "expired") break;
    // Sleep before the next check, but never past the deadline.
    await new Promise((resolve) => setTimeout(resolve, Math.min(everyMs, deadline - Date.now())));
  }
  throw new Error(`condition not met within ${timeoutMs} ms`);
}
The test now finishes as soon as the app is ready, tolerates a slow machine, and when it does fail, the message says what never happened. The race matters because a loop that checks the deadline only between checks would wait as long as a single check hangs, and capping each sleep at the time left keeps a long polling interval from running past the deadline too. The race abandons a hung check but cannot cancel it, so the I/O inside check should carry its own timeout too.
Mocks that hide the bug
The trial feature also needs a query for users whose trial ends in the next three days, so the system can email them:
export async function trialsEndingSoon(db: Db, now: Date): Promise<User[]> {
  const soon = new Date(now.getTime() + 3 * DAY);
  return db.query(
    "SELECT id, email FROM users WHERE trial_end > $2 AND trial_end <= $1",
    [now, soon],
  );
}
The parameters are swapped. The query asks for trials that end after three days from now and also before now, which no row satisfies, so the query returns nothing and no reminder is sent. The agent's test replaces the database:
test("returns users whose trial ends soon", async () => {
  const now = new Date("2026-03-10T12:00:00Z");
  const user = { id: 1, email: "a@example.com" };
  const db = { query: vi.fn().mockResolvedValue([user]) };
  expect(await trialsEndingSoon(db, now)).toEqual([user]);
});It passes. The SQL never ran, so the test proves only that the function returns whatever the mock returns. Every bug that lives in the query, such as a swapped parameter, a misspelled column or a wrong comparison, is invisible to it.
Replacements for real dependencies are called test doubles. A stub returns canned answers. A mock also records how it was called so the test can assert on the calls. A fake is a small working implementation, such as an in-memory store. Each one is useful when it replaces something slow, unreliable or outside your control, such as a payment provider or an email service. A double makes the test lie when it replaces the very thing that might be wrong. Here the thing that might be wrong is the query, so the test needs a real database.
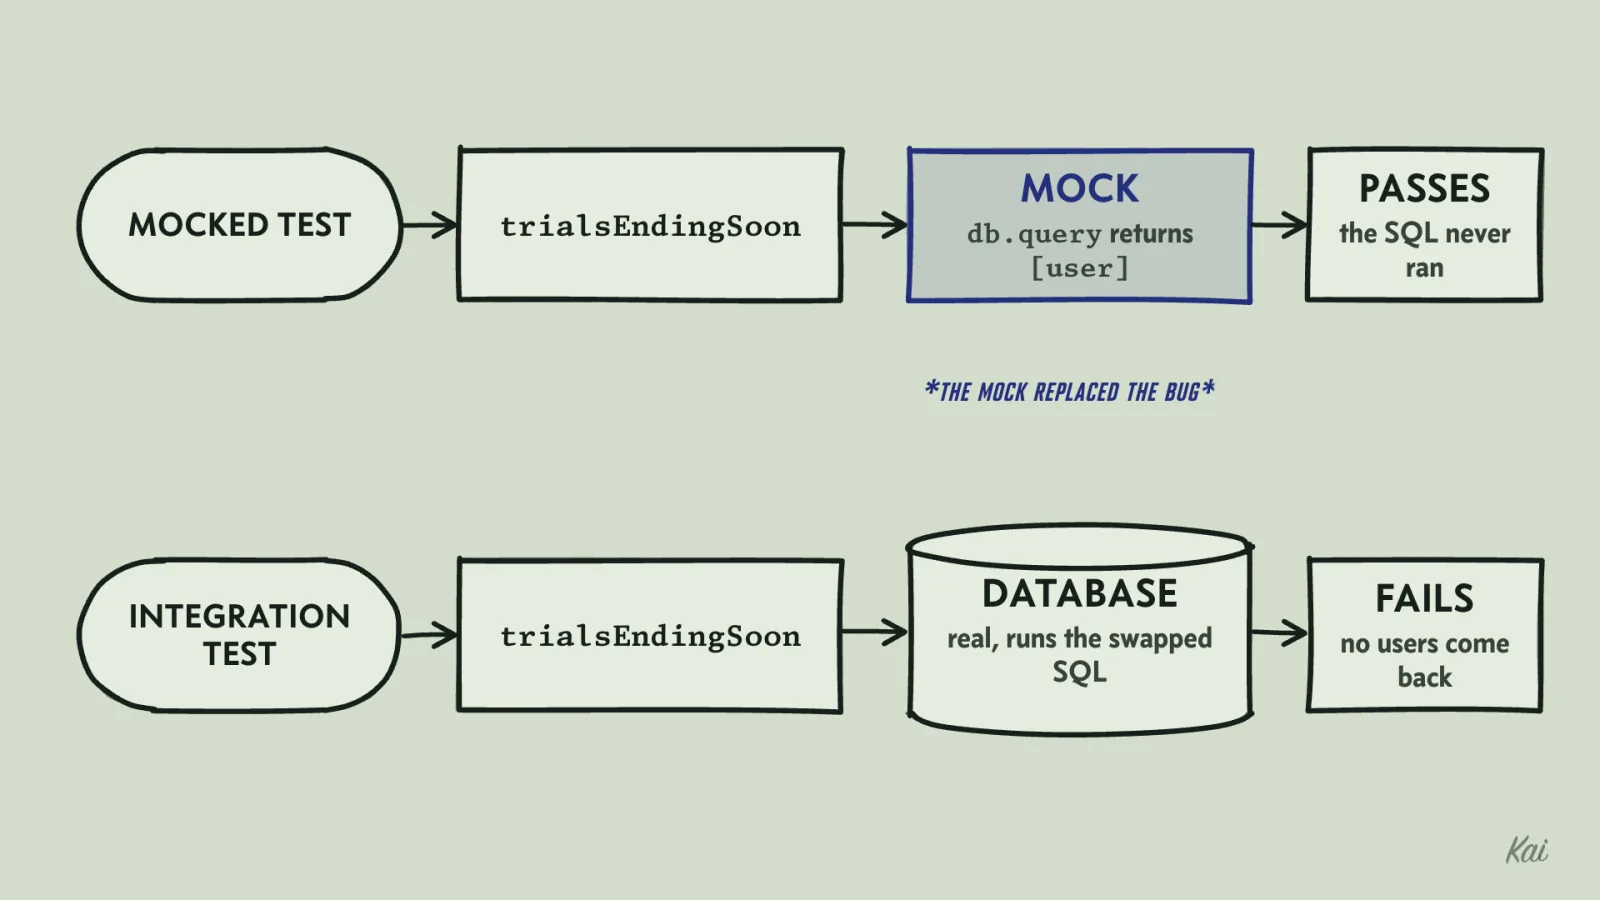
An integration test runs the query against the same database engine as production, in a throwaway instance, often started in a container. Insert three users whose trials end one day from now, five days from now, and yesterday. Assert that only the first comes back. Against the swapped parameters, that test fails.
The playground runs that data through the query in SQLite, with the timestamps stored as ISO text, which SQLite compares in time order. A real integration test would use the production engine; the point here is that the SQL itself runs. now is 2026-03-10 12:00 UTC and soon is three days later, written in where $1 and $2 would be bound.
CREATE TABLE users (id INTEGER PRIMARY KEY, email TEXT NOT NULL, trial_end TEXT NOT NULL);
INSERT INTO users VALUES
  (1, 'ends-tomorrow@example.com',   '2026-03-11T12:00:00Z'),
  (2, 'ends-in-5-days@example.com',  '2026-03-15T12:00:00Z'),
  (3, 'ended-yesterday@example.com', '2026-03-09T12:00:00Z');

-- As the agent wrote it: $1 = now, $2 = soon, so the bounds are swapped.
SELECT 'as written' AS query, count(*) AS users_found
FROM users
WHERE trial_end > '2026-03-13T12:00:00Z' AND trial_end <= '2026-03-10T12:00:00Z';

-- The bounds the right way round.
SELECT 'fixed' AS query, id, email
FROM users
WHERE trial_end > '2026-03-10T12:00:00Z' AND trial_end <= '2026-03-13T12:00:00Z';
Output
The mocked test passed against the first query. A real database returns no users for it and exactly the right one for the second.
Choosing the level
Tests come in three rough levels. A unit test runs one piece of logic in memory and takes milliseconds. An integration test runs your code together with a real dependency you control, such as the database, and takes longer. An end-to-end test drives the whole system through its user interface or public API, and is the slowest and the most prone to timing trouble.
Pick the lowest level at which the bug you care about can actually occur:
| Behavior | Level | Reason |
|---|---|---|
| Days-left arithmetic | Unit | Pure logic with many cases, cheap to run by the hundred |
| Query selects the right users | Integration | The bug lives in the SQL and the schema, which only a real database runs |
| Reminder email content for a given user | Unit, with a fake mail sender | The content is logic; the sending belongs to a vendor |
| A new user can start a trial and see the banner | End-to-end | Only the whole stack, browser included, proves it |
Most tests end up at the unit level, fewer at integration, and a handful end to end. Each step up costs speed and adds chances for flakiness, so each end-to-end test should cover a path that nothing lower can.
Boundaries come from the specification
Here is the banner's specification: a trial lasts 14 days, the banner shows whole days left rounded down, and once the trial has ended it shows 0, never a negative number.
Inputs that the specification treats the same way form an equivalence class. Test a representative input or two from each class, then test the boundaries where the result changes. This specification has three classes: at least a day left, less than a day left, and ended, and the result also steps at every whole-day boundary, since 2 days left gives 2 and 2 days minus a millisecond gives 1. Bugs cluster at these edges, so test them from both sides. For the last day and the end of the trial:
- exactly 1 day left gives 1;
- 1 day minus 1 millisecond gives 0;
- exactly at the end gives 0;
- 1 millisecond after the end gives 0.
The playground runs these four cases against trialDaysLeft, then against a version that clamps the result at 0.
const DAY = 86_400_000;
const end = new Date("2026-03-24T12:00:00Z");

const versions: Record<string, (trialEnd: Date, now: Date) => number> = {
  "as written": (trialEnd, now) => Math.floor((trialEnd.getTime() - now.getTime()) / DAY),
  "clamped at 0": (trialEnd, now) => Math.max(0, Math.floor((trialEnd.getTime() - now.getTime()) / DAY)),
};

// [case, milliseconds left before the end, what the specification says]
const cases: [string, number, number][] = [
  ["exactly 1 day left", DAY, 1],
  ["1 day minus 1 ms left", DAY - 1, 0],
  ["exactly at the end", 0, 0],
  ["1 ms after the end", -1, 0],
];

for (const [name, trialDaysLeft] of Object.entries(versions)) {
  console.log(`-- ${name}`);
  for (const [label, msLeft, expected] of cases) {
    const got = trialDaysLeft(end, new Date(end.getTime() - msLeft));
    console.log(`${got === expected ? "pass" : "FAIL"}  ${label}: got ${got}, expected ${expected}`);
  }
}
Output
The last case fails. Math.floor of a tiny negative number is -1, and the specification forbids negatives. None of the agent's tests looked past the end of the trial, because none of them came from the specification. You found this case by reading the rule and asking where its classes meet, without reading the code.
Most suites an agent writes test only the happy path. For any input, ask about these as well:
- Empty: an empty string, an empty list, a query that matches no rows.
- Maximum: a value exactly at the limit, and one past it.
- Negative: a negative quantity, or a date before the start date.
- Non-ASCII: names like "Zoë" or "東京", and emoji. A 20-character limit checked with
.lengthin JavaScript counts "👍" as two, because.lengthcounts UTF-16 code units. - Concurrent: two requests at the same moment. Fire two "start trial" requests for one user at a real database and assert that exactly one trial exists.
Each of these is a class the specification has an opinion about, even when it does not say so out loud. If you cannot say what the right answer is for an empty or concurrent input, the specification has a gap, and the agent filled it with a guess.
Before trusting a test, list every input it did not set up itself and every real component it replaced. Each item on that list is a place where the test can pass while the code is wrong.