
Measuring Things That Vary
An agent rewrites the system prompt for your support bot, runs the eval suite, and reports back: pass rate up from 80% to 84%, average response latency down from 72 ms to 66 ms, and the flaky integration test that failed now and then is fixed because it just passed. Each of those sentences is a measurement of something that varies, and each one can be true while meaning nothing.
The suite has 50 cases, so 80% versus 84% is 40 passes versus 42. The average hides whatever the slowest requests are doing. One green run of a flaky test is what a flaky test produces most of the time. Probability and statistics are the tools for asking how much a number would move by chance, and whether the difference in front of you is bigger than that.
The average hides the requests people remember
Take 1,000 requests to a service. Suppose 950 of them take 40 ms, 45 take 300 ms because they missed a cache, and 5 take 3,000 ms because they hit a garbage-collection pause or a retry.
The mean is the total divided by the count: (950 × 40 + 45 × 300 + 5 × 3,000) / 1,000 = 66.5 ms. No request took 66.5 ms. The number mixes a big fast group with a small slow group and describes neither.
The median is the middle value when the requests are sorted, here 40 ms. It tells you what a typical request feels like. A percentile generalizes that: the 99th percentile, written p99, is the value that 99% of requests are at or below. Sort the 1,000 times, and the 990th is 300 ms. The p99.9 is the 999th, which is 3,000 ms.
function percentile(sorted: number[], p: number): number {
  const rank = Math.ceil((p / 100) * sorted.length); // nearest-rank method
  return sorted[Math.max(rank, 1) - 1];
}

const times = [
  ...Array(950).fill(40),
  ...Array(45).fill(300),
  ...Array(5).fill(3000),
].sort((a, b) => a - b);

const mean = times.reduce((sum, t) => sum + t, 0) / times.length;
console.log(mean);                    // 66.5
console.log(percentile(times, 50));   // 40
console.log(percentile(times, 99));   // 300
console.log(percentile(times, 99.9)); // 3000
Output
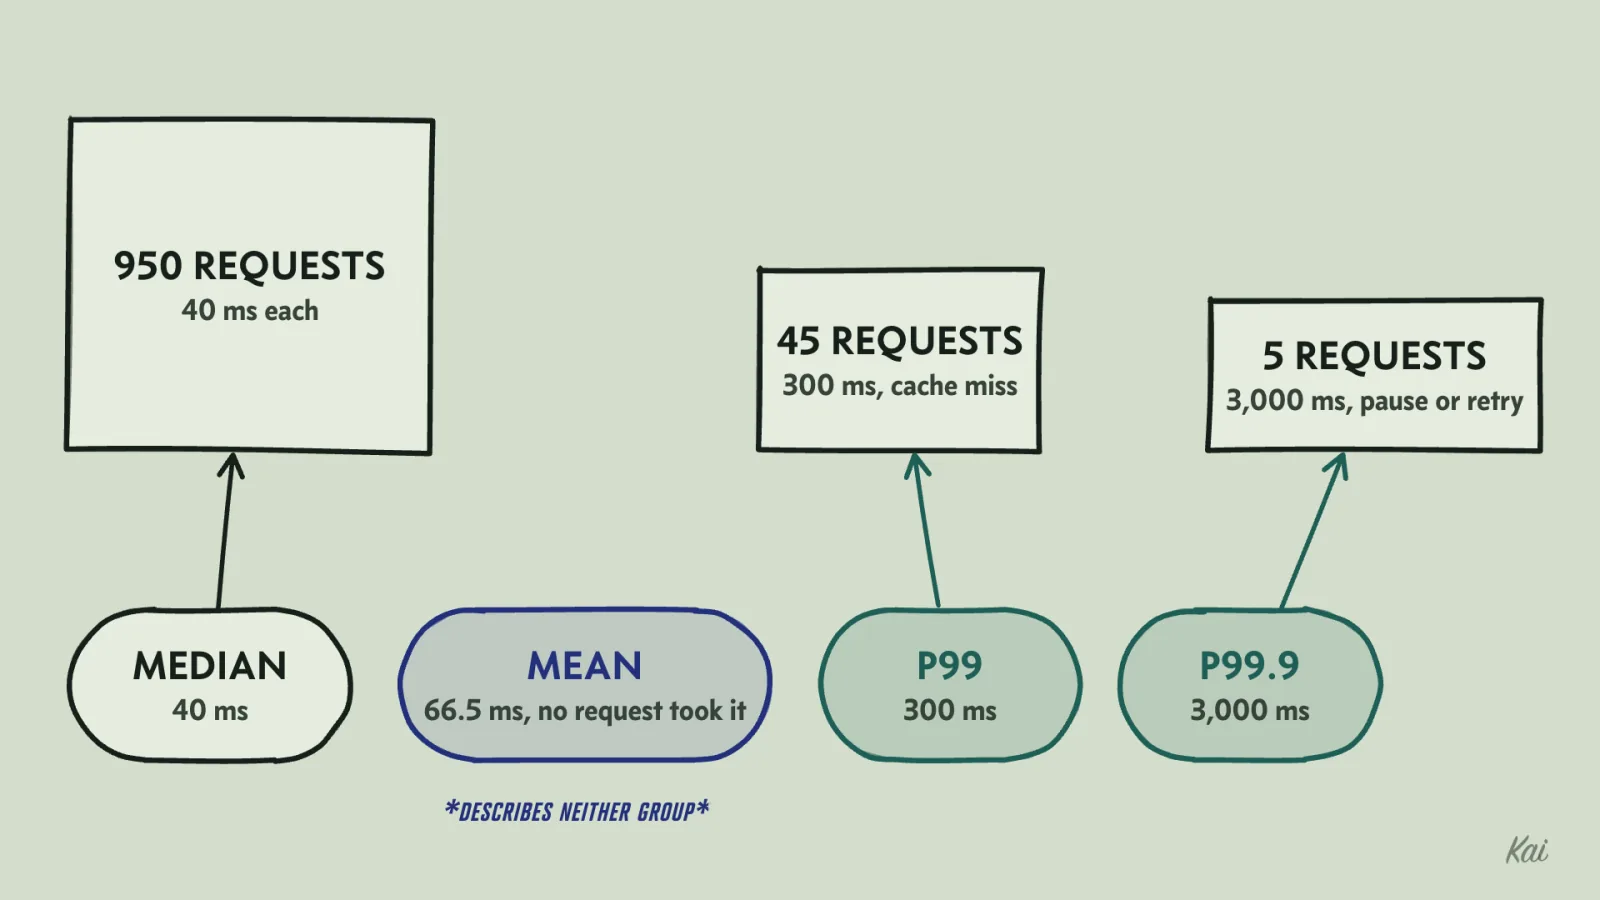
Latency distributions usually look like this: a large cluster of fast responses and a long tail of slow ones caused by cache misses, queueing, pauses and retries. The mean does react to the tail, but it blends the tail into one number with everything else, so you cannot tell from it whether five requests took three seconds or fifty took a little longer. The median does not see the tail at all. The high percentiles show the tail that the mean and median hide. So when an agent reports an improvement in average latency, ask for p50, p99 and p99.9 before and after. A change that makes the fast requests faster and the slow ones slower can lower the average and make the product worse.
Why the tail is the common case for a user
A user does not make one request. Loading a page, scrolling a feed or finishing a checkout can take dozens. If each request independently has a 1% chance of landing above the p99, the chance that a session of k requests hits at least one of them is 1 − 0.99^k.
For 10 requests that is about 10%. For 50 it is about 40%. For 100 it is about 63%. Past roughly 70 requests, more than half of sessions include at least one request slower than the p99. That is why the p99 describes something most users actually feel, even though its name suggests it only affects 1 in 100. The same arithmetic applies inside a system: a request that fans out to 100 servers and waits for all of them is slower than the p99 of a single server most of the time. Dean and Barroso's paper "The Tail at Scale" works through this in detail.
Independence is an assumption about causes
That calculation multiplied probabilities, and multiplying is only correct when the events are independent: one happening tells you nothing about whether the other happens. The same assumption sits under most reliability estimates, and it is where designs go wrong.
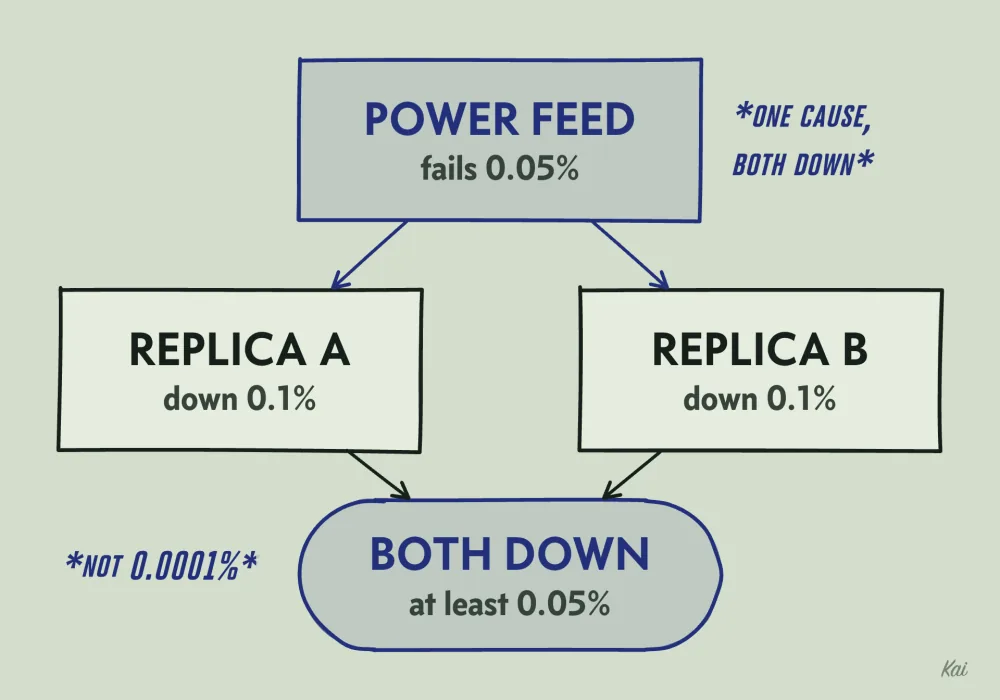
Suppose an agent proposes two database replicas, each unavailable 0.1% of the time, and reports that both will be down at once only 0.1% × 0.1% = 0.0001% of the time, about 30 seconds a year. That number assumes the replicas fail for unrelated reasons. If both sit in the same data center on the same power feed, a single power failure takes out both. If that feed fails 0.05% of the time, the pair is down at least 0.05% of the time, about 4.4 hours a year, at least 500 times the independent estimate. Shared causes include a data center, a power feed, a network switch, a bad deploy pushed to both, and a certificate that expires on both at the same minute.
The question that exposes the assumption: what single event would make both of these fail? If you can name one, the probabilities do not multiply, and the joint failure rate is at least the rate of that event.
How much a number moves by itself
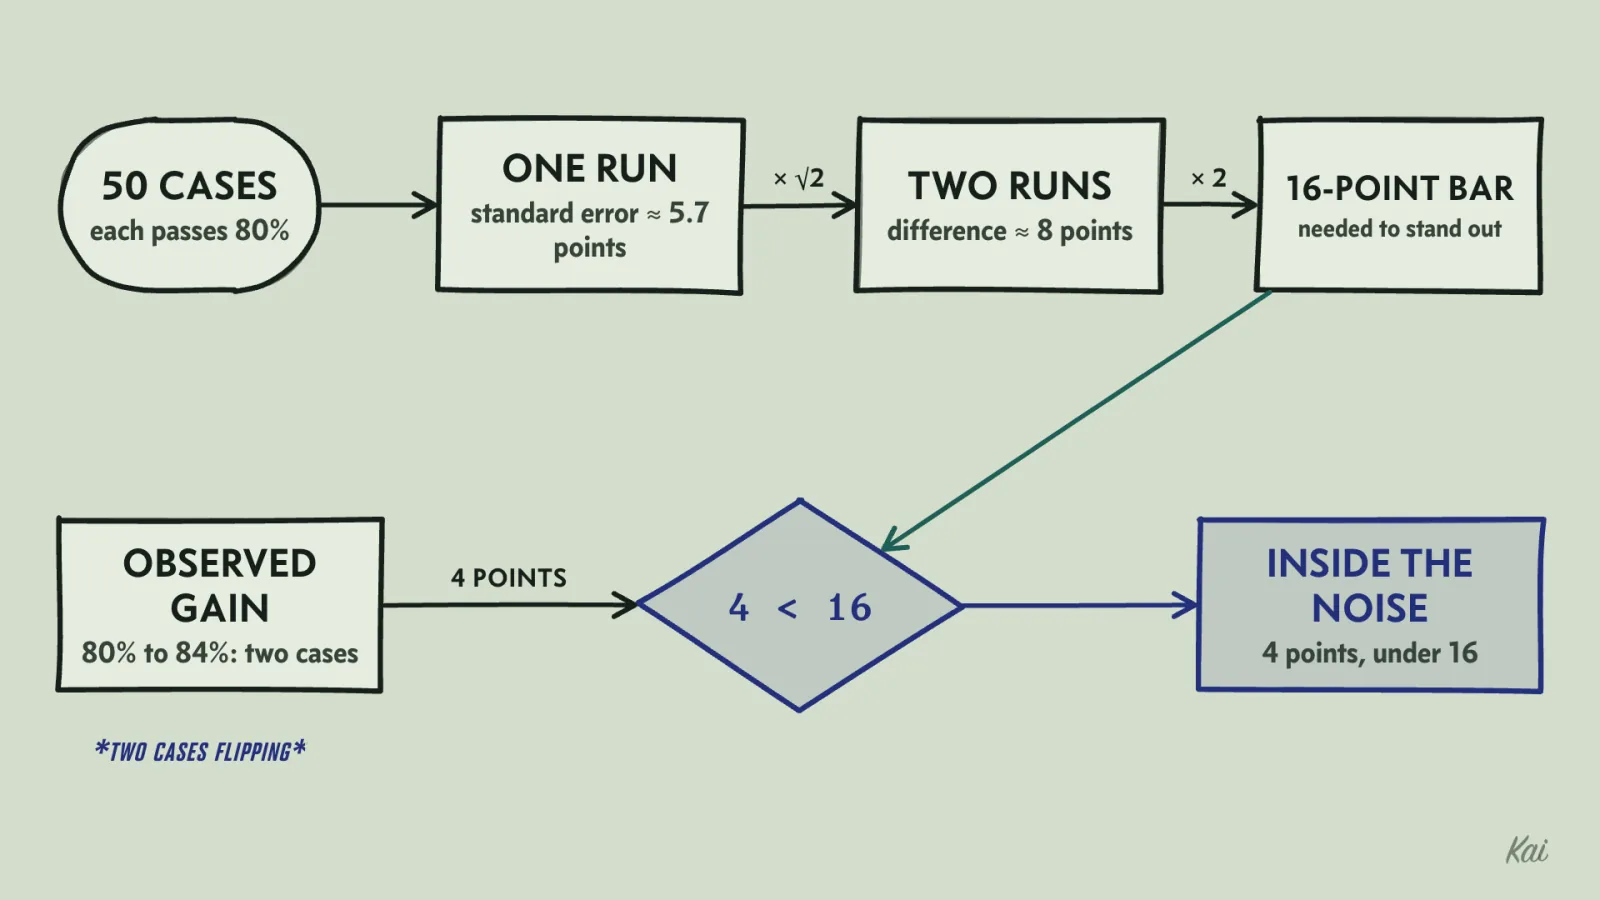
Go back to the eval. Treat each of the 50 cases as a pass-or-fail draw with an 80% chance of passing. The standard error of a pass rate, which measures how far it typically lands from the true rate, is
√(p × (1 − p) / n) = √(0.8 × 0.2 / 50) ≈ 0.057,
or about 5.7 percentage points. The difference between two independent runs has a standard error √2 times larger, about 8 points. A rough rule is that an observed difference needs to be around two standard errors of the difference before it stands out from noise. On 50 cases that is about 16 points: a measured gap smaller than that is a result chance produces often. The rule sets what a suite of this size can detect, and the true change can be smaller than that and still real. A 4-point gain is two cases flipping, well inside what chance produces.
The formula is a first estimate. Language models are also nondeterministic, so the same prompt on the same case can pass on one run and fail on the next. The direct way to measure that is to run the old version against itself. Run version A on the suite five times and look at the spread of the five pass rates. If A varies between 76% and 86% with nothing changed, a result of 84% for version B tells you nothing about B.
The playground simulates that with a 50-case suite in which every case passes 80% of the time and nothing ever changes. Its random numbers come from a fixed seed, so it prints the same result on every run.
// A small seeded random number generator (mulberry32).
function seeded(seed: number) {
  return () => {
    seed = (seed + 0x6d2b79f5) | 0;
    let t = Math.imul(seed ^ (seed >>> 15), 1 | seed);
    t = (t + Math.imul(t ^ (t >>> 7), 61 | t)) ^ t;
    return ((t ^ (t >>> 14)) >>> 0) / 4294967296;
  };
}
const random = seeded(7);

function passRate(cases: number, p: number): number {
  let passed = 0;
  for (let i = 0; i < cases; i++) if (random() < p) passed++;
  return Math.round((100 * passed) / cases);
}

const fiveRuns = Array.from({ length: 5 }, () => passRate(50, 0.8));
console.log("version A, five runs:", fiveRuns.map((r) => r + "%").join(", "));

const pairs = 20_000;
let gains = 0;
for (let i = 0; i < pairs; i++) if (passRate(50, 0.8) - passRate(50, 0.8) >= 4) gains++;
console.log(`one run of A beat another run of A by 4+ points in ${Math.round((100 * gains) / pairs)}% of pairs`);
Output
The same version scores anywhere from 72% to 84% across five runs. One run of it beats another by at least the agent's 4 points about a third of the time, with nothing changed.
To make a small difference detectable, you need more cases. For a 4-point gap near 80% to reach two standard errors, √(2 × 0.16 / n) has to be at most 0.02, which gives n of at least 800 cases per version. Even then, if the true improvement is exactly 4 points, the measured gap lands above or below 4 about equally often, so a real gain clears the bar only about half the time. Small improvements need large suites, repeated runs, or both. Comparing the two versions case by case on the same inputs helps, because the difficulty of each case then cancels out of the comparison.
A streak of greens is weak evidence
A flaky test is one that fails some fraction of runs for the same code. Suppose a test failed about one run in five before an agent's fix. After the fix it passes once, and the agent calls it fixed.
Ask how likely that green run would be if the fix did nothing. If the failure rate is still one in five, each run passes with probability 0.8. One green run happens 80% of the time. A streak of n green runs, assuming runs are independent, happens 0.8^n of the time:
| green runs in a row | chance of that streak if the failure rate is still 1 in 5 |
|---|---|
| 1 | 80% |
| 3 | 51% |
| 5 | 33% |
| 10 | 11% |
| 14 | 4.4% |
To get that chance below 5%, solve 0.8^n < 0.05. Take logarithms: n > ln(0.05) / ln(0.8) ≈ 13.4, so 14 consecutive green runs. If the failure rate had not changed, a streak of 14 would come up 4.4% of the time, so it counts as evidence against the old rate. The probability that the bug remains is a different number, and it also depends on how likely the fix was to work before you ran anything.
The number of runs has to be fixed in advance, for example the next 14, with every result recorded. If you keep rerunning until a streak of 14 shows up, the 4.4% no longer applies, because you gave chance many tries to produce it. The rarer the original failure, the longer the streak you need, because a test that failed 1 run in 50 produces long green streaks all by itself.
The playground tries both habits on 10,000 tests whose fix did nothing. One plan decides on 14 runs before it starts. The other reruns, up to 100 times, and stops as soon as it sees 14 greens in a row.
// A small seeded random number generator (mulberry32).
function seeded(seed: number) {
  return () => {
    seed = (seed + 0x6d2b79f5) | 0;
    let t = Math.imul(seed ^ (seed >>> 15), 1 | seed);
    t = (t + Math.imul(t ^ (t >>> 7), 61 | t)) ^ t;
    return ((t ^ (t >>> 14)) >>> 0) / 4294967296;
  };
}
const random = seeded(1);

// The fix did nothing: every run still fails one time in five.
const runIsGreen = () => random() >= 0.2;

function decideRunsFirst(): boolean {
  for (let i = 0; i < 14; i++) if (!runIsGreen()) return false;
  return true;
}

function rerunUntilStreak(): boolean {
  let streak = 0;
  for (let i = 0; i < 100; i++) {
    streak = runIsGreen() ? streak + 1 : 0;
    if (streak === 14) return true;
  }
  return false;
}

const tests = 10_000;
for (const plan of [decideRunsFirst, rerunUntilStreak]) {
  let calledFixed = 0;
  for (let i = 0; i < tests; i++) if (plan()) calledFixed++;
  console.log(`${plan.name}: ${((100 * calledFixed) / tests).toFixed(1)}% of still-broken tests called fixed`);
}
Output
Deciding first calls about 4% of the broken tests fixed, close to the 4.4% the arithmetic predicts. Rerunning until the streak appears calls about 60% of them fixed.
The independence assumption matters here too. If the test fails only when the machine is under load or when the clock is near midnight, fifty green runs in a row on a quiet laptop prove little. Rerun it under the conditions where it used to fail.
Rare events make accurate detectors noisy
Say a fraud detector catches 99% of fraudulent transactions and wrongly flags 1% of legitimate ones. It sounds 99% accurate. Now suppose 1 transaction in 1,000 is fraud, and run 100,000 transactions through it.
There are 100 fraudulent transactions, and the detector flags 99 of them. There are 99,900 legitimate ones, and it flags 1% of those, which is 999. So it raises 1,098 flags, and only 99 of them are fraud. When the detector fires, it is right about 9% of the time.
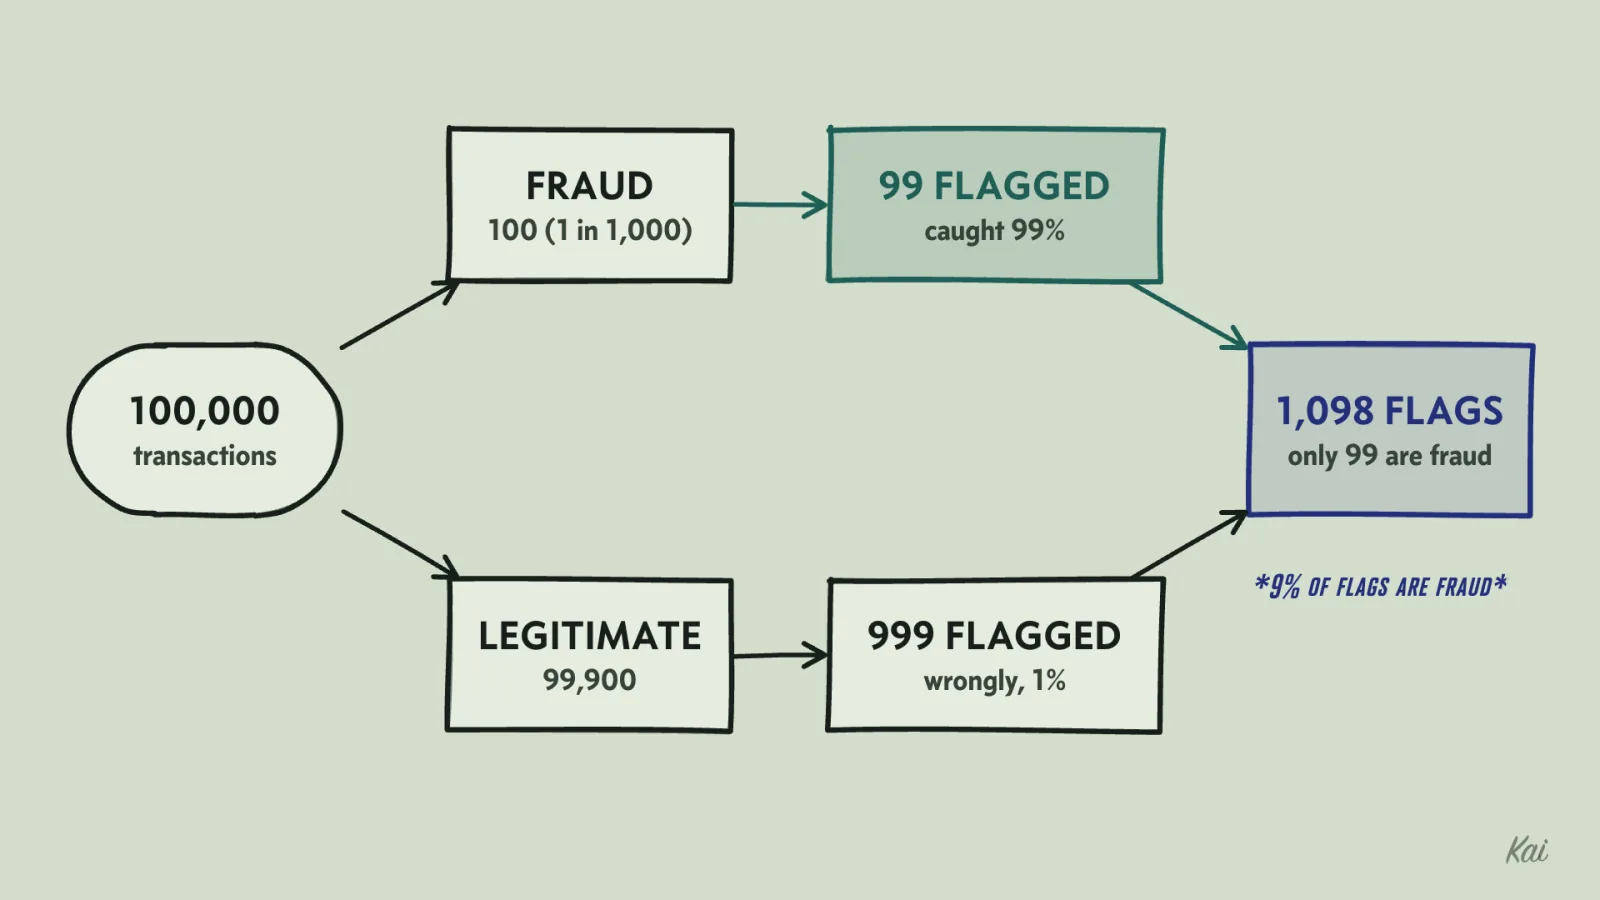
This is Bayes' rule at work. The chance that a flag is real depends on how accurate the detector is and on how common the thing it detects is, called the base rate. When the base rate is small, the false positives from the huge pool of normal cases outnumber the true positives from the tiny pool of real ones, even with a good detector. The same arithmetic applies to security alerts, anomaly detection, classifiers that screen content, and a monitor that pages you on a rare failure. When an agent quotes a detector's accuracy, ask for three numbers: the base rate b, the fraction s of real cases the detector catches, and the fraction f of legitimate cases it flags anyway. For N events, true alerts are N × b × s and false alerts are N × (1 − b) × f. Here that is 100,000 × 0.001 × 0.99 = 99 and 100,000 × 0.999 × 0.01 = 999, and 99 of 1,098 flags is the 9% above.
A measurement means something only when you know how much it would vary with nothing changed. Before accepting a difference, estimate or measure that variation and check that the difference is at least twice its own standard error.