
Let the Computer Choose the Inputs
An agent needs to store a list of tags in a single text column. It writes an encoder, a decoder and four example tests. ["urgent", "billing"] encodes to "urgent,billing" and decodes back, and a single tag round-trips. The coverage report says 100%.
export const encodeTags = (tags: string[]) => tags.join(",");
export const decodeTags = (s: string) => s.split(",");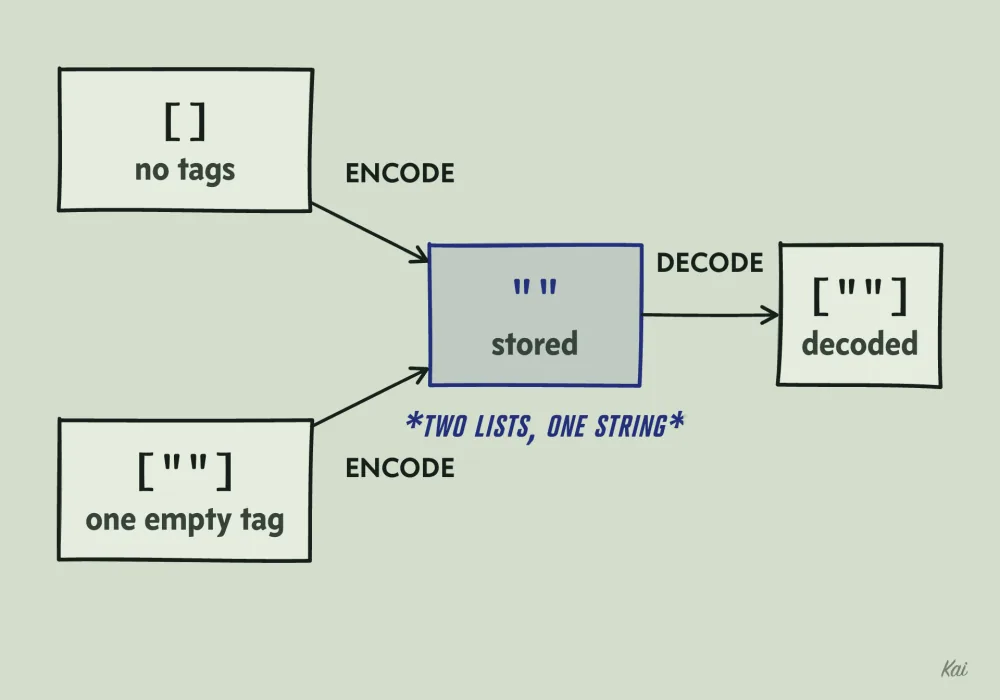
This code is broken three ways, and none of the four tests can see it. A tag containing a comma comes back as two tags. An empty list encodes to "", and "".split(",") returns [""], a list with one empty tag. And a list holding one empty tag also encodes to "", so two different lists produce the same stored string.
Every example test was chosen by someone, and whoever chose the inputs brought their blind spots along. An agent that writes tests after reading its own code tends to pick inputs the code already handles. One remedy is to let the computer generate the inputs. A second tool, mutation testing, measures whether a suite would notice a bug at all.
A property is a rule that holds for every input
An example test says: for this input, expect this output. A property says: for every input, this relationship holds. For an encoder and decoder the obvious property is the round trip. Decode what you encoded and you get back exactly what you started with.
A property-based testing library turns that sentence into a test. It generates random inputs, a hundred by default in both fast-check for JavaScript and Hypothesis for Python, checks the property on each one, and reports any input that breaks it.
import { test, expect } from "vitest";
import fc from "fast-check";

test("decoding an encoding gives back the original tags", () => {
  fc.assert(
    fc.property(fc.array(fc.string()), (tags) => {
      expect(decodeTags(encodeTags(tags))).toEqual(tags);
    }),
  );
});
fc.array(fc.string()) is a generator: a recipe for random lists of random strings, including empty lists and empty strings. Run this against the comma version and it fails within a few runs, reporting the empty list.
Patch the decoder to return [] for "" and run again. Now it fails with [""], a list holding one empty tag. No decoder can fix that one, because [] and [""] both encode to "" and the information is gone before the decoder sees it.
Shrinking makes a failure readable
The first random input that breaks a property is usually messy, such as a list of six strings full of punctuation. Reading it tells you little, so when a property fails the library shrinks the input. It tries smaller versions, such as a shorter list, a shorter string or a smaller number, and keeps any version that still fails. It stops when no smaller version fails and reports that one, though the search is best-effort and the result is not guaranteed to be the smallest possible.
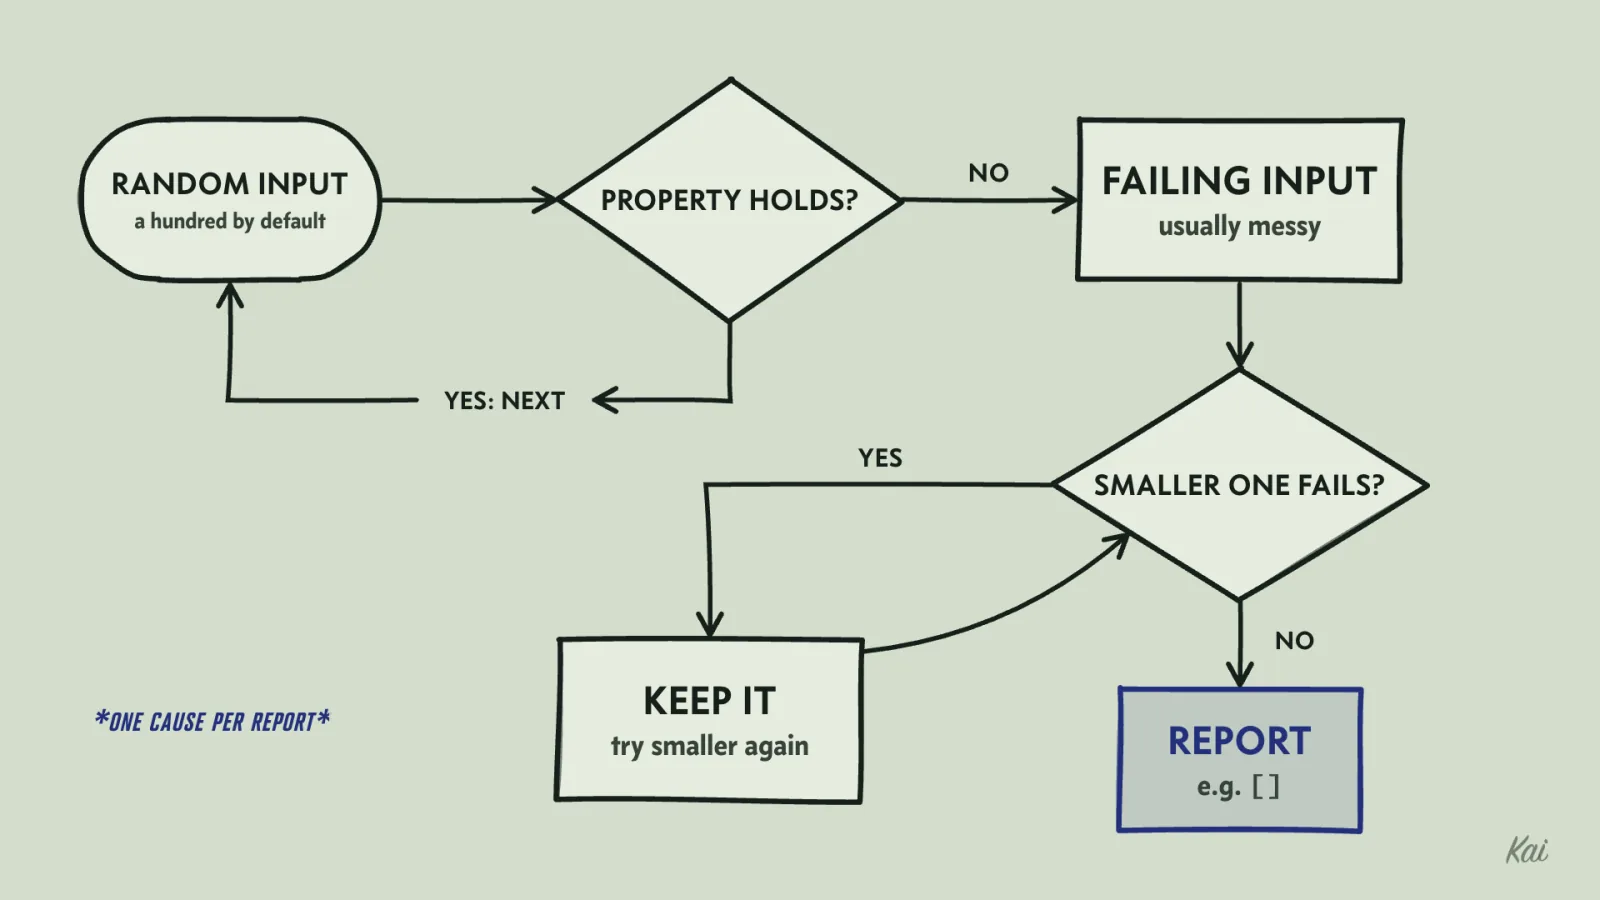
That is how you get [] and [""] instead of a wall of noise. Filter those two lists out of the generator and the next report is [","], a single tag that is just a comma. Each shrunk counterexample points at one cause.
The block below is a small property checker written from scratch, so you can watch all three reports happen. It draws random tag lists from a seeded generator, so every run draws the same lists. It stops at the first list that fails the round trip, then shrinks it by dropping one tag or one character at a time for as long as the smaller list still fails. Change the seed to another whole number from 1 to 2,147,483,646 and the first failing list changes, but the shrunk results stay the same. A seed outside that range can break the generator. Zero, for example, stays zero under multiplication, so every list it draws is empty.
const encodeTags = (tags: string[]) => tags.join(",");
const splitDecode = (s: string) => s.split(",");
const patchedDecode = (s: string) => (s === "" ? [] : s.split(","));
const show = (x: unknown) => JSON.stringify(x);

// A seeded random generator, so every run draws the same inputs.
// The seed must be a whole number from 1 to 2147483646.
let seed = 7;
const rand = (n: number) => (seed = (seed * 48271) % 2147483647) % n;
const randomTag = () => Array.from({ length: rand(4) }, () => "ab,"[rand(3)]).join("");
const randomTags = () => Array.from({ length: rand(5) }, randomTag);

// Smaller versions of an input: drop one tag, or drop one character from one tag.
function* smaller(tags: string[]) {
  for (let i = 0; i < tags.length; i++) yield tags.filter((_, j) => j !== i);
  for (let i = 0; i < tags.length; i++)
    for (let c = 0; c < tags[i].length; c++)
      yield tags.map((t, j) => (j === i ? t.slice(0, c) + t.slice(c + 1) : t));
}

function check(decode: (s: string) => string[], skip: string[][] = []) {
  const fails = (tags: string[]) =>
    !skip.some((x) => show(x) === show(tags)) && show(decode(encodeTags(tags))) !== show(tags);
  for (let run = 1; run <= 100; run++) {
    const tags = randomTags();
    if (!fails(tags)) continue;
    let small = tags;
    let shrinking = true;
    while (shrinking) {
      shrinking = false;
      for (const s of smaller(small)) {
        if (fails(s)) { small = s; shrinking = true; break; }
      }
    }
    return `run ${run} failed on ${show(tags)}, shrunk to ${show(small)}`;
  }
  return "100 runs passed";
}

console.log(check(splitDecode));
console.log(check(patchedDecode));
console.log(check(patchedDecode, [[], [""]]));
Output
The fix is a format that cannot be confused, where each tag is prefixed with its length:
export const encodeTags = (tags: string[]) =>
  tags.map((t) => `${t.length}:${t}`).join("");
// ["ab", "", "c,d"] becomes "2:ab0:3:c,d"
The round-trip property now passes. The decoder reads a number, a colon, and then exactly that many characters, so commas and empty tags carry no special meaning.
Malformed input and fuzzing
The round trip only feeds the decoder strings the encoder produced. In production the decoder reads whatever is in the column, including rows written by an older version, edited by hand, or corrupted. So here is a second property: for any string at all, the decoder returns a list or throws a clean decode error. It never crashes with some other error, and it always finishes.
Here is the agent's first length-prefix decoder:
export function decodeTags(s: string): string[] {
  const tags: string[] = [];
  let i = 0;
  while (i < s.length) {
    const colon = s.indexOf(":", i);
    const len = Number(s.slice(i, colon));
    tags.push(s.slice(colon + 1, colon + 1 + len));
    i = colon + 1 + len;
  }
  return tags;
}
Feed it a single space. There is no colon, so colon is -1. s.slice(0, -1) is the empty string, Number("") is 0, and i becomes -1 + 1 + 0, which is 0 again. The loop never moves forward, and the program hangs.
A hang is harder to catch than a crash, because a test that never finishes never reports. Fuzzers handle this by running each input under a time limit. In a property test, the simpler move is to make the loop prove it makes progress, which turns any would-be hang into an error the tool can report and shrink. The corrected decoder validates before it trusts:
export class DecodeError extends Error {}

export function decodeTags(s: string): string[] {
  const tags: string[] = [];
  let i = 0;
  while (i < s.length) {
    const colon = s.indexOf(":", i);
    const prefix = s.slice(i, colon);
    if (colon === -1 || !/^\d+$/.test(prefix)) throw new DecodeError(`bad length prefix at ${i}`);
    const end = colon + 1 + Number(prefix);
    if (end > s.length) throw new DecodeError(`tag at ${i} runs past the end`);
    tags.push(s.slice(colon + 1, end));
    i = end; // end > i, so every pass moves forward
  }
  return tags;
}

test("any string decodes or throws DecodeError", () => {
  fc.assert(
    fc.property(fc.string({ unit: "binary" }), (s) => {
      try {
        decodeTags(s);
      } catch (e) {
        if (!(e instanceof DecodeError)) throw e;
      }
    }),
  );
});
The unit: "binary" option makes the generator draw from the whole range of code points, including strings no encoder would ever write. fast-check's default strings are ASCII only and would miss most malformed input.
A dedicated fuzzer takes the same idea further. Coverage-guided fuzzers such as libFuzzer, AFL and Go's built-in go test -fuzz watch which code paths each input reaches and mutate the inputs that reach new ones. They run for minutes or hours and are the standard tool for parsers that read untrusted data. A property test runs a hundred inputs in milliseconds on every commit, so the two work well together.
The generator decides what you can find
Suppose the agent writes the length prefix as [...t].length to "handle Unicode," which counts code points instead of JavaScript's UTF-16 code units. The decoder still slices by code units. A character outside the Basic Multilingual Plane, such as most emoji, is one code point and two code units. The prefix says 1, so the decoder takes half the character and then throws on the other half.
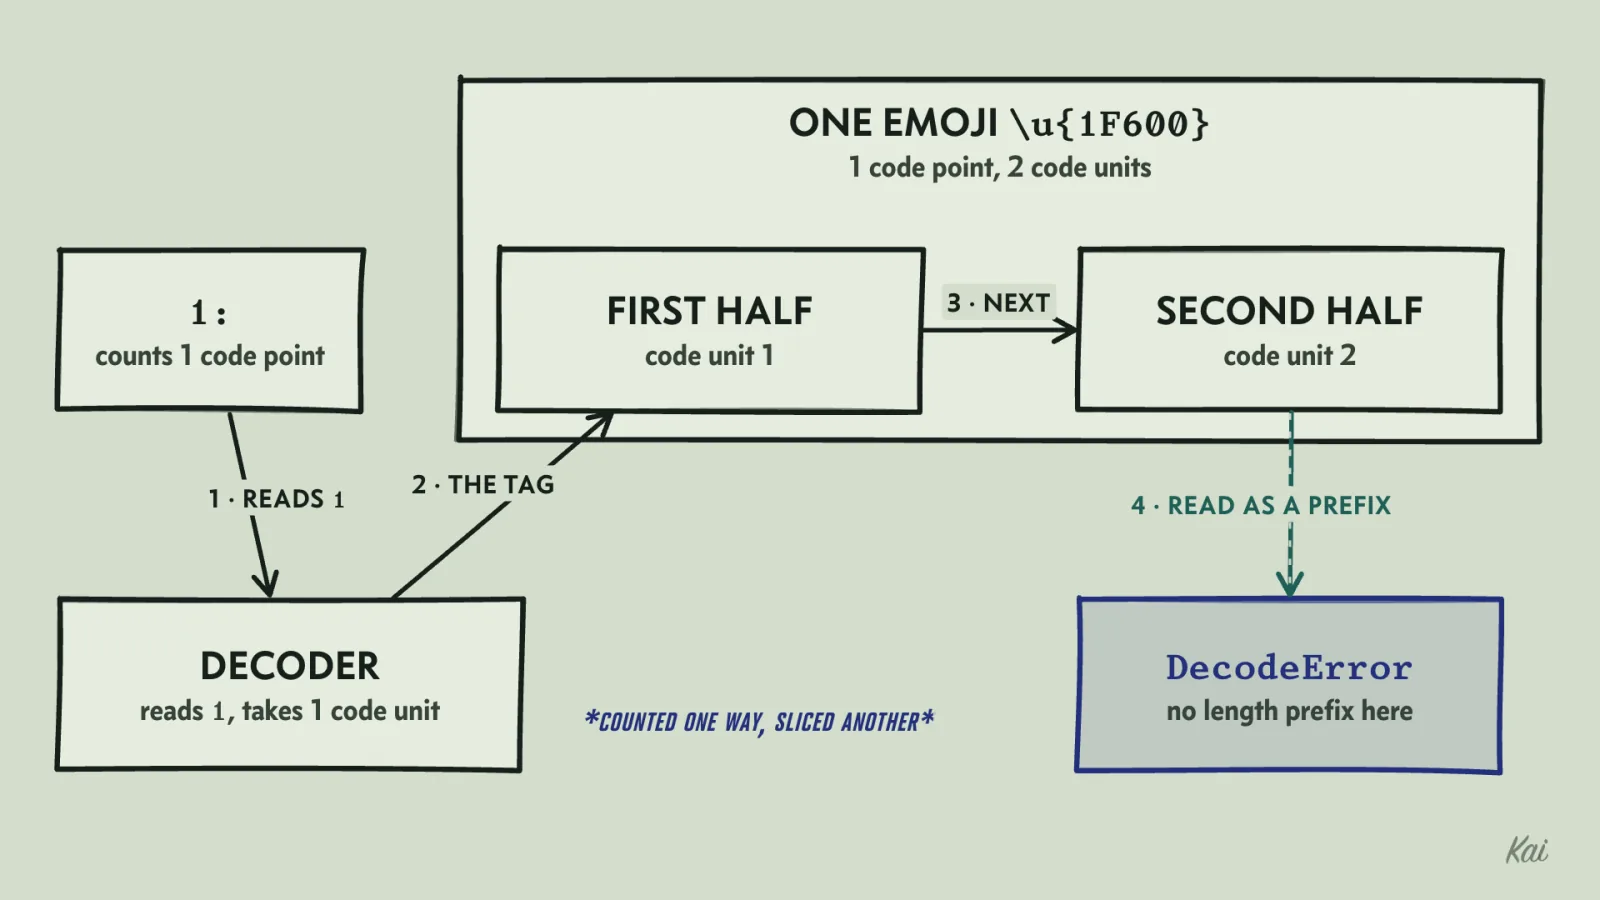
The round-trip property from the start of the lesson does not catch this. In fast-check 4, fc.string() produces ASCII characters by default, so it never generates an emoji. Give the round-trip test the generator the fuzz property above uses, fc.string({ unit: "binary" }), and it starts failing. That generator draws from the whole range of code points, and the counterexample shrinks to a single character such as U+10000, which is one code point and two code units.
Here are the two encoders side by side, each fed one ASCII list and one emoji, through the validating decoder from the previous section. The ASCII list cannot tell them apart.
class DecodeError extends Error {}
function decodeTags(s: string): string[] {
  const tags: string[] = [];
  let i = 0;
  while (i < s.length) {
    const colon = s.indexOf(":", i);
    const prefix = s.slice(i, colon);
    if (colon === -1 || !/^\d+$/.test(prefix)) throw new DecodeError(`bad length prefix at ${i}`);
    const end = colon + 1 + Number(prefix);
    if (end > s.length) throw new DecodeError(`tag at ${i} runs past the end`);
    tags.push(s.slice(colon + 1, end));
    i = end;
  }
  return tags;
}

const byCodePoints = (tags: string[]) => tags.map((t) => `${[...t].length}:${t}`).join("");
const byCodeUnits = (tags: string[]) => tags.map((t) => `${t.length}:${t}`).join("");

const emoji = "\u{1F600}";
console.log("code points:", [...emoji].length, " code units:", emoji.length);

for (const encode of [byCodePoints, byCodeUnits]) {
  for (const tags of [["a,b", ""], [emoji]]) {
    try {
      console.log(encode.name, JSON.stringify(tags), "->", JSON.stringify(decodeTags(encode(tags))));
    } catch (e) {
      console.log(encode.name, JSON.stringify(tags), "->", `DecodeError: ${(e as Error).message}`);
    }
  }
}
Output
The code-point encoder writes 1: in front of the emoji. The decoder takes one code unit, the first half of the emoji, and then finds the second half where it expects the next length prefix.
A property only checks the inputs its generator can produce. When you read a property test, read the generator and ask what it can never produce: empty values, very large numbers, characters outside ASCII, or combining characters. The letter "é" can be one code point or an "e" followed by a combining accent, and the two look identical on screen. If the generator cannot produce the case, the test is silent about it.
Common property shapes
Finding a property is the hard part. A few shapes cover most code:
- Round trip:
decode(encode(x))equalsx. Fits serializers, parsers paired with printers, and compression. - Idempotence: applying the function twice gives the same result as applying it once. Fits normalizers, formatters and deduplication.
- Output invariants: something is true of every output, whatever the input. A sorted list is in order and has the same length as the input; a sanitized string contains only allowed characters.
- Conservation: a quantity survives the operation. A transfer between two accounts leaves the total unchanged.
- Reference comparison: a fast implementation gives the same answers as a slow, obviously correct one.
Each shape states a requirement without naming a single expected output, which is why it can be checked on inputs that appear in no example test. When a property fails, the fault can be in the code or in the property. A wrong property is worth finding too, because it means the requirement was misunderstood.
Coverage says what ran
Go back to the agent's original suite. One of its tests looked like this:
test("round trips tags", () => {
  expect(decodeTags(encodeTags(["a", "b"]))).toBeTruthy();
});
It executes every line of both functions, so line coverage is 100%. Coverage measures exactly that: which lines, or with branch coverage which branches, ran during the tests. It says nothing about whether any assertion looked at the result. Low coverage proves some code is untested, and high coverage proves only that the code ran.
Mutation testing measures whether tests notice
Mutation testing asks the question coverage cannot: the tool makes one small change to your code, called a mutant, such as turning < into <=, + 1 into - 1, or a function's return value into an empty array. Then it runs the tests. If some test fails, the mutant is killed. If every test passes, the mutant survived, and you have found a change to the code that no test can see.
Against that test, the mutant that makes decodeTags return [] survives, because an empty array is truthy in JavaScript. The fix is a stronger assertion, toEqual(["a", "b"]), which kills it. Tools include Stryker for JavaScript and TypeScript, PIT for Java, mutmut for Python and cargo-mutants for Rust. Mutation testing runs the suite once per mutant, so teams usually run it on the files a change touched.
The block below runs four mutants of the validating decoder against the weak test and the strong one. Each mutant is written into the code behind a switch, and Stryker does much the same: it builds every mutant into one copy of the code and turns on one per test run.
class DecodeError extends Error {}
const encodeTags = (tags: string[]) => tags.map((t) => `${t.length}:${t}`).join("");

// The decoder with four mutants built in; `mutant` switches one on.
function decodeTags(s: string, mutant = "none"): string[] {
  if (mutant === "return []") return [];
  const tags: string[] = [];
  let i = 0;
  while (mutant === "< to <=" ? i <= s.length : mutant === "< to !==" ? i !== s.length : i < s.length) {
    const colon = s.indexOf(":", i);
    const prefix = s.slice(i, colon);
    if (colon === -1 || !/^\d+$/.test(prefix)) throw new DecodeError(`bad length prefix at ${i}`);
    const end = colon + (mutant === "+ 1 to - 1" ? -1 : 1) + Number(prefix);
    if (end > s.length) throw new DecodeError(`tag at ${i} runs past the end`);
    tags.push(s.slice(colon + 1, end));
    i = end;
  }
  return tags;
}

// A test passes if it returns true without throwing.
const passes = (test: () => boolean) => { try { return test(); } catch { return false; } };
const weak = (m: string) => passes(() => Boolean(decodeTags(encodeTags(["a", "b"]), m)));
const strong = (m: string) => passes(() => JSON.stringify(decodeTags(encodeTags(["a", "b"]), m)) === '["a","b"]');

for (const m of ["return []", "< to <=", "+ 1 to - 1", "< to !=="]) {
  const verdict = (t: (m: string) => boolean) => (t(m) ? "survived" : "killed");
  console.log(`${m.padEnd(11)} weak test: ${verdict(weak).padEnd(8)}  strong test: ${verdict(strong)}`);
}
Output
The weak test misses the return [] mutant and the strong test kills it. The other two broken mutants make the decoder throw, so even the weak test catches them. The last one survives both tests because no input makes it behave differently from the original.
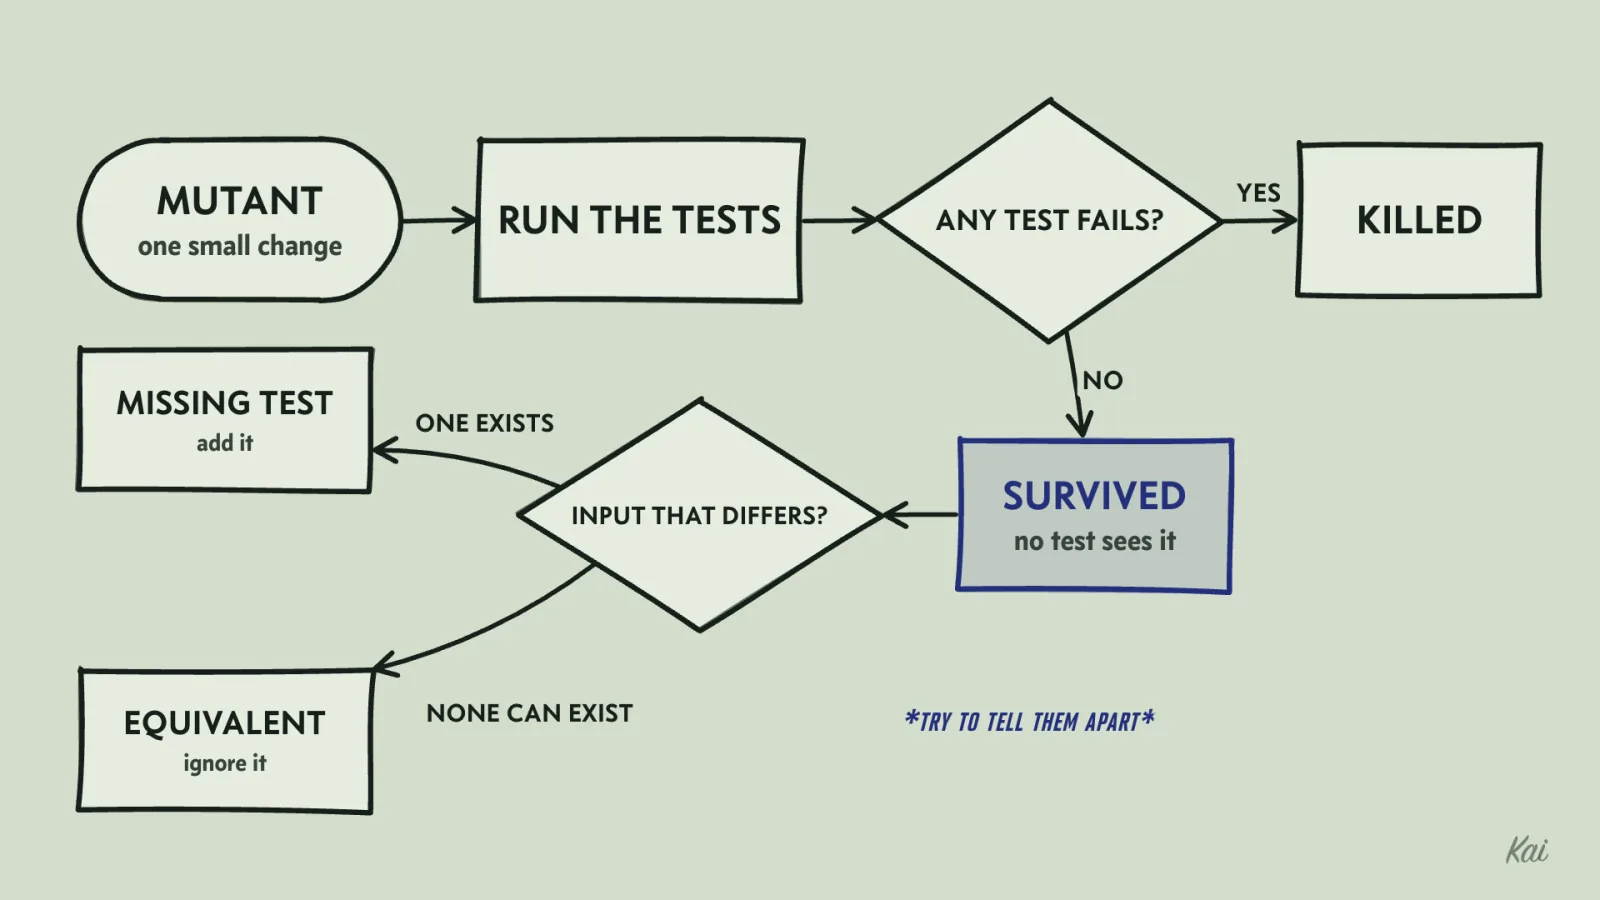
Read each surviving mutant and decide which kind it is. Most mark an assertion that is missing or too weak. Some are equivalent mutants, changes that cannot alter behavior. In for (let i = 0; i < tags.length; i++), changing < to != is one: i starts at 0 and rises by 1, so it reaches the array length exactly and never passes it. The decoder's while loop is another. Every pass sets i to end, and the decoder throws before end can pass s.length, so i !== s.length stops at the same moment i < s.length does.
To tell the two kinds apart, try to write an input on which the mutant and the original give different results. If one exists, it is a missing test, so add it. If none can exist, ignore the mutant.