
Reading Code as Logic
An agent adds a shipping rule to your checkout. The ticket said: "Orders of $50 or more ship free, as long as the address is in the country." The agent wrote this:
if (order.total > 50 && !order.address.isDomestic) {
  order.shipping = 0;
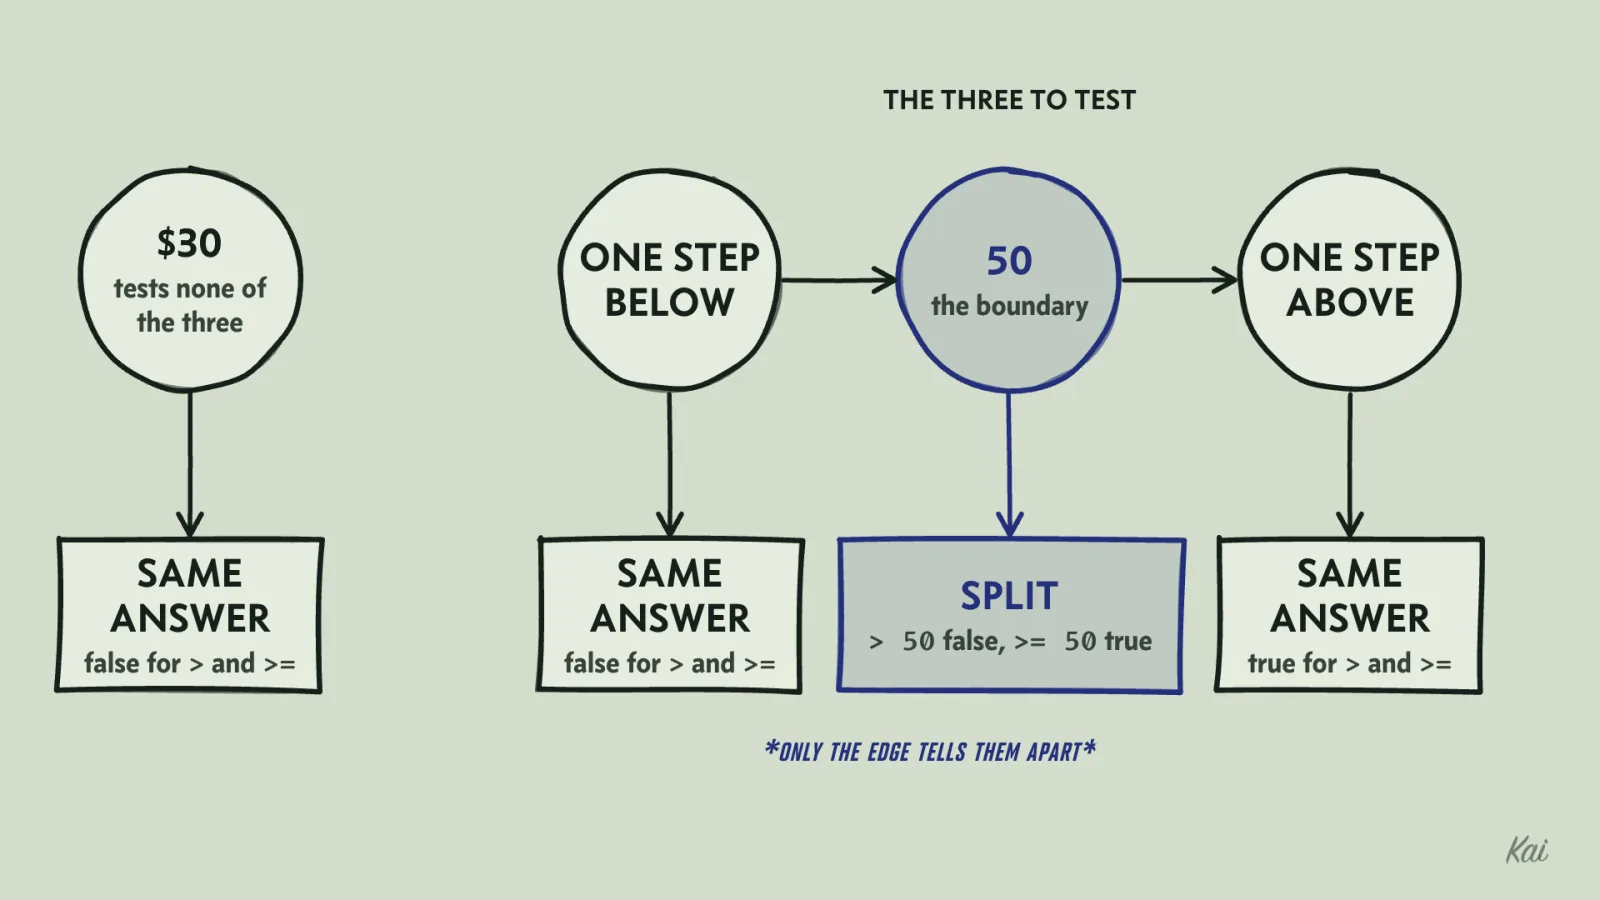
}That one line has two mistakes. An order of exactly $50 still pays for shipping, because > leaves 50 out. And the ! is in the wrong place, so free shipping goes only to foreign addresses, the opposite of the rule. The test suite passed. Its only case was a $30 order, which pays shipping under the right rule and under this one too.
Mistakes like these are logic mistakes, and logic is a small, exact subject. A condition in code is a formula in propositional logic. A database relationship is a relation in set theory. A tangle of imports or startup dependencies is a directed graph. Agents write all three fluently, and they get each one slightly wrong in ways a few hand-picked test cases will not reveal.
A condition is a formula you can check row by row
A condition combines true-or-false values with three operators: and, or, not. Given the inputs, the answer is fully determined, so you can list every possible input and the result. That list is a truth table. With two inputs there are four rows.
Here is the table for what the ticket asked, with the two inputs "total is at least 50" and "address is domestic":
| total ≥ 50 | domestic | free shipping |
|---|---|---|
| false | false | false |
| false | true | false |
| true | false | false |
| true | true | true |
The agent's code is true in one situation only: a foreign address with a total above 50. That sits in the third row, where the rule says false. In the fourth row, where the rule says true, the code says false. Write the code's column next to the rule's and the disagreement is plain to see.
The number of rows doubles with every input: three booleans give 8 rows, ten give 1,024, twenty give about a million. This is the counting argument for why tests alone cannot confirm a condition over many flags. At some size you have to stop enumerating and reason about the shape of the condition.
Boundaries: which side does the edge fall on
A comparison on a number splits the number line in two. The only question is which side the boundary value lands on, and English is sloppy about it. "At least 50" and "50 or more" mean >= 50. "More than 50" and "over 50" mean > 50. "Up to 50" and "before the deadline" are ambiguous, and the right move is to ask what happens at exactly 50 or at exactly the deadline.
To check a boundary, test three values: the boundary itself, one step below, and one step above. The $30 test in the opening example checked none of them.
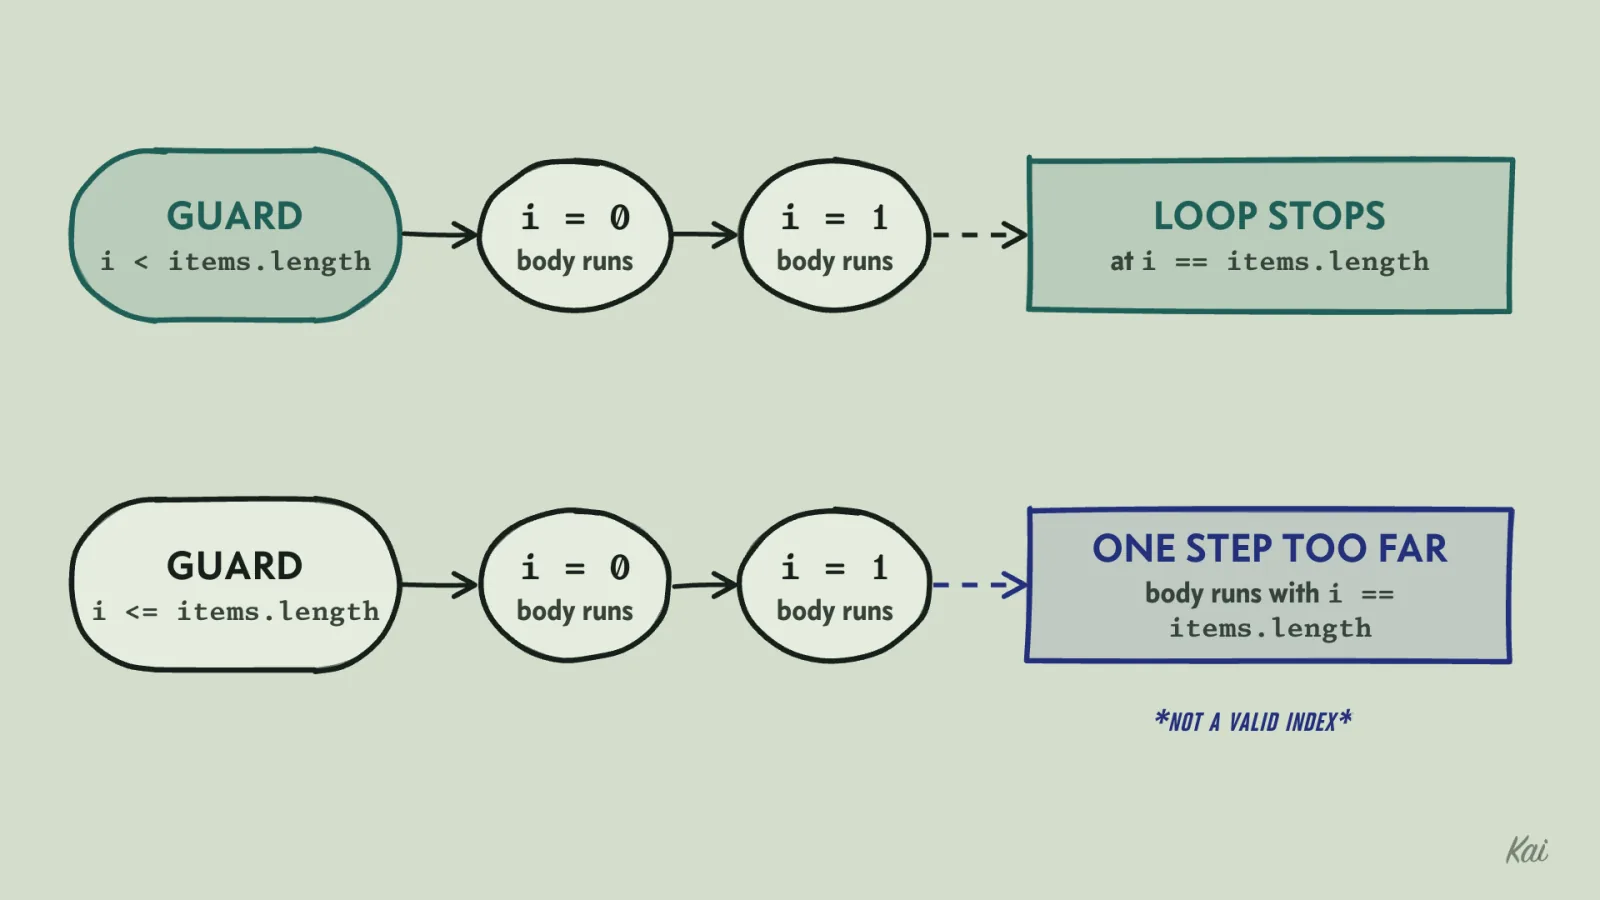
Loops have boundaries too. for (let i = 0; i <= items.length; i++) runs one step too far and reads past the end of the array. The way to check a loop is to name its invariant, a statement that is true each time the loop tests its condition. For a loop over an array it is 0 <= i <= items.length: i starts at 0, each step adds 1, and the test stops the loop once i reaches the length. The guard i < items.length then makes i a valid index inside the body. If the invariant holds before the first test, and each iteration keeps it true, then it holds at every test. That is proof by induction, and it is the same argument you use informally when you convince yourself a loop is right. With the guard i <= items.length, the body runs once with i == items.length, which is not a valid index, so the loop is wrong. An empty array shows the same thing: the invariant holds with i == 0, and only the correct guard keeps the body from running.
A proof is only as good as its assumptions. Joshua Bloch's essay on broken binary searches describes a search whose correctness argument was sound on paper. The code computed the midpoint as (low + high) / 2, and when the array got large enough, low + high overflowed a 32-bit integer. The proof had assumed integers never overflow, and that assumption was false for the Java int the code actually used.
Negation and De Morgan's laws
Negating a compound statement is an easy place to go wrong. Two rules, called De Morgan's laws, tell you how to do it:
!(A && B)is the same as!A || !B!(A || B)is the same as!A && !B
In words: "not both" means "at least one is missing", and "neither" means "each one is missing". When you move a ! inside parentheses, every && becomes || and every || becomes &&.
This comes up whenever a rule is stated as who is allowed but the code is written as who is denied. Suppose the rule is "a user may post if they are verified and not banned". The allow condition is verified && !banned. The deny condition is its negation:
// allow: verified && !banned
// deny:  !(verified && !banned)  ===  !verified || banned
if (!user.verified || user.banned) {
  return deny();
}
A common wrong version is if (!user.verified && user.banned) deny(). It denies only users who are both unverified and banned. An unverified user who has never been banned gets through. The question that exposes it: write the allow rule, negate the whole thing, push the ! inward with De Morgan, and compare the result with the code.
Precedence: where the parentheses really are
In C, Java, JavaScript, Go and most other languages, && binds tighter than ||, the way multiplication binds tighter than addition. Python's and and or follow the same order. So a || b && c means a || (b && c), whatever the spacing or the comment above it suggests.
Consider an event system where the intent is "staff or members may enter, but only while the event is open":
if (user.isStaff || user.isMember && event.isOpen) {
  allowEntry();
}
This parses as isStaff || (isMember && isOpen), so staff can enter a closed event. When a condition mixes && and ||, rewrite it with explicit parentheses before you judge it. Then compare it with the intended rule on every combination of inputs. With three booleans you can do that in a few lines:
const intended = (staff: boolean, member: boolean, open: boolean) => (staff || member) && open;
const written = (staff: boolean, member: boolean, open: boolean) => staff || (member && open);

for (const staff of [false, true])
  for (const member of [false, true])
    for (const open of [false, true])
      if (intended(staff, member, open) !== written(staff, member, open))
        console.log("staff:", staff, "member:", member, "open:", open);
Output
It prints two rows, both with staff: true and open: false. Those two rows are exactly the users the code admits and the rule excludes. The same loop works for any condition you are unsure about: encode the comment as one function, the code as another, and print the disagreements.
Saying "every" and "some" precisely
Rules about permissions and data usually contain a hidden quantifier. "Every admin can see every document" is a for-all statement. "Some reviewer has approved this change" is a there-exists statement. They behave differently. One example confirms a there-exists claim and can only refute a for-all claim. To negate "every document is visible to admins" you need a single document that some admin cannot see.
This matters when you read an agent's test. A test that logs in as one admin and opens one document shows that some admin can see some document. The comment above the code claims something much stronger. When the rule says "every", ask how the cases the test skipped are covered. The usual answers are a property-based test that generates many users and documents, or an argument from the structure of the code.
Relationships: ask the question in both directions
A relation is a set of pairs: (user, team), (order, tag), (student, course). The kind of relation is set by two questions. For one X, how many Y can there be? For one Y, how many X? If both answers are "one", it is one-to-one. If one side is "many", it is one-to-many. If both are "many", it is many-to-many, and a relational database needs a separate table of pairs to store it.
Agents often ask only one of the two questions. A schema with a team_id column on users says each user belongs to one team. If a user can in fact join two teams, the column can hold only one of them, and the second membership either overwrites the first or leads someone to create a duplicate user row. The correct shape is a team_memberships table with one row per (user, team) pair.
The opposite mistake shows up in queries. Suppose orders can carry several tags, stored in order_tags, and an agent computes revenue like this:
SELECT SUM(o.total)
FROM orders o
JOIN order_tags t ON t.order_id = o.id;
Take two orders. Order 1 is $100 with the tags gift and rush. Order 2 is $40 with no tags. True revenue is $140. The join produces one row per (order, tag) pair, so order 1 appears twice and order 2, which has no pairs, disappears. The query returns $200. It is wrong in both directions at once, and the answer looks believable.
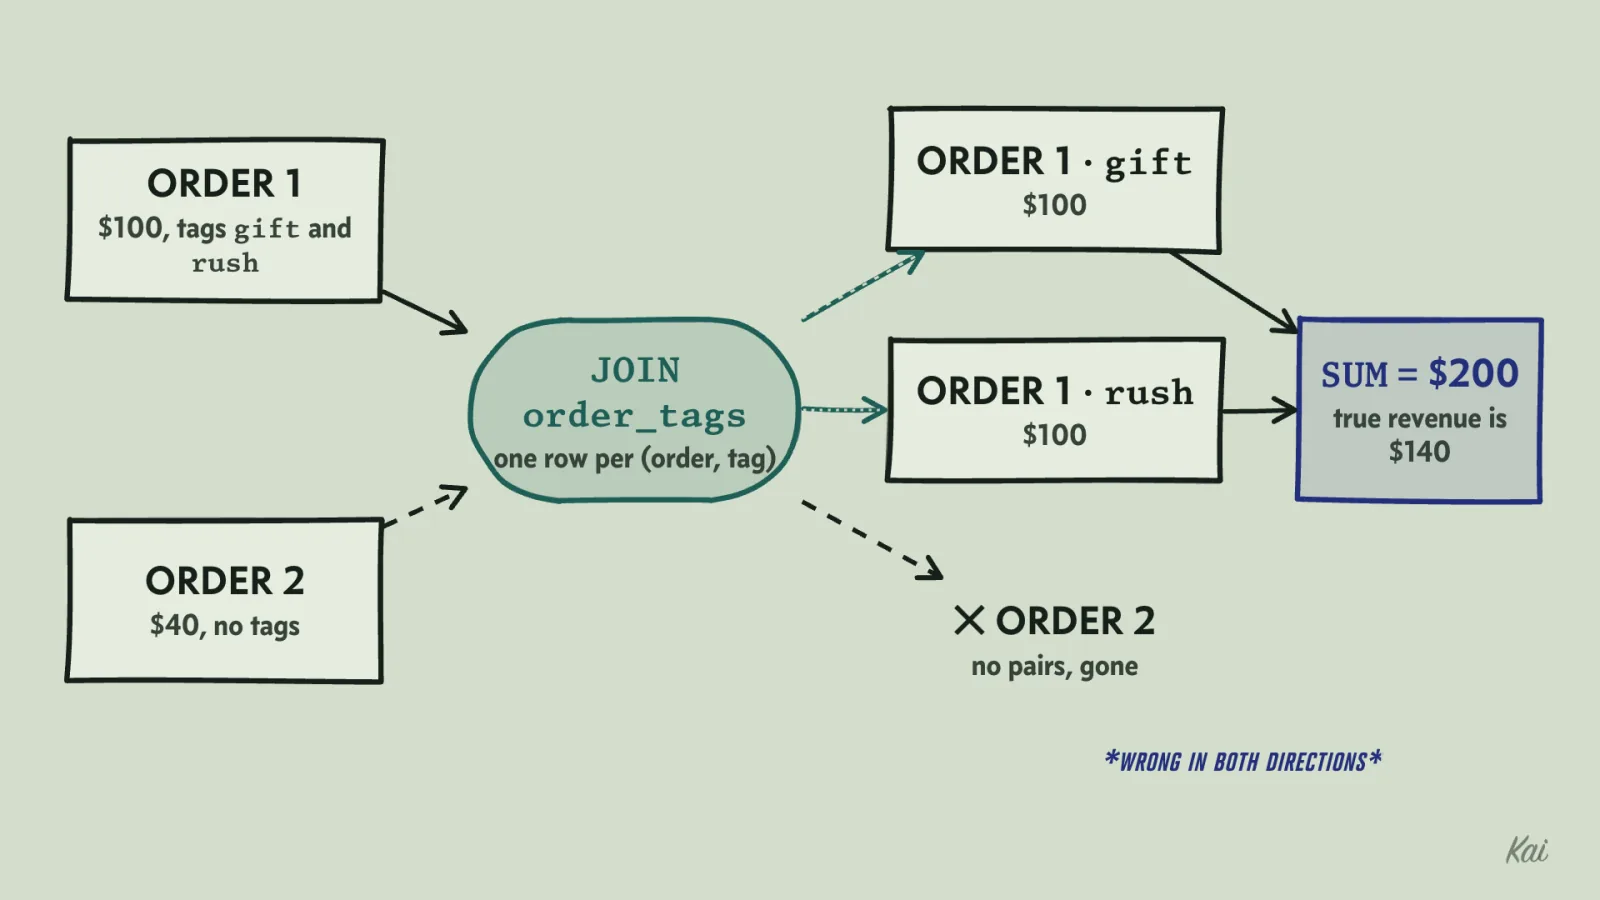
The question that catches this: after the join, is there still exactly one row per order? Compare the count of rows per order ID before and after the join, because equal totals can hide damage. The join above returns two rows for two orders, one order twice and the other not at all. If the join fans out, aggregate before joining or use EXISTS to test for a tag without multiplying rows.
Here are the same two orders in a database you can run. The first query is the agent's, the second is the row-count check, and the last two are the repairs.
CREATE TABLE orders (id INTEGER PRIMARY KEY, total INTEGER NOT NULL);
CREATE TABLE order_tags (order_id INTEGER NOT NULL REFERENCES orders(id), tag TEXT NOT NULL);
INSERT INTO orders VALUES (1, 100), (2, 40);
INSERT INTO order_tags VALUES (1, 'gift'), (1, 'rush');

-- The agent's query: one row per (order, tag) pair.
SELECT SUM(o.total) AS revenue
FROM orders o
JOIN order_tags t ON t.order_id = o.id;

-- The check: how many rows each order becomes in that join.
SELECT o.id, COUNT(t.order_id) AS rows_after_join
FROM orders o
LEFT JOIN order_tags t ON t.order_id = o.id
GROUP BY o.id;

-- Revenue is a fact about orders, so sum the orders table alone.
SELECT SUM(total) AS revenue FROM orders;

-- Revenue from tagged orders: EXISTS tests for a tag without multiplying rows.
SELECT SUM(o.total) AS tagged_revenue
FROM orders o
WHERE EXISTS (SELECT 1 FROM order_tags t WHERE t.order_id = o.id);
Output
The second result shows the damage directly: order 1 became two rows and order 2 became none. Order 1 is the only tagged order, so the tagged revenue is $100.
Dependencies are graphs
Modules import modules. Services wait for other services at startup. Packages depend on packages. Roles inherit permissions from other roles. Each of these is a directed graph: a set of nodes and arrows between them, where an arrow from B to A means A needs B, so arrows point from what is needed to what needs it.
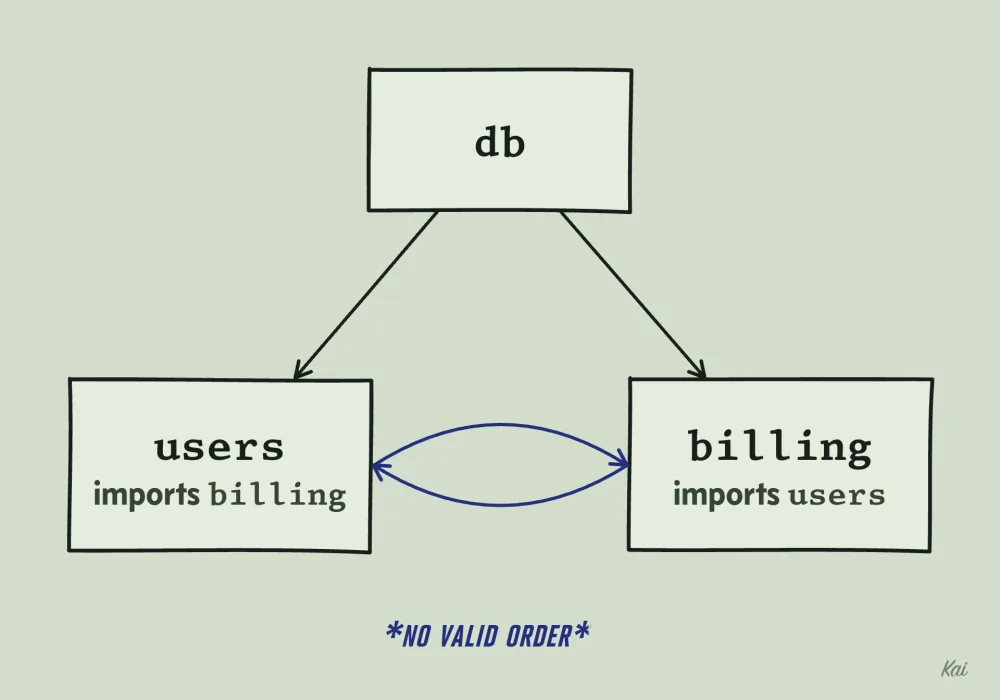
A build order or startup order is a topological order, a list in which every arrow points forward, so every node comes after everything it depends on. Such an order exists exactly when the graph has no cycle. When an agent splits a codebase so that billing imports users to look up a customer and users imports billing to show a plan on the profile page, it has created a cycle. What happens next depends on the runtime. Go refuses to compile an import cycle. Node.js with CommonJS modules hands one of the two a partly filled exports object, so a value is undefined at startup only when a certain file happens to load first. Two services that each wait for the other to report healthy never start.
The standard way to find an order, or prove there is none, is Kahn's algorithm. Count how many dependencies each node is still waiting on. Repeatedly take a node that is waiting on nothing, emit it, and reduce the count of everything that depends on it. If nodes remain when you run out of ready ones, they are in a cycle or depend on one.
// deps[x] lists what x depends on; every node must appear as a key.
function buildOrder(deps: Map<string, string[]>): string[] {
  const waiting = new Map<string, number>();
  const dependents = new Map<string, string[]>(); // the arrows leaving each node
  for (const [node, needs] of deps) {
    waiting.set(node, needs.length);
    for (const d of needs) dependents.set(d, [...(dependents.get(d) ?? []), node]);
  }
  const ready = [...deps.keys()].filter((n) => waiting.get(n) === 0);
  const order: string[] = [];
  while (ready.length > 0) {
    const n = ready.pop()!;
    order.push(n);
    for (const m of dependents.get(n) ?? []) {
      waiting.set(m, waiting.get(m)! - 1);
      if (waiting.get(m) === 0) ready.push(m);
    }
  }
  const blocked = [...deps.keys()].filter((n) => waiting.get(n)! > 0);
  if (blocked.length > 0) throw new Error(`blocked by a cycle: ${blocked.join(", ")}`);
  return order;
}

console.log(buildOrder(new Map([["db", []], ["users", ["db"]], ["billing", ["db", "users"]]])));
// [ "db", "users", "billing" ]

try {
  buildOrder(new Map([["db", []], ["users", ["db", "billing"]], ["billing", ["db", "users"]]]));
} catch (e) {
  console.log((e as Error).message);
}
// blocked by a cycle: users, billing
Output
It visits each node and each arrow once, so its cost grows linearly with the size of the graph.
Permission inheritance is a different graph question. "Can this user delete invoices?" means "is there a path from the user's role to a role that grants delete?" That is reachability, answered by breadth-first or depth-first search. The bug to look for is a recursive function that walks up a role's parents without recording which roles it has already visited. It works on every tree, then loops forever the first time someone configures two roles that inherit from each other.
When an agent hands you anything with the words order, depends, inherits, or before, draw an arrow from each thing to whatever needs it, and check whether any path leads back to where it started. If one does, no valid order exists.