
What the Runtime Does With Your Code
An agent adds a report endpoint to your Node.js API. It reads a month of sales from the database, builds a large summary in a loop, and returns it. The code is typed, the tests pass, and the endpoint answers in 800 milliseconds on your machine. A week after it ships, someone notices that every page on the site stalls for about a second at random, and the person on call does not link it to the new endpoint.
The link between those two facts sits in the runtime: the program that takes your source code and turns it into behavior on the machine. Each language makes choices about when code is checked, where values live, when memory is freed and what gets to run when. An agent writes code that is correct inside those rules most of the time. The bugs worth catching are the ones where it forgets a rule the language never enforces.
From text to running instructions
Source code is text. Before anything runs, a program reads that text, splits it into tokens such as names, numbers and operators, and builds a tree that records how they nest. Everything after that is a choice about what to do with the tree.
A compiler such as the ones for C, Rust or Go translates the tree ahead of time into machine instructions for a specific CPU, and you ship the result. An interpreter walks the program and carries out each step as it goes.
Most popular languages sit in between. CPython compiles your file to bytecode, a compact instruction set for a virtual machine, and then interprets the bytecode. JavaScript engines and the JVM start that way too, then watch which functions run often and compile those to machine code while the program runs, which is called just-in-time (JIT) compilation.
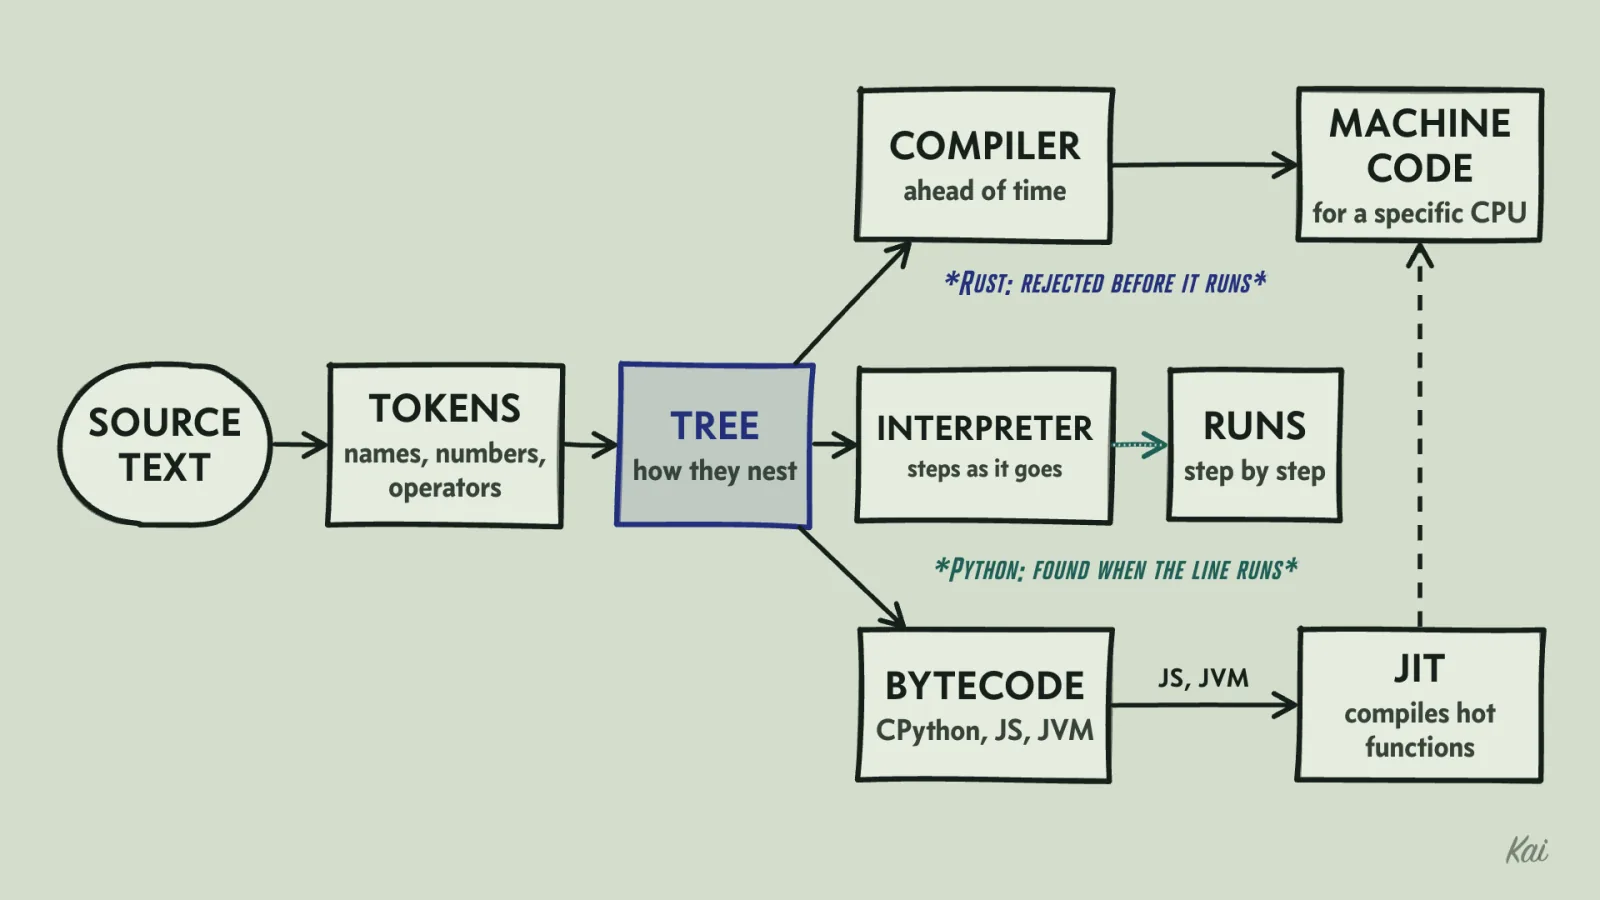
For review, the part that matters is when errors appear. A Rust compiler rejects a call with the wrong argument types before the program exists. Python finds the same mistake only when that line runs, which might be in production on the one path your tests skipped. The earlier a language checks something, the less of that kind of bug reaches users.
What a type checker proves
A static type checker reads the program without running it and checks that the code is consistent with the types it declares. In TypeScript, if a function takes a User and User declares email: string, the checker confirms that user.email.toLowerCase() is called on a declared string at every call site it can see. TypeScript is deliberately unsound: some typings and escape hatches let a wrong value through on purpose, so a clean check is evidence about the code and carries no guarantee about runtime.
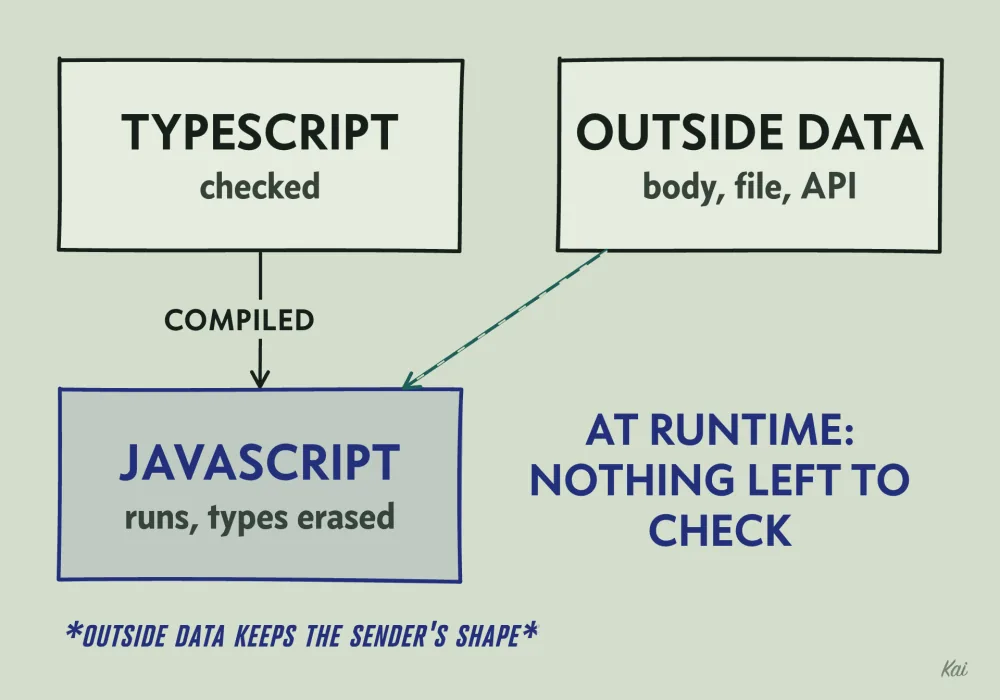
The phrase "declared types" carries the weight. TypeScript's types are erased when the code is compiled to JavaScript, so at runtime there is nothing left to check against. Data that arrives from outside the program, such as a request body, a file or an API response, has whatever shape the sender gave it.
Ordinary types also say little about values. Sale[] does not say the array is non-empty, number does not say the number is positive, and string does not say two IDs refer to the same account. More precise types can encode some of these, such as [Sale, ...Sale[]] for a non-empty array, and validation code at the boundary can establish the rest.
Languages give you ways to tell the checker to stop asking. In TypeScript they are any, the as cast, the ! non-null assertion and the // @ts-ignore comment. Each one replaces a check with your promise.
interface Sale { amountCents: number; region: string }

// The checker accepts this. It proves nothing about the data.
const sales = JSON.parse(body) as Sale[];

// @ts-ignore  -- "Property 'regoin' does not exist on type 'Sale'"
const regions = sales.map(s => s.regoin);
The as Sale[] promises that the parsed JSON has the right shape, and if a field is missing the code fails later, far from the cause. The @ts-ignore is worse: the checker found a real typo and the comment told it to be quiet, so regions is now an array of undefined.
When you see an escape hatch in an agent's diff, read the error it silenced. Often that error was correct. The fix for outside data is to validate it at the boundary with a parser that checks the shape and returns a typed value or an error, so every line after it can rely on the type.
The call stack and the heap
When a function is called, the runtime pushes a frame onto the call stack. The frame holds the function's arguments, its local variables and the place to return to. When the function returns, the frame is popped and those slots are gone. This is why local variables cost almost nothing: freeing them is just moving a pointer.
Objects that must outlive the call that made them go on the heap, a separate region the runtime manages. In JavaScript, objects, arrays and strings live there, and a local variable holds a reference to one. Trace this call.
function summarize(sales) {
  const totals = new Map();                  // Map object allocated on the heap
  for (const s of sales) {
    const prev = totals.get(s.region) ?? 0;  // prev: a number in this frame
    totals.set(s.region, prev + s.amountCents);
  }
  return totals;                             // the reference escapes the frame
}

const report = summarize(rows);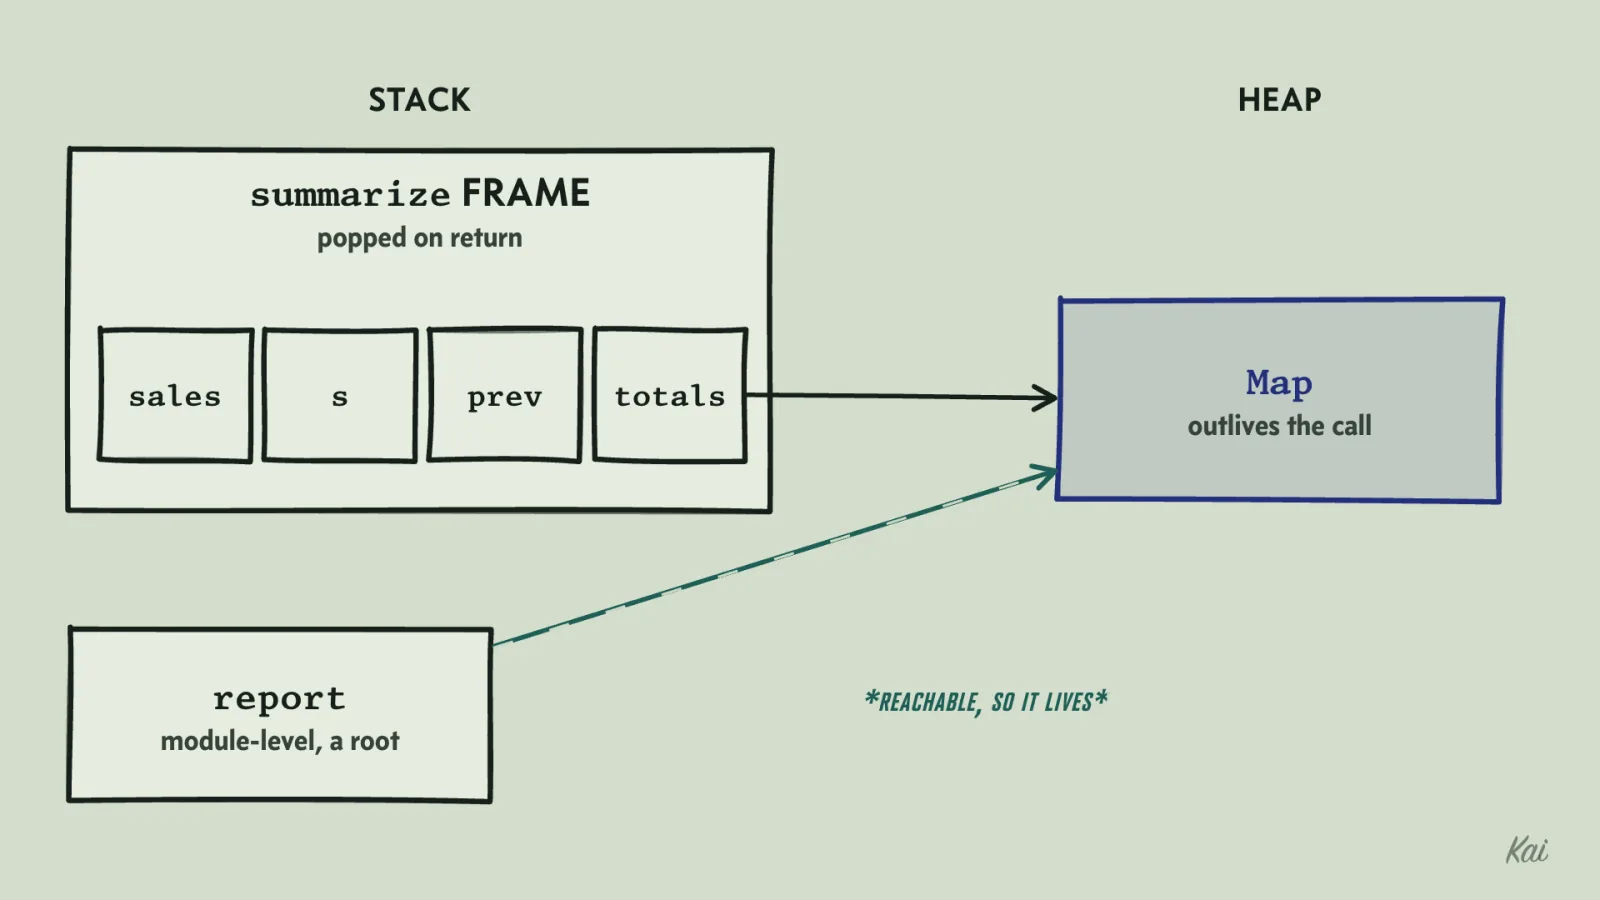
summarize runs, its frame holds sales, totals, s and prev. When it returns, the frame and its reference to the Map are gone, but the Map lives on the heap and survives because report, a module-level root, still refers to it.While summarize runs, its frame holds sales, totals, s and prev. When it returns, the frame is popped. The Map survives because report now refers to it. If a variable is captured by a closure, the engine moves it to a heap object so it can outlive the frame too.
In a garbage-collected language, the runtime periodically finds every object reachable from the roots, meaning the stack, global and module-level variables, and anything those point to. Everything else is freed. That rule tells you what a memory leak is in JavaScript, Python, Java or Go: an object that is still reachable after the program is done with it.
const cache = new Map();  // module-level: reachable for the life of the process

export async function getReport(month) {
  if (!cache.has(month)) cache.set(month, await buildReport(month));
  return cache.get(month);
}
Every distinct month adds an entry and nothing removes one. If the key were a user ID or a search string, the map would grow with traffic until the process hit its memory limit and was killed. A closure does the same thing more quietly: an event handler that refers to a large buffer keeps that buffer alive for as long as the handler is registered.
When you see a module-level collection, ask what removes entries and what bounds its size. If new keys keep arriving and nothing removes entries, memory grows without bound.
Rust makes the other choice. The compiler tracks which variable owns each heap value and frees it when the owner goes out of scope, with no collector at runtime. C leaves freeing to you, which allows use-after-free and double-free bugs that garbage collection rules out.
Two references, one object
Because variables hold references, two names can point at the same object. A change made through one name shows up through the other.
type Options = { retries: number; headers: Record<string, string> };
const DEFAULTS: Options = { retries: 3, headers: { "user-agent": "reporter/1.0" } };

function clientFor(token: string): Options {
  const opts = { ...DEFAULTS };                   // copies the top level only
  opts.headers.authorization = `Bearer ${token}`; // writes into the shared headers object
  return opts;
}

const a = clientFor("A");
const b = clientFor("B");
console.log(a.headers.authorization);        // Bearer B
console.log(DEFAULTS.headers.authorization); // Bearer B
console.log(a.headers === b.headers);        // true
Output
The spread makes a new outer object, but opts.headers and DEFAULTS.headers are the same object. Each call overwrites the authorization field of that one shared object, so the client built for A now carries B's token, and so does DEFAULTS itself. The type checker accepts all of this, because nothing in the types says who else holds the object. The bug surfaces far from this function, in whichever request uses the client next.
The question that exposes it is who else holds a reference to the object being changed. Safer code builds a new object at every level it changes (headers: { ...DEFAULTS.headers, authorization: ... }). Freezing the defaults can also make a write fail loudly, but Object.freeze is shallow: freezing DEFAULTS leaves DEFAULTS.headers writable, so the nested object needs its own freeze. Outside strict mode a write to a frozen object is silently ignored, and ES modules and classes are strict by default.
What runs when
The runtime also decides what code runs at any moment. There are a few common models.
With threads, the operating system runs several instruction streams at once on different cores, or switches between them at any moment. Threads share memory, so two of them can change the same data at the same time, and code needs locks to stay correct. Java, C# and Go (with goroutines) work this way. CPython has a global interpreter lock that lets only one thread execute Python bytecode at a time, though an optional free-threaded build exists since Python 3.13.
JavaScript uses an event loop. One thread runs your code. When code starts a slow operation such as a network request or a file read, the runtime hands it to the operating system and moves on, and when the result arrives a callback is queued.
The loop takes the next queued callback only after the current code has finished. Nothing interrupts a running function.
That gives a strict order you can predict.
console.log("A");
setTimeout(() => console.log("B"), 0);
Promise.resolve().then(() => console.log("C"));
console.log("D");
Output
This prints A, D, C, B. The synchronous lines run first, in order. The promise callback goes on the microtask queue, which is emptied as soon as the current synchronous code finishes.
The timer callback goes on a separate queue that the loop checks only after microtasks are done, even with a delay of zero. An await follows the same rule: everything after it in the function runs later as a microtask.
async function f() { console.log("1"); await null; console.log("2"); }
console.log("0"); f(); console.log("3");
// 0, 1, 3, 2
One slow function, every user waiting
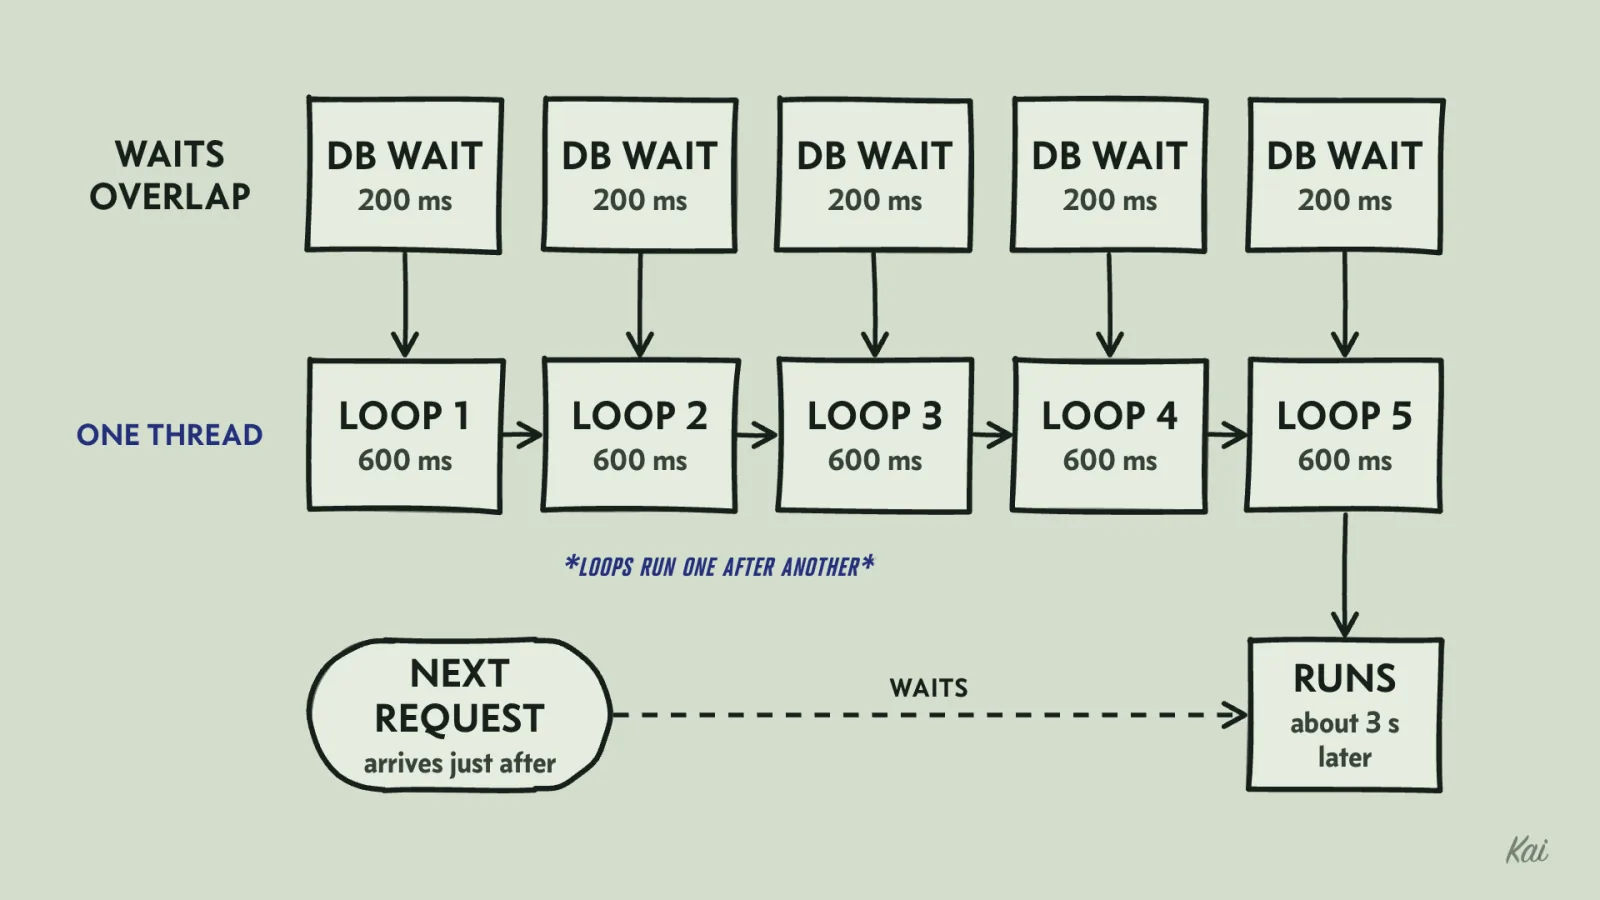
Now the report endpoint makes sense. Say 600 of its 800 milliseconds are the summary loop, plain synchronous code on the CPU, and the other 200 are waiting for the database, which does not block the thread. During the 600 milliseconds of loop the one thread is busy, so no other callback runs. Every other request that arrives, including a health check that needs one millisecond of work, waits for the loop to finish.
If five people load the report at once, their database waits overlap but their loops run one after another. A request arriving just after them waits about three seconds.
The async keyword on the handler changes none of this. It only lets the function pause at an await while other work happens elsewhere, and the function's own computation still runs on the one thread. Synchronous file reads (readFileSync), heavy JSON.parse on large bodies, compression with the Sync functions, CPU-heavy hashing and long loops all block the loop the same way.
The fixes move the work somewhere else or cut it into pieces. Node's worker_threads run JavaScript on a separate thread with its own event loop. A job queue hands the work to a different process entirely. For I/O, the asynchronous version of the call lets the operating system do the waiting.
This program does 300 ms of synchronous work while a health check waits on a 5 ms timer, first in one piece and then in 10 ms slices that hand control back to the event loop between them.
const sleep = (ms: number) => new Promise((r) => setTimeout(r, ms));

// 300 ms of synchronous work in one piece. The async keyword changes nothing.
async function inOnePiece() {
  const end = Date.now() + 300;
  while (Date.now() < end) {}
}

// The same 300 ms in 10 ms slices, letting the event loop run between them.
async function inSlices() {
  for (let i = 0; i < 30; i++) {
    const end = Date.now() + 10;
    while (Date.now() < end) {}
    await sleep(0);
  }
}

async function run(label: string, buildReport: () => Promise<void>) {
  const start = Date.now();
  const health = sleep(5).then(() => console.log(`${label}: health check answered after ${Date.now() - start} ms`));
  await buildReport();
  console.log(`${label}: report finished after ${Date.now() - start} ms`);
  await health;
}

await run("one piece", inOnePiece);
await run("sliced", inSlices);
Output
In one piece, the health check that wanted 5 ms waits the full 300, and it runs only after the report is done. Sliced, it answers after the first slice, about 10 ms in. The report finishes a little after 300 ms because each hand-back adds a little time. The exact numbers vary from run to run.
When you review a handler in an event-loop runtime, find the code that runs between one await and the next and ask how long it takes on the largest input the handler will ever see. Anything past a few milliseconds is time every other user spends waiting.