
Reading Run Time Off the Page
You ask an agent to attach the customer's name to each order before an export. It writes this, and the tests pass:
function attachNamesScan(orders, customers) {
  const result = [];
  for (const order of orders) {
    for (const customer of customers) {
      if (customer.id === order.customerId) {
        result.push({ ...order, customerName: customer.name });
        break;
      }
    }
  }
  return result;
}The test fixture had 20 orders and 10 customers, and the function returned in well under a millisecond. In production the export has 100,000 orders and 100,000 customers. Measured under Bun on a laptop, this function, which this lesson calls attachNamesScan, takes about 7.4 seconds. A version that does the same job with a different data structure, attachNamesMap below, takes about 12 milliseconds, roughly six hundred times faster, and the gap keeps widening as the data grows.
The code has no sleep and no network call, and each line looks cheap. The cost is in the shape: a loop inside a loop. You can read that shape off the page and put a number on it before the code meets real data.
Count the steps, then ignore the constants
A computer runs code as a sequence of basic steps: compare two numbers, read a field, add to an array. Each takes from a fraction of a nanosecond to a few nanoseconds when the data is in the CPU cache, and much longer when it is not, or when it allocates memory. What decides whether a function is fast is how many steps it takes, and in particular how that count grows as the input grows.
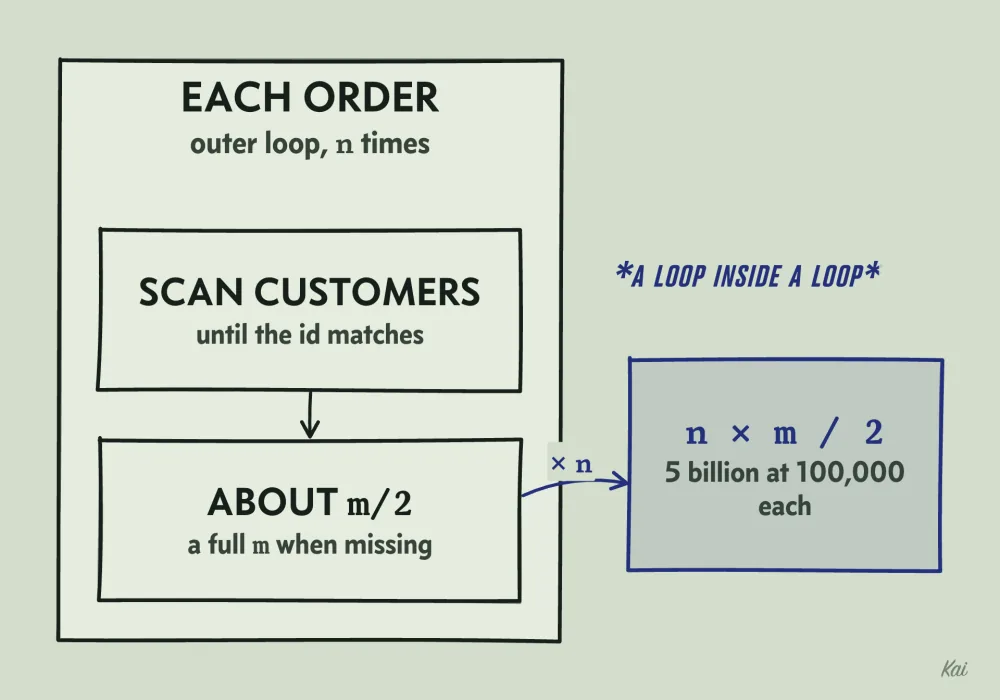
Count the steps in attachNamesScan. The outer loop runs once per order, call that n. For each order, the inner loop scans customers until it finds a match. With m customers and a random match position, that is about m/2 comparisons on average, and a full m when the customer is missing. Total work is about n × m / 2 comparisons. With 100,000 of each, that is 5 billion.
Big-O notation keeps the growth and drops the constant. n × m / 2 is O(n × m), and when both lists are about the same size it is O(n²), called quadratic. The constant matters for the exact time, but it never changes the shape: double the input to a quadratic function and the work goes up four times, multiply it by ten and the work goes up a hundred times.
Here is what the common growth rates mean in raw step counts:
| n | O(n) | O(n log n) | O(n²) |
|---|---|---|---|
| 1,000 | 1,000 | about 10,000 | 1,000,000 |
| 100,000 | 100,000 | about 1.7 million | 10 billion |
| 10,000,000 | 10 million | about 230 million | 100 trillion |
As a rough working figure, a JIT-compiled or compiled language does a few hundred million to a billion simple steps per second, and a plain CPython loop does tens of millions. So a quadratic loop is harmless at a thousand items, costs seconds to minutes at a hundred thousand, and does not finish in any useful time at ten million. A linear loop is fine at all three. That is how a quadratic function passes a test suite built from small fixtures and then fails on production data.
The rewrite: trade a scan for a lookup
The inner loop exists to answer one question: which customer has this id? Scanning a list answers it in O(m). A hash map answers it in O(1) on average, meaning the time for one lookup stays about the same however many entries the map holds. It does this by computing a number from the key and using it to jump straight to the right bucket.
So build the map once, then look up each order:
function attachNamesMap(orders, customers) {
  const nameById = new Map();
  for (const c of customers) {
    if (!nameById.has(c.id)) nameById.set(c.id, c.name);
  }
  const result = [];
  for (const order of orders) {
    if (nameById.has(order.customerId)) {
      result.push({ ...order, customerName: nameById.get(order.customerId) });
    }
  }
  return result;
}
Building the map is O(m). The second loop is O(n) with constant-time lookups inside. The total is O(n + m), linear. The cost is space: the map holds one entry per customer, so memory use is O(m) where the old version used none beyond the result.
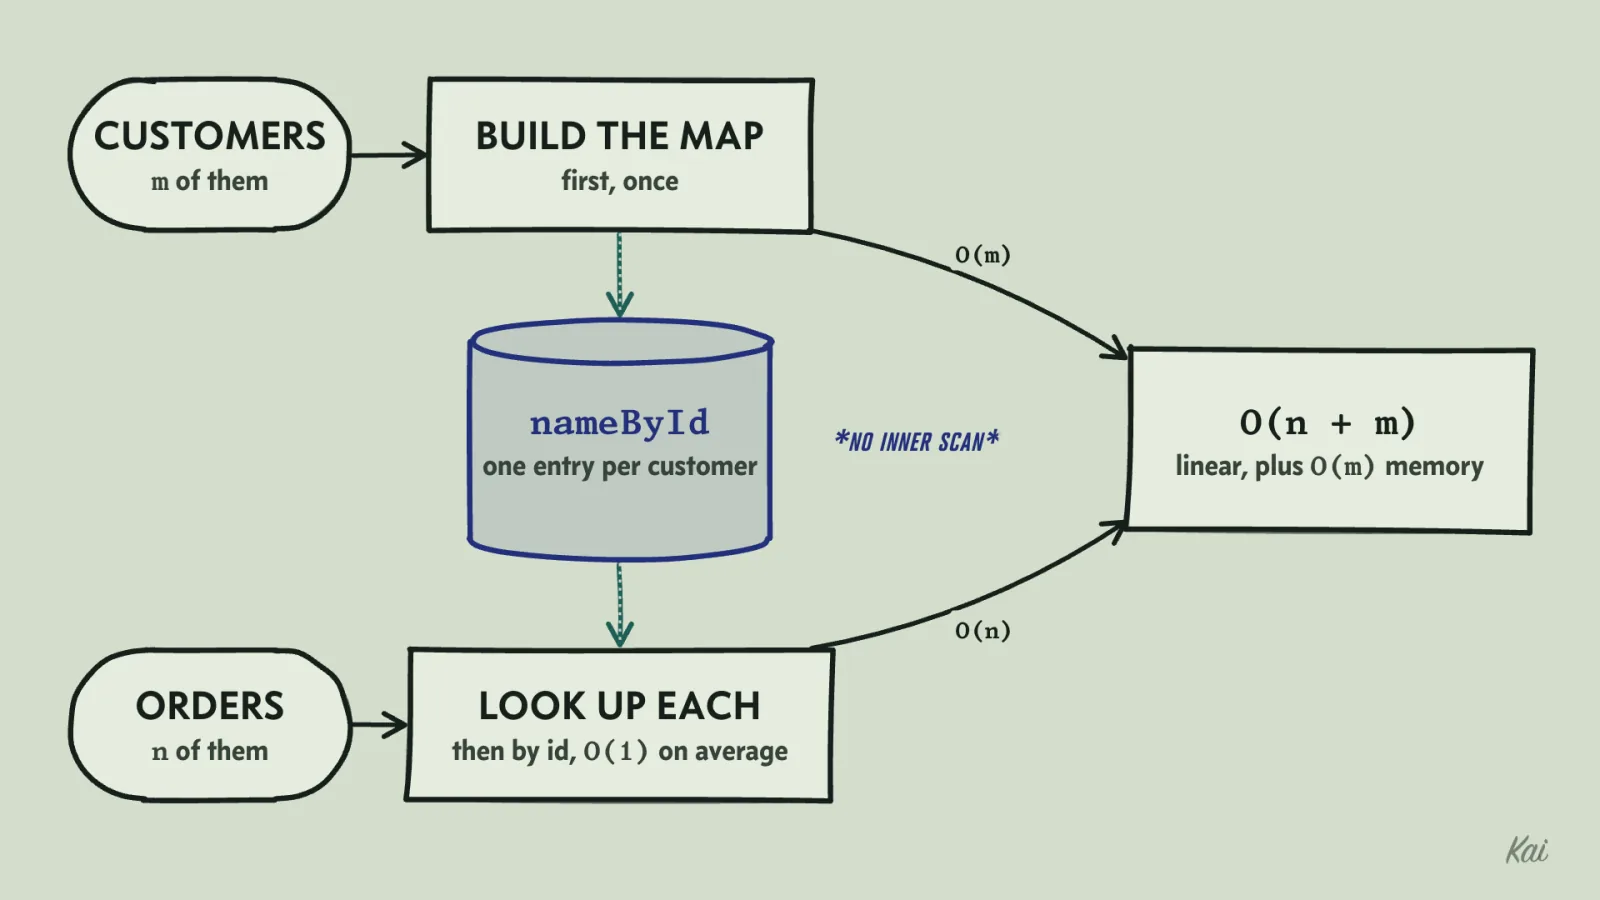
O(n + m) instead of multiplying.You can check that arithmetic by counting. The playground below gives both functions a step counter: one step per comparison in the scan, and one per map insert or lookup in the rewrite. Every order points at a different customer, spread through the list.
type Customer = { id: number; name: string };
type Order = { id: number; customerId: number };
let steps = 0;

function attachNamesScan(orders: Order[], customers: Customer[]) {
  const result = [];
  for (const order of orders) {
    for (const customer of customers) {
      steps++;
      if (customer.id === order.customerId) {
        result.push({ ...order, customerName: customer.name });
        break;
      }
    }
  }
  return result;
}

function attachNamesMap(orders: Order[], customers: Customer[]) {
  const nameById = new Map<number, string>();
  for (const c of customers) {
    steps++;
    if (!nameById.has(c.id)) nameById.set(c.id, c.name);
  }
  const result = [];
  for (const order of orders) {
    steps++;
    if (nameById.has(order.customerId)) {
      result.push({ ...order, customerName: nameById.get(order.customerId)! });
    }
  }
  return result;
}

for (const fn of [attachNamesScan, attachNamesMap]) {
  for (const n of [1_000, 10_000]) {
    const customers = Array.from({ length: n }, (_, i) => ({ id: i, name: `customer ${i}` }));
    const orders = Array.from({ length: n }, (_, i) => ({ id: i, customerId: (i * 7919) % n }));
    steps = 0;
    fn(orders, customers);
    console.log(fn.name, n, "items:", steps, "steps");
  }
}
Output
Ten times as many items gives the scan about 100 times as many steps, 50,005,000 against 500,500, and the map version exactly 10 times as many. The counts are the same on every machine and every run, which makes them a cleaner first check than a stopwatch.
Three details keep the rewrite honest. The original skipped orders whose customer was missing, so the new version does too. The original took the first matching customer when ids repeated, so the map keeps the first one it sees. The third is an assumption: ids are strings or integers, validated where the data enters the system. A Map treats NaN as equal to NaN and === never does, so an order whose customer id is NaN gets a name from the map version and is skipped by the scan. A rewrite for speed that silently changes which rows come out is a new bug. When you ask an agent for the faster version, ask it which inputs, if any, produce different output.
Where else quadratic time hides
A search can also hide inside a method call. These lines each contain a loop:
const active = users.filter((u) => !bannedIds.includes(u.id));
const idx = rows.findIndex((r) => r.sku === sku);Array.prototype.includes, indexOf, find and findIndex scan the array from the start. So does x in some_list in Python, which the Python wiki's TimeComplexity page lists as O(n), against O(1) on average for a set. The first line above is a loop over users with a scan of bannedIds inside each step, so it is O(users × banned). The fix is to build new Set(bannedIds) once and call .has(). The question to ask of every method call inside a loop is: does this method walk a collection?
Recomputation is the other place. A value that does not change between iterations gets recomputed on every one:
const maxScore = (rs) => rs.reduce((m, x) => Math.max(m, x.score), -Infinity);
const top = rows.filter((r) => r.score >= 0.9 * maxScore(rows));
The maximum is the same for every row, but the code computes it n times, each time over all n rows. That is O(n²) for what should be O(n). Compute maxScore(rows) once into a variable above the filter and the scan runs once. The same pattern appears across requests: a handler that reads and parses a config file, compiles a regular expression, or builds a lookup table from the whole database on every request. For each expensive expression inside a loop or a handler, ask what it depends on. If nothing it depends on changes from one iteration or request to the next, compute it once outside.
Choosing a data structure from the access pattern
Every data structure makes some operations cheap by making others expensive. You choose one by writing down what the code will do most often, then picking the structure that makes that operation cheap.
| Structure | Cheap | Expensive |
|---|---|---|
| Array or list | read by position, append at the end | find by value O(n), insert or remove at the front O(n) |
| Hash map or set | insert, delete, look up by key, O(1) average | anything that needs order, such as "all keys between A and F" |
| Sorted tree (and B-tree database indexes) | look up and insert in O(log n); a range query returning k entries in O(log n + k), in order | a lookup makes O(log n) comparisons where a hash map averages O(1) key checks; real speed depends on memory layout and cache |
| Heap (priority queue) | read the smallest item O(1), add or remove O(log n) | find an arbitrary item O(n) |
| Queue or deque | add and remove at either end O(1) | find by value O(n) |
Read a described access pattern into a row of that table. "Look up a user by email on every request" is a hash map. "Show all orders placed between two dates" wants order, so a sorted structure or a database index on the date. "Always run the most urgent job next" is a heap. "Process jobs in the order they arrived" is a queue, and in Python that means collections.deque, because list.pop(0) shifts every remaining element and costs O(n).
Predict, then measure
A complexity class makes a prediction you can test. If a function is linear, ten times the input should take about ten times as long. If it is quadratic, about a hundred times. Measuring both versions at three sizes gave this, in one run under Bun on a laptop:
| n (orders = customers) | nested loop | map lookup |
|---|---|---|
| 1,000 | 2.8 ms | 0.4 ms |
| 10,000 | 73 ms | 1.0 ms |
| 100,000 | 7,385 ms | 11.9 ms |
From 10,000 to 100,000 the nested loop took about 100 times longer and the map version about 12 times longer, which is what the two growth rates predict. The step from 1,000 to 10,000 does not match as well, because at a few milliseconds the timer, the JIT compiler warming up and memory allocation are a large share of the total. Measure at sizes where each run takes at least tens of milliseconds, and compare the ratios between sizes.
The measuring code is short. makeInput gives every customer a distinct id and every order a random customer, so the scan has to walk half the list on average, as the step count assumed:
function makeInput(n) {
  const customers = Array.from({ length: n }, (_, i) => ({ id: i, name: `customer ${i}` }));
  const orders = Array.from({ length: n }, (_, i) => ({
    id: i,
    customerId: Math.floor(Math.random() * n),
  }));
  return [orders, customers];
}

for (const fn of [attachNamesScan, attachNamesMap]) {
  for (const n of [1_000, 10_000, 100_000]) {
    const [orders, customers] = makeInput(n);
    const start = performance.now();
    fn(orders, customers);
    console.log(fn.name, n, (performance.now() - start).toFixed(1), "ms");
  }
}
Write your prediction down before you run it. If the ratio is far off, either your reading of the code is wrong or something else, like a hidden scan in a library call, is doing work you did not count.
The same ratio lets you extrapolate from a test. If a quadratic function takes 2 milliseconds on 1,000 items, it takes about 2 × 100² = 20,000 milliseconds, or 20 seconds, on 100,000.
Constant factors and repeated subproblems
Big-O describes growth and hides constant factors, and at small sizes the constants win. Scanning an array of eight items can be faster than hashing a key, because the array sits in one contiguous block of memory and the CPU reads it quickly. The standard library's comparison sorts are O(n log n) comparisons, each costing whatever your comparator costs, and they are heavily tuned, so calling the built-in is almost always better than an agent's hand-written sort. The Big-O class tells you which version will lose as data grows. For which one is faster at the size you actually have, measure.
Recursion has its own trap. A recursive function that calls itself twice on overlapping subproblems can take exponential time:
function ways(n) {
  if (n <= 1) return 1;
  return ways(n - 1) + ways(n - 2);
}
ways(40) makes over 300 million calls because it solves the same smaller cases again and again. Storing each answer the first time it is computed, in a map keyed on n, makes it linear. That technique is dynamic programming. The sign to look for is a recursive call tree where the same arguments appear on many branches.
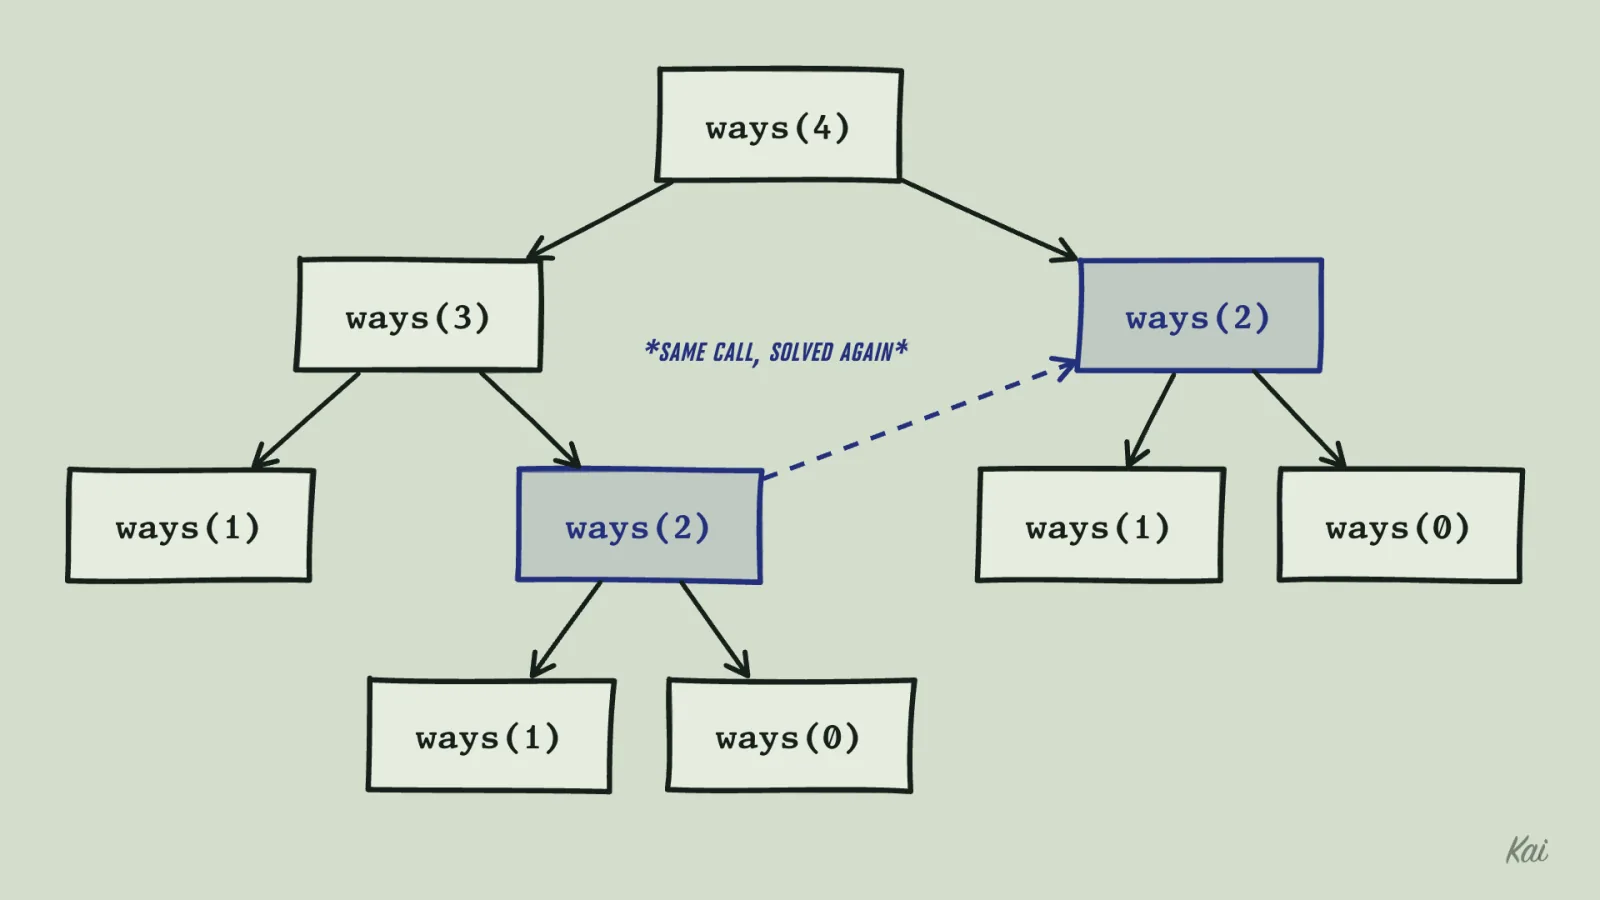
The playground counts the calls each version makes. The second version checks a map before it recurses and stores each answer it computes.
let calls = 0;

function ways(n: number): number {
  calls++;
  if (n <= 1) return 1;
  return ways(n - 1) + ways(n - 2);
}

const known = new Map<number, number>();
function waysStored(n: number): number {
  calls++;
  if (n <= 1) return 1;
  const hit = known.get(n);
  if (hit !== undefined) return hit;
  const answer = waysStored(n - 1) + waysStored(n - 2);
  known.set(n, answer);
  return answer;
}

for (const n of [10, 20, 30]) {
  calls = 0;
  const answer = ways(n);
  const plainCalls = calls;
  calls = 0;
  known.clear();
  const same = waysStored(n) === answer;
  console.log(`n=${n}: ${plainCalls} calls plain, ${calls} calls stored, same answer: ${same}`);
}
Output
Each step of 10 in n multiplies the plain version's calls by more than a hundred. The stored version makes 2n - 1 calls.
When you review a loop, multiply the cost of its body by the number of times it runs. A search, a scan or a recomputation over n items inside a loop over n items makes the whole function O(n²), however innocent each line looks alone.