
Green Checks and Real Failures
An agent sets up production for a document-upload service and reports back. Two app instances run behind a load balancer. Each has a health check, and both show green. A cron job backs up the database every night and has succeeded every night for three months. The summary calls the setup highly available with daily backups.
Each of those statements can be true while the service is down and its data is gone. Two instances protect you only from failures that hit one of them and spare the other. A green health check means the check passed, which says as much about the check as about the service. A backup job that succeeds tells you a command exited with status 0. What counts is what each mechanism does during the failure it exists for, and the only reliable way to learn that is to cause the failure and watch.
Redundancy depends on independence
Redundancy works by arithmetic. If each app instance is up 99% of the time and the two fail independently, both are down at once only 1% × 1% = 0.01% of the time, so the pair is up 99.99% of the time.
That calculation assumes the two failures are unrelated. Suppose both instances talk to one database that is up 99.9% of the time. A request needs an instance and the database, so the availabilities multiply: 0.9999 × 0.999 ≈ 0.9989, or 99.89%. The second instance did help, since one instance with that database gives 0.99 × 0.999 ≈ 98.9%. But the database now caps the whole system below 99.9%, so a third app instance would change almost nothing. The next gain has to come from the database, the component every request shares.
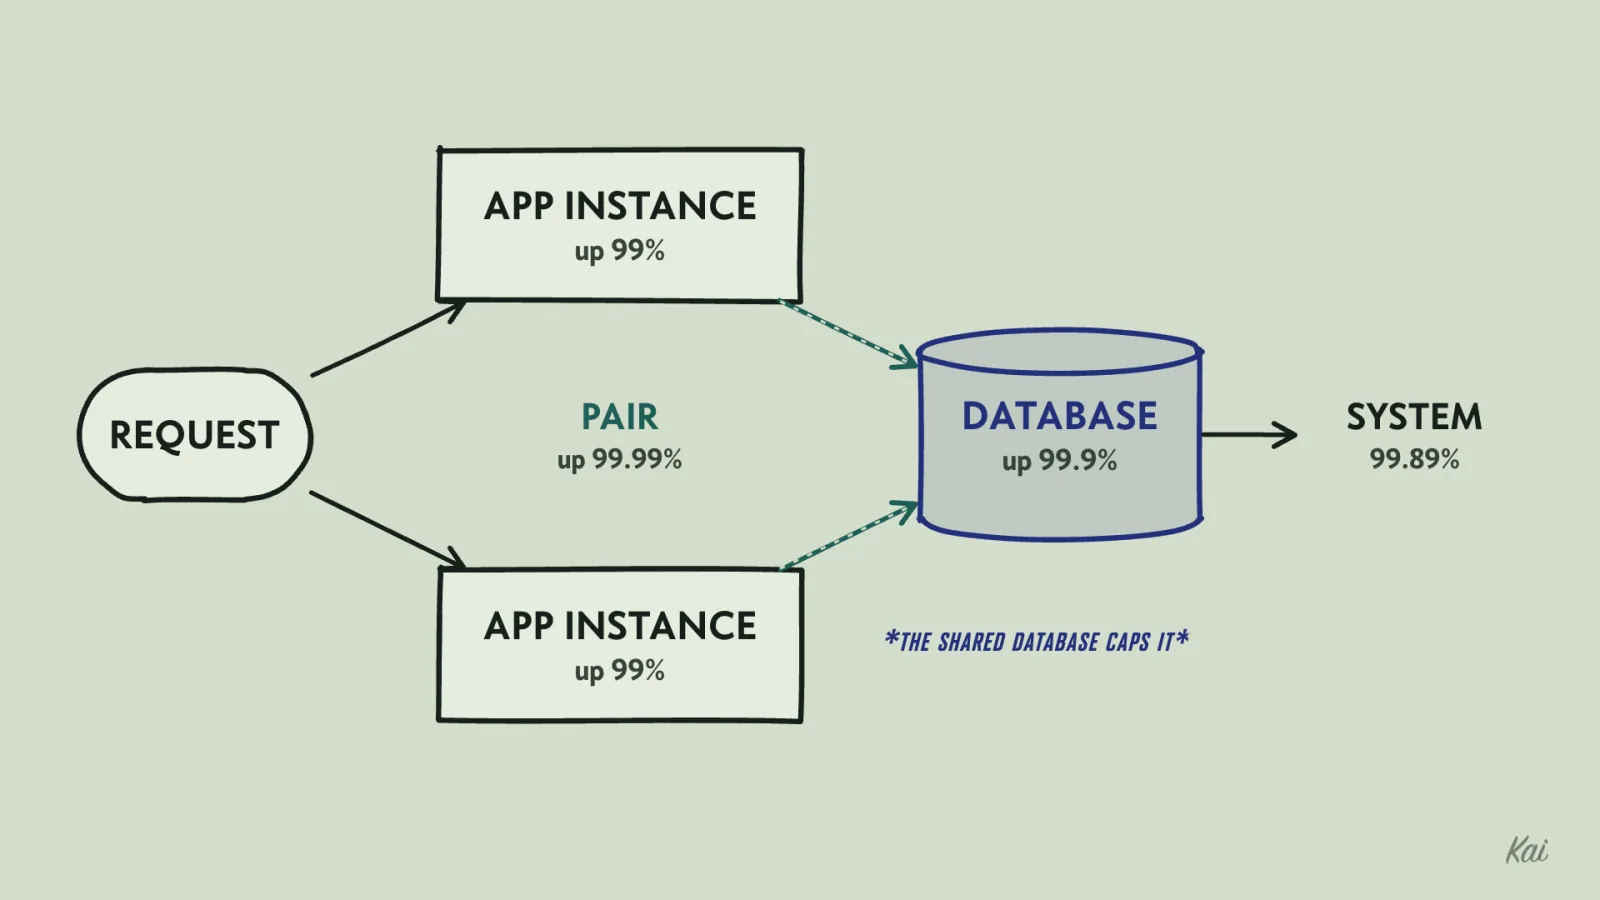
This block runs the same arithmetic, then adds a second database and a shared zone:
// Parts a request needs all of multiply. Copies where any one will do fail only together.
const allOf = (...parts: number[]) => parts.reduce((up, a) => up * a, 1);
const anyOf = (...copies: number[]) => 1 - copies.reduce((down, a) => down * (1 - a), 1);
const pct = (a: number) => (a * 100).toFixed(3) + "%";

const app = 0.99;
const db = 0.999;
const zone = 0.999; // an assumed figure for one availability zone

console.log("1 app + database:      ", pct(allOf(app, db)));
console.log("2 apps + database:     ", pct(allOf(anyOf(app, app), db)));
console.log("3 apps + database:     ", pct(allOf(anyOf(app, app, app), db)));
// Assumes failover always works and the two databases fail independently.
console.log("2 apps + 2 databases:  ", pct(allOf(anyOf(app, app), anyOf(db, db))));
console.log("same, all in one zone: ", pct(allOf(anyOf(app, app), anyOf(db, db), zone)));
Output
The third app instance adds 0.01 percentage points. The second database adds about ten times that, and putting everything in one zone undoes that gain, because the zone is a part every request needs and nothing else covers for it.
A failure domain is a set of things that fail together. A machine is one. So is a data center, an availability zone (one or more data centers that a cloud provider isolates from the others), and a region. Less obvious ones matter just as much: one cloud account, one API key, one DNS provider, one config file pushed to every instance at once, one deploy that ships the same bug everywhere. Two instances in the same zone share a power and network failure domain. Two instances using the same API key share a credential failure domain: if the key is revoked or expires, both stop in the same second.
Mapping the single points of failure
A single point of failure is any component whose loss takes the whole service down. To find them, draw the system and then go through every box and every arrow with one question: if this disappeared right now, what would stop working?
users -> DNS -> load balancer -> app-1 (zone a) -+-> Postgres primary (zone a)
                              -> app-2 (zone a) -+-> object storage (one API key)
cron on app-1: pg_dump -> /backups on app-1's disk
Walking this diagram gives a table like this one.
| Component | If it fails | Shared by |
|---|---|---|
| app-1 | Traffic moves to app-2. Backups stop, and if its disk is lost, every backup goes with it | Backups live here |
| app-2 | Traffic moves to app-1 | Nothing else |
| Load balancer or DNS | Nobody reaches either app | Everything, unless the provider runs it across zones |
| Zone a | Everything stops | Both apps, the database, the backups |
| Postgres primary | Every request fails | Both apps |
| Storage API key | Uploads and downloads fail on both apps | Both apps |
Rank each one by how much stops and how likely the failure is. The database is a single machine that every request needs, so its failure is both fairly likely and total, which makes it the worst. Zone a is close behind: zone outages are rarer, and one takes everything with it, backups included. One proposal addresses both: put a standby database in a second zone with automatic failover, move app-2 to that zone, and move backups off app-1 entirely.
A standby helps only if failover works, and failover has several parts that can each fail: replication has to be current, clients have to reconnect to a new address, and the old primary has to stay out of the way. The only way to know is to stop the primary on purpose, in a staging copy or a planned window, and watch what happens and how long it takes.
Health checks that tell the truth
A load balancer calls each instance's health check every few seconds and stops sending traffic to instances that fail it. That makes the health check the load balancer's entire picture of your service. A check that returns 200 without looking at anything reports that the process is running, which is also true while every request it serves is failing because the database is unreachable.
The fix is to decide what question each check answers.
async function withTimeout<T>(work: Promise<T>, ms: number): Promise<T> {
  let timer: ReturnType<typeof setTimeout> | undefined;
  const timeout = new Promise<never>((_, reject) => {
    timer = setTimeout(() => reject(new Error(`timed out after ${ms}ms`)), ms);
  });
  try {
    return await Promise.race([work, timeout]);
  } finally {
    clearTimeout(timer);
  }
}

// Liveness: is this process able to answer at all? A failure here means restart it.
export function livez(): Response {
  return new Response("ok");
}

// Readiness: can this instance do its job right now? A failure here means stop sending it traffic.
export async function readyz(db: { query(sql: string): Promise<unknown> }): Promise<Response> {
  try {
    await withTimeout(db.query("SELECT 1"), 500);
    return new Response("ok");
  } catch (err) {
    const reason = err instanceof Error ? err.message : String(err);
    return new Response(`database: ${reason}`, { status: 503 });
  }
}
The readiness check touches the database with a query that cannot change anything and stops waiting after half a second, so a hung connection produces a failure instead of a check that never answers. The query itself may keep running, which is one reason the database needs its own statement timeout.
This block runs both kinds of check against a fake database in three states:
type Db = { query(sql: string): Promise<unknown> };

async function withTimeout<T>(work: Promise<T>, ms: number): Promise<T> {
  let timer: ReturnType<typeof setTimeout> | undefined;
  const timeout = new Promise<never>((_, reject) => {
    timer = setTimeout(() => reject(new Error(`timed out after ${ms}ms`)), ms);
  });
  try {
    return await Promise.race([work, timeout]);
  } finally {
    clearTimeout(timer);
  }
}

// What the agent's endpoint does: answer 200 whenever the process is running.
function shallowCheck(): string {
  return "200 ok";
}

async function readinessCheck(db: Db): Promise<string> {
  try {
    await withTimeout(db.query("SELECT 1"), 500);
    return "200 ok";
  } catch (err) {
    return `503 database: ${(err as Error).message}`;
  }
}

const databases: Record<string, Db> = {
  "up": { query: async () => [{ one: 1 }] },
  "refusing connections": { query: async () => { throw new Error("connection refused"); } },
  "hung": { query: () => new Promise(() => {}) }, // never answers
};

for (const [state, db] of Object.entries(databases)) {
  console.log(`database ${state}: shallow ${shallowCheck()}, readiness ${await readinessCheck(db)}`);
}
Output
The shallow check says the same thing in all three states, so in two of them the load balancer keeps sending traffic to an instance that fails every request. The readiness check fails fast when the database refuses, and fails after half a second when it hangs.
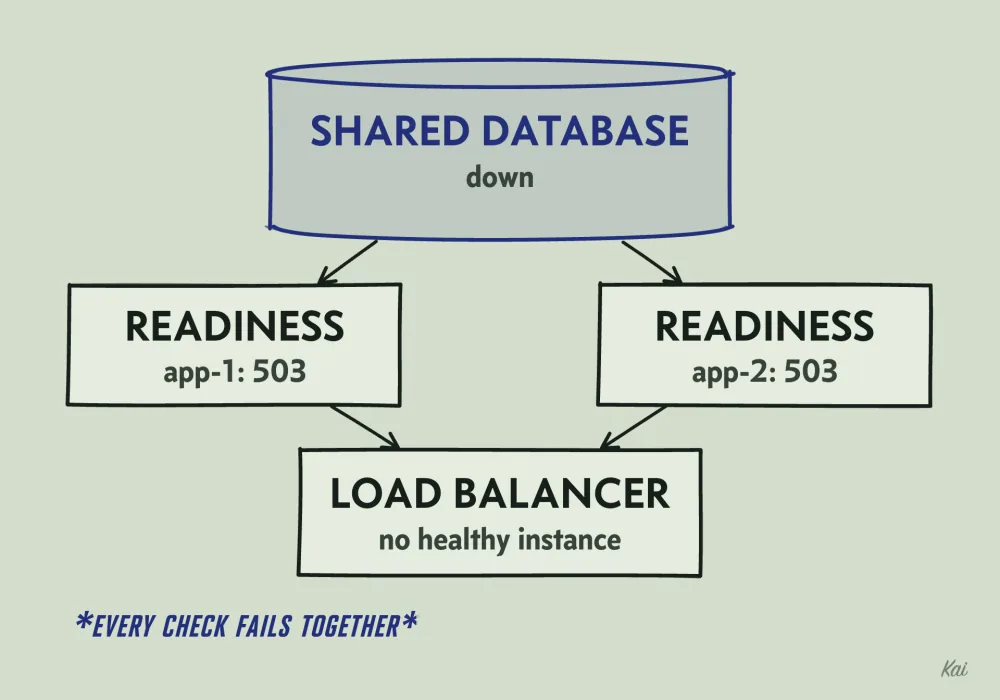
Deep checks carry a risk of their own. If every instance shares the database and the database goes down, every readiness check fails together, and the load balancer has no healthy instance left. Some load balancers then send traffic to all instances anyway. Others return errors for everything. And if you wire a deep check to liveness, the orchestrator restarts every instance during a database blip, which turns a short outage into a longer one. Keep liveness shallow, make readiness reflect real dependencies, alert on readiness failures, and find out what your load balancer does when every target is unhealthy.
The test for any health check is to break the dependency and look. Stop the database in staging and call the endpoint. If it still says 200, the check reports on the process and nothing more.
Degrading instead of falling over
Some failures should take out one feature and leave the rest of the product working. If the thumbnail service is slow, document uploads should still succeed without thumbnails. Four techniques handle most of this. A timeout on every outbound call bounds how long your code waits on a slow dependency. It does not release what the call holds: the withTimeout helper above uses Promise.race, which stops waiting but leaves the work running. To free connections and threads, put deadlines on the dependency itself, such as a timeout on acquiring a pooled connection and a statement timeout on the database, or cancel the work, for example with an AbortSignal. A fallback returns something useful when a call fails, like a cached value or a placeholder image. A circuit breaker counts recent failures to a dependency and, past a threshold, stops calling it for a while, so you fail fast instead of piling up waiting requests. Load shedding rejects some requests early when the service is overloaded, so the ones it accepts still finish in time.
Backups are measured by restores
Here is the backup job from the opening, as the agent wrote it:
# crontab: 0 2 * * * /opt/app/nightly-backup.sh
pg_dump "$DATABASE_URL" | gzip > /backups/app-$(date +%F).sql.gz
Suppose the database password was rotated in June and nobody updated this job. Since then pg_dump fails to connect every night and writes nothing to the pipe. gzip compresses zero bytes into a valid 20-byte file and exits 0. A shell pipeline reports the exit status of its last command, so the job succeeds every night, and /backups fills with small, well-formed, empty files. On top of that, the files sit on app-1's disk, in the same zone as the database, deletable by anyone who can reach app-1.
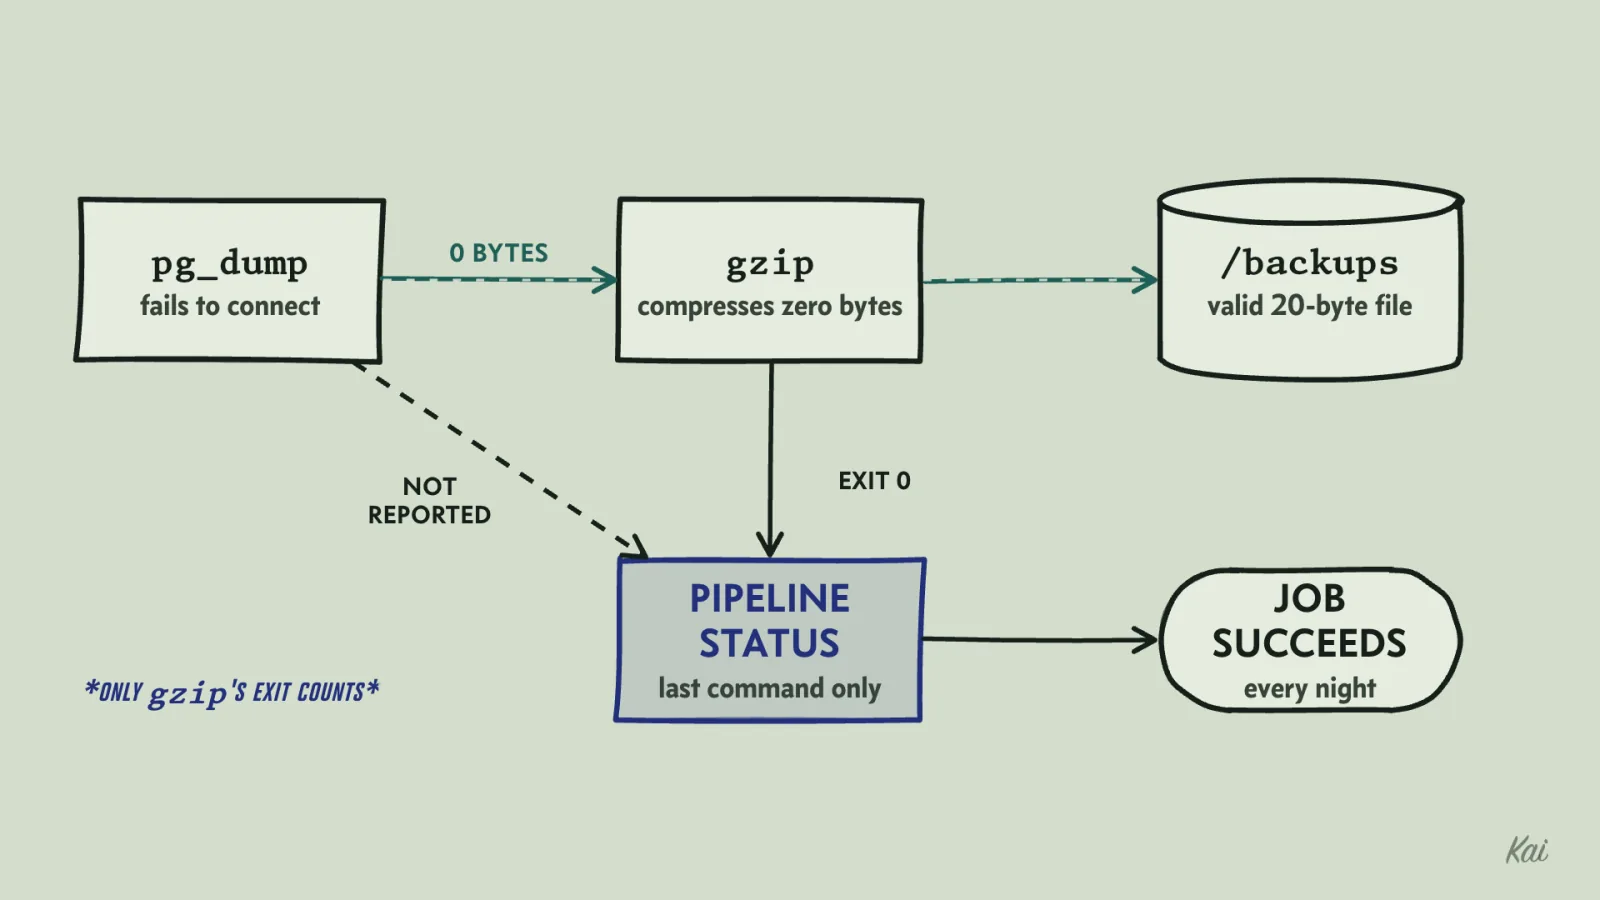
pg_dump fails to connect, gzip turns zero bytes into a valid 20-byte file, and the pipeline reports only gzip's exit 0. The job succeeds every night while every backup is empty.A backup job must fail loudly when any step fails, and must check what it produced.
#!/usr/bin/env bash
set -euo pipefail   # stop on any error, including one in the middle of a pipeline

out="/var/tmp/app-$(date +%F).dump"
pg_dump --format=custom --file="$out" "$DATABASE_URL"

size=$(stat -c %s "$out")   # GNU stat; on macOS use: stat -f %z
if [ "$size" -lt 1000000 ]; then
  echo "backup is only $size bytes" >&2
  exit 1
fi
# Then copy "$out" to storage in a separate account, whose credentials
# production does not hold, with deletion blocked for 30 days.
A size check catches the empty file. It does not prove the backup can be restored. Only a restore proves that, so restore on a schedule and time it:
#!/usr/bin/env bash
set -euo pipefail
dump="$1"
start=$(date +%s)

createdb restore_check
pg_restore --no-owner --dbname=restore_check "$dump"
recent=$(psql -d restore_check -tAc \
  "SELECT count(*) FROM documents WHERE created_at > now() - interval '2 days'")
dropdb restore_check

echo "restored in $(( $(date +%s) - start ))s; documents from the last 2 days: $recent"
[ "$recent" -gt 0 ]
The query checks for recent rows because a restore can succeed with old data. A backup that stopped updating two months ago restores cleanly and is still useless. Compare the counts against production for the tables you care about, and record the duration every time.
Recovery objectives
Two numbers say how good your recovery has to be, and the business sets them. The recovery point objective (RPO) is how much data you can afford to lose, measured in time. The recovery time objective (RTO) is how long the service can be down.
A nightly backup at 02:00 gives an RPO of up to 24 hours: a failure at 01:59 loses almost a full day of uploads. If the business can accept one hour, nightly dumps cannot meet it, and you need continuous copying of changes, which for Postgres means a physical base backup plus continuous archiving of its write-ahead log, so you can replay changes up to any chosen moment. The pg_dump files above are logical dumps and cannot be combined with log replay, so point-in-time recovery needs that different kind of backup. The RTO is checked by the drill. If the restore script takes 40 minutes and repointing the app and checking it takes another 15, the drill measured a recovery time of at least 55 minutes. If your RTO is shorter than that, the procedure does not meet it, whatever the design document says.
Incidents and postmortems
On a Tuesday at 02:00, uploads start failing with FATAL: sorry, too many clients already from Postgres. At 02:25 the on-call engineer restarts both app instances, errors stop, and the incident is closed. The next Tuesday at 02:00 it happens again.
Closing an incident when the symptom stops is the mistake. During the incident, mitigating first is right: restore service, then investigate. But the restart was a mitigation that happened to line up with the real end of the problem, and nobody checked what else was happening at 02:00 on Tuesdays. A weekly export job starts then and opens 80 connections. Postgres allows 100 by default. The two app instances may each open up to 20, but at night they keep only a few open and open more as uploads arrive, and those new connections are refused. The export finished at 02:24, one minute before the restart got the credit.
A blameless postmortem records what happened and why the system allowed it, without assigning fault to the person who scheduled the export. Its core is a timeline built from logs and chat, with timestamps:
02:00  export job starts, opens 80 connections (100 max; apps may need 40)
02:00  upload error rate rises to 35%; no alert (alerts watch CPU only)
02:11  customer report reaches support
02:25  on-call restarts app-1 and app-2; errors stop
       (export had already finished at 02:24)
Then the systemic fixes, each of which would have prevented or shortened this: a connection cap on the export's database role (ALTER ROLE exporter CONNECTION LIMIT 10;), an alert when connections pass 80% of the maximum, an alert on the upload error rate, and a rule that incidents close only when the cause is known and a check exists that would catch it next time.
Write down two measurements after every drill: the time from the start of the restore until the app was serving again, compared with the RTO, and the data the restore lost, compared with the RPO. Measure the loss as the time between the newest write the restore contains and the moment the drill started, as if production had failed then. Read that newest write from a table the app writes every minute, or from a heartbeat row it updates on a schedule, because a quiet table's newest row can be days old with nothing lost. A drill that recorded neither has tested neither objective.