
Reading What the Agent Built
Your agent finished overdue-invoice reminders for your billing app. Before it started, you wrote the ideal state for the feature and four criteria a stranger could check:
## Reminders
A customer whose invoice is past due hears about it by email, so overdue
invoices get paid without anyone on the team chasing them by hand.

- R1: An open invoice past its due date gets a reminder email that names
  the invoice number and the amount due.
- R2: A paid or void invoice gets no reminder.
- R3: The reminder job runs every hour.
- R4: The email reads as polite and clear, judged against three sample
emails the support lead wrote.The agent's report lists each criterion, the command that checked it and the result: four passes on commit 7c1e0b2. The change is about 500 lines across seven files, and CI has not finished on the branch yet.
Reading all 500 lines would take an afternoon, and the four checks already prove most of what they cover. Two questions are left, and they decide where your reading goes: which behavior nobody wrote a criterion for, and whether you understand what was built well enough to run it, secure it and change it next month.
What reading is for
Code review used to be a gate: a person approved each diff before it merged. When agents write most of the code, a person in the loop on every step becomes the bottleneck, and a check that runs on every commit proves its criterion more reliably than a tired reader skimming the same lines. The criteria and their checks carry the routine proof, and human reading keeps two jobs that checks cannot do.
The first job is understanding. In his 1985 essay "Programming as Theory Building", Peter Naur held that the real program is the understanding its programmers carry: what each part is for, why it has this shape, how it would bend to a new need. The code records only part of it, so with agent-written code someone has to build that understanding on purpose. The line between engineering and vibe coding sits here: whether you understand what was built and why, whoever typed it.
The second job is risk. Some behavior has no criterion, because nobody thought of it, and some mistakes cost so much that a passing check is thin evidence. Security, money and one-way doors (actions you cannot take back: a sent email, a deleted row, a migration) get human reading even when every check is green, and so does any behavior no criterion mentions.
Read the checks before the code
Read the tests behind each criterion before the implementation. They show what the agent decided "done" means, and reading them first keeps the implementation from persuading you. For each check, ask what wrong version of the code would still pass it.
The check for R1 creates one open invoice due yesterday, calls sendOverdueReminders(now) once, and asserts that exactly one email was sent. Here are wrong versions it lets through:
- A job that sends the same reminder every time it runs. The test calls it once.
- A job that treats an invoice due later today as overdue. Every fixture is at least a day overdue.
- Dates formatted in the wrong time zone. The suite runs with
TZ=UTCand every fixture date is midnight UTC. - A job that stops at the first failed send and skips everyone after it. The fake mailer always succeeds.
Every item on that list is behavior the criteria leave open. The ideal state says a customer "hears about it by email" and stops there: how often, and what happens when one address bounces, are unwritten. The list is your reading plan for the implementation.
Build the theory from the entry point
To understand code you did not write, find where it starts, follow the data, and write down every side effect. Side effects are the actions that reach outside the function: database writes, network calls, files, emails.
The entry point is in schedule.ts:
scheduler.every("1 hour", () => sendOverdueReminders(new Date()));The job itself, in job.ts:
export async function sendOverdueReminders(now: Date): Promise<void> {
  const invoices = await db.invoices.findMany({
    where: { status: "open", dueAt: { lt: now } },
  });
  for (const inv of invoices) {
    await email.send({
      to: inv.customer.email,
      subject: `Invoice ${inv.number} is overdue`,
      body: renderReminder(inv),
    });
  }
}
Every hour, the query selects every open invoice past its due date, and the job emails each one. Sending the email is the only side effect, and nothing records that a reminder went out. Write the theory down in plain sentences, the way you would explain it to whoever is on call next week:
Every hour the scheduler calls sendOverdueReminders(now).
It selects every open invoice whose dueAt is before now and emails each one.
Side effect: one email per selected invoice. Nothing is written back.
So an invoice that stays open is selected, and emailed, on every run.
A send that throws ends the loop; every invoice after it is skipped until the next run.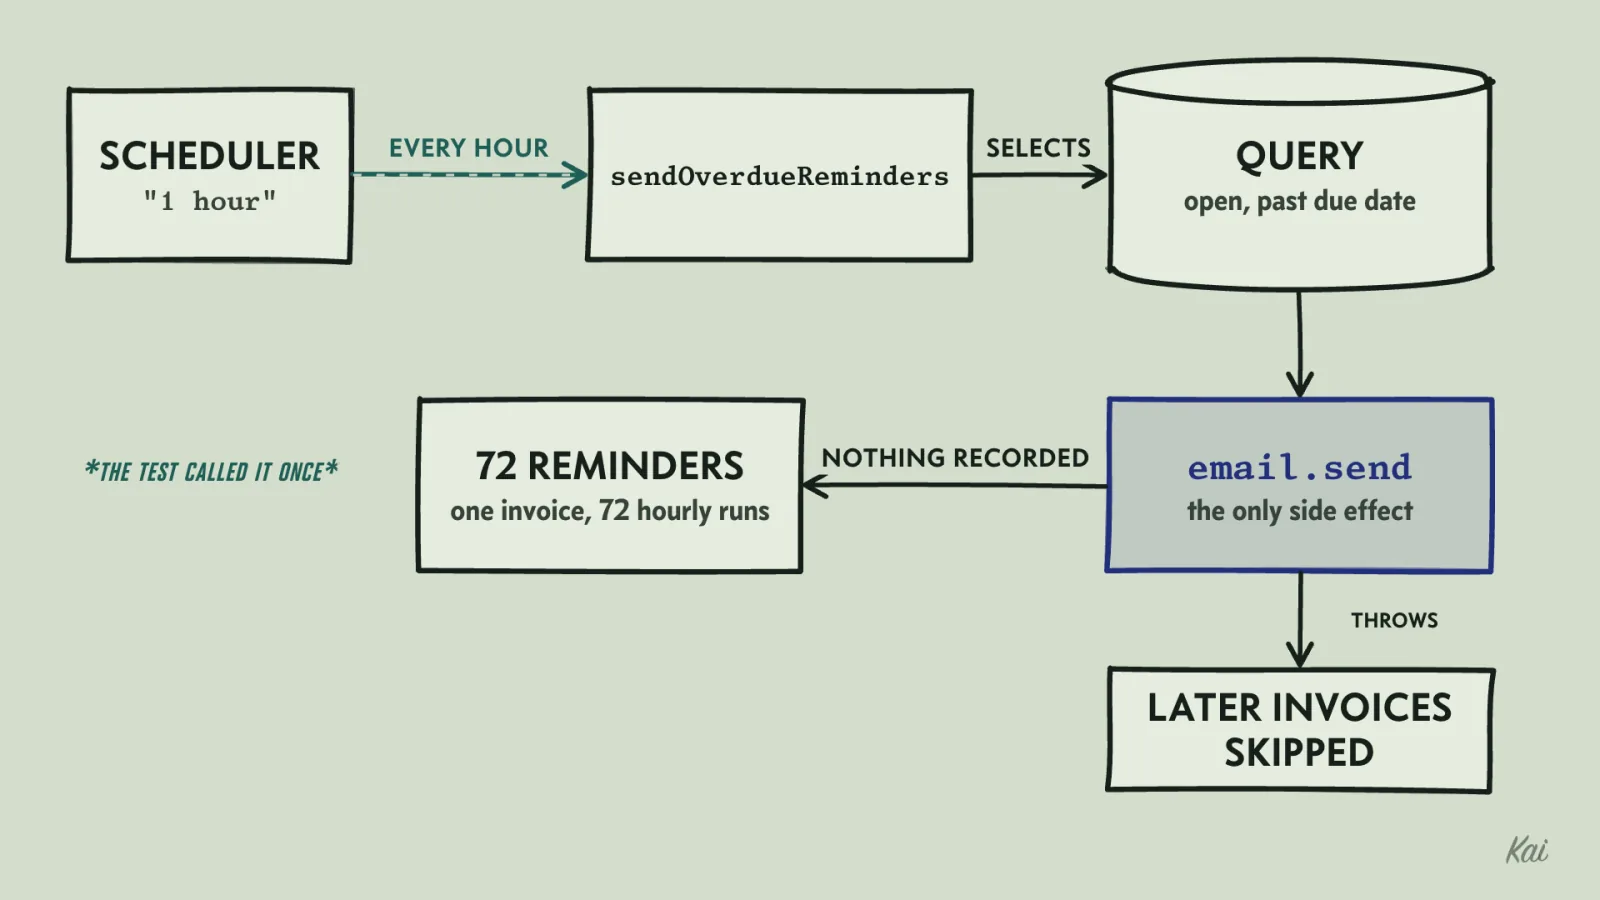
email.send is the only side effect, so with nothing recorded one invoice gets 72 reminders over 72 hourly runs. If one send throws, the job exits and every later invoice is skipped.The last two lines are predictions, and they come from the trace alone. Ask what happens when the job runs twice: the same invoices come back, and the same customers get a second email. For one invoice that stays open through 72 successful hourly runs, the job sends 72 reminders. If the query keeps returning a bad address early in its results, the customers behind it get no reminder at all. R1 through R4 still pass, and both behaviors reach real customers.
The theory also says where a change would go. If the product owner asks for "remind again after seven days", you need a recorded send time and a query that reads it. Being able to say that without asking the agent is the test of whether you understand what was built.
Turn the predictions into checks
A prediction you can run settles the question faster than one you argue about. The playground models the agent's job and a version that records each reminder and keeps going after a failed send. It runs three checks against both: the agent's R1 test, and two checks written from your theory.
type Invoice = { number: string; email: string; dueAt: Date; reminderSentAt: Date | null };
type Job = (db: Invoice[], now: Date) => Promise<void>;

// In-memory stand-ins for the invoices table and the email provider.
const due = new Date("2026-10-01T00:00:00Z");
const HOUR = 3_600_000;
const at = (hours: number) => new Date(due.getTime() + hours * HOUR);
const invoice = (number: string, email: string): Invoice => ({ number, email, dueAt: due, reminderSentAt: null });
let sent: string[] = [];
let failed: string[] = [];
async function send(to: string): Promise<void> {
  if (!to.includes("@")) throw new Error(`rejected address ${to}`);
  sent.push(to);
}

// The agent's job, as traced: every open invoice past its due date gets an email.
const agentJob: Job = async (db, now) => {
  for (const inv of db.filter((i) => i.dueAt < now)) await send(inv.email);
};

// Records each reminder and keeps going after a failed send.
// This fixes sequential runs only; overlapping runs still need an atomic claim.
const recordedJob: Job = async (db, now) => {
  for (const inv of db.filter((i) => i.dueAt < now && i.reminderSentAt === null)) {
    try {
      await send(inv.email);
      inv.reminderSentAt = now;
    } catch (e) {
      failed.push(`${inv.number}: ${(e as Error).message}`);
    }
  }
};

// Each check returns true when the job does what the check expects.
const checks: [string, (job: Job) => Promise<boolean>][] = [
  ["agent's R1 test: one run, one email", async (job) => {
    await job([invoice("INV-1", "ana@example.com")], at(1));
    return sent.length === 1;
  }],
  ["three hourly runs: still one email", async (job) => {
    const db = [invoice("INV-1", "ana@example.com")];
    for (let h = 1; h <= 3; h++) await job(db, at(h));
    return sent.length === 1;
  }],
  ["a bad address: the next customer still hears", async (job) => {
    const db = [invoice("INV-1", "ana@example.com"), invoice("INV-2", "not-an-address"), invoice("INV-3", "kim@example.com")];
    await job(db, at(1)).catch(() => {});
    return sent.includes("kim@example.com");
  }],
];

for (const [name, job] of [["agent's job", agentJob], ["recorded job", recordedJob]] as const) {
  for (const [label, check] of checks) {
    sent = [];
    failed = [];
    console.log(`${name.padEnd(13)} ${(await check(job)) ? "pass" : "FAIL"}  ${label}`);
  }
}
Output
The agent's job passes its own test and fails both checks your theory produced. The recorded job passes all three. Recording each reminder fixes sequential runs only. Overlapping runs and a crash between the send and the record can still duplicate an email, so the full fix also claims each invoice atomically before sending and passes an idempotency key to the email provider where it supports one.
What you do next goes through the ideal state. Add the missing criteria, such as "R5: an invoice gets at most one reminder in any seven days" and "R6: a failed send for one invoice still lets every other reminder go out", each with its check, and hand them back to the agent. The agent writes the fix, and it lands against checks that will catch the same mistake in every later version.
Where criteria cannot reach
With the checks read and the theory written, rank what is left by two things: whether a check covers it, and whether a mistake there is cheap to undo or expensive or one-way.
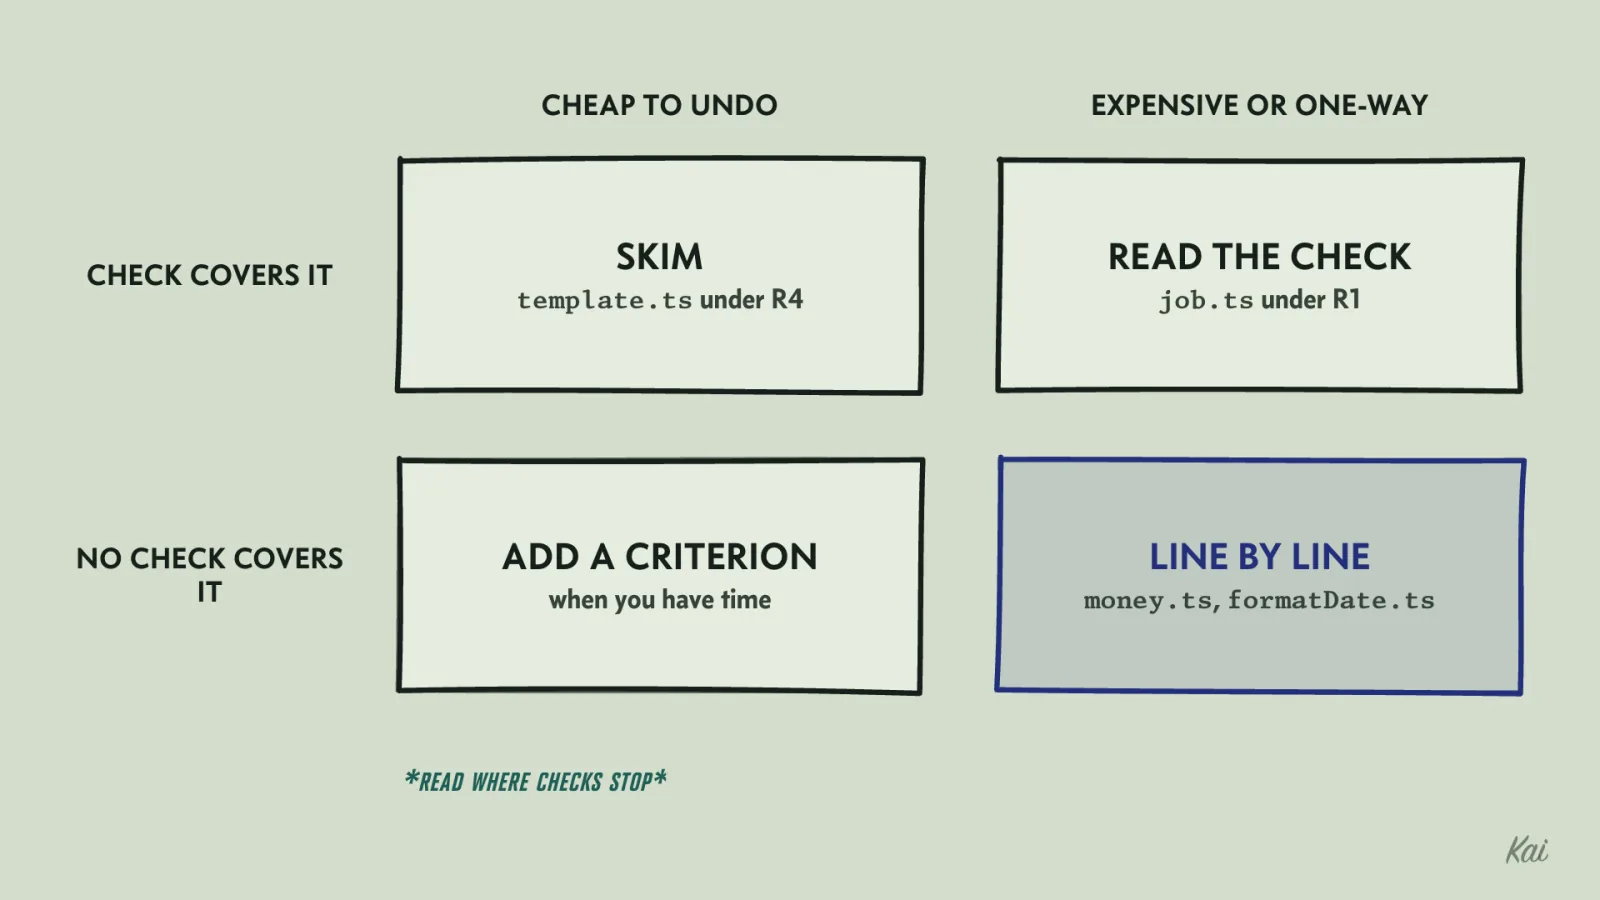
A part a check covers, where a mistake is cheap to undo, gets a skim; the email's wording under R4 is one, and you read the rendered email. A part a check covers, where a mistake is expensive, gets its check read closely, and every line too if the check turns out weak, because a weak check there gives false confidence. A part no check covers, where a mistake is cheap, earns a new criterion when you have time. A part no check covers, where a mistake is expensive or one-way, gets read line by line now.
| Part | Covered by | Cost of a mistake | How to read it |
|---|---|---|---|
job.ts query and send loop |
R1, weakly | Repeated or missing emails; a sent email cannot be recalled | Every line |
money.ts default parameter |
No criterion | Wrong amounts shown across the product | Every line, plus every caller |
formatDate.ts |
No criterion | Wrong due date in customer emails | Every line |
template.ts wording and layout |
R4 | Awkward copy, fixed next week | Skim, then read the rendered email |
schedule.ts registration |
R3 | Job runs at the wrong interval | Every line; it is three lines |
About 40 of the 500 lines decide whether the feature is safe. Most of the rest is template markup and test setup that the checks already exercise, and spending your line-by-line attention there while the send loop goes unread is the expensive mistake.
Security sits in the expensive column every time. This change touches no permission check, no secret and no input that reaches a query or a shell. If it did, that hunk would be read line by line whatever the checks say, because a missing authorization check passes every test that logs in as the owner.
The code the diff does not show
money.ts is outside the task, so none of the four criteria can see it. Here is what changed there, and the snapshot the agent updated:
-export function formatMoney(amount: number, currency: string): string {
+export function formatMoney(amount: number, currency: string, showCurrency = false): string {
   const n = amount.toLocaleString("en-US", { minimumFractionDigits: 2, maximumFractionDigits: 2 });
-  return `${currency} ${n}`;
+  return showCurrency ? `${currency} ${n}` : n;
}- <td class="total">USD 1,250.00</td>
+ <td class="total">1,250.00</td>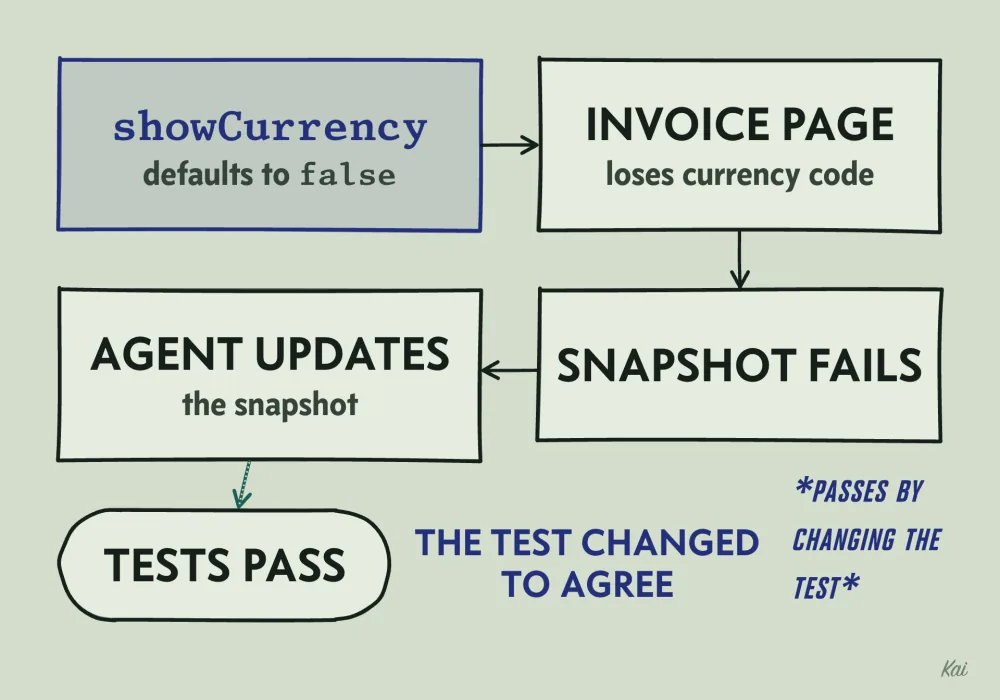
showCurrency parameter defaults to false, so the invoice page loses its currency code and its snapshot test fails. The agent updated the snapshot to match, and the tests pass because the test was changed to agree with the new behavior.The agent wanted amounts without a currency code in its email template and added a parameter to get them. The default is false, so every existing caller that passes two arguments now gets the bare number. The invoice page lost its currency code, its snapshot test failed, and the agent updated the snapshot to match. The tests pass because the test was changed to agree with the new behavior.
A changed test for code outside the task is a question to settle first: did the task ask for this output to change? Here it did not. A diff shows the lines that changed and leaves out the lines that depend on them, so search for the callers. The results include the definition in src/lib/money.ts; the caller matches are excerpted here:
$ git grep -n "formatMoney(" -- src
src/invoices/page.ts:41:      formatMoney(inv.total, inv.currency)
src/invoices/pdf.ts:88:       formatMoney(line.amount, inv.currency)
src/billing/receipt.ts:23:    formatMoney(payment.amount, payment.currency)
src/reminders/template.ts:30: formatMoney(inv.total, inv.currency, false)
Three callers outside the task changed behavior, and one of them is covered by the snapshot the agent rewrote. The fix is a default of true, or a separate function for the email. Say so in your reply to the agent, and add a criterion to the invoice page's ideal state that every amount it shows carries its currency.
The same search finds duplicates. The new formatDate.ts is a second date-formatting helper next to the existing one, with different time-zone handling. It formats with toISOString, which always gives the UTC date, while the invoice page uses formatInZone(d, timeZone) from src/lib/dates.ts, which gives the date on the customer's own calendar. For a customer in Tokyo whose invoice is due at local midnight on 15 October, the stored instant is 2026-10-14T15:00:00Z: the invoice page says the 15th and the reminder says the 14th. When a change adds a small utility for dates, money, strings, retries or paths, look for the one the project already has. Deleted lines deserve the same attention as added ones, since a removed check or a removed await changes behavior as much as new code does.
Claims and their evidence
The report says all four criteria pass on commit 7c1e0b2. git rev-parse --short HEAD prints 9f3a4d1. The agent's transcript shows one more edit after its run: it reworded a sentence in the email body. Run the checks on the head commit and R4's judge still passes, but one test in job.test.ts fails, because it checks for the old sentence.
The claim was true of an earlier commit and was carried forward into the report unchanged. Treat a claim that something passes as evidence only when it names the command, shows the output and ran on the exact commit you are looking at. A green CI run on that commit qualifies, and so does a run you start yourself.
Model reviewers share the blind spot
It is tempting to ask a second agent to review the first agent's work. A model reviewer adds a pass over all 500 lines and may catch typos, unused imports or a missing null check. Weigh each of its findings; its approval alone is weak evidence.
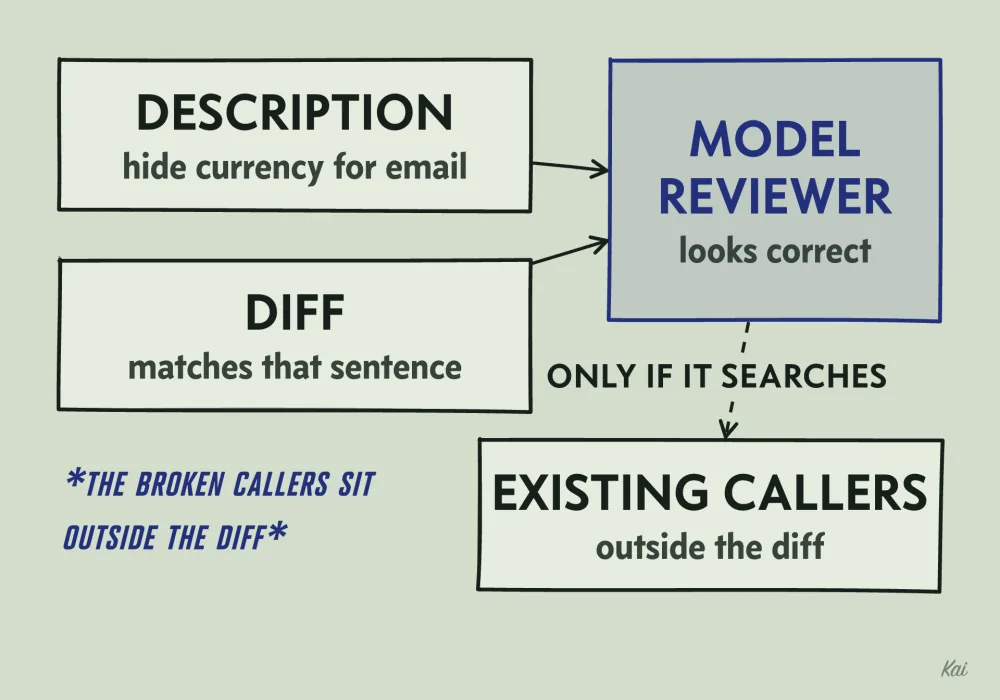
It is less likely to catch the defects above. The reviewing model reads the same diff and the same description. The description says formatMoney "now supports hiding the currency for email templates", and the diff matches that sentence, so the change looks intentional and correct. The callers that broke sit outside the diff, and the reviewer sees them only if it searches for them. When two models accept the same assumption from the same description, the second approval adds little evidence, and a reviewer from another vendor handed that description can share the assumption too.
Give a model reviewer a specific search, such as every caller of each changed shared function, and confirm from its report that it ran it. Do the reading that builds the theory yourself, because an agent's summary of the code is one more description, and the theory has to live in the head of the person who will run the system and change it.