
The price of the next change
An agent adds gift wrapping to your checkout. The feature is small: each wrapped item costs $3.50. The diff that comes back has a GiftWrapPricingProvider interface, a StandardGiftWrapPricing class that implements it, a GiftWrapPricingFactory that builds the class, and a loader that reads the $3.50 from a JSON config file. The tests pass and the feature works.
In the same diff, the agent needed the free-shipping rule to show a shipping line in the order confirmation email, so it wrote the rule again in the email module. Checkout and invoicing already had their own copies, so there are now three.
Nothing here is a bug today. The problem shows up in six months, when someone changes the shipping threshold and one copy doesn't get the update, or when someone has to read four files to find out what gift wrapping costs.
What complexity is
John Ousterhout, in A Philosophy of Software Design, defines complexity as whatever makes a program hard to understand or hard to change. The definition is useful because you can test it. Pick a likely change, such as "free shipping now starts at $75", and count how many places you would have to find, read and edit to make it safely. The more places, and the harder they are to find, the more complex the code is with respect to that change.
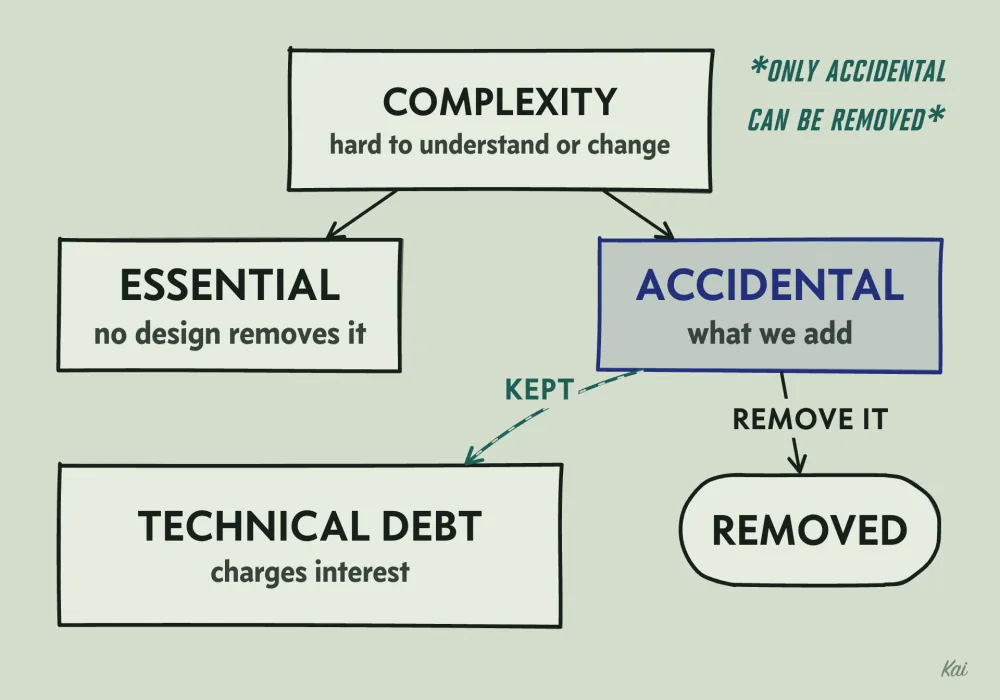
Fred Brooks split this difficulty in two. Essential complexity comes from the problem itself: tax law has cases, shipping has zones, refunds have deadlines, and no design makes those rules go away. Accidental complexity is what we add while solving the problem: layers nobody needed, rules written twice, names that hide what a function does.
You can only remove the accidental kind. Technical debt is accidental complexity that stays in the code, either kept on purpose to ship sooner or discovered later. Like financial debt, it charges interest: every later change that touches that code costs a little more, and the cost repeats on every change until someone pays down the principal.
Taking on debt on purpose can be the right call. The trouble with agent-written code is debt you take on without noticing, because the agent adds it without mentioning it.
Coupling and cohesion
Two parts of a program are coupled when a change to one forces a change to the other. Some coupling is unavoidable, because code that cooperates has to agree on something. The goal is to make each agreement explicit and to keep it in one place.
Cohesion is the other side. A module is cohesive when the things inside it change for the same reason. A shipping module that holds the threshold, the flat fee and the function that combines them is cohesive: when shipping policy changes, you open one file. A module that holds date formatting, money rounding and a database connection has low cohesion, because those three things change for unrelated reasons and share a file only by accident.
David Parnas made the underlying argument in 1972. Build each module around a design decision that is likely to change, and hide that decision inside the module, so that code elsewhere depends only on what the module promises. The free-shipping threshold is exactly that kind of decision. The rest of the program should be able to ask "what does shipping cost for this subtotal?" without knowing the threshold exists.
A rule written three times
Here are the three copies of the shipping rule, as they might look after a few months of agent-assisted work.
// checkout.ts
export function shippingFee(subtotalCents: number): number {
  return subtotalCents >= 5000 ? 0 : 599;
}

// invoice.ts
function shippingLine(subtotalCents: number): number {
  if (subtotalCents >= 5000) return 0;
  return 599;
}

// order-email.ts
const shippingCents = order.subtotalCents > 5000 ? 0 : 599;
Read the third line closely. It uses > where the other two use >=. A customer whose cart is exactly $50.00 sees free shipping at checkout, sees free shipping on the invoice, and gets an email saying they paid $5.99. The copies already disagree, and no test caught it because each copy has its own tests, or none.
Now the business raises the threshold to $75. Someone searches for 5000, finds checkout.ts, and changes it. The invoice still says shipping is free on a $60 order, while checkout charged $5.99. Duplicated rules drift this way because the second and third copies depend on someone remembering they exist.
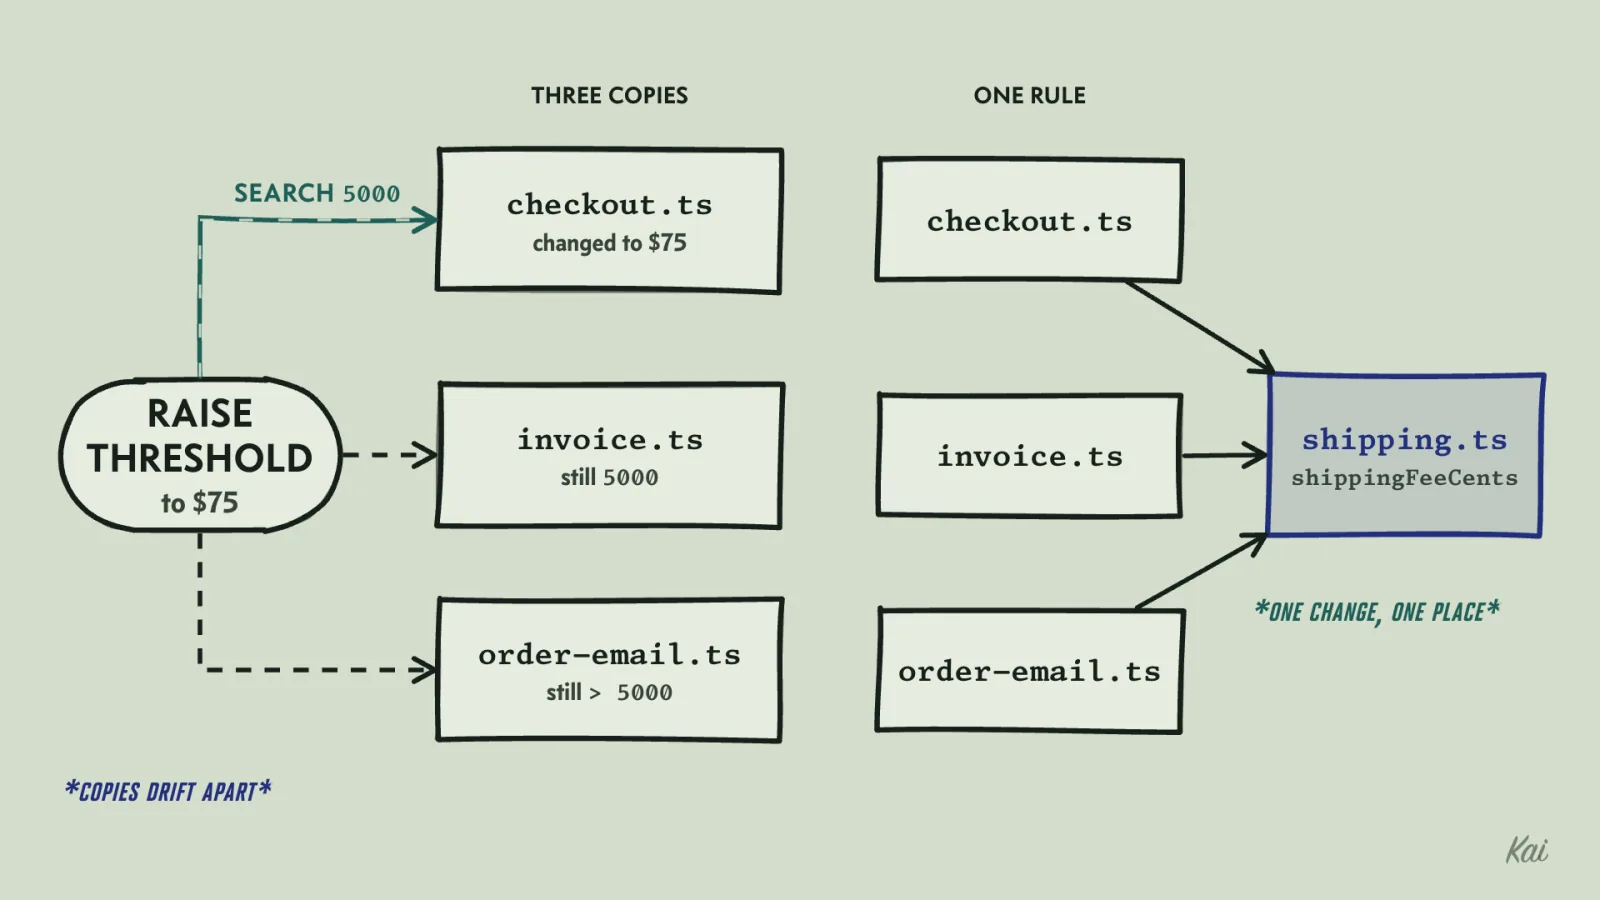
The fix is to move the rule to one place and have every caller use it.
// shipping.ts
export const FREE_SHIPPING_THRESHOLD_CENTS = 5000;
export const FLAT_SHIPPING_CENTS = 599;

export function shippingFeeCents(subtotalCents: number): number {
  return subtotalCents >= FREE_SHIPPING_THRESHOLD_CENTS ? 0 : FLAT_SHIPPING_CENTS;
}
A refactor is a change to structure that leaves behavior alone. Tests that pass before and after are evidence that the behavior they cover stayed the same, and they say nothing about what they do not cover. Write the test first, against the current code, at the values where the rule could flip: just under the threshold, exactly on it, and just over it.
import { test, expect } from "bun:test";
import { shippingFeeCents } from "./shipping";

const cases: Array<[number, number]> = [
  [0, 599],
  [4999, 599],
  [5000, 0],
  [5001, 0],
];

for (const [subtotal, fee] of cases) {
  test(`subtotal ${subtotal} cents ships for ${fee} cents`, () => {
    expect(shippingFeeCents(subtotal)).toBe(fee);
  });
}
Run the same four cases against each old copy before you delete it.
// The three copies, as they are today.
const checkout = (subtotalCents: number) => (subtotalCents >= 5000 ? 0 : 599);
const invoice = (subtotalCents: number) => {
  if (subtotalCents >= 5000) return 0;
  return 599;
};
const orderEmail = (subtotalCents: number) => (subtotalCents > 5000 ? 0 : 599);

const cases: Array<[number, number]> = [
  [0, 599],
  [4999, 599],
  [5000, 0],
  [5001, 0],
];

for (const [name, fee] of Object.entries({ checkout, invoice, orderEmail })) {
  const wrong = cases
    .filter(([subtotal, expected]) => fee(subtotal) !== expected)
    .map(([subtotal, expected]) => `${subtotal} gives ${fee(subtotal)}, expected ${expected}`);
  console.log(name.padEnd(10), wrong.length === 0 ? "passes" : `fails: ${wrong.join("; ")}`);
}
Output
The checkout and invoice copies pass. The email copy fails at 5000, where it returns 599. That failure is the useful result: merging the copies changes what the email says for a $50.00 order, so this is a behavior change, however small, and a person has to decide which answer is correct.
Make that decision in its own commit, then do the pure structural move in another. When a single diff mixes "moved code" with "changed what the code does", a reviewer can't tell which lines are which.
When two copies should stay two copies
Merging duplicates is right when the copies express the same rule. It is wrong when they only look alike.
Suppose the loyalty program gives members a bonus when they spend $50 in a month. That code might read if (monthlySpendCents >= 5000), identical in shape to the shipping rule. An agent looking for duplication will happily extract isOverFiftyDollars() and point both callers at it.
Now shipping policy and loyalty policy share a function, and the day marketing moves the loyalty bonus to $40, someone either changes shipping by accident or adds a parameter to the shared helper. After a few rounds of that, the helper has flags for every caller and nobody can say what it does.
Sandi Metz put the trade-off in one line: "duplication is far cheaper than the wrong abstraction." The question that separates the two cases is whether the copies can change independently. Ownership is a clue, so ask who decides the value. If the same person, following the same policy, would always change both copies together, they are one rule and belong in one place. If two different people own them, they are two rules that happen to share a number, and they should stay apart.
Layers for a feature that has one case
Back to gift wrapping. Here is roughly what the agent wrote.
interface GiftWrapPricingProvider {
  priceCents(itemCount: number): number;
}

class StandardGiftWrapPricing implements GiftWrapPricingProvider {
  constructor(private readonly perItemCents: number) {}
  priceCents(itemCount: number): number {
    return itemCount * this.perItemCents;
  }
}

class GiftWrapPricingFactory {
  static create(config: { perItemCents: number }): GiftWrapPricingProvider {
    return new StandardGiftWrapPricing(config.perItemCents);
  }
}

// elsewhere: GiftWrapPricingFactory.create(loadConfig("gift-wrap.json"))
Each piece exists so that some future second implementation could be swapped in. There is no second implementation, and nobody has asked for one. The whole thing does one multiplication.
const GIFT_WRAP_PER_ITEM_CENTS = 350;

export function giftWrapCents(itemCount: number): number {
  return itemCount * GIFT_WRAP_PER_ITEM_CENTS;
}
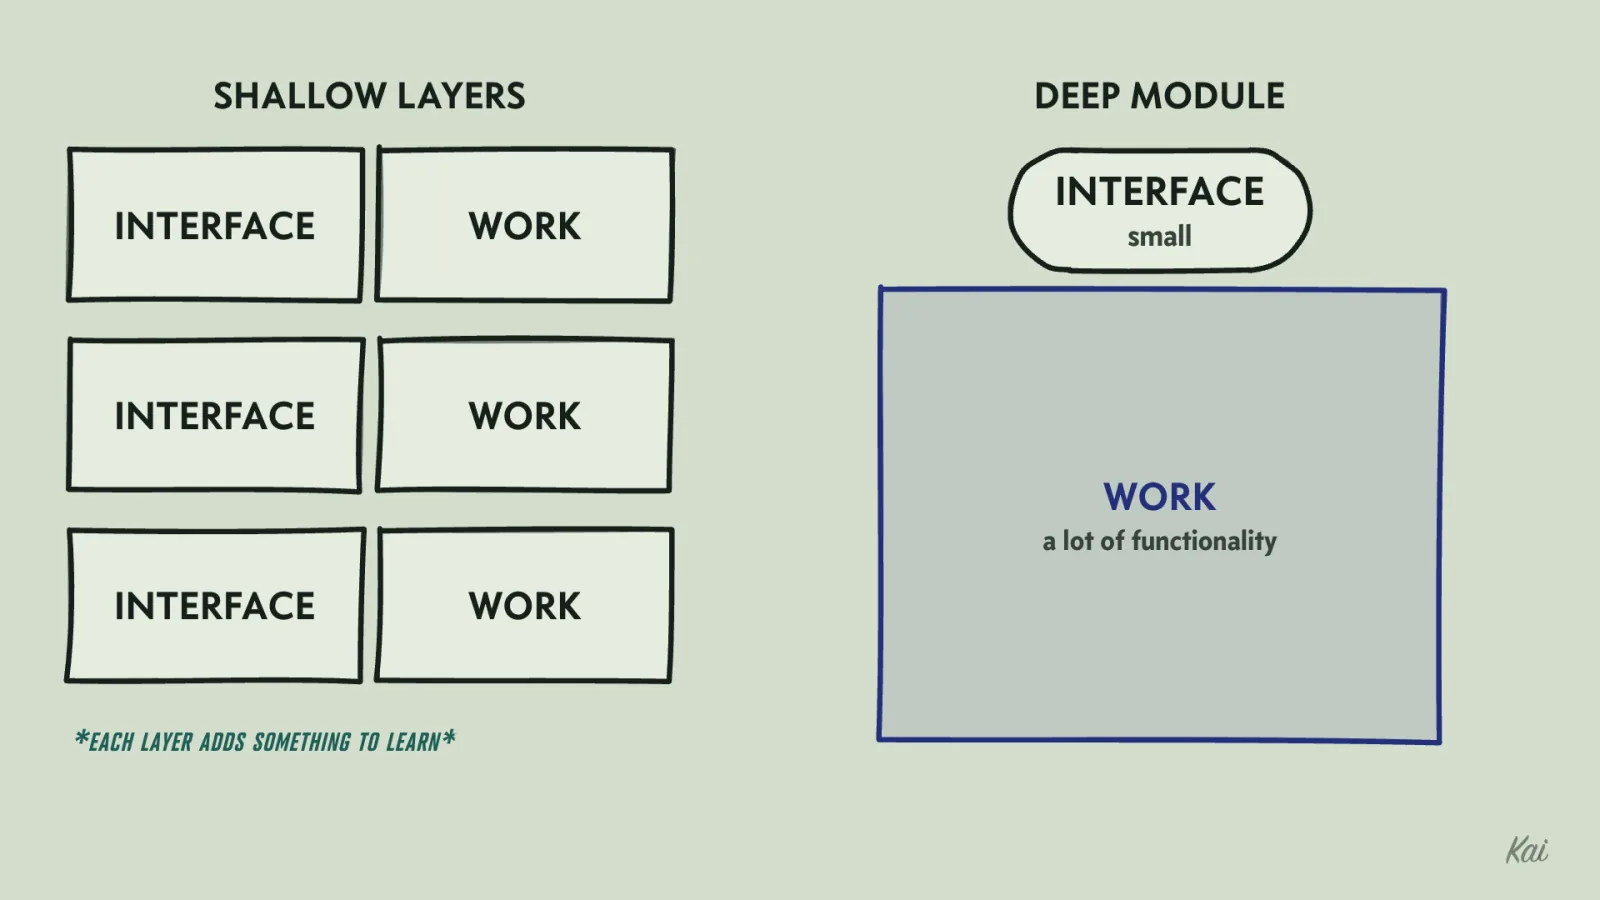
Ousterhout calls the first version shallow: its interfaces are about as large as the work behind them, so each layer adds something to learn and hides almost nothing. A deep module is the opposite, a small interface over a lot of functionality. A reader of the shallow version has to open four files to learn that wrapping costs $3.50 per item.
The principle behind the deletion is often called YAGNI, "you aren't gonna need it": build for the requirements you have, and add generality when a second real case shows up. When it does, you'll know what actually varies between the two cases, which is information you don't have when you guess in advance. Adding an interface to a one-function module later takes minutes.
Before deleting a layer, ask what it does that the simpler version would not. The config loader is the piece to check carefully.
If operations staff edit gift-wrap.json in production to change the price without a deploy, the loader is a real requirement and the constant would break their workflow. If the file is only ever changed through a code commit, the loader adds a file read and a failure mode and buys nothing. To find which is true, look at where the file is deployed, at its history, and at everything else that reads it, such as build scripts and other tools, before replacing it with a constant.
The module everything imports
Agents like to create utils.ts and add to it whenever a small function has no obvious home. After a while it holds formatDate, roundMoney, slugify, retryFetch and getDbConnection, and nearly every file in the project imports it.
That file now couples unrelated parts of the system. If getDbConnection opens a connection pool when the module loads, then a unit test for slugify needs database credentials to run.
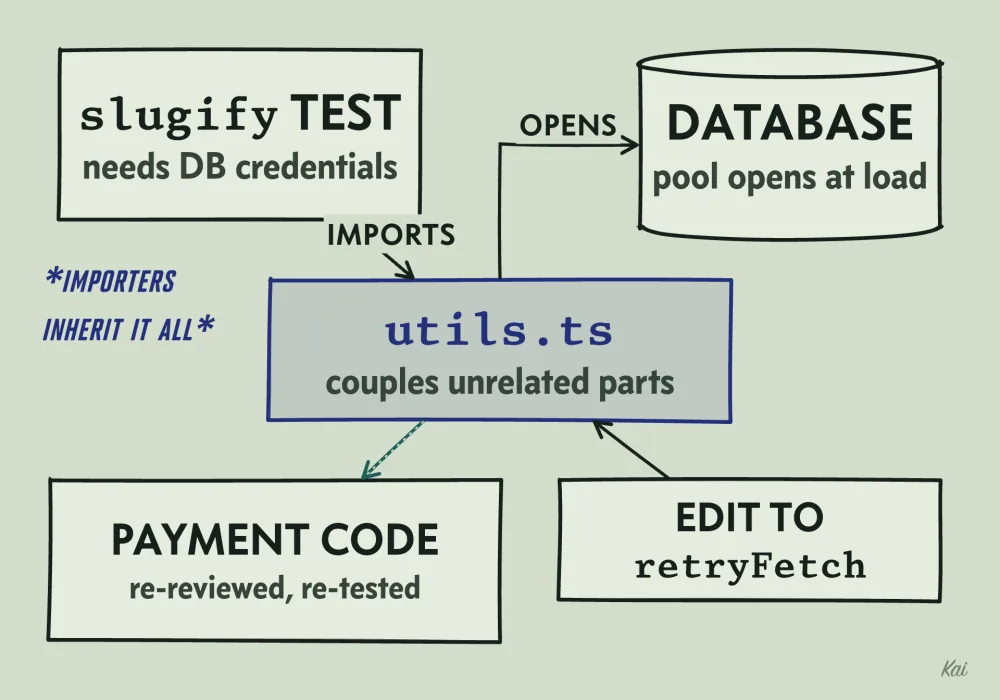
utils.ts inherits whatever it does. The slugify test needs database credentials because of a pool opened at load, and an edit to retryFetch puts the payment code back under review.A change to retryFetch shows up as a change to a file that the payment code imports, so the payment code has to be re-reviewed and re-tested for an edit it never cared about. The question that exposes a module like this is simple: what do the functions in it have in common, other than being small? If the honest answer is nothing, each function should move next to the code that uses it, and roundMoney probably belongs in a money module with the other money rules.
You can find the most tightly coupled module in a codebase with two measurements. The first is how many files depend on a module. This command counts the files that import utils; run it once for each candidate module and compare the counts:
grep -rlE "from ['\"].*/utils['\"]" src | wc -lThe second ranks files by how often they changed, since a module many files depend on is riskiest when it changes often. A stable one can still hurt through its load-time side effects, like the connection pool above:
git log --since="6 months ago" --name-only --format= -- src \
  | sort | uniq -c | sort -rn | head -20
A module with a high import count that also sits near the top of the change list is where changes spread. For that file, name the specific changes it makes hard: which edits force a re-test of unrelated features, and which teams have to coordinate before touching it.
Names that say everything the function does
The last tell is the name. Here is a helper an agent might write while building an order form.
async function processData(order: OrderInput): Promise<Order> {
  if (order.items.length === 0) throw new Error("order has no items");
  if (order.items.some((item) => item.qty <= 0)) throw new Error("bad quantity");
  return db.orders.insert(order);
}
Later, a different task asks for a "check my order" button that validates the cart before payment. The agent searches for existing validation, finds processData, sees that it throws on bad input, and calls it. Every click on "check my order" now inserts an order into the database. The name gave no hint that the function writes anything.
Split it into two functions whose names state their effects.
function validateOrder(order: OrderInput): void {
  if (order.items.length === 0) throw new Error("order has no items");
  if (order.items.some((item) => item.qty <= 0)) throw new Error("bad quantity");
}

async function saveOrder(order: OrderInput): Promise<Order> {
  validateOrder(order);
  return db.orders.insert(order);
}
The test for a name is whether a caller can predict every side effect from the name alone. Words like process, handle, manage and data fail that test because they fit any function. This matters more with agents in the loop, because an agent chooses which function to call largely by reading names, the same way the one that wrote "check my order" did.
The rule
For any diff, pick the next change you expect the business to ask for and count the places it would touch. If a single policy lives in more than one file, or a single file mixes policies that change for different reasons, or a layer exists for a case that doesn't exist yet, the diff made that count go up, and you can point to the exact lines that did it.