
Writing Down What Done Means
An agent finishes an export feature and reports it done. The tests pass. Two weeks later a customer writes in: their export is missing forty projects. The projects are archived, and the export query filters on archived = false because the list screen does. Nobody decided that archived projects should be left out of an export. Nobody decided they should be included either. The agent had to pick one, and it copied the nearest existing query.
The code is correct for a requirement the customer never had, and the one they did have was never written down. Agent-built features often fail this way: the agent builds exactly what the words allow, and the words allow more than one thing.
A requirement turns intent into a statement you can check. An acceptance criterion is a requirement sharp enough that a test, a reviewer or an agent can say pass or fail without having to interpret it. In a written ideal state these are its criteria, listed under the prose that says what you want. When criteria exist before the work starts, "done" means every criterion passes. Without them, the only signal of done is that the agent stopped working.
What a requirement has to pin down
Requirements come in two kinds, and a vague brief usually states only the first.
Functional requirements say what the system does. "The export includes every project the user can see." "Submitting an order charges the card and sends a confirmation email."
Quality requirements say how well it must do it. These cover speed, availability, cost, accessibility and security. "Search returns results in under 300 ms at the 95th percentile." "The export for an account with 50,000 projects completes in under 60 seconds."
A quality requirement needs a condition someone can observe. For speed and capacity that is usually a number. For security it can be a yes-or-no statement. "Fast" and "secure" on their own are words every implementation can claim to satisfy, which means they rule nothing out.
The test for any requirement is simple. Could two reasonable implementations both claim to meet it while behaving differently in a way a user would notice? If so, the requirement is still ambiguous, and an agent will resolve the ambiguity for you, silently.
A vague requirement, worked all the way through
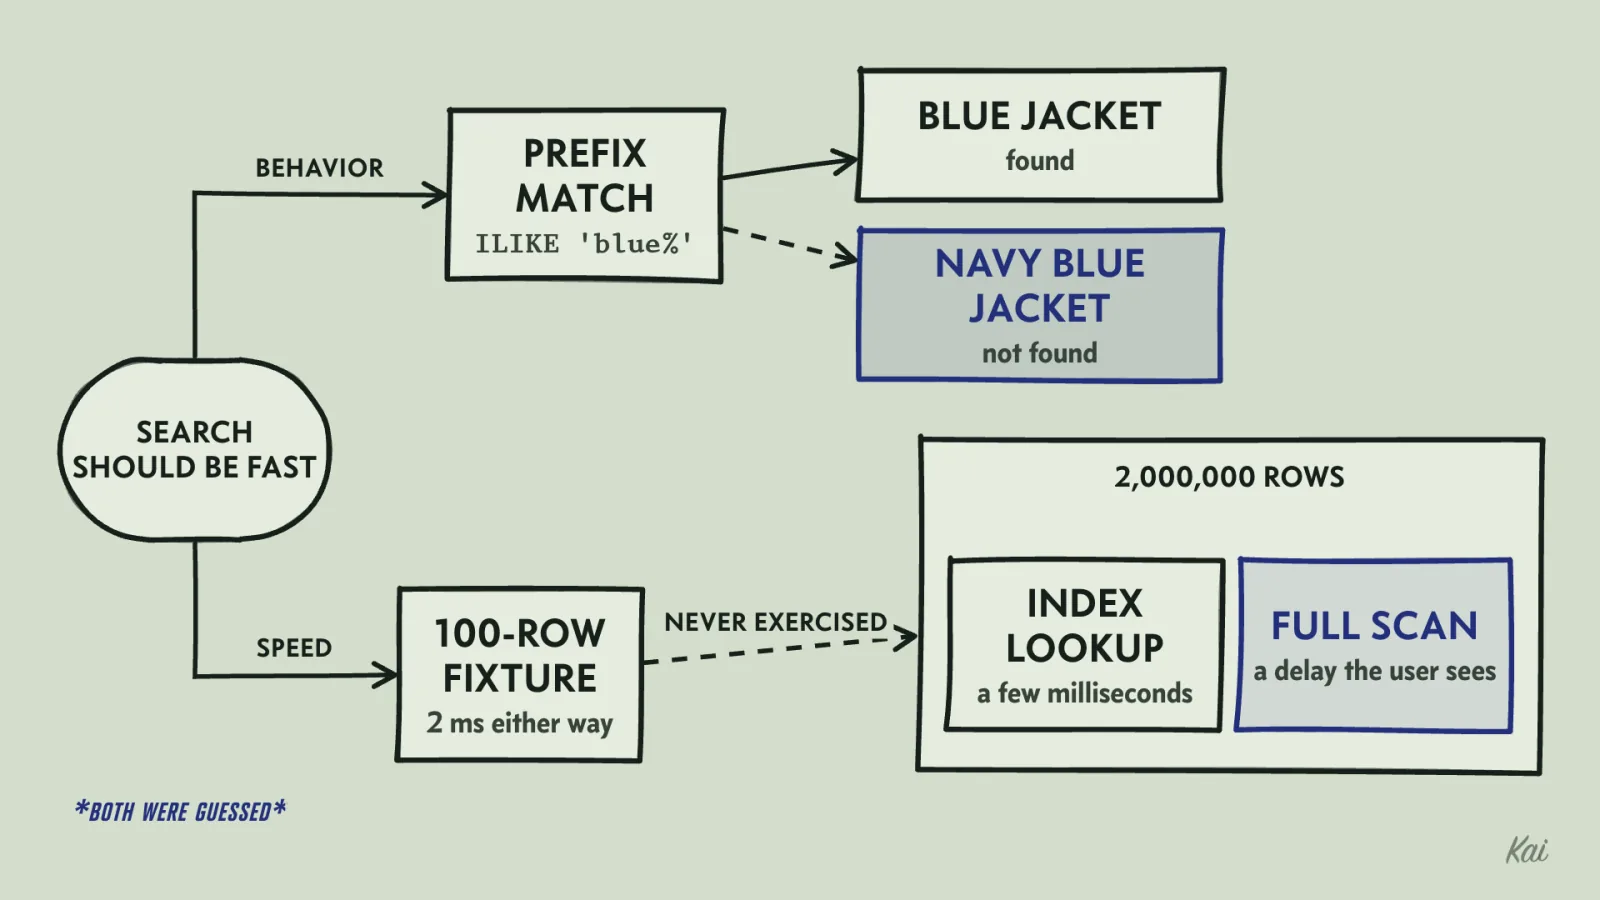
Take "search should be fast." An agent implements it as a prefix match:
-- Postgres; ILIKE ignores case
SELECT id, name FROM products WHERE name ILIKE 'blue%' ORDER BY name LIMIT 20;It tests the query against a fixture of 100 products, sees 2 ms, and reports that search is fast.
At 100 rows the database can scan the whole table in far less time than any user could notice, so the test cannot tell a query that uses an index from one that reads every row. Suppose the products table has 2 million rows. Now the difference between an index lookup and a full scan is the difference between a few milliseconds and a delay the user sees, and the fixture never exercised it.
There is a second problem hiding in the same line. A prefix match finds "Blue Jacket" but not "Navy Blue Jacket". The requirement never said whether a search term can match the middle of a name, so the agent chose the version that is easiest to make fast. Neither the speed nor the behavior was specified, so both were guessed.
A checkable version names the behavior, the threshold, the data size and the way it will be measured:
A search for a term returns products whose name contains that term anywhere, ignoring case. With 2,000,000 products loaded, the 95th-percentile response time of
GET /searchis under 300 ms, measured over 1,000 queries sampled from last month's search log, against a server of the production instance size.
Each part closes a door. "Anywhere, ignoring case" settles the prefix question. The 95th percentile makes slow outliers count, where an average would hide them. If 6 searches in 100 take four seconds and the rest take 50 ms, the average is 287 ms, under the threshold, while the 95th percentile is four seconds. "Sampled from last month's search log" stops someone from benchmarking with one convenient term. The data size stops the 100-row fixture from counting as evidence.
The nearest-rank 95th percentile is the value 95 places into the sorted list of times:
// 100 searches: most take 50 ms, a few take 4 seconds.
function summarize(slow: number) {
  const times = [...Array(100 - slow).fill(50), ...Array(slow).fill(4000)].sort((a, b) => a - b);
  const average = times.reduce((sum, t) => sum + t, 0) / times.length;
  const p95 = times[Math.ceil(0.95 * times.length) - 1];
  console.log(`${slow} slow: average ${average} ms, p95 ${p95} ms`);
}

summarize(6);
summarize(5);
Output
With five slow searches in 100, the 95th percentile drops back to 50 ms, because the threshold allows one search in twenty to be slow. If that is too many for your users, the requirement needs a 99th-percentile target as well.
The same move rescues most vague words. "The page should load fast" becomes a named metric, a threshold, a device or network condition and a way to measure it. "Secure" becomes specific statements about who may do what, such as "a request for another account's order returns 404 and reveals nothing about whether the order exists."
Criteria written as examples
Prose describes behavior in general terms, and general terms are where ambiguity lives. A concrete example with a specific input and a specific expected output is much harder to misread. This is the idea behind specification by example, and the Given/When/Then format from behavior-driven development is the usual shape:
Scenario: Archived projects are included in the export
  Given an account with 3 active projects and 2 archived projects
  When the owner requests a full export
  Then the export contains 5 projects
And each archived project has the column "status" set to "archived"Writing this forces the decision the export feature skipped. You cannot write "Then the export contains ..." without choosing a number, and choosing the number means choosing whether archived projects count. If the business isn't sure, you have found an open question before anyone wrote code, which is the cheapest time to find it.
Examples also expose combinations. When a behavior depends on more than one input, a small table of every combination shows which cases are still undecided. For the export, two yes-or-no inputs give four rows:
| Project archived | User is account owner | Included in export |
|---|---|---|
| no | yes | yes |
| yes | yes | yes |
| no | no, a member | yes, if the member can see it |
| yes | no, a member | ? |
The question mark in the last row is a real gap. A literal-minded agent will fill it with whatever the nearest code does. A person should fill it on purpose.
Edge cases are requirements too
Most acceptance criteria describe the path where everything goes right. Many production bugs come from inputs that are empty, duplicated, too large, malformed or simultaneous. Each of those needs a stated behavior, because "the obvious thing" differs between people and between agents.
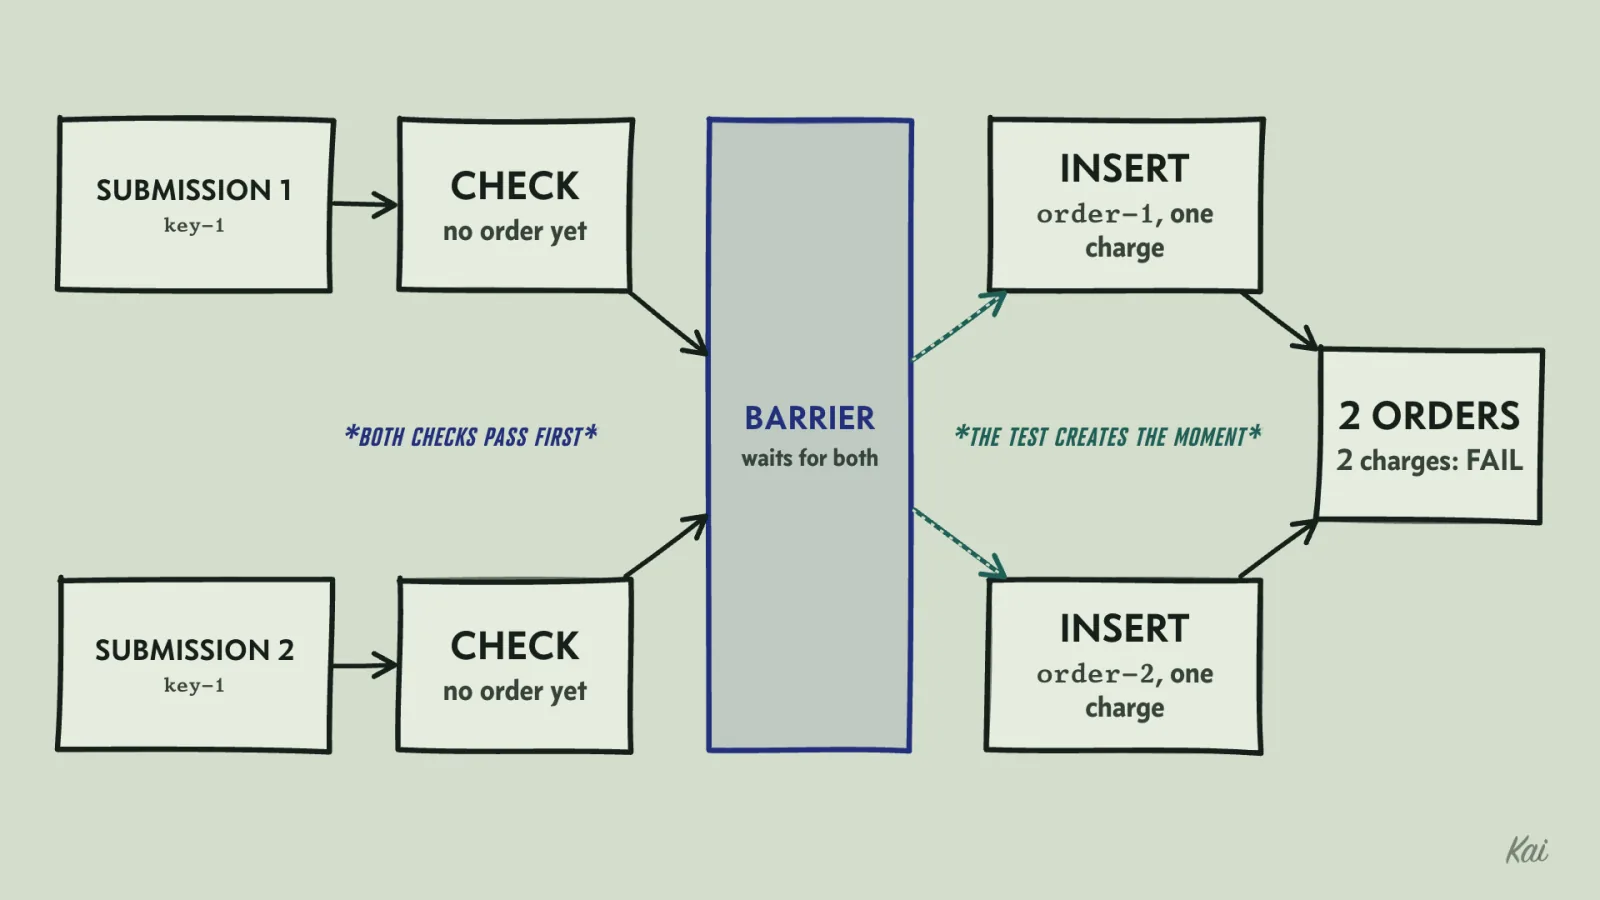
Consider an order form. A customer clicks Submit, the page is slow, and they click again. Two requests reach the server. If nothing was specified, the server does what it was built to do twice: two orders, two charges. The usual fix is an idempotency key. The browser creates one key for each intended order and sends it with every click and retry of that order. The server records the key with the order, and a second request with the same key returns the first order.
A criterion and a test for it:
Two submissions of the same cart with the same idempotency key, including two that arrive at the same moment, produce exactly one order and one charge, and both responses return the same order ID.
The test below runs against an in-memory stand-in for the order service, three times:
type Store = { orders: { id: string; key: string }[]; charges: number };
type Hooks = { beforeInsert?: () => Promise<void> };

// Checks whether an order with this key exists, then inserts one.
async function checkThenInsert(store: Store, key: string, hooks: Hooks) {
  const existing = store.orders.find((o) => o.key === key);
  if (existing) return existing.id;
  if (hooks.beforeInsert) await hooks.beforeInsert();
  const id = `order-${store.orders.length + 1}`;
  store.orders.push({ id, key });
  store.charges++;
  return id;
}

// Checks and inserts in one step, with no await between them. The hook runs
// first because there is no gap to put it in.
async function insertOrReturn(store: Store, key: string, hooks: Hooks) {
  if (hooks.beforeInsert) await hooks.beforeInsert();
  const existing = store.orders.find((o) => o.key === key);
  if (existing) return existing.id;
  const id = `order-${store.orders.length + 1}`;
  store.orders.push({ id, key });
  store.charges++;
  return id;
}

// Holds each caller until `parties` callers have arrived, then releases them together.
function barrier(parties: number) {
  let arrived = 0;
  let release!: () => void;
  const open = new Promise<void>((resolve) => (release = resolve));
  return async () => {
    if (++arrived === parties) release();
    await open;
  };
}

// The criterion: two submissions with one key give one order, one charge and the same order ID.
async function test(label: string, submit: typeof checkThenInsert, useBarrier: boolean) {
  const store: Store = { orders: [], charges: 0 };
  const hooks: Hooks = useBarrier ? { beforeInsert: barrier(2) } : {};
  const [first, second] = await Promise.all([submit(store, "key-1", hooks), submit(store, "key-1", hooks)]);
  const pass = first === second && store.orders.length === 1 && store.charges === 1;
  console.log(`${pass ? "PASS" : "FAIL"} ${label}: orders ${store.orders.length}, charges ${store.charges}`);
}

await test("check-then-insert, Promise.all only", checkThenInsert, false);
await test("check-then-insert, with barrier", checkThenInsert, true);
await test("insert-or-return, with barrier", insertOrReturn, true);
Output
The first run passes even though the code has the bug. The array expression calls both functions, and Promise.all only waits for their results. Calling both does not make them interleave. This fake has nothing to wait on between its check and its insert, so the first call finishes before the second begins, and the test passes against check-then-insert code that still breaks when both requests do the check before either inserts.
The barrier forces that order: both callers finish the existence check, then wait until both have arrived, and only then insert. The same code now makes two orders and two charges. The third version does the check and the insert as one step, and it passes with the barrier in place. The criterion said "at the same moment", so the test has to create that moment. This is how criteria and tests connect: every phrase in the criterion should map to something the test does.
In a real database, a unique index on the key only makes the second insert fail. Returning the existing order also takes conflict handling, such as an insert that falls back to reading the order when the key already exists. Charging needs its own guard too, such as charging only when the insert created the order.
For any form or endpoint, walk the same list and write one expected behavior per line:
- Empty: the cart has no items. The server returns 422 with a message, and no order is created.
- Duplicate: the same key arrives twice. One order, as above.
- Oversized: a quantity of 1,000,000. The server rejects any line above a stated maximum, say 100 units, with 422 and the limit in the message.
- Malformed: a quantity of "three" or -1. The server returns 400 and names the field.
- Simultaneous: two different customers buy the last unit at once. One succeeds and one gets an out-of-stock response.
Each line is short, and each line is a decision the agent would otherwise make for you.
Every criterion carries its eval
Write each criterion with its eval, the check that will judge it, beside it. Pick the cheapest check that could prove the criterion false. If none could, the criterion is unfinished: "customers are told when their order ships" needs who gets what, through which channel and within how long. An assert, plain code comparing a result with an expected value like the order test above, comes first. Where code cannot judge, as with whether an error message tells a customer what to do next, a fast model answers a few yes-or-no questions about the output. A judge, a stronger model scoring against a rubric, is the last rung.
| Criterion | Cheapest check |
|---|---|
| An export of 3 active and 2 archived projects contains 5 projects | Assert |
p95 of GET /search is under 300 ms at 2,000,000 products |
Load test replaying the sampled log |
| The out-of-stock message tells the customer what to do next | Question set |
| The export never contains another account's projects | Assert, with a second account in the fixture |
The last row is an anti-criterion: something that must never happen. Agents usually break these as a side effect. A query copied from an admin screen, with no account filter, makes a complete export, and every criterion about what the export includes still passes. The test has to set up the forbidden case, here a second account with projects of its own.
When a build passes every criterion and you still would not ship it, the reason is a criterion nobody wrote. Write it with its eval and the build fails, which is the right result: from then on the eval catches that problem for you. Hill-climbing works this loop in full.
Reading a requirement the way an agent will
The skill that ties this together is reading a requirement with no charity at all. A literal reader asks, of every word, "what else could this mean?"
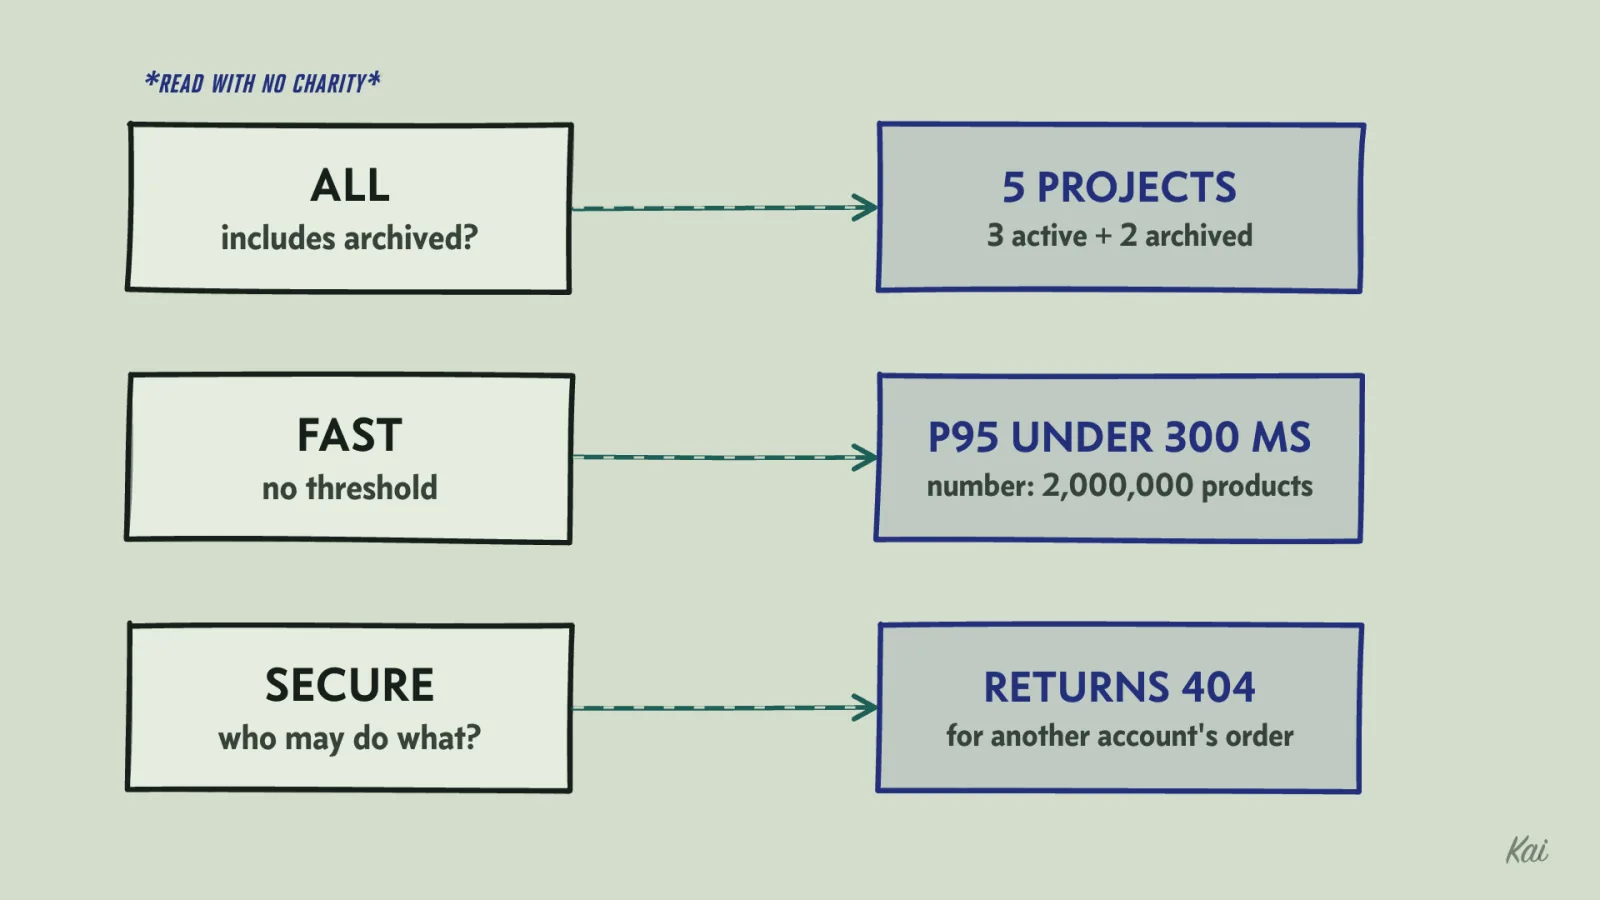
Some words are almost always ambiguous. "All" hides whether it includes archived, deleted or other users' records. "Users" hides which role. "Fast", "secure", "simple" and "reliable" have no threshold. "Should" hides whether the thing is required or merely preferred. "Recent" and "large" have no number. "Handle errors" hides what the user sees. When one of these appears in a criterion, replace it with a number, a list or an example.
Templates help. Alistair Mavin's EARS patterns, such as "When [event], the [system] shall [response]", force you to name the trigger and the response, as Gherkin's Given/When/Then does. Neither makes a requirement correct; both make it harder to leave out the trigger, the condition or the expected result.
Spotting the gaps in an agent's criteria
When an agent hands you acceptance criteria, check each one against three questions.
Can it fail? A criterion that no implementation could violate, such as "the export works correctly", is a restatement of the goal. Look for the input that would make it fail.
Does it say what happens to the data you forgot about? Archived, deleted, shared, very old, very large, belonging to someone else. The export that dropped archived projects passed every criterion it was given, because none of them mentioned archived projects.
Does it say what happens when the input is wrong or doubled? Look for any mention of empty, duplicate, oversized, malformed or simultaneous input. If there is none, the double-click bug and its relatives are still open.
A criterion is ready when a person who has never seen the code can read it, run one test or make one observation, and say pass or fail, and a second person doing the same thing gets the same answer.