
What Happens Between Two Machines
An agent builds a dashboard page. The server that renders it calls an internal API twelve times, once per widget, each call waiting for the one before.
On your laptop, with the API running on the same machine, the page loads in 90 milliseconds. In production the API runs in a data center across the country, and the same page takes more than a second before the first widget appears. The code is identical in both places, and the whole difference is the distance to the API.
Every network call your code makes pays for a trip that is invisible in development, because in development the other machine is your own. To review networked code you need to know what that trip consists of, what it costs, and what each protocol along the way does and does not promise.
Packets and the speed of light
A network moves data in packets, small chunks of bytes with an address on the front. On a typical Ethernet link a packet carries at most about 1,500 bytes, so a 1 MB response travels as several hundred of them. Each packet carries the IP address of its source and destination, and every router on the way looks at the destination and forwards the packet one hop closer. Packets can be dropped when a router's queue is full, and they can arrive out of order.
Light in optical fiber covers about 200,000 kilometers per second, two thirds of its speed in a vacuum. New York to London is about 5,570 km, so a packet needs at least 28 ms one way and 56 ms for a round trip, before any router touches it. Real round trips on that route run around 70 to 80 ms because cables do not follow straight lines. Within one data center a round trip is well under a millisecond.
Bandwidth, the number of bytes per second a link carries, keeps getting cheaper. Round-trip time is set by distance and physics, and no purchase lowers it below the fiber limit. For most requests an application sends, the payload is small and the round trips dominate the total time.
From a name to a connection
Before your code can send anything to api.example.com it needs an IP address, and DNS supplies it. Your program asks a resolver, usually run by your network or cloud provider. If the resolver has no cached answer, it asks a root server which servers handle .com, asks one of those which servers are authoritative for example.com, and asks the authoritative server for the address.
$ dig api.example.com
;; ANSWER SECTION:
api.example.com.    300    IN    A    203.0.113.10
The 300 is the TTL, the number of seconds any resolver may cache this answer. When you change the record, resolvers that fetched it a minute ago keep serving the old address until their copy expires, and some clients cache it longer on their own. That is why a DNS change takes time to spread, and why you lower the TTL a day before a planned migration.
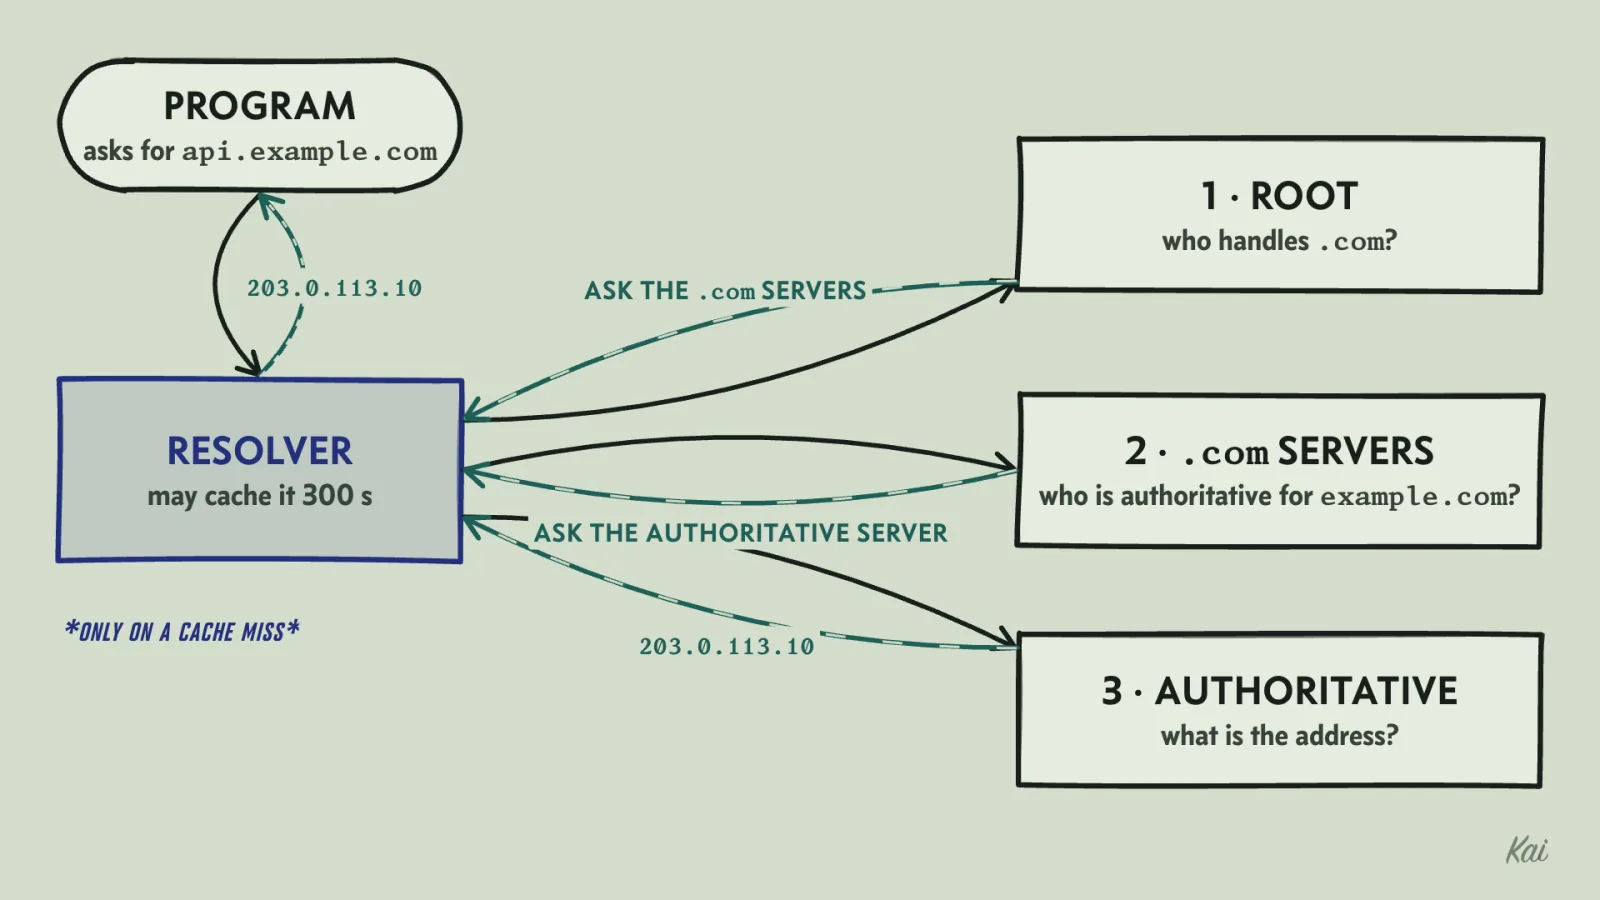
.com servers, then the authoritative server, one after another, and hands the address back to the program. It may keep the answer for 300 seconds.With an address in hand, the client opens a TCP connection. TCP turns unreliable packets into a reliable, ordered stream of bytes. It numbers every byte, the receiver acknowledges what it got, and the sender retransmits anything unacknowledged.
Setting up a connection takes a handshake: the client sends SYN, the server replies SYN-ACK, and the client sends ACK along with its first data. That costs one round trip before any request is sent.
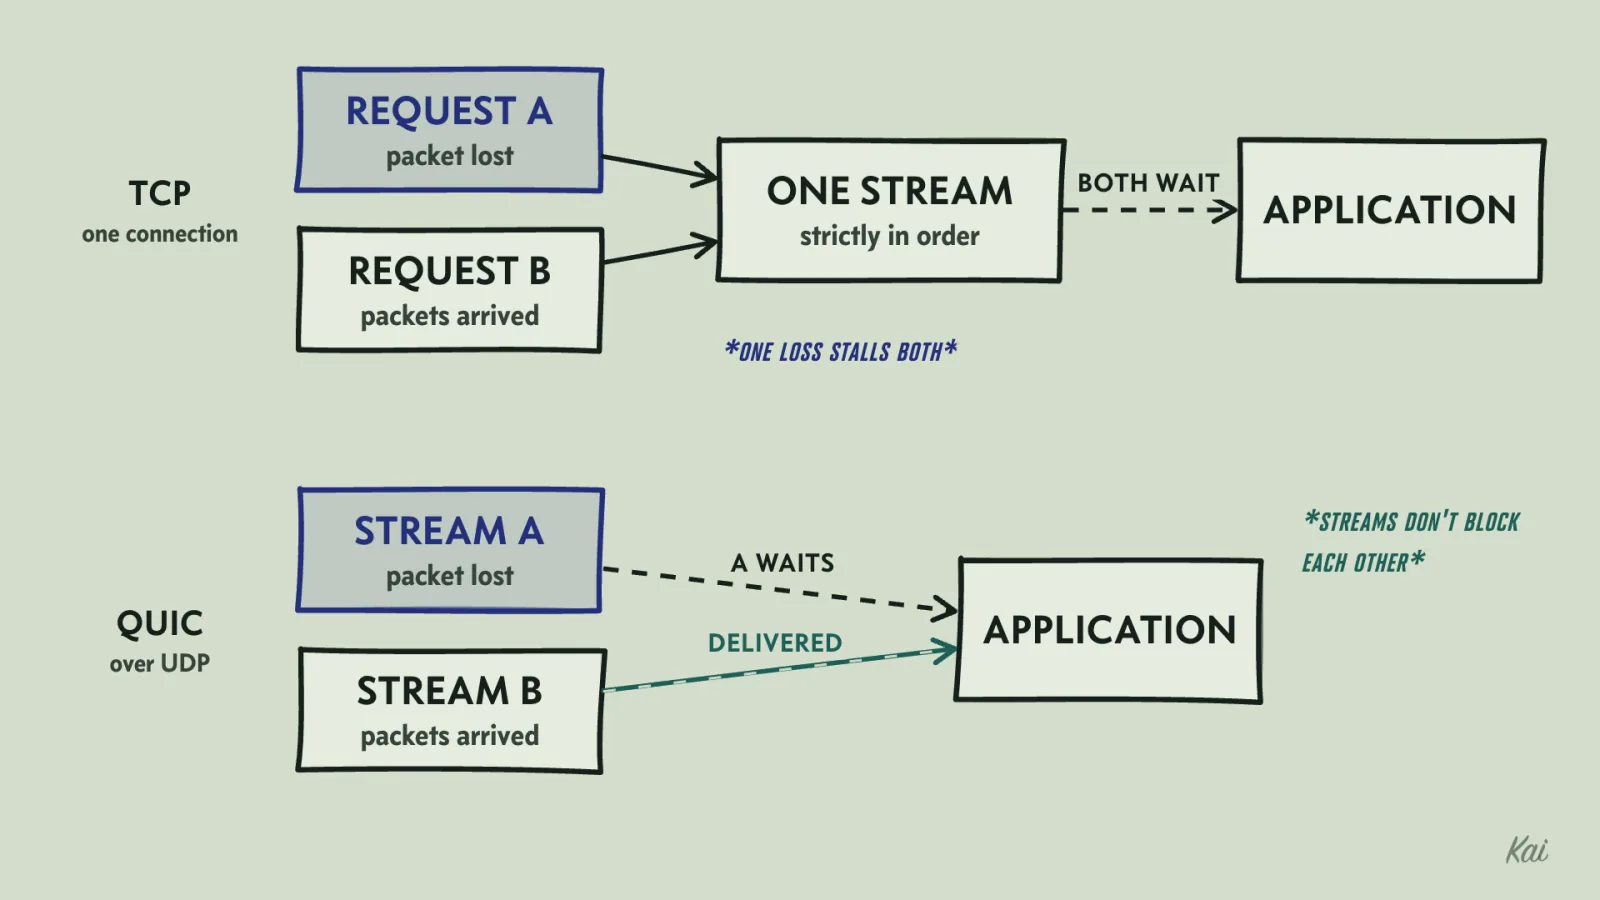
Reliability has a price. Because TCP delivers bytes strictly in order, one lost packet holds back every packet behind it until the retransmission arrives, even packets that belong to unrelated requests sharing the connection. This is called head-of-line blocking.
UDP is the other main transport: it sends individual datagrams with no handshake, no retransmission and no ordering, and the application handles loss itself. Video calls and games use it, and HTTP/3 runs over QUIC, a protocol built on UDP that keeps separate streams from blocking each other.
TLS: who you are talking to
For HTTPS, the client next runs a TLS handshake over the TCP connection. In TLS 1.3 this takes one more round trip (TLS 1.2 took two).
The handshake does two jobs. The two sides agree on encryption keys that no one watching the packets can learn. And the server proves its identity with a certificate: a statement that this public key belongs to api.example.com, signed by a certificate authority the client already trusts. The client checks the signature chain, the expiry date and that the name matches the host it meant to reach.
After that the connection has confidentiality (outsiders cannot read it), integrity (outsiders cannot change it without detection) and server authentication. TLS says nothing about what the server does with the data, and the IP addresses and usually the server name remain visible to anyone on the path.
Here is the fix an agent reaches for when it hits a certificate error.
const agent = new https.Agent({ rejectUnauthorized: false });
https.get("https://billing.internal/api/invoices", { agent }, onResponse);
Setting NODE_TLS_REJECT_UNAUTHORIZED=0 in the environment does the same for every connection the process makes. The traffic is still encrypted, but the client no longer checks who holds the other end of the key. Anyone who can intercept traffic on the path, on a hotel network, a misconfigured proxy or a compromised router, can present their own certificate, and the client will encrypt everything to them.
The error was reporting a real problem: an expired certificate, a missing intermediate certificate, a hostname mismatch, or a server signed by a private certificate authority the client does not trust. Each has a real fix. For a private authority, give that one client the authority's certificate as a trusted root, which keeps verification on.
const agent = new https.Agent({ ca: readFileSync("internal-ca.pem") });Adding up a page load
Put the pieces together for a fresh HTTPS request with a 70 ms round trip. The DNS lookup takes somewhere between nothing (cached) and a few round trips. The TCP handshake takes one round trip and TLS takes one more. Sending the request and receiving the first byte of the response takes a third, plus the server's own processing time. So the first byte arrives about 210 ms after the connection starts, plus the server time.
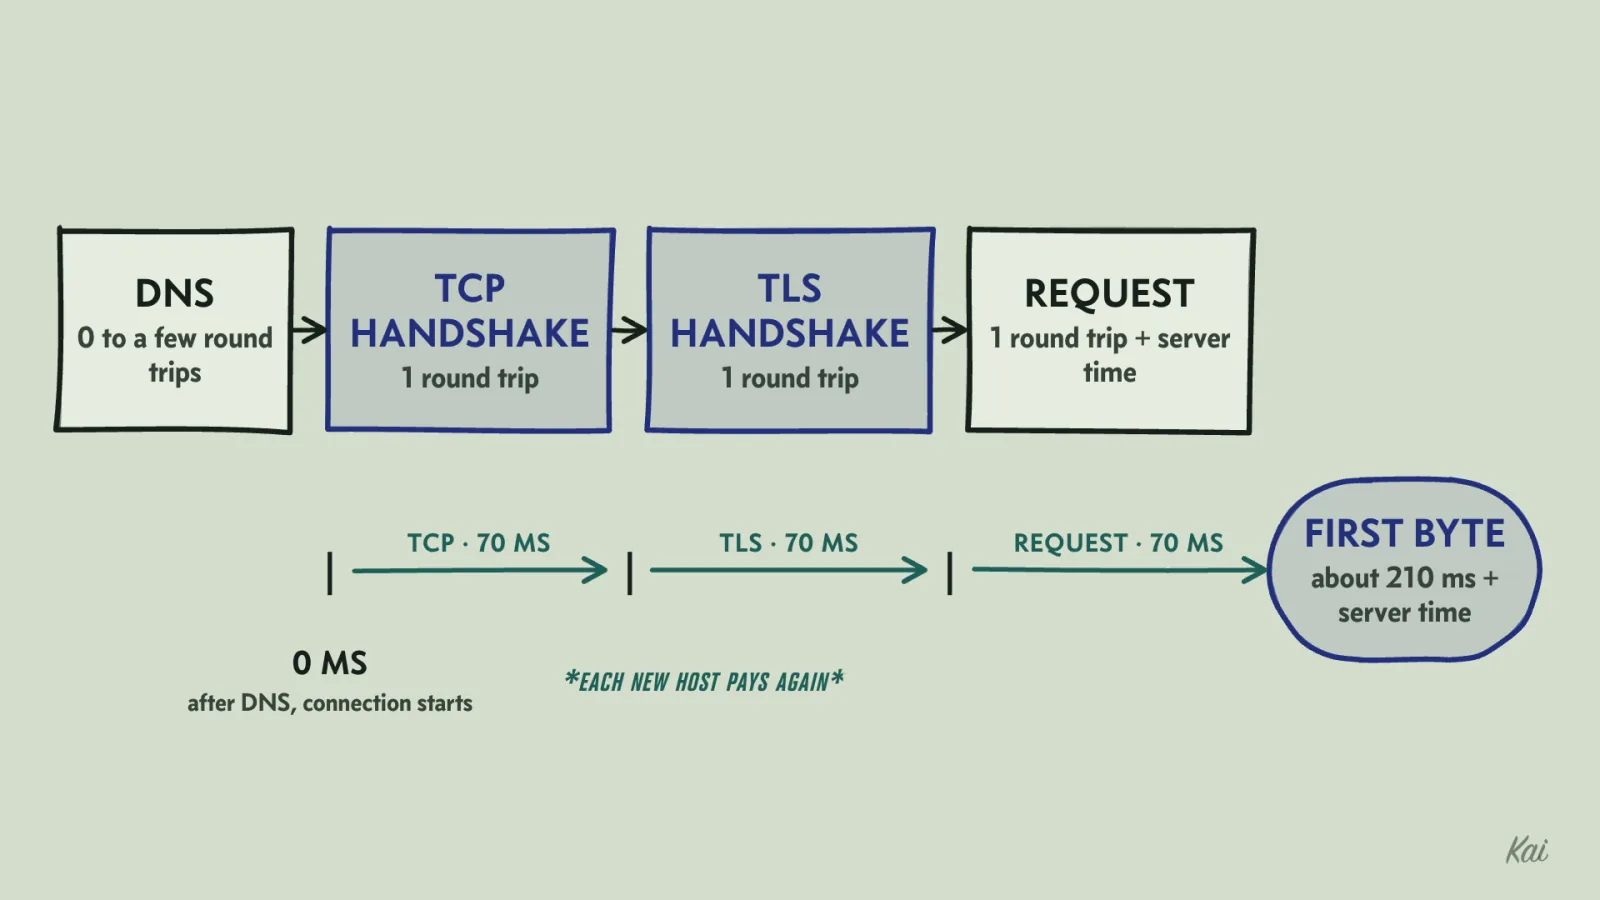
For a web page, the browser then parses the HTML and discovers the stylesheets, scripts and images it needs, and each new host it contacts pays the handshakes again.
curl shows these phases for any URL.
$ curl -o /dev/null -s -w 'dns %{time_namelookup} connect %{time_connect} tls %{time_appconnect} ttfb %{time_starttransfer}\n' https://api.example.com/health
dns 0.012 connect 0.083 tls 0.155 ttfb 0.241
The numbers are cumulative seconds from the start. Connect minus DNS is about 70 ms, one round trip for TCP. TLS minus connect is another 72 ms. The last gap, 86 ms, is one round trip plus about 16 ms of server work.
Browser developer tools show the same breakdown on the Timing tab of each request.
Now the dashboard. Twelve calls in sequence, each with 10 ms of server work, over a connection that is reused:
const widgets = [];
for (const id of widgetIds) {
  widgets.push(await fetch(`${API}/widgets/${id}`).then(r => r.json()));
}
That costs about 12 × (70 + 10) = 960 ms, plus the handshakes for the first call. If each call opens a new connection, add two handshake round trips per call and it becomes 12 × (3 × 70 + 10) = 2,640 ms. Sending the calls at once lets their round trips overlap:
const widgets = await Promise.all(
  widgetIds.map(id => fetch(`${API}/widgets/${id}`).then(r => r.json()))
);
Now the total is one set of handshakes (two round trips, 140 ms), one round trip for the requests (70 ms) and the slowest server response (10 ms): 70 + 70 + 70 + 10 = 220 ms, plus DNS. A batch endpoint that returns all twelve widgets in one response gets the same result with one request. Moving the server closer to the API cuts the round trip itself.
This program runs both shapes against a fake call that takes 80 ms, one round trip plus the server's work, over a connection that is already open.
const sleep = (ms: number) => new Promise((r) => setTimeout(r, ms));
// Stands in for fetch: one 70 ms round trip plus 10 ms of server work.
const getWidget = async (id: number) => { await sleep(70 + 10); return { id }; };
const widgetIds = Array.from({ length: 12 }, (_, i) => i + 1);

let start = Date.now();
const inTurn = [];
for (const id of widgetIds) inTurn.push(await getWidget(id));
console.log(`one at a time: ${inTurn.length} widgets in ${Date.now() - start} ms`);

start = Date.now();
const together = await Promise.all(widgetIds.map((id) => getWidget(id)));
console.log(`all at once: ${together.length} widgets in ${Date.now() - start} ms`);
Output
The loop lands near 960 ms and the parallel version near 80, a few milliseconds over each because timers fire late.
When you see await inside a loop around a network call, multiply the loop count by the round-trip time between where the code runs and where it is calling. That number is the floor on how long the loop takes.
Methods carry promises
HTTP gives each request a method, and the method tells every machine that handles the request what it is allowed to assume. RFC 9110, the HTTP specification, defines GET, HEAD and OPTIONS as safe: the client is only asking to read. PUT and DELETE are idempotent, meaning that sending the same request twice has the same effect as sending it once. POST is neither.
Software all over the network relies on those promises. Chat apps fetch links to build previews, and email security scanners open links in messages to check them. Search crawlers follow every link they find, and browsers prefetch pages they expect you to visit. All of them send GET, because GET is supposed to be harmless.
GET /projects/42/archive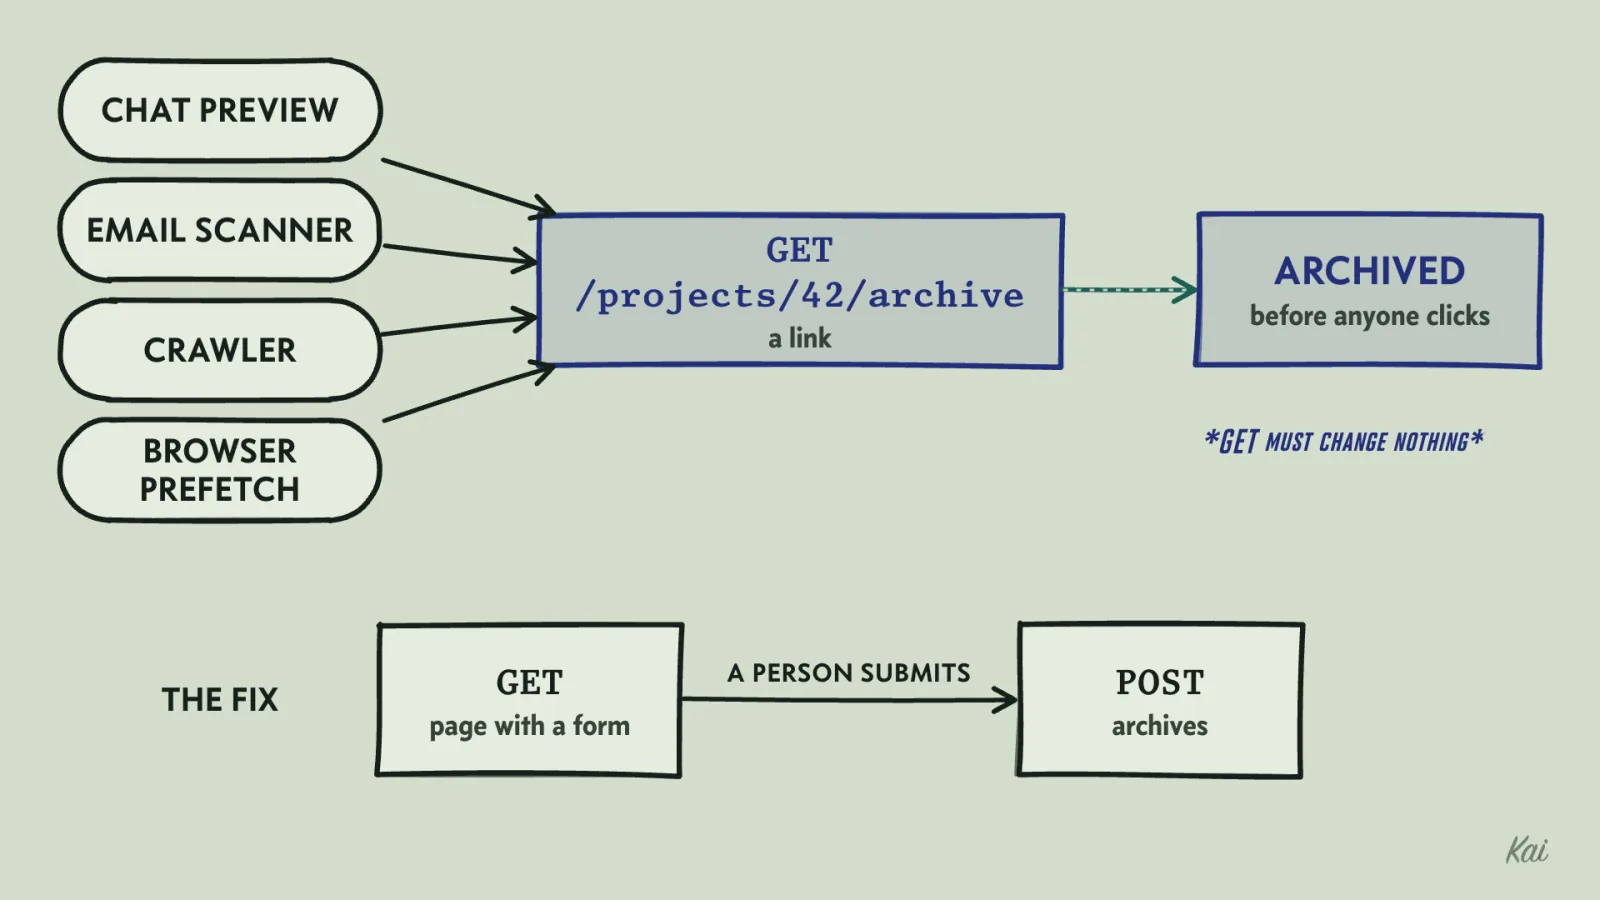
GET, so an archive link fires before anyone clicks. The fix returns a page with a form whose POST does the archiving.An agent that implements "archive project" as a link to that URL has built a button that any of those programs will press. If the chat app's preview fetcher can reach that URL, for example because the link carries its own login token, pasting the link into a channel archives the project before anyone clicks. The design that works is a GET that returns a page describing the action, with a form that submits a POST to perform it. The question to ask of any route is whether calling it twice, or having a robot call it, changes anything.
Reading a response
Status codes group by the first digit. 2xx means success: 200 OK, 201 Created, 204 No Content. 3xx means look elsewhere: 301 and 308 are permanent redirects, 302 and 307 temporary ones, and 304 Not Modified means your cached copy is still good.
4xx means the client's request was wrong: 400 malformed, 401 not authenticated, 403 the server understood the request and refuses to carry it out, often because of a permission check, 404 not found, 409 conflicts with current state, 429 too many requests. 5xx means the server failed: 500 an error in the server, 502 and 504 a bad or missing answer from a server behind it, 503 temporarily unavailable.
Caching headers tell every cache on the path what it may keep. Here is a response captured in developer tools, followed by the browser's next request for the same file.
HTTP/2 200
cache-control: public, max-age=3600
etag: "a1b2c3"

GET /app.css
if-none-match: "a1b2c3"

HTTP/2 304
max-age=3600 lets any cache reuse the response for an hour without asking. After that, the browser sends the etag back in if-none-match, and if the file has not changed the server answers 304 with no body. no-store tells every cache, the browser's included, not to keep a copy, which suits a response that must not be stored anywhere, such as a one-time token. private lets the user's own browser keep the response and keeps it out of shared caches such as a CDN, which suits personal data the browser may reuse.
Every call needs a deadline
A network call can fail fast, with a refused connection or an error status, or it can hang. The other side may have accepted the connection and then stopped responding. Python's requests library waits forever by default in that case, and Node's built-in fetch waits five minutes for the response headers before it gives up.
const res = await fetch(GEOCODER_URL, {
  method: "POST",
  headers: { "Content-Type": "application/json" },
  body: JSON.stringify(address),
}); // no deadline of our own: relies on fetch's five-minute default
Suppose this runs in a server that works on at most 40 requests at a time, and 20 requests per second each call the geocoder. When the geocoder hangs, every request that reaches this line stops there and holds its slot. After two seconds all 40 are stuck, and the server stops answering everything, including pages that never touch the geocoder. Connection pools, file descriptors and memory for pending requests fill the same way.
try {
  const res = await fetch(GEOCODER_URL, {
    method: "POST",
    headers: { "Content-Type": "application/json" },
    body: JSON.stringify(address),
    signal: AbortSignal.timeout(3000),
  });
  return await res.json(); // reading the body is still under the same deadline
} catch {
  return fallbackLocation(address); // a TimeoutError lands here, before or after the headers
}
AbortSignal.timeout(3000) covers the whole exchange, connecting and reading the body included. If the 3 seconds run out before the response headers arrive, fetch rejects with a TimeoutError. If they run out while the body is still arriving, fetch has already returned, and it is res.json() that rejects, which is why the body read sits inside the same try. Some clients only limit the gap between bytes, so a server that trickles data never trips them; a total deadline closes that gap. Choose the limit from what the caller can afford to wait, and decide what the code does when it fires.
Here is the same story on a faster clock: a request every 5 ms, 40 slots, and a geocoder that never answers.
const sleep = (ms: number) => new Promise((r) => setTimeout(r, ms));

// The geocoder accepted the connection and then stopped answering.
// Only an abort signal ever ends a call to it.
const hungGeocoder = (signal?: AbortSignal) =>
  new Promise<never>((_, reject) => signal?.addEventListener("abort", () => reject(signal.reason)));

async function simulate(label: string, timeoutMs: number | null) {
  const SLOTS = 40;
  let busy = 0, peak = 0, refused = 0, fallback = 0;
  const pending: Promise<unknown>[] = [];
  for (let i = 0; i < 100; i++) {  // a request every 5 ms for half a second
    if (busy === SLOTS) {
      refused++;
    } else {
      busy++;
      peak = Math.max(peak, busy);
      const signal = timeoutMs === null ? undefined : AbortSignal.timeout(timeoutMs);
      pending.push(hungGeocoder(signal).catch(() => fallback++).finally(() => busy--));
    }
    await sleep(5);
  }
  if (timeoutMs !== null) {
    await sleep(timeoutMs + 10);  // let the last deadlines fire
    await Promise.all(pending);   // every accepted request has now settled
  }
  console.log(`${label}: at most ${peak} slots in use, ${refused} requests refused, ${fallback} answered with a fallback`);
}

await simulate("no timeout", null);
await simulate("30 ms timeout", 30);
Output
Without a timeout every slot fills within 200 ms and the server refuses the rest. With one, only the calls from the last 30 ms are waiting at any moment, so a handful of slots is ever in use, nothing is refused, and once the last deadline passes all 100 requests have an answer.
A timeout on an outbound call has to leave time before the caller's own deadline. If the request must answer within 10 seconds and the geocoder's timeout is also 10 seconds, nothing remains to handle the failure and still respond, so set the dependency's limit lower, for example 3 seconds, and spend the difference on a fallback or a clean error.