
The Queries Behind Your Code
An agent builds you an endpoint that returns the 50 most recent orders, each with the customer's name. It is a few lines of TypeScript on TypeORM, the tests pass, and on your laptop the page loads instantly:
app.get("/orders/recent", async (req, res) => {
  const orders = await orderRepo.find({ order: { createdAt: "DESC" }, take: 50 });
  const rows = [];
  for (const o of orders) {
    const customer = await o.customer;
    rows.push({ id: o.id, total: o.totalCents, customer: customer.name });
  }
  res.json({ orders: rows });
});In production the page is several times slower than on your laptop, and the database is doing far more work than one list should need. Nothing in the code looks slow. There is one query, a loop, and an object per row. The cost is in a line that does not look like a database call at all: await o.customer. It reads like waiting for a value the order already holds.
Code that uses an ORM (object-relational mapper, the library that turns database rows into objects) reads like ordinary object access. In TypeORM, a relation declared with the type Promise<Customer> is lazy: nothing is loaded until the first time you await it. Underneath, every relation that isn't already loaded becomes a SQL statement sent over a network to another process. To review this kind of code you need to see those statements, count them, and know where the rules about your data are actually enforced.
What actually gets sent
A database is a separate program, usually on a separate machine. Every query is a round trip: your code sends SQL, waits, and receives rows. The query itself may take microseconds, but the round trip has a fixed cost on top, typically somewhere around half a millisecond to a millisecond inside one data center, and tens of milliseconds if the app and database are in different regions.
Here is what the endpoint above sends, trimmed from the query log. TypeORM prints every statement when the data source has logging: ["query"], Prisma does the same with log: ["query"], and every ORM and database has an equivalent.
SELECT id, customer_id, total_cents, created_at FROM orders
  ORDER BY created_at DESC LIMIT 50;
SELECT id, name, email FROM customers WHERE id = 812;
SELECT id, name, email FROM customers WHERE id = 97;
SELECT id, name, email FROM customers WHERE id = 812;
-- ... 47 more, one per order
The first query loads the orders. Each order row carries customer_id, but the customer relation is loaded lazily: the ORM fetches it the first time you touch it. The loop touches it 50 times, so the ORM sends 50 more queries, including repeats for a customer who placed two orders. That is 51 queries for one page.
This is the N+1 pattern: one query for the list, then one for each of the N items. At 1 ms per round trip, 51 queries spend about 50 ms waiting on the network. With the database in another region at 30 ms per round trip, it is about 1.5 seconds. On your laptop the database is on the same machine and has ten test orders, which is why you never saw it.
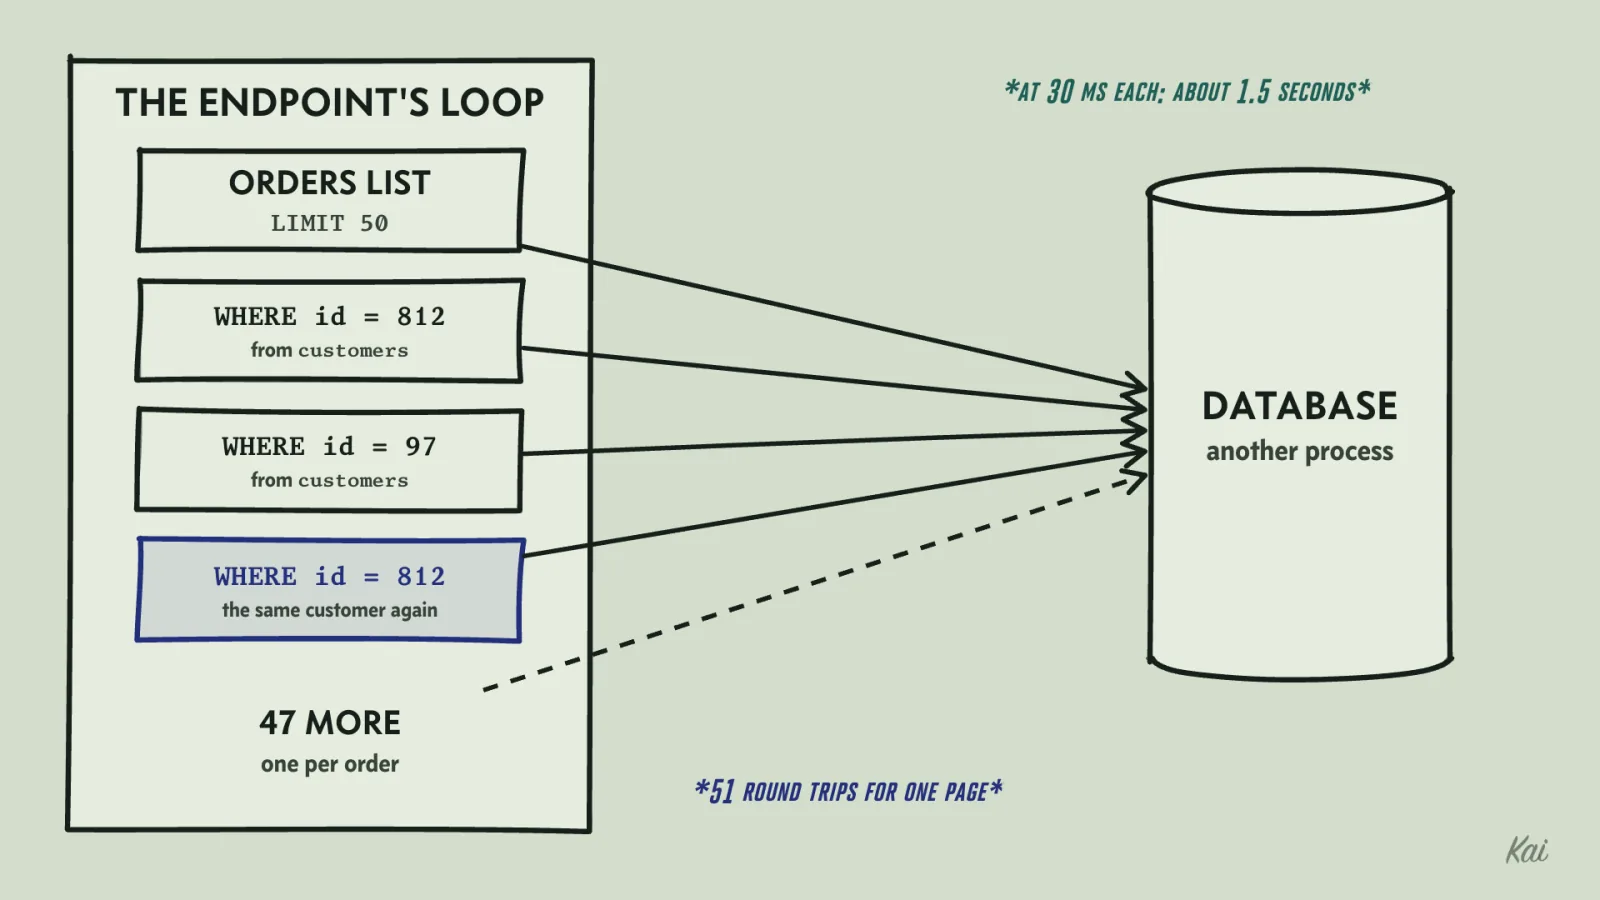
await o.customer sends one more per order, repeats included: 51 round trips for one page.To count, remember that the first access to each uncached relation issues a query, and a relation that is already cached or prefetched issues none. Inside a loop over fresh objects, that is one query per pass. If the loop is inside another loop, the inner access runs once per inner pass, so the counts multiply. A useful detail is that o.customerId costs nothing, because the ID is a column on the order row. await o.customer costs a query, because the name lives in another table.
You can watch the count happen. The block below stands in for the database with two tables in memory and a log of every statement. Each order gets a lazy customer that queries on first access and keeps the result, the way the ORM's does. It uses a plain getter instead of a promise, which changes nothing about the count.
const customers = new Map([[812, "Maya"], [97, "Ravi"], [301, "Lena"]]);
const buyers = [812, 97, 812, 301, 97];
const orderRows = Array.from({ length: 50 }, (_, i) => ({ id: 5000 - i, customerId: buyers[i % 5] }));
const log: string[] = [];
const send = (sql: string) => log.push(sql);

function loadOrders() {
  send("SELECT id, customer_id FROM orders ORDER BY created_at DESC LIMIT 50");
  return orderRows.map((row) => {
    let customer: { name: string } | undefined;
    return {
      ...row,
      get customer() {
        if (!customer) {
          send(`SELECT name FROM customers WHERE id = ${row.customerId}`);
          customer = { name: customers.get(row.customerId) ?? "?" };
        }
        return customer;
      },
    };
  });
}

// The endpoint's loop: read the ID (a column), then the name (another table), twice.
for (const o of loadOrders()) {
  o.customerId;
  o.customer.name;
  o.customer.name;
}
const repeats = log.filter((q) => q.endsWith("= 812")).length;
console.log(`lazy loop: ${log.length} queries, customer 812 fetched ${repeats} times`);
for (const rtt of [1, 30]) console.log(`  at ${rtt} ms per round trip: ${log.length * rtt} ms waiting`);

// Batched: the list, then every customer it needs in one query.
log.length = 0;
const orders = loadOrders();
const ids = [...new Set(orders.map((o) => o.customerId))];
send(`SELECT id, name FROM customers WHERE id IN (${ids.join(", ")})`);
console.log(`batched load: ${log.length} queries`);
for (const q of log) console.log(`  ${q}`);
Output
The second read of o.customer.name on each order sent nothing, because that object had already cached its customer. The repeats come from different order objects that point at the same customer.
There are two standard fixes. A join asks the database to combine the rows in one query. This is a place where writing the query yourself, with the ORM's query builder, says exactly what gets sent:
const rows = await orderRepo
  .createQueryBuilder("o")
  .innerJoin("o.customer", "c")
  .select("o.id", "id")
  .addSelect("o.totalCents", "total")
  .addSelect("c.name", "customer")
  .orderBy("o.createdAt", "DESC")
  .limit(50)
.getRawMany();SELECT orders.id, orders.total_cents, customers.name
FROM orders JOIN customers ON customers.id = orders.customer_id
ORDER BY orders.created_at DESC LIMIT 50;A batched load sends a second query that fetches all the related rows at once, then matches them up in memory:
const orders = await orderRepo.find({ order: { createdAt: "DESC" }, take: 50 });
const ids = [...new Set(orders.map((o) => o.customerId))];
const found = await customerRepo.findBy({ id: In(ids) });
const nameById = new Map(found.map((c) => [c.id, c.name]));
const rows = orders.map((o) => ({ id: o.id, total: o.totalCents, customer: nameById.get(o.customerId) }));
That is two queries no matter how many orders there are. The DataLoader library does the same batching for GraphQL resolvers. Joins suit one-to-one and many-to-one relations. Batching suits one-to-many relations, where a join would repeat the parent row once per child.
Then lock the number in with a test, so the next change can't quietly bring it back:
test("recent orders page sends one query", async () => {
  await makeOrders(50);
  const sent = await countQueries(() => request(app).get("/orders/recent"));
  expect(sent).toBe(1);
});
countQueries is a small helper that counts the statements the ORM reports while the callback runs. TypeORM accepts a custom logger whose logQuery method is called once per statement, which is all the helper needs.
Measure the change as well as asserting it. Record the query count and the response time before and after, against a database with realistic row counts and at the same network distance as production. The count should drop from 51 to 1, and the time saved grows with the round-trip cost.
When you review a page, open the query log for one page load, count the statements, and say which line of code produced each one. If you can't match a query to a line, you don't yet understand what the page does.
Filtering in the wrong place
A second shape looks like this:
const all = await orderRepo.find();
const biggest = all
  .filter((o) => o.status === "open")
  .sort((a, b) => b.totalCents - a.totalCents)
  .slice(0, 10);
It returns the right ten orders. It gets them by loading every order in the table into the app, checking each one, sorting the survivors and throwing away all but ten. With 2 million orders at a few hundred bytes each, that is several hundred megabytes crossing the network, and more than that in memory once each row becomes a JavaScript object. The database could have done the same work with an index and returned ten rows:
const biggest = await orderRepo.find({
  where: { status: "open" },
  order: { totalCents: "DESC" },
  take: 10,
});SELECT ... FROM orders WHERE status = 'open'
ORDER BY total_cents DESC LIMIT 10;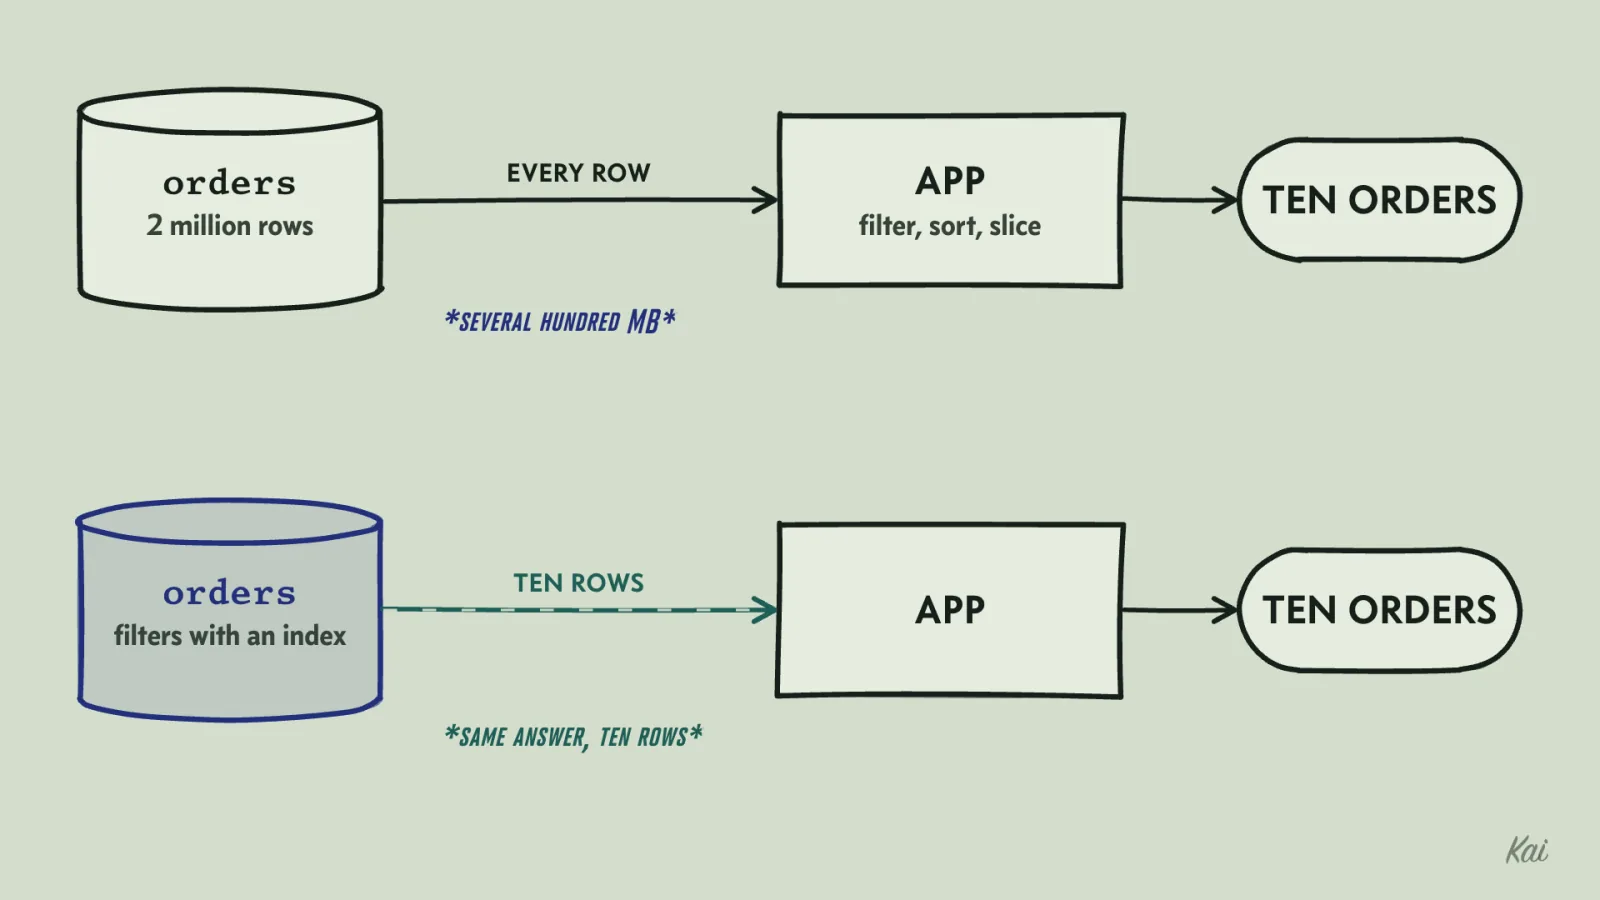
The signs to look for in review are a find() with no where followed by .filter, .sort or .length on the result, and slicing after a loop. Taking .length of a find result loads every matching row to count them; orderRepo.count({ where }) sends SELECT COUNT(*) and returns one number. Filtering in code is fine when the set is small and bounded by design, such as the eight line items on one order. It is a bug when the set grows with your data.
Two requests at once
Now a rule. Usernames must be unique, and the agent enforces it like this:
async function createAccount(username: string) {
  const taken = await accountRepo.findOneBy({ username });
  if (taken) throw new UsernameTaken(username);
  return accountRepo.save({ username });
}
With one user at a time, this works. With two requests for the same name arriving a few milliseconds apart, here is what happens:
| Time | Request A | Request B |
|---|---|---|
| t1 | SELECT: is "maya" taken? No rows. | |
| t2 | SELECT: is "maya" taken? No rows. | |
| t3 | INSERT "maya" | |
| t4 | INSERT "maya" |
Both checks ran before either insert, so both passed, and the table now has two accounts named maya. In production this is easy to trigger. A user double-clicks the submit button, or a mobile client retries after a slow response, and the two requests land within milliseconds of each other.
Wrapping the two statements in a transaction does not fix this at PostgreSQL's default isolation level. Each request's SELECT only sees rows that other transactions have already committed, and neither has committed when the other checks.
The block below runs that interleaving. A 5 ms timer stands in for each round trip, and two signups for maya start at the same moment. The second half runs the same requests against a table with a unique index, where the database checks and writes in one step.
const roundTrip = () => new Promise((r) => setTimeout(r, 5));

const rows: string[] = [];
async function createAccount(username: string) {
  await roundTrip();
  if (rows.includes(username)) return `${username}: taken`;
  await roundTrip();
  rows.push(username);
  return `${username}: created`;
}
console.log(await Promise.all([createAccount("maya"), createAccount("maya")]));
console.log("rows:", rows);

const index = new Set<string>();
const indexed: string[] = [];
async function insertAccount(username: string) {
  await roundTrip();
  const key = username.toLowerCase();
  if (index.has(key)) return `${username}: unique violation, shown as taken`;
  index.add(key);
  indexed.push(username);
  return `${username}: created`;
}
console.log(await Promise.all([insertAccount("maya"), insertAccount("maya"), insertAccount("Maya")]));
console.log("rows:", indexed);
Output
The fix is to let the database enforce the rule, because the database is the one place that sees every write in order:
CREATE UNIQUE INDEX accounts_username_lower ON accounts (lower(username));Now the second INSERT fails no matter how the requests interleave. The index on lower(username) also stops "Maya" and "maya" from both existing, which the application check would have allowed. The application catches the database's error and turns it into the same friendly message:
async function createAccount(username: string) {
  try {
    return await accountRepo.insert({ username });
  } catch (e) {
    if (isUniqueViolation(e, "accounts_username_lower")) throw new UsernameTaken(username);
    throw e;
  }
}

// PostgreSQL reports a unique violation as error code 23505 and names the index it hit.
function isUniqueViolation(e: unknown, name: string): boolean {
  const pg = (e as { driverError?: { code?: string; constraint?: string } } | null)?.driverError;
  return pg?.code === "23505" && pg.constraint === name;
}
The helper checks the index by name, since a different constraint on the same table would raise the same kind of error, and any other error is thrown on unchanged. You can keep the lookup in front as well, to show a nice message in the common case. It is a convenience; the index is what makes the rule true.
Deciding where a rule lives
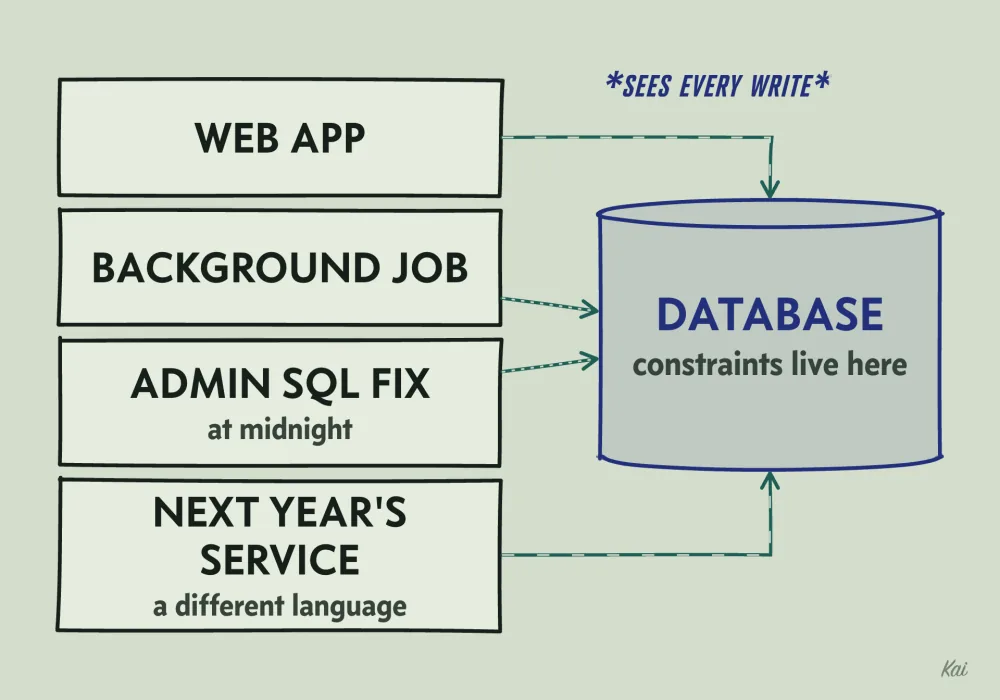
The question to ask of any rule is whether it must hold for every row, from every writer, forever. Writers include the web app, a background job, an admin running a SQL fix at midnight, and next year's service in a different language. If the answer is yes, it belongs in the database as a constraint: UNIQUE, NOT NULL, FOREIGN KEY, or CHECK (total_cents >= 0). The database enforces these under concurrency, and a check in application code does not.
If the rule needs context the database doesn't have, such as the current user's permissions, the pricing plan, or an external service, it belongs in application code. Many rules belong in both: the constraint guarantees the invariant, and the application check gives the user a clear message before the write.
| Rule | Where | Reason |
|---|---|---|
| Username is unique | Constraint, plus app check for the message | Concurrent writes |
| Order total is not negative | CHECK constraint |
Impossible state; every writer must respect it |
| Order points to a real customer | Foreign key | Deleting a customer must not orphan orders silently |
| Free plan allows 3 projects | Application code | Depends on the plan, which changes with pricing |
That last row has the same race as the username check. Two requests can each count two projects and each insert a third. If an occasional fourth project is acceptable, application code is enough. If it isn't, the check has to lock something, for example by selecting the account row with SELECT ... FOR UPDATE inside the transaction, so the second request waits until the first commits.
The same rule in two places
The last mistake takes months to show up. The rule for an "active customer" gets written once as a getter for the account page:
class Customer {
  get isActive(): boolean {
    return this.status === "active" && this.deletedAt === null;
  }
}
and once, a month later, as a query for the admin dashboard:
const activeCount = await customerRepo.count({ where: { status: "active" } });The query forgot deletedAt, so the dashboard counts deleted customers as active. Later someone adds a "trial" status and updates the getter, and the query drifts further. Neither version is obviously wrong when you read it alone. You find the bug when two screens disagree about the same number:
CREATE TABLE customers (id INTEGER PRIMARY KEY, name TEXT, status TEXT, deleted_at TEXT);
INSERT INTO customers VALUES
  (1, 'Maya', 'active', NULL),
  (2, 'Ravi', 'active', '2026-08-02'),
  (3, 'Lena', 'active', NULL),
  (4, 'Omar', 'cancelled', NULL);

-- The getter's rule next to the dashboard's query.
SELECT
  (SELECT COUNT(*) FROM customers WHERE status = 'active' AND deleted_at IS NULL) AS account_pages,
  (SELECT COUNT(*) FROM customers WHERE status = 'active') AS dashboard;

-- One definition that every caller reads from.
CREATE VIEW active_customers AS
  SELECT * FROM customers WHERE status = 'active' AND deleted_at IS NULL;
SELECT COUNT(*) AS active FROM active_customers;
SELECT EXISTS (SELECT 1 FROM active_customers WHERE id = 2) AS ravi_is_active;
Output
To spot it, pick a business term that appears in the product ("active", "overdue", "eligible") and search the code for every place that decides it. If you find the logic in both a query and a method, or in two queries, ask which one wins when they disagree.
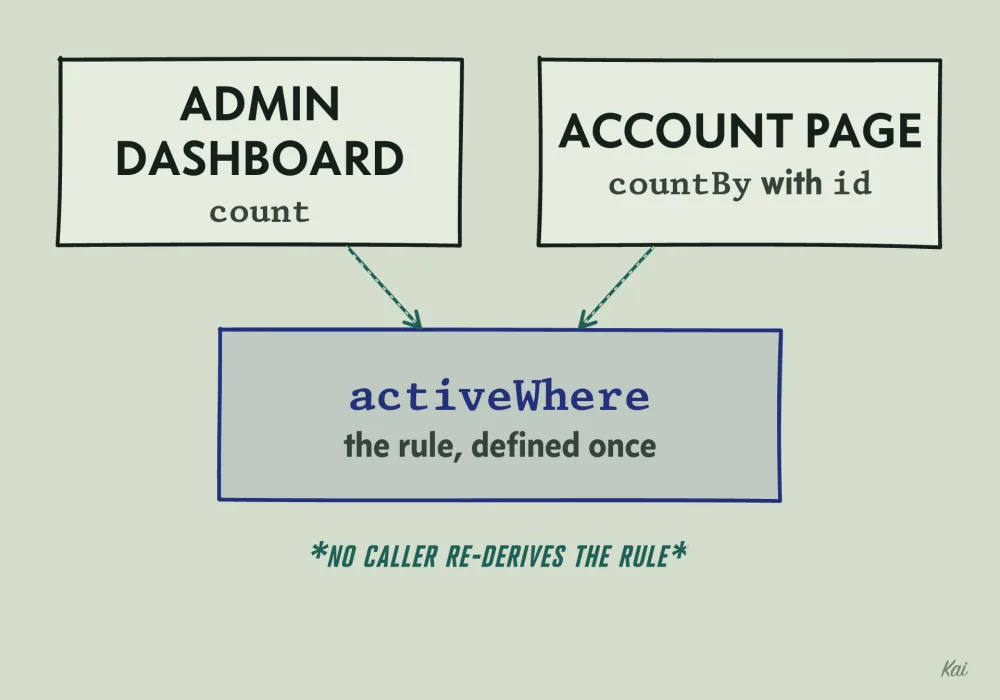
activeWhere, so they cannot disagree about who is active.The fix is to define the rule once, in a form that produces a query, and have every caller go through it. That can be a database view like the one above, a repository function, or in TypeORM one exported condition such as const activeWhere = { status: "active", deletedAt: IsNull() } that every count and lookup uses. Keeping all queries for a table in one module helps here, since there is one file to read to find every definition. When a page needs to know whether a single customer is active, it asks the same query, for example customerRepo.countBy({ ...activeWhere, id }), instead of re-deriving the rule.
When you review code that touches a database, read the query log for each page it changes and count the statements, and for each rule it enforces, ask whether two concurrent requests could both pass the check. If they can, the rule needs a constraint or a lock.