
Make It Fail, Then Ask Why
An agent hands you a two-line diff. A nightly job that builds a daily sales report had been crashing about once a month with TypeError: Cannot read properties of undefined (reading 'total'). The agent changed one line so the lookup reads totalsByDay[key]?.total ?? 0, ran the tests, and reported that the crash is fixed. The tests pass and the crash reports stop.
You now have a report that never crashes, and you have no idea whether its numbers are right. The crash was the only signal that something upstream produced a bad value. The diff removed the signal and left the bad value where it was. Debugging is the work of finding where that value came from, and it has a method that works far better than guessing.
What a bug actually is
Every failure you see is the end of a chain. Somewhere, code produced a wrong value: a wrong key, a stale timestamp, a count off by one. That wrong value then travelled through the program, passed between functions, stored in variables, until some line tried to use it in a way that could not work. That last line is where the crash happens and where the stack trace points.
So there are two places in every bug. The defect is where the wrong value was created. The failure is where you noticed it. They can be one line apart or in different services. A stack trace tells you exactly where the failure is. It shows the defect only if the defective code is still on the call stack when the crash happens, and often it has already returned.
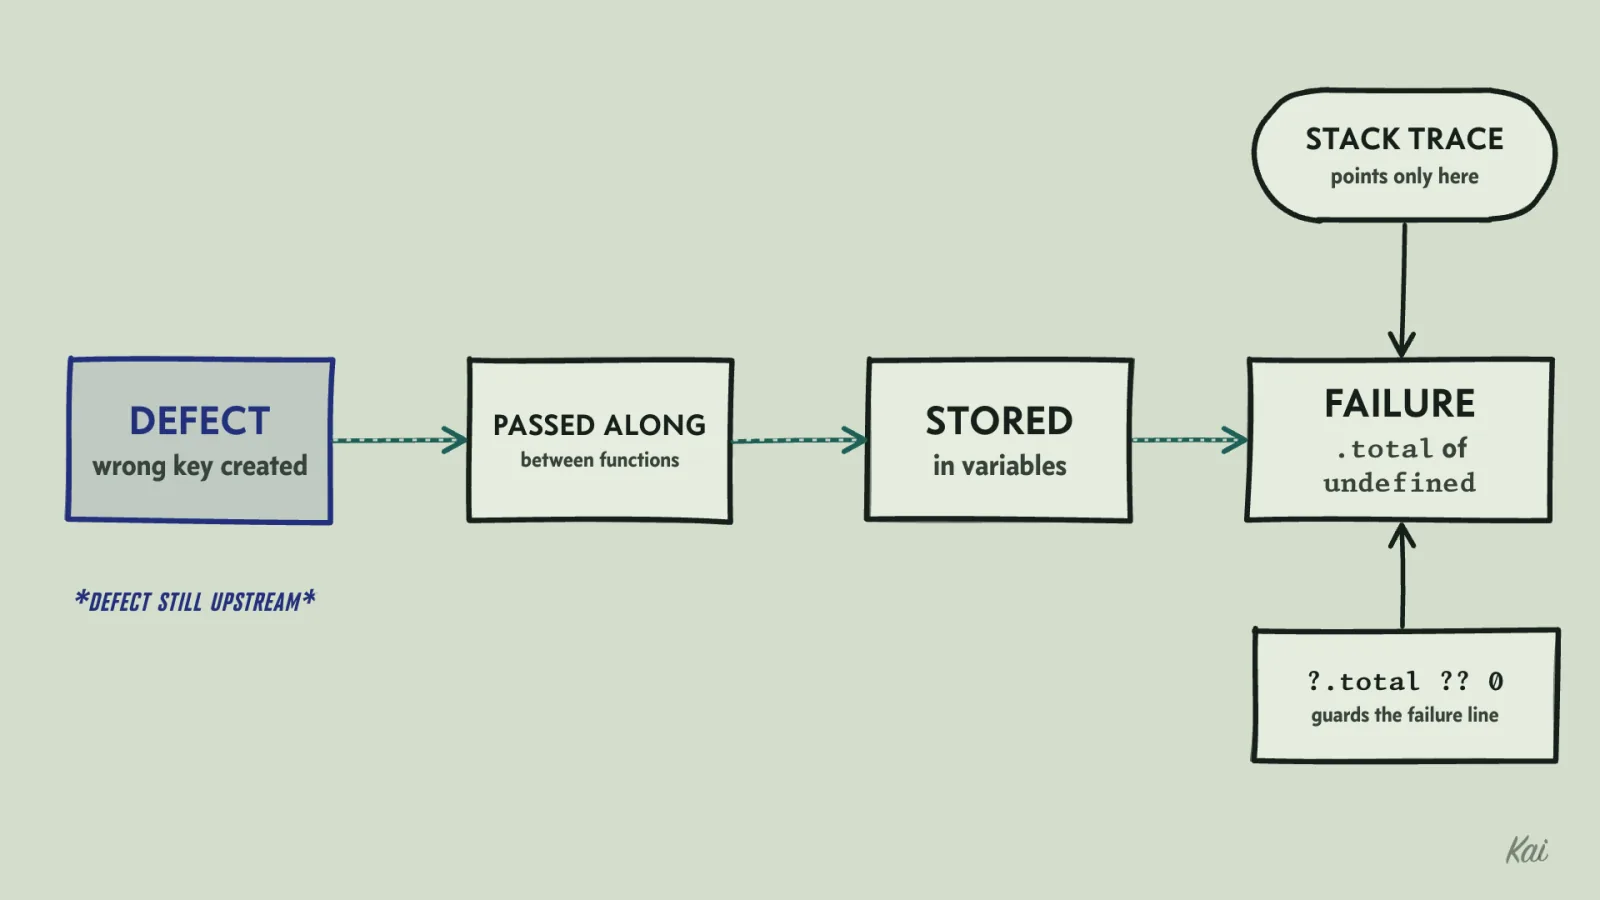
?.total ?? 0 patch guards that failure line, so the defect keeps producing wrong keys with nothing left to complain.This is why a null check at the crash site is the wrong fix here. The lookup must find the day, so a missing entry means something upstream went wrong, and defaulting to zero hides that. A null check is the right fix when absence is a valid state, such as a day that really had no sales. The ?.total ?? 0 change guards the failure line. The defect is still upstream, still producing wrong keys, and now nothing complains. The same logic applies to wrapping a handler in try/catch, or adding retries. A retry helps when the failure depends on something that changes between attempts, like a dropped network connection. When the failure comes from the code or its input, a retry runs the same defect again. If it fails every time, the retry only delays the error. If it fails some of the time, the retry hides it, and the defect keeps running on every attempt.
The question that exposes a symptom patch is: in the case that used to crash, what does the program produce now, and is that value correct? For the sales report, the answer is "zero dollars for that day", which is false.
Reproduce first
Before changing any code, try to make the failure occur on demand, and make that way as small as you can. When you can't reproduce it, test your hypotheses against whatever evidence was captured, such as logs, memory dumps and traces, and say plainly what remains uncertain.
The production job crashed "about once a month", on no particular weekday, which sounds random. The crash reports carried the job's input, and when you line them up they have one thing in common: every crash was a report for the 1st of a month. Here is the code involved.
// src/sales.ts
export function dayKey(isoDate: string): string {
  const d = new Date(isoDate);
  const mm = String(d.getMonth() + 1).padStart(2, "0");
  const dd = String(d.getDate()).padStart(2, "0");
  return `${d.getFullYear()}-${mm}-${dd}`;
}

export function dailyTotal(totalsByDay: Record<string, { total: number }>, isoDate: string): number {
  return totalsByDay[dayKey(isoDate)].total;
}
totalsByDay holds one entry per day of the current month, keyed like "2026-03-01". A reproduction starts from the real input and cuts away everything that turns out to be irrelevant: the database, the scheduler, the other days of the month. Each time you remove something, run it again. If it still fails, the thing you removed was not needed for the failure. If it stops failing, put it back, because it matters. What survives is a test like this one, which Node 22.18 and later run straight from the .ts file.
// test/daykey.regress.test.ts
import { test } from "node:test";
import assert from "node:assert/strict";
import { dayKey, dailyTotal } from "../src/sales.ts";

test("dayKey keeps the calendar date it was given", () => {
  assert.equal(dayKey("2026-03-01"), "2026-03-01");
});

test("the 1st of the month reads its own total", () => {
  const march = { "2026-03-01": { total: 412 } };
  assert.equal(dailyTotal(march, "2026-03-01"), 412);
});
On your laptop this test passes. In CI it passes too. It fails only when you run it the way production runs it:
TZ=UTC node --test test/daykey.regress.test.ts                   # passes
TZ=America/Los_Angeles node --test test/daykey.regress.test.ts   # fails
The production servers were configured for Pacific time. CI containers and many cloud machines default to UTC. That one environment variable separates a bug that never appears in testing from a test that fails every time.
A failing test is the best form a reproduction can take, because it doubles as the proof of the fix. The rule for accepting any fix, from an agent or a person, is to see this test fail before the change and pass after it. A fix accepted without that is a guess that happened to coincide with the crash reports going quiet, and an intermittent failure can go quiet for weeks with no change at all.
Debug by experiment
When an agent gets an error, the easy loop is to paste the error back and ask for another fix. Each round, the agent reads the same stack trace, makes a new guess about the cause, and changes some code. Nothing is learned between rounds, because the last guess, what it predicted and whether the prediction held were never written down. After five rounds you have five changes and no more understanding than you started with.
The alternative is to treat each step as an experiment. State a hypothesis about the cause. Say what you would observe if it were true. Then run the smallest check that could prove it false. Write all three down, including the ones that fail, because a disproved hypothesis narrows the search as much as a confirmed one.
Here is how that went for the sales report.
- Hypothesis 1: the data loader skips the 1st of the month. Prediction:
totalsByDayhas no"2026-03-01"key. Check: print the keys. The key is there, with the right total. Disproved. - Hypothesis 2: the key being looked up is wrong. Prediction:
dayKey("2026-03-01")returns something other than"2026-03-01". Check: call it under Pacific time. It returns"2026-02-28". Confirmed. - Hypothesis 3: other days are also shifted, and they only avoid crashing because the previous day exists in the map. Prediction:
dayKey("2026-03-15")returns"2026-03-14"under Pacific time. Check: it does.
Hypothesis 3 is the important one. The crash on the 1st was the visible part of a larger bug. Every other day of the month, the report silently showed the previous day's total. The agent's ?? 0 patch would have hidden the only case that made noise and kept all the wrong numbers.
When you work with an agent, give it the experiment instead of the error. "Under TZ=America/Los_Angeles, what does dayKey('2026-03-01') return, and why?" is a question with a checkable answer. "It crashed again, here's the trace" invites another guess.
Why it happens
JavaScript's new Date("2026-03-01") parses the string as midnight UTC on that date. The ECMAScript spec treats date-only ISO strings as UTC, and date-time strings without an offset, like "2026-03-01T00:00", as local time. Midnight UTC on March 1 is 16:00 on February 28 in Los Angeles. getDate() and getMonth() read the date in the machine's local timezone, so they return the 28th of February. East of UTC, local time is ahead of UTC, the calendar date stays the same, and the bug never shows. That is why a developer in Berlin and a CI runner in UTC both saw green tests.
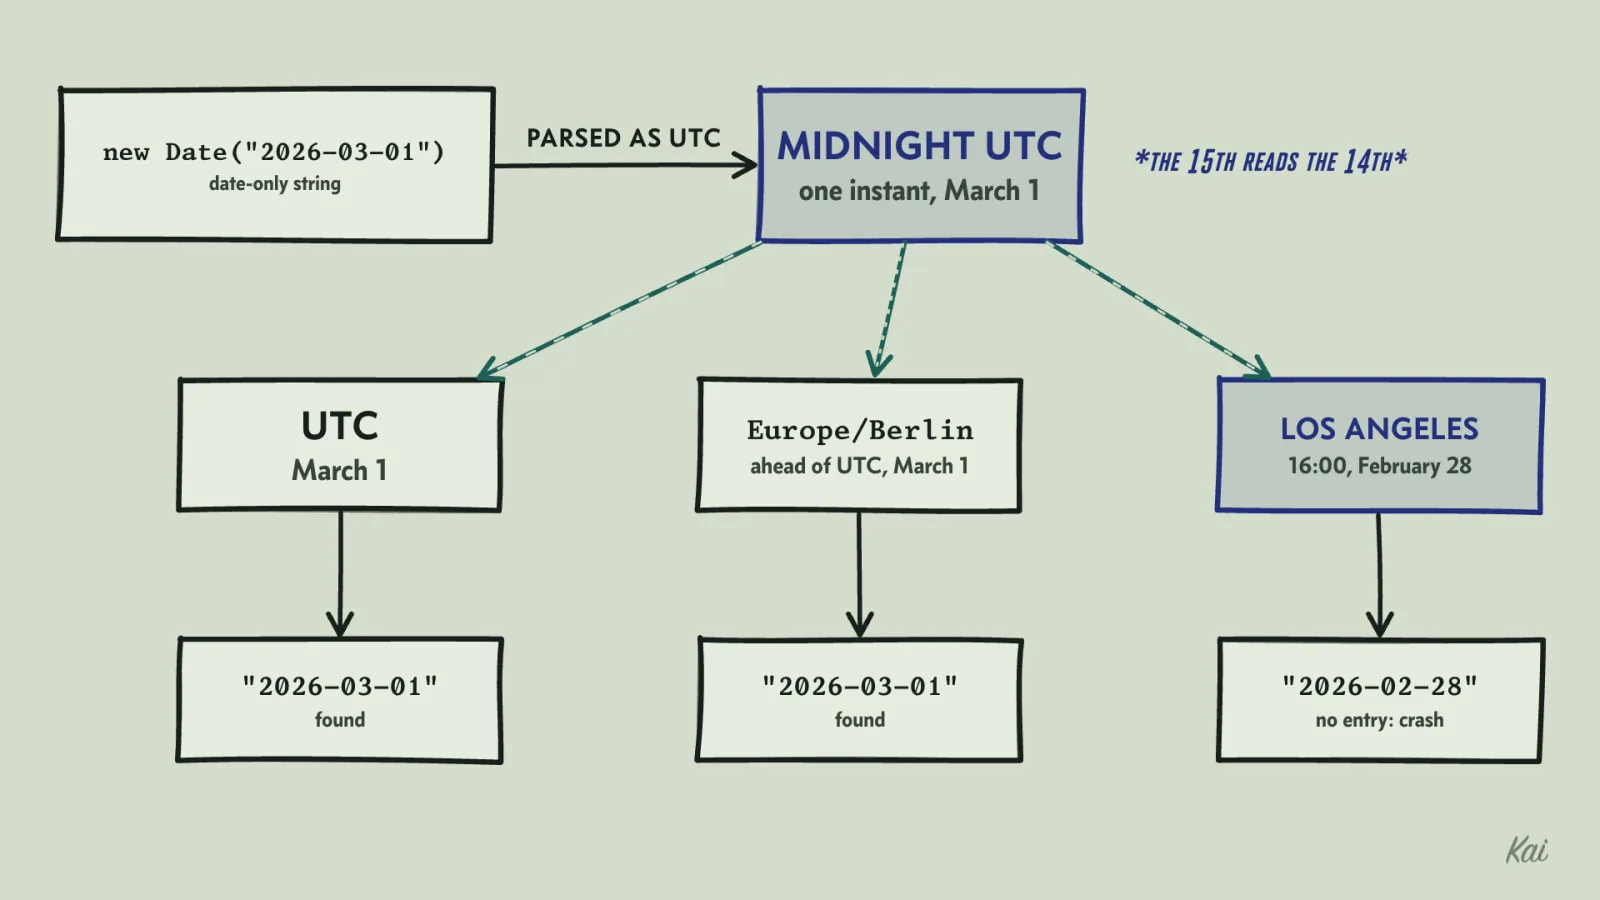
new Date("2026-03-01") is one instant, midnight UTC. In UTC and Berlin the local getters still read March 1, but in Los Angeles they read February 28, so the key misses on the 1st and quietly points at the wrong day on every other date.A browser cannot change its own timezone, so the block below passes the zone in and reads the date the way getDate() would read it there. Near the end it runs the real dayKey in your machine's own zone, so that line depends on where you are.
const march: Record<string, { total: number }> = {
  "2026-03-01": { total: 412 },
  "2026-03-14": { total: 980 },
  "2026-03-15": { total: 655 },
};

function dayKeyIn(isoDate: string, timeZone: string): string {
  const parts = new Intl.DateTimeFormat("en-CA", { timeZone, year: "numeric", month: "2-digit", day: "2-digit" })
    .formatToParts(new Date(isoDate));
  const part = (type: string) => parts.find((p) => p.type === type)?.value;
  return `${part("year")}-${part("month")}-${part("day")}`;
}

console.log(`new Date("2026-03-01") is the instant ${new Date("2026-03-01").toISOString()}`);
for (const zone of ["UTC", "Europe/Berlin", "America/Los_Angeles"]) {
  for (const day of ["2026-03-01", "2026-03-15"]) {
    const key = dayKeyIn(day, zone);
    const total = march[key]?.total ?? "undefined, the crash";
    console.log(`${zone.padEnd(20)} ${day}: key ${key}, total ${total}`);
  }
}

function dayKey(isoDate: string): string {
  const d = new Date(isoDate);
  const mm = String(d.getMonth() + 1).padStart(2, "0");
  const dd = String(d.getDate()).padStart(2, "0");
  return `${d.getFullYear()}-${mm}-${dd}`;
}
const here = Intl.DateTimeFormat().resolvedOptions().timeZone;
console.log(`your machine (${here}): dayKey("2026-03-01") is ${dayKey("2026-03-01")}`);
console.log(`the fix, "2026-03-01".slice(0, 10), is ${"2026-03-01".slice(0, 10)} in every zone`);
Output
In Los Angeles the 15th quietly reads the 14th's total, 980 instead of 655. That is the wrong number Hypothesis 3 predicted, and nothing in the output marks it as wrong.
Stack traces and logs each gave part of this. The trace said where: line 10 of sales.ts, reading .total of undefined. The job's log gave when and with what data: the input date, and the fact that every failure was on the 1st. The timezone came from comparing the environment where it failed with the environments where it did not. Read a trace for the location of the failure, then go to the logs and the environment for the data that led there.
A debugger is the other way to see the chain directly. Run the test with node --inspect-brk, set a breakpoint inside dayKey, and watch d and d.getDate() as they are computed. You see the wrong day appear on the line where it is created, which is the defect, instead of in the caller, where it is used.
Finding the commit with bisection
The report used to work. Somewhere between the last release and today, a commit introduced the bug, and knowing which one tells you what the author was trying to do and what else they changed.
Bisection finds it by halving. Mark one commit where the bug is present and one where it is absent. Test the commit halfway between. Whichever half contains the change from good to bad is where you look next. With 200 commits between the two, you need about 8 tests, since 2 to the 8th is 256. Git automates the whole search:
git bisect start
git bisect bad HEAD
git bisect good v1.4.0
git bisect run env TZ=America/Los_Angeles node --test test/daykey.regress.test.ts
git bisect reset
git bisect run checks out each candidate commit, runs your command, and reads its exit code: 0 means good, 125 means this commit cannot be tested and should be skipped, and most other non-zero codes mean bad. Two details matter. Keep the regression test untracked, in a new path that no candidate commit touches (or outside the checkout), because Git leaves untracked files in place as it checks out old commits, so the test exists at every step. And the command must fail only for the bug you are chasing. If a commit fails for another reason, such as the test being unable to import sales.ts there, the search follows the wrong trail. Have the command exit with 125 on those commits instead.
The block below runs the halving over 200 commits. The bug arrives in commit 137, and commits 95 to 104 had sales.ts moved to another folder, so the test cannot import it there. A careless test calls those commits bad; a careful one skips them.
type Verdict = "good" | "bad" | "skip";
const BUG_FROM = 137;
const moved = (c: number) => c >= 95 && c <= 104;
const careless = (c: number): Verdict => (moved(c) || c >= BUG_FROM ? "bad" : "good");
const careful = (c: number): Verdict => (moved(c) ? "skip" : c >= BUG_FROM ? "bad" : "good");

function bisect(name: string, test: (c: number) => Verdict) {
  let good = 0;
  let bad = 200;
  const seen: string[] = [];
  while (bad - good > 1) {
    let c = Math.floor((good + bad) / 2);
    // Git picks another commit nearby when one is skipped; this takes the next one up.
    while (test(c) === "skip" && c + 1 < bad) {
      seen.push(`${c} skip`);
      c++;
    }
    const v = test(c);
    if (v === "skip") break;
    seen.push(`${c} ${v}`);
    if (v === "good") good = c;
    else bad = c;
  }
  console.log(`${name}: first bad commit is ${bad}`);
  console.log(`  ${seen.join(", ")}`);
}

bisect("careless", careless);
bisect("careful", careful);
console.log(`at most ${Math.ceil(Math.log2(200))} verdicts for 200 commits, without skips`);
Output
The careless run blames commit 95, the folder move, and never looks past it.
Here, bisection lands on a commit titled "tidy dayKey", which replaced isoDate.slice(0, 10) with the Date-based version. The earlier code never converted the string into an instant, so it could not shift the date.
Fix the cause, then the class
A root cause is a cause you can fix that explains every observation. "The report crashed" is a symptom. "The key was wrong" is closer. "Date-only strings are parsed as UTC instants and then read back with local-time getters" explains the crash on the 1st, the silent shift on other days, the timezone dependence, and why tests passed. It also tells you where else to look.
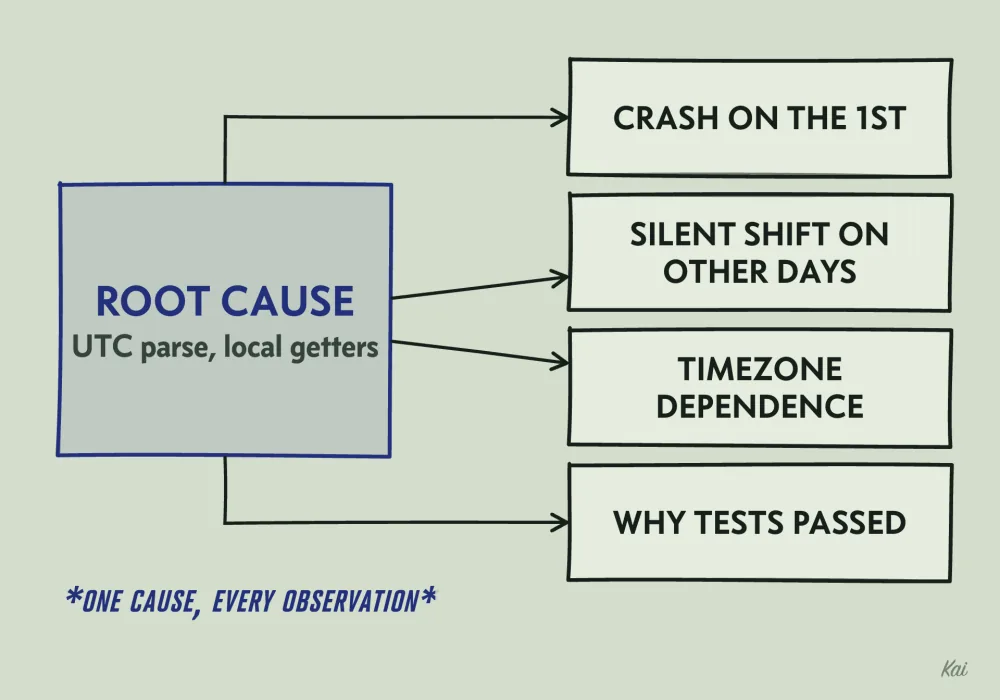
Any code in the repository that has to preserve a calendar date, but passes a date-only string to new Date and then calls getDate, getMonth, getDay or toLocaleDateString, has the same bug. Code that only needs the instant, or that reads it back with the UTC getters, is fine. A search for new Date( finds the candidates, and each one gets the same question. The fix for dayKey is to keep the calendar date as the string it already is. The fix for the class is that plus a CI job that runs the test suite under a timezone west of UTC, so the next person who writes the same line sees a red test.
When you review a bug fix, ask for three things: the reproduction that failed before, the root cause in one sentence that accounts for every observation, and the list of other places that sentence says the same mistake could live.