
Where One Phone Number Ends Up
You asked an agent to add text-message delivery updates to your shop. It added a phone column to the users table, a field on the account page and a call to an SMS provider. Customers get a text when their parcel ships, and the feature works.
Look at the rest of the diff. The request logger now records every form body, so each phone number lands in your logs. The analytics call sends the whole user object as "traits," which includes email, phone and date of birth. The support chat, which asks a language model to summarize each conversation, now pastes the full user record into the prompt. The phone-verification link is https://shop.example/verify?phone=15551234567&code=829301. There is a new fixtures/users.json with twenty rows the agent exported from production "for realistic test data." And the SMS provider's API key sits in src/sms.ts.
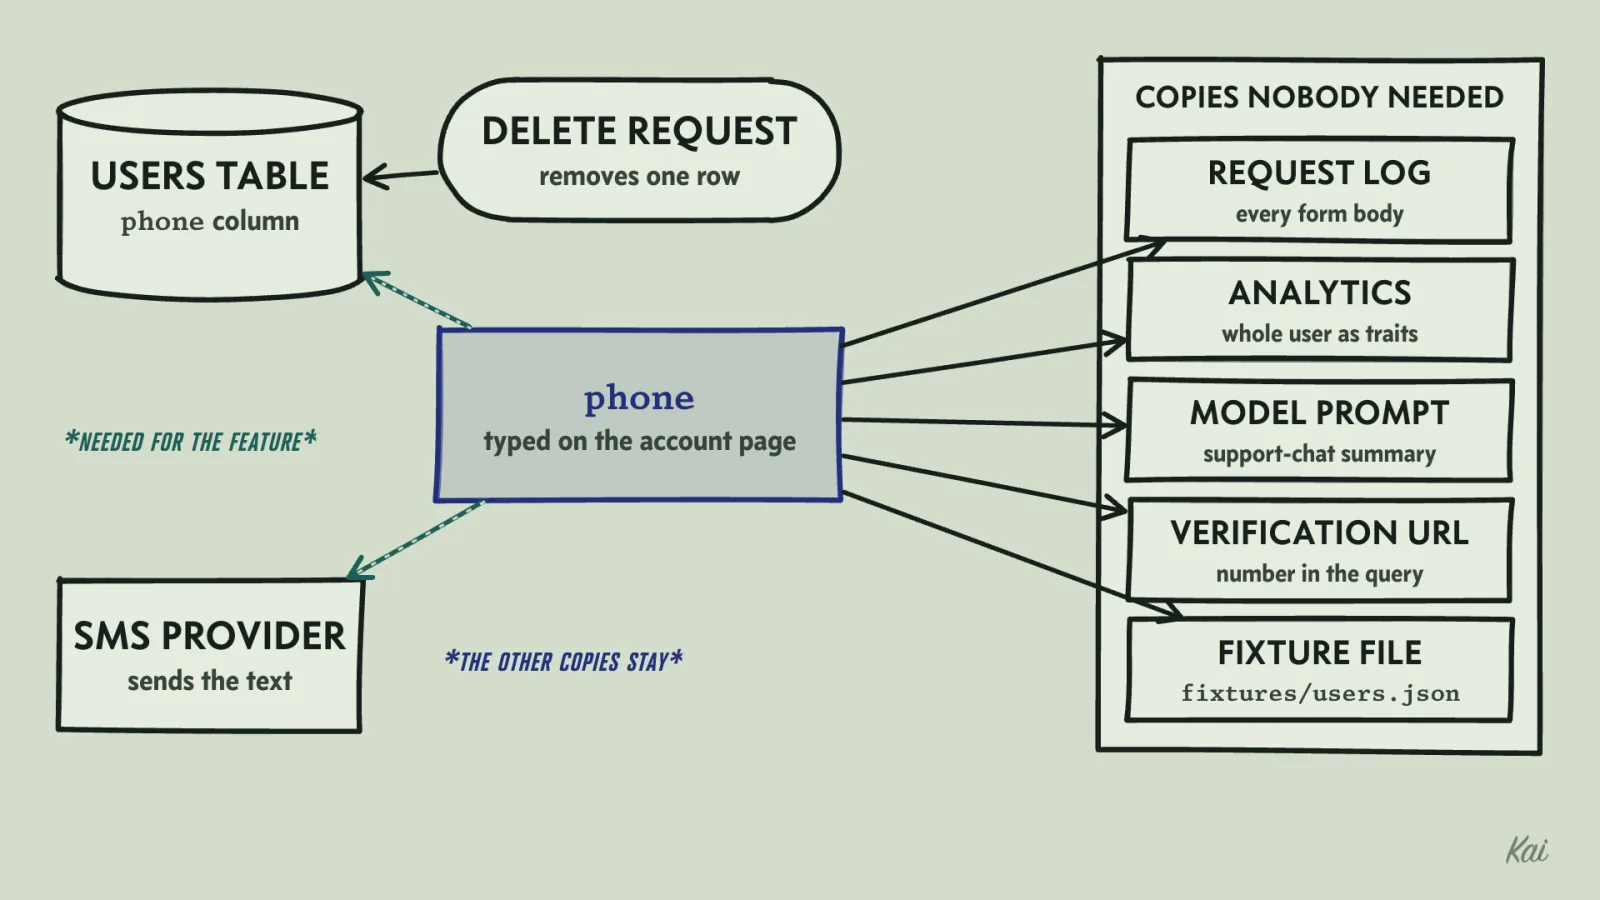
None of these copies were needed for the feature. Access and retention rules differ between these copies. When a customer asks you to delete their data, you delete one row, and the other copies stay where they are.
Sorting data by what a leak would cost
The first step is to decide which data is sensitive. A classification scheme sorts every field into a small number of classes by one question: who is harmed if this leaks, and how badly? A common four-class scheme has these classes:
| Class | Meaning | Examples |
|---|---|---|
| Public | Already published; a leak costs nothing | Product names, prices, public display names |
| Internal | For staff only; a leak is embarrassing but harms no individual | Internal record IDs, feature flags, order counts |
| Confidential | Identifies or describes a person; a leak harms them | Email, phone, address, order history |
| Restricted | A leak enables direct harm such as account takeover or fraud, or carries specific legal duties | Password hashes, API keys, card numbers, government IDs, health records |
Handling rules attach to the class, so a field starts with default rules from its label instead of a fresh judgment call. Restricted fields are never logged or copied into test data, and they go only to the one service whose job requires them, such as a payment processor for card numbers. Confidential fields go only to services that need them for a stated purpose. The label supplies the defaults. Reassess it when the field's use or the data around it changes, and check each destination's need on its own.
The shop's users table, classified field by field:
| Field | Class | Reason |
|---|---|---|
id |
Internal | Meaningless alone, though it links to everything else about the user |
display_name |
Public | Shown next to the user's product reviews |
email |
Confidential | Identifies the person and is their login name |
phone |
Confidential | Identifies the person; if it is used for account recovery, treat it as restricted |
date_of_birth |
Confidential | Combined with name and address, it helps someone impersonate the user |
password_hash |
Restricted | A copy lets an attacker guess passwords offline |
last_login_ip |
Confidential | Reveals roughly where the person is and can count as personal data under laws such as the EU's GDPR |
created_at |
Internal | Harmless alone |
Some data carries legal duties on top of this. Depending on who you are and where your users live, health information can fall under HIPAA in the United States, card numbers under the PCI DSS standard, data about people in the EU under GDPR, and data collected from children under 13 in the US under COPPA. Record the legal and contractual obligations that apply to a field next to its sensitivity label, and use the stricter handling while someone who knows the law assesses them.
Tracing one field
Classification tells you which fields to worry about. Tracing tells you where they are. Pick one field, phone, and follow it from the moment the customer types it.
- The users table in the primary database.
- The database's read replica and its nightly backups, which keep deleted rows until each backup expires.
- A cache that stores the user profile for faster page loads.
- The request log, shipped to a log service where every engineer can search it for 90 days.
- The analytics provider, through the
identifycall. - The SMS provider, which needs it to send the text.
- The model provider, through the support-chat prompt.
- The verification URL, which can be recorded in web-server, CDN or reverse-proxy access logs and in the customer's browser history.
- The fixture file, which is in every clone of the repository and stays in git history after the file is deleted.
The database stores the number and the SMS provider needs it. The replica and backups hold it because they copy the database. The profile cache may not need it at all, so check, and omit it if it does not. The other five copies, in the logs, analytics, the model prompt, the URL and the fixture file, are ones the agent created while making something else work. Error reports and crash dumps belong on this list too whenever they capture request data, so a trace has to include every service the application talks to and every place it writes.
Closing the leaks
Start with the logger. The agent's version records everything.
app.use((req, _res, next) => {
  log.info("request", { method: req.method, url: req.originalUrl, body: req.body });
  next();
});
req.originalUrl includes the query string, so the verification code and phone number from the URL are logged too. The fix logs the path without the query string, and it builds the logged body from values the application has checked.
app.use((req, _res, next) => {
  log.info("request", { method: req.method, path: req.path, body: loggableBody(req.body) });
  next();
});
There are three common ways to write loggableBody. A denylist removes the names it knows are sensitive. An allowlist of names keeps only approved fields. The third keeps approved fields and logs each value only after checking it against what the server knows. Run all three on two request bodies that hide a phone number and on one ordinary order:
const url = "/verify?phone=15551234567&code=829301";
const bodies: Record<string, unknown> = {
  "nested and renamed": { productId: { phone: "15551234567" }, quantity: 2, mobile: "15551234567" },
  "phone as productId": { productId: "15551234567", quantity: 2 },
  "an ordinary order": { productId: "MUG-01", quantity: 2 },
};

// The server's product catalog, standing in for a database lookup.
const catalog = new Map([
  ["MUG-01", { id: "MUG-01", name: "Mug" }],
  ["TEE-RED-M", { id: "TEE-RED-M", name: "Red T-shirt, M" }],
]);

function denylist(body: unknown) {
  const out = { ...(body as Record<string, unknown>) };
  delete out.password;
  delete out.phone;
  return out;
}

function nameAllowlist(body: unknown) {
  const b = body as Record<string, unknown>;
  return { productId: b.productId, quantity: b.quantity };
}

function loggableBody(body: unknown): Record<string, string | number> {
  const b = typeof body === "object" && body !== null ? (body as Record<string, unknown>) : {};
  const out: Record<string, string | number> = {};
  const product = typeof b.productId === "string" ? catalog.get(b.productId) : undefined;
  if (product) out.productId = product.id; // the catalog's ID, logged only when the lookup succeeds
  if (typeof b.quantity === "number" && Number.isInteger(b.quantity) && b.quantity >= 1 && b.quantity <= 99) {
    out.quantity = b.quantity;
  }
  return out;
}

console.log("logged url: ", url);
console.log("logged path:", url.split("?")[0]);
for (const [name, body] of Object.entries(bodies)) {
  console.log(name);
  console.log("  denylist: ", JSON.stringify(denylist(body)));
  console.log("  allowlist:", JSON.stringify(nameAllowlist(body)));
  console.log("  checked:  ", JSON.stringify(loggableBody(body)));
}
Output
The denylist would strip a field called phone, but it passes mobile, the kind of field someone adds next month, and the number nested under productId. The allowlist of names drops mobile but passes the nested number, because it checks names and never looks at values. Both pass a phone number typed straight into productId. A format check such as /^[A-Z0-9-]{1,20}$/ passes it too, because eleven digits fit that pattern. loggableBody logs a product ID only when the catalog lookup finds it, and quantity only when it is a small integer, so neither phone number reaches the log and the ordinary order is still recorded.
The analytics call has the same shape of problem.
analytics.identify(user.id, { ...user });Ask what the analytics service needs to do its job. It counts distinct users and groups them, and an opaque ID plus a plan name does both. Send { plan: user.plan } and nothing else. The model prompt gets the same treatment: the summary needs the conversation, so send only the excerpts it needs with unnecessary personal details removed, since the conversation can itself contain a phone number or an address, and leave the user record out. Check the provider's data-retention terms as well, because what you send may be stored.
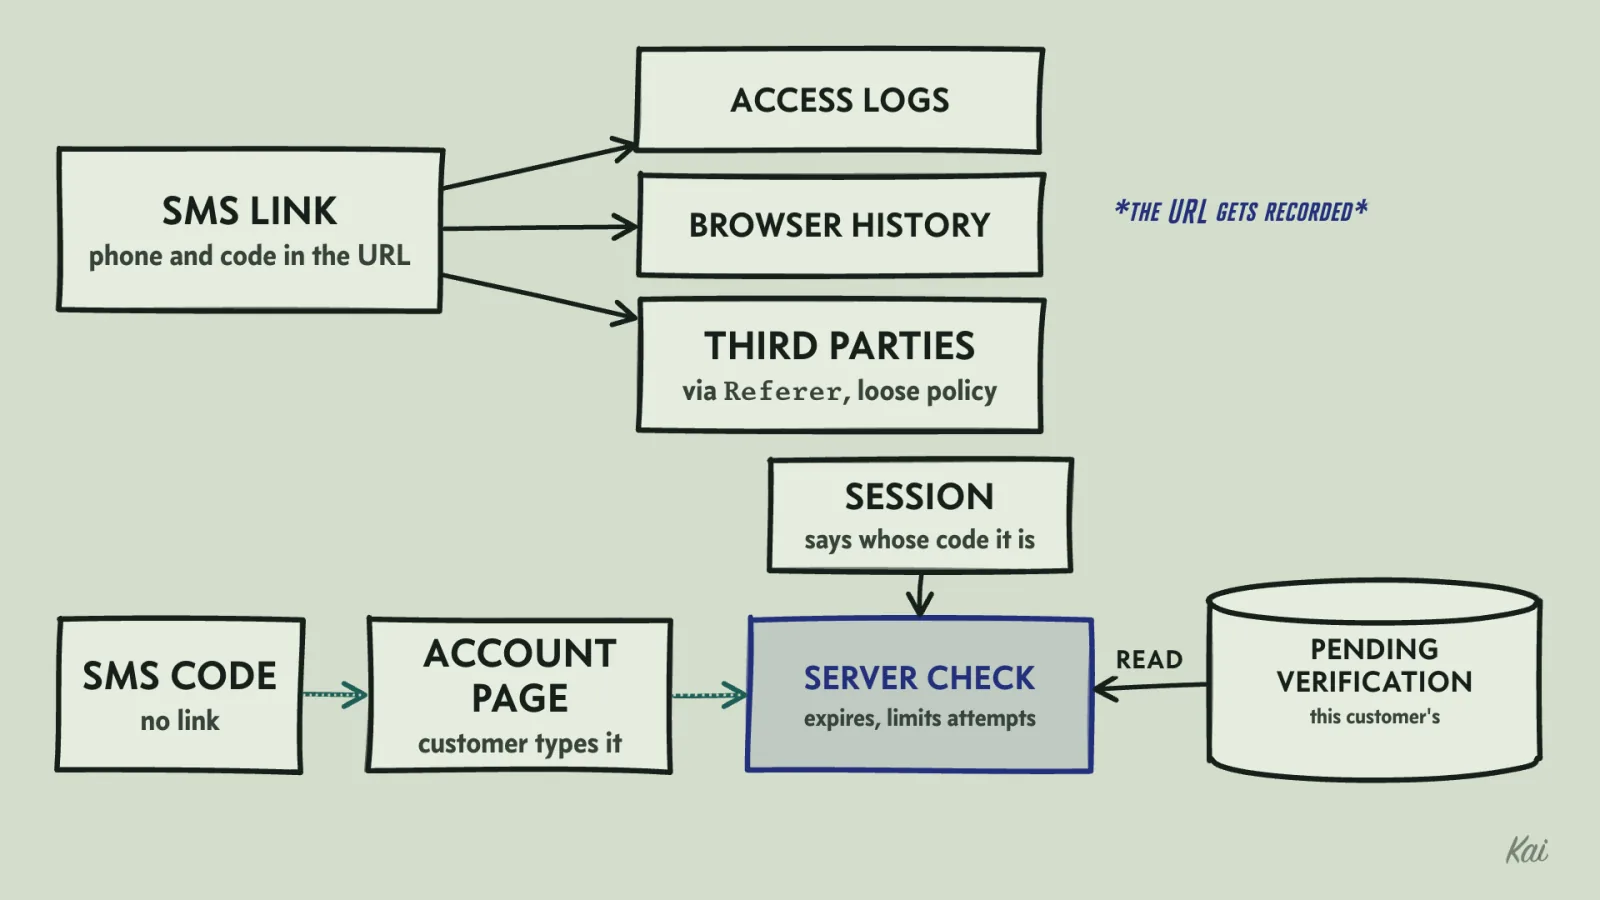
The verification URL has two problems: it carries the phone number, and it carries the code. The text message does not need a link. It can contain the code, and the customer types it on the account page, where the server checks it against that customer's pending verification, expires it after a few minutes and limits the number of attempts. A six-digit code is safe in that setting because the session already says whose code it is, and the attempt limit keeps anyone from trying all million.
If you want a link, put a token in it instead of the phone number. Generate the token with a cryptographically secure random generator, at 128 bits or more, and store its association with the pending verification on the server. Expire it, accept it once, and rate-limit attempts. The landing page exchanges the token for a session with restricted rights and redirects to a clean URL. A six-digit code cannot do this job alone, because a code used as the only lookup key can be guessed in a million tries.
Sensitive values in URL paths or query strings can reach access logs, browser history and third parties, so check which components record the URL. A URL can also reach third parties through the Referer header. Modern browsers send only the origin to other sites by default, but a page with a looser Referrer-Policy, or an older browser, sends the full URL with its query string.
Secrets
The SMS key in src/sms.ts is a restricted value in a file every developer and every CI job can read. Once it is committed, deleting it in the next commit leaves it in the repository's history, where anyone with a clone can find it. If the repository has ever been public, assume the key is stolen: hosting platforms and attackers both scan public commits for credentials.
A secret should live in a secrets manager or your deployment platform's secret store. The running service receives it at start-up, as an environment variable or a mounted file, and the code refuses to start without it.
const smsApiKey = process.env.SMS_API_KEY;
if (!smsApiKey) {
  throw new Error("SMS_API_KEY is not set");
}
Environment variables have leaks of their own. Child processes inherit them, and debug pages or crash reports that dump the environment copy them out. Diogo Mónica's essay on environment variables walks through these paths. Whichever way you inject the secret, keep it out of anything that prints configuration.
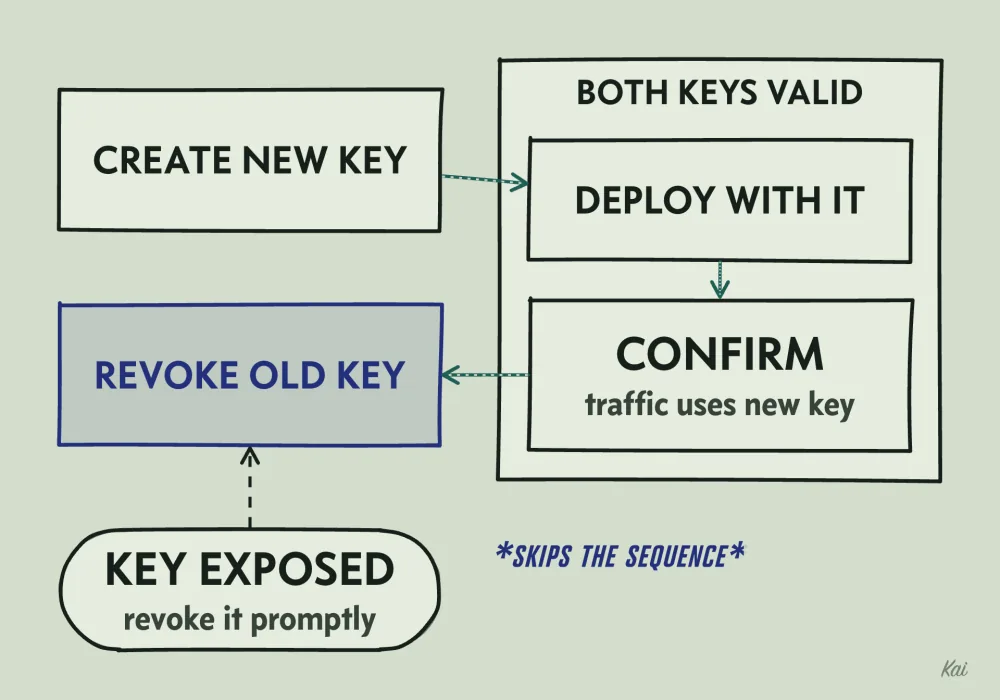
Rotation replaces an existing key. For scheduled rotation, run two keys side by side: create the new key, deploy the service with it, confirm that traffic is using it, then revoke the old one. Doing this on a schedule keeps the steps practiced. If a key is exposed, revoke it promptly instead. The side-by-side sequence leaves the leaked key valid while it runs, and restoring service afterward may involve some downtime. A pre-commit scanner such as gitleaks catches credentials that match its configured rules, so review what it finds and check for secrets the rules miss. That is cheaper than rotating after a leak.
Test data and screenshots
The twenty production rows in fixtures/users.json are real customers' names, emails and phone numbers, now copied into every laptop and CI runner that checks out the code. Test data should be generated. Use the example.com domain, which is reserved for documentation, and numbers ending in 555-0100 through 555-0199, which are reserved for fictional use in North America.
const fixtureUsers = Array.from({ length: 20 }, (_, i) => ({
  id: i + 1,
  email: `user${i + 1}@example.com`,
  phone: `+1202555${String(100 + i).padStart(4, "0")}`,
  displayName: `Test User ${i + 1}`,
}));
To spot a fixture built from real data, look for realistic personal email domains, names that look like real people, and IDs in the same format and range as production. Then ask where the file came from. Screenshots carry the same risk. A bug report, a design doc or a demo video captured from a real admin screen shows real customers, so capture them from a seeded demo account.
Before a field leaves your database, you should be able to name where it is going, why that destination needs it, who can read it there and when it will be deleted. If any answer is missing, withhold the field until the destination and its handling rules are understood. Apply the same review to an ID that can link records to a person.