
Where the Expected Value Comes From
An agent hands you a pull request titled "Fix failing late-fee test." The diff is one line:
- expect(lateFee(49967, "2026-03-01", "2026-03-04")).toBe(750);
+ expect(lateFee(49967, "2026-03-01", "2026-03-04")).toBe(749);The test is green now, and the code is still wrong. The requirement says a late fee is 1.5% of the amount due, rounded to the nearest cent. 1.5% of 49,967 cents is 749.505 cents, which rounds to 750. The function truncates instead of rounding. The test caught that, and the fix taught the test to agree with the bug.
When an agent writes both the code and the tests, the tests are where your criteria become checks a machine runs for you. That only works if you know where each test's expected value came from.
A test compares the result with a value decided in advance
Strip away the framework and a test does two things. It runs some code, and it compares the result with a value someone decided before the code ran. Everything else is setup.
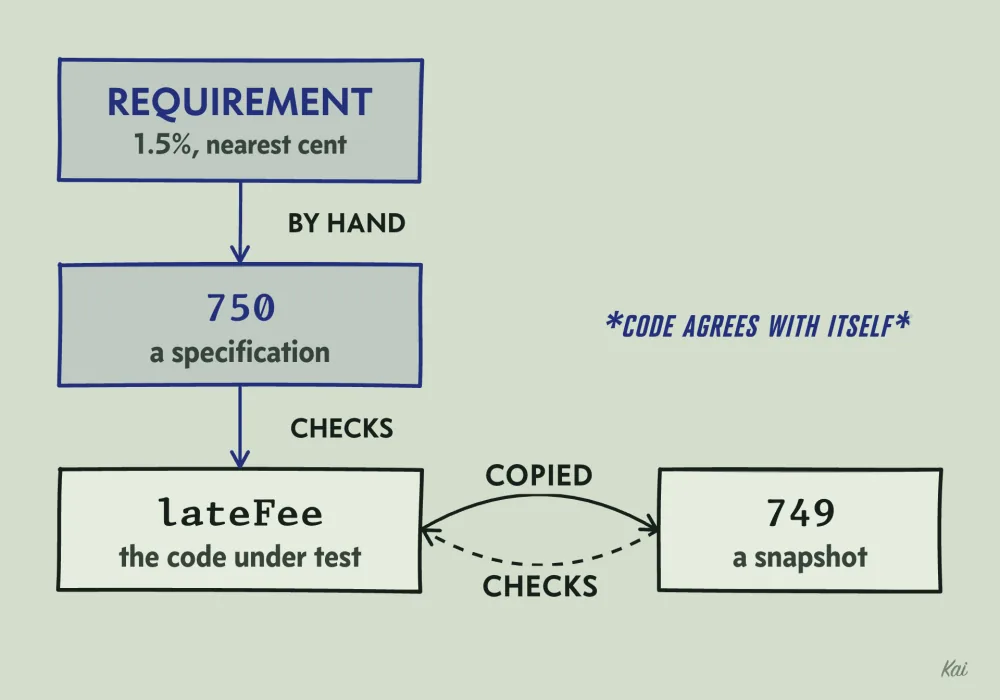
The comparison is only as good as that value. Testers call the source of the expected value the oracle: whoever or whatever knows the right answer. For the late fee, the oracle is the requirement. Someone read "1.5%, rounded to the nearest cent," did the arithmetic by hand, and wrote 750.
Now look at the agent's change again. The 749 came from running the code and copying what it printed, so the oracle became the code under test. A test whose expected value comes from the code checks that the code agrees with itself. It records what the code does today and establishes nothing about whether that behavior is correct.
So the first question to ask of any expected value is whether you could derive it from the criterion without running the code. If you can, the test is a specification. If the number exists only because the code printed it, the test is a snapshot of whatever the code does today, bugs included.
Write the tests from the criteria, before the code
Here is the full requirement, written as acceptance criteria:
- An invoice paid on or before its due date has no late fee.
- An invoice paid after its due date has a fee of 1.5% of the amount due, rounded to the nearest cent, with halves rounding up.
- The late fee is never less than $5.00.
Each criterion becomes at least one test, and you can write all of them before lateFee exists. Amounts are integer cents, so no stored amount has a fraction. The fee calculation still produces a fractional cent on the way, which is why criterion 2 states a rounding rule and the tests below pin it.
All three criteria have exact answers, so plain tests can check them. A criterion with no single right value, such as whether an error message is clear, gets an eval that scores the output instead, the subject of the lesson on evals. Its standard still comes from the criterion, written before anyone sees the output.
import { test, expect } from "vitest";
import { lateFee } from "./lateFee";

// Dates are ISO "YYYY-MM-DD" strings: due date first, then payment date.

test("no fee when paid on the due date", () => {
  expect(lateFee(49967, "2026-03-01", "2026-03-01")).toBe(0);
});

test("fee is 1.5% of the amount, rounded to the nearest cent", () => {
  // 49967 * 0.015 = 749.505 cents, which rounds to 750
  expect(lateFee(49967, "2026-03-01", "2026-03-04")).toBe(750);
});

test("half a cent rounds up", () => {
  // 40100 * 0.015 = 601.5 cents exactly, which rounds up to 602
  expect(lateFee(40100, "2026-03-01", "2026-03-04")).toBe(602);
});

test("fee is at least 500 cents", () => {
  // 1.5% of 10000 is 150, below the minimum
  expect(lateFee(10000, "2026-03-01", "2026-03-02")).toBe(500);
});
Run them and they fail, because there is no implementation yet. If ./lateFee does not exist at all, the run stops with an import error and executes no assertion, so first make the module importable with a stub that returns a wrong value, such as -1. Then each test fails on its own assertion.
That red run tells you each test is capable of failing. A test you have never seen fail has never shown you that it can detect anything.
Then the agent writes the code:
export function lateFee(amountCents: number, due: string, paid: string): number {
  if (paid <= due) return 0; // ISO dates of equal length compare correctly as strings
  const fee = Math.floor(amountCents * 0.015);
  return Math.max(fee, 500);
}
Two tests pass. The two rounding tests fail, with 749 where 750 was expected and 601 where 602 was expected, and those failures are the loop doing its job. They point at Math.floor, which truncates, where the requirement says round halves up. The fix does the rounding in integer arithmetic:
const fee = Math.floor((amountCents * 15 + 500) / 1000); // 1.5% is 15/1000; adding half of 1000 rounds halves upThis is exact for any amount up to a trillion cents, ten billion dollars. Far above that, amountCents * 15 passes 2 ** 53, above which a JavaScript number cannot hold every integer exactly, so a function that could see such amounts should reject them or compute with BigInt.
The expected values stay where they are, because they came from the criteria and the criteria have not changed.
That is also why tests written this way outlive the code they test. They hold for any implementation that meets the criteria. If an agent's version is bad enough, you can throw it away, have the function rebuilt against the same criteria, and let the same tests judge the new build. A suite copied from the old code's output cannot do that job, because it fails every correct rebuild that differs from the bug it recorded.
You can watch the whole loop in the playground below. A small check stands in for the test runner, and the same four tests run against the stub, the first version and the fixed one.
type LateFee = (amountCents: number, due: string, paid: string) => number;

function runSuite(name: string, lateFee: LateFee) {
  console.log(`-- ${name}`);
  const check = (test: string, actual: number, expected: number) =>
    console.log(`${actual === expected ? "pass" : "FAIL"}  ${test}: got ${actual}, expected ${expected}`);
  check("no fee when paid on the due date", lateFee(49967, "2026-03-01", "2026-03-01"), 0);
  check("fee is 1.5%, rounded to the nearest cent", lateFee(49967, "2026-03-01", "2026-03-04"), 750);
  check("half a cent rounds up", lateFee(40100, "2026-03-01", "2026-03-04"), 602);
  check("fee is at least 500 cents", lateFee(10000, "2026-03-01", "2026-03-02"), 500);
}

runSuite("stub", () => -1);

runSuite("first version", (amountCents, due, paid) => {
  if (paid <= due) return 0;
  return Math.max(Math.floor(amountCents * 0.015), 500);
});

runSuite("fixed", (amountCents, due, paid) => {
  if (paid <= due) return 0;
  return Math.max(Math.floor((amountCents * 15 + 500) / 1000), 500);
});
Output
Against the stub every test fails, which shows that each one can. The first version fails exactly the two rounding tests, and the fixed version passes all four without any expected value moving.
This is test-first work, often called red-green-refactor: write a test that fails for the right reason, make it pass, then clean up the code with the test as a safety net. You can skip the ceremony on trivial lines. The order has to hold for every behavior, though: the expectation exists, derived from the criterion, before anyone looks at what the code produces.
So when a test fails, changing its expected value needs an independent justification: the criterion changed, or the old value misread it and you can show the arithmetic from the criterion. If a diff moves the number and nobody can point to either, the fix belongs in the code.
Tests generated from the implementation
Ask an agent to "add tests for lateFee" after the truncating version exists, and you may get this:
test("calculates late fee", () => {
  expect(lateFee(49967, "2026-03-01", "2026-03-04")).toBe(749);
});The agent read the code, predicted its output and wrote that down. The test is green on its first run and it faithfully records the bug. Months later someone fixes the rounding, this test fails, and the correct change looks like a regression.
You can spot these in review. The test names describe the function ("calculates late fee") where they should state a rule ("rounds to the nearest cent"). The expected values are odd numbers with no arithmetic shown. And every test passed the first time it ran. When an agent writes tests after the code, ask it to cite the criterion behind each expected value and show the arithmetic. If it cannot, treat the value as unverified and derive it yourself from the criterion.
Tests that watch the machinery
Suppose the rate comes from a lookup, because different customer tiers pay different rates. An agent writes:
import { test, expect, vi } from "vitest";

test("looks up the rate", () => {
  const getRate = vi.fn().mockReturnValue(0.015);
  lateFeeForTier(49967, "gold", "2026-03-01", "2026-03-04", getRate);
  expect(getRate).toHaveBeenCalledTimes(1);
  expect(getRate).toHaveBeenCalledWith("gold");
});
This test passes with Math.floor and with Math.round. It passes if the minimum fee is missing. It never looks at the fee at all. And it can fail when the fee is right: add a cache that remembers each tier's rate, and the first call for "gold" in an earlier test warms it, so this test sees zero lookups and toHaveBeenCalledTimes(1) fails.
Whether such a cache is acceptable is a requirement question about how fresh the rate must be. A cache that holds a rate for up to a day is fine if the business accepts a day of the old rate after a change, and wrong if a new rate must apply from the moment it takes effect. A fee test catches the wrong kind. The call-count test cannot tell the two apart.
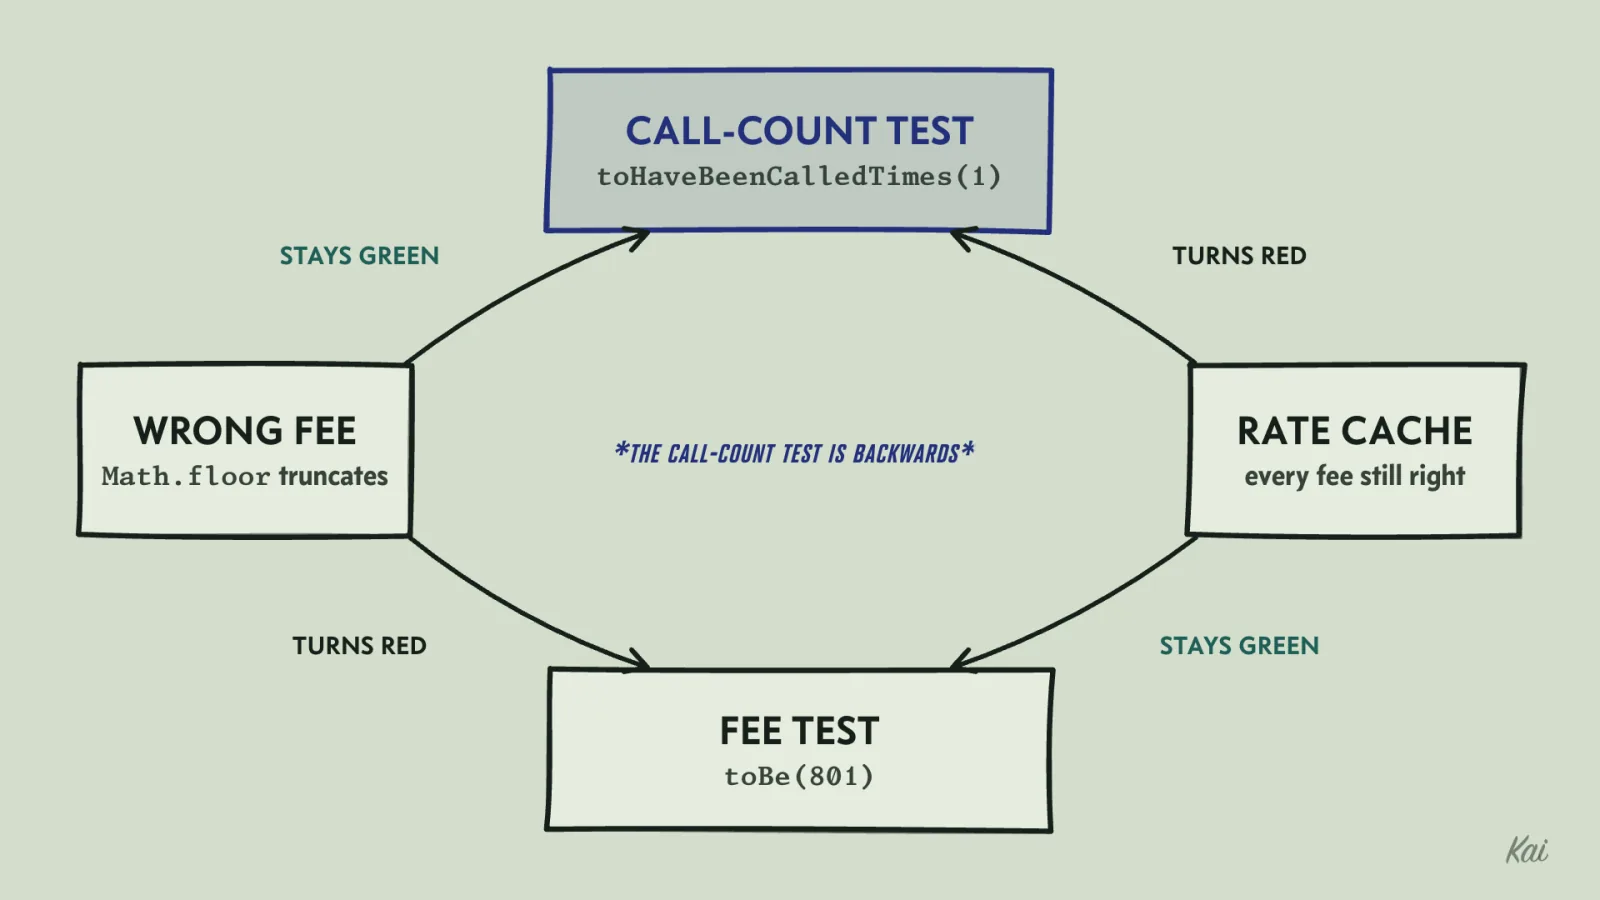
That pairing is the signature of a test coupled to implementation details: it breaks when you restructure correct code and stays green when the behavior is wrong. Asserting that a private helper ran, or that internal calls happened in a certain order, has the same shape.
Two questions sort these out. If the answer were wrong, would this test fail? If I changed the internals without changing any answer, would this test fail? A good test says yes to the first and no to the second. The call-count test says no and yes.
The fix keeps a stand-in for the lookup, because you still need to control the rate, and moves the assertion to what a caller sees:
test("fee uses the tier's rate, rounded to the nearest cent", () => {
  const getRate = (tier: string) => (tier === "gold" ? 0.01 : 0.015);
  // 1% of 80060 = 800.6 cents, which rounds to 801
  expect(lateFeeForTier(80060, "gold", "2026-03-01", "2026-03-04", getRate)).toBe(801);
});
Sometimes an interaction really is the behavior. A payment must be charged exactly once; a receipt email must be sent. There the call is what the customer experiences, so asserting on it is correct. The rate lookup is different, because callers see only the fee and never how the rate was found.
Tests that cannot fail
The weakest test has no meaningful assertion:
test("handles late payments", () => {
  const fee = lateFee(49967, "2026-03-01", "2026-03-04");
  expect(fee).toBeDefined();
});
Every number is defined, and so is NaN. This test passes for any implementation that returns something. Its relatives are a test with no expect at all, a test that only checks the function does not throw, and an async test that never awaits its promise, so the runner can finish the test before the assertion runs.
The question that exposes all of them is the one to ask of every test in a file: what broken behavior would make this test fail? Answer it for each test, in words. "Fails if the fee truncates." "Fails if the minimum is ignored." If the honest answer is "nothing," the test is decoration.
You can check your answers by hand. Break the code on purpose, by replacing the rounding with Math.floor(amountCents * 0.015) or deleting the Math.max, and run the suite. Every deliberate break should turn at least one test red. A break that leaves the suite green marks a behavior no test checks. Mutation testing automates exactly this, and the lesson on property-based testing covers it.
The playground runs that experiment. It breaks the correct lateFee four ways and lists, for each break, the tests that turn red. The suite is the four criteria tests plus the toBeDefined test above.
type LateFee = (amountCents: number, due: string, paid: string) => number;

const tests: Record<string, (lateFee: LateFee) => boolean> = {
  "no fee on the due date": (f) => f(49967, "2026-03-01", "2026-03-01") === 0,
  "rounds to the nearest cent": (f) => f(49967, "2026-03-01", "2026-03-04") === 750,
  "half a cent rounds up": (f) => f(40100, "2026-03-01", "2026-03-04") === 602,
  "at least 500 cents": (f) => f(10000, "2026-03-01", "2026-03-02") === 500,
  "handles late payments (toBeDefined)": (f) => f(49967, "2026-03-01", "2026-03-04") !== undefined,
};

const versions: Record<string, LateFee> = {
  "correct": (a, due, paid) => (paid <= due ? 0 : Math.max(Math.floor((a * 15 + 500) / 1000), 500)),
  "break: truncate": (a, due, paid) => (paid <= due ? 0 : Math.max(Math.floor(a * 0.015), 500)),
  "break: no minimum": (a, due, paid) => (paid <= due ? 0 : Math.floor((a * 15 + 500) / 1000)),
  "break: always charge": (a) => Math.max(Math.floor((a * 15 + 500) / 1000), 500),
  "break: return NaN": () => NaN,
};

for (const [name, lateFee] of Object.entries(versions)) {
  const red = Object.keys(tests).filter((t) => !tests[t](lateFee));
  console.log(`${name.padEnd(22)} red: ${red.length ? red.join(", ") : "none"}`);
}
Output
Every break turns at least one criteria test red. The toBeDefined test never appears in a red list, even for the version that returns NaN for every invoice.
Every bug becomes a test first
A customer reports a late fee on an invoice paid on its due date. Before touching the code, write the test that reproduces the report. It turns out the payment system sends full timestamps, so the test uses one:
test("no fee when paid on the due date, even with a timestamp", () => {
  expect(lateFee(20000, "2026-03-01", "2026-03-01T09:30:00Z")).toBe(0);
});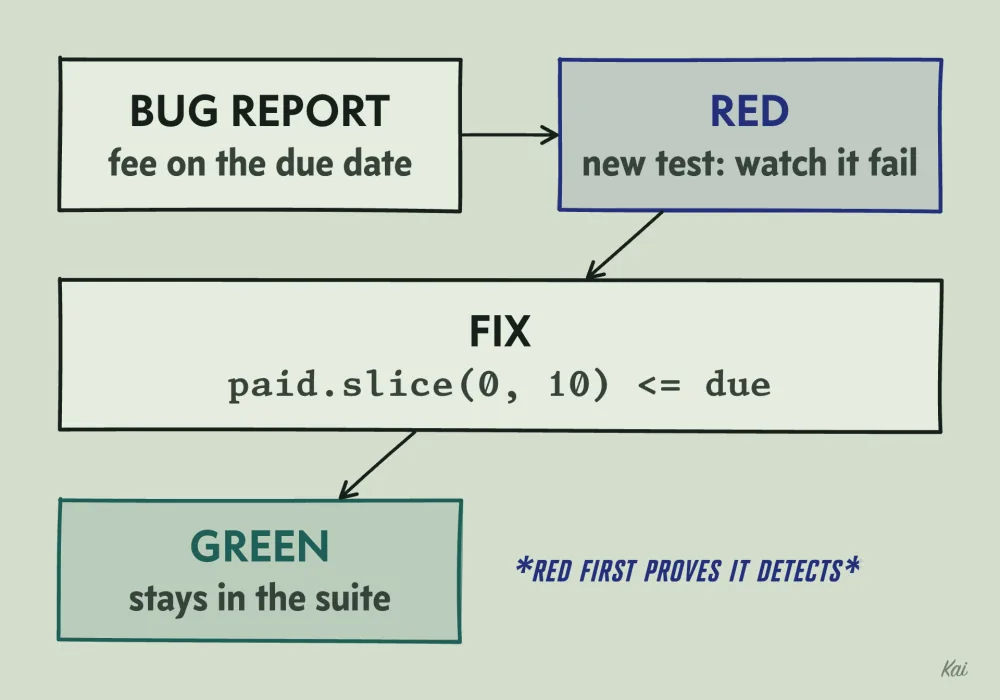
Run it and watch it fail. Now you know the bug is real and that your test detects it. The cause is plain once the test exists: "2026-03-01T09:30:00Z" <= "2026-03-01" is false, because a string sorts after any shorter string it starts with, so the payment looks late.
Compare only the date part, paid.slice(0, 10) <= due, and the test goes green. That is correct only because the requirement says billing dates are in UTC, and the Z timestamp is UTC. The billing timezone has to be stated, since a timestamp belongs to a calendar date only in some timezone: a payment at 23:30 in California on the due date is already the next day in UTC. For any other billing timezone, convert the timestamp into it before comparing dates.
The test stays in the suite, so this bug cannot return without a red test announcing it. If you fix first and test after, run the new test against the revision from before the fix and watch it fail. Without that, you cannot tell whether you fixed the bug the customer hit or some other one.
One behavior per test
Each test above checks one rule and is named after it. When "fee is at least 500 cents" goes red, the failure line alone tells you which requirement broke, before you open a file. A single test called "lateFee works" with twelve assertions tells you only that something is wrong, and it stops at the first failed assertion, which hides any others.
Named this way, the test file reads as the specification. Each criterion should map to tests that cover its examples, its boundaries and its error cases, and each test should trace back to a criterion. A criterion with no test is a behavior the code may drop without anyone noticing, and a test with no criterion is checking something no requirement asked for.
A test earns its place when you can name the criterion its expected value came from and the broken behavior that turns it red. If either answer is missing, the test is checking nothing you need.